Introduction
Artificial Intelligence (AI) is the technology behind so much of the technologies we use today, such as Chatbots, Recommender Systems, Fraud Detection, Virtual Assistant, etc. These systems are based on information that identifies patterns and learns relationships and does predictions. For instance, an e-mail service can learn to detect spam based on examples of spam mail and “good” mail. Likewise, customers’ previous purchases and browsing habits on the Internet can enable an online shopping platform to recommend products.
Knowing how AI processes data to learn can shed light on why certain AI systems provide correct responses and others provide incorrect responses. It consists of data collection, data preparation, training machine learning models, model testing and predictions made by the trained model. The performance of the model depends on the quality, quantity and diversity of the information used in training. This article covers the working of these stages and how their importance is data to building reliable AI systems.
How AI Learns from Data
AI learning is the ability of a computer system to leverage examples to recognize patterns and enhance the computer system’s performance with respect to a specific task. Machine learning systems can detect relationships in data without programmers specifying all the rules, whereas traditional software looks for relationships according to explicitly programmed rules. For instance, a developer can train a model from models of spam messages and normal email messages instead of having to manually make all the parameters of the spam email.
This is referred to as a machine-learning model. It absorbs and keeps parameters that are helpful for understanding new information and making predictions about that new information. For example, a computer could be trained using pictures of cats and dogs and learn trends in the images that could aid the recognition of different animals, distinguishing between cats and dogs. AI systems learn in a variety of ways such as through supervised learning, unsupervised learning, and reinforcement learning. Look into these methods in IBM’s guide to machine-learning models.
Significance of Data to AI.
Data is the foundation that fuels AI systems in learning from examples and information. If no relevant data is provided, there will be no useful patterns in a machine learning algorithm to be used in the task assigned. A bank setting up a fraud detection program could rely on transaction levels, locations, time stamps, or fraud history information to detect fraud. These examples are analyzed by the model to obtain the estimation of whether new transactions are similar to the previously identified fraud transactions.
But it is not just a matter of having lots of data, because an accurate model will not necessarily come out of data. Not having specific data, inaccurate information or examples that are not representative can result in bad predictions. A model trained with mainly data from one region, e.g., London, for instance, might not work well if applied to customers with different behaviors, e.g., from a different region, e.g., New York. Understanding data mining, data analytics, and machine learning helps explain how data is processed and used to identify meaningful patterns. The data should, therefore, represent the situations that the model will be used for, and must be appropriate, meaningful, and accurate.
AI Training Data Collection and Preparation
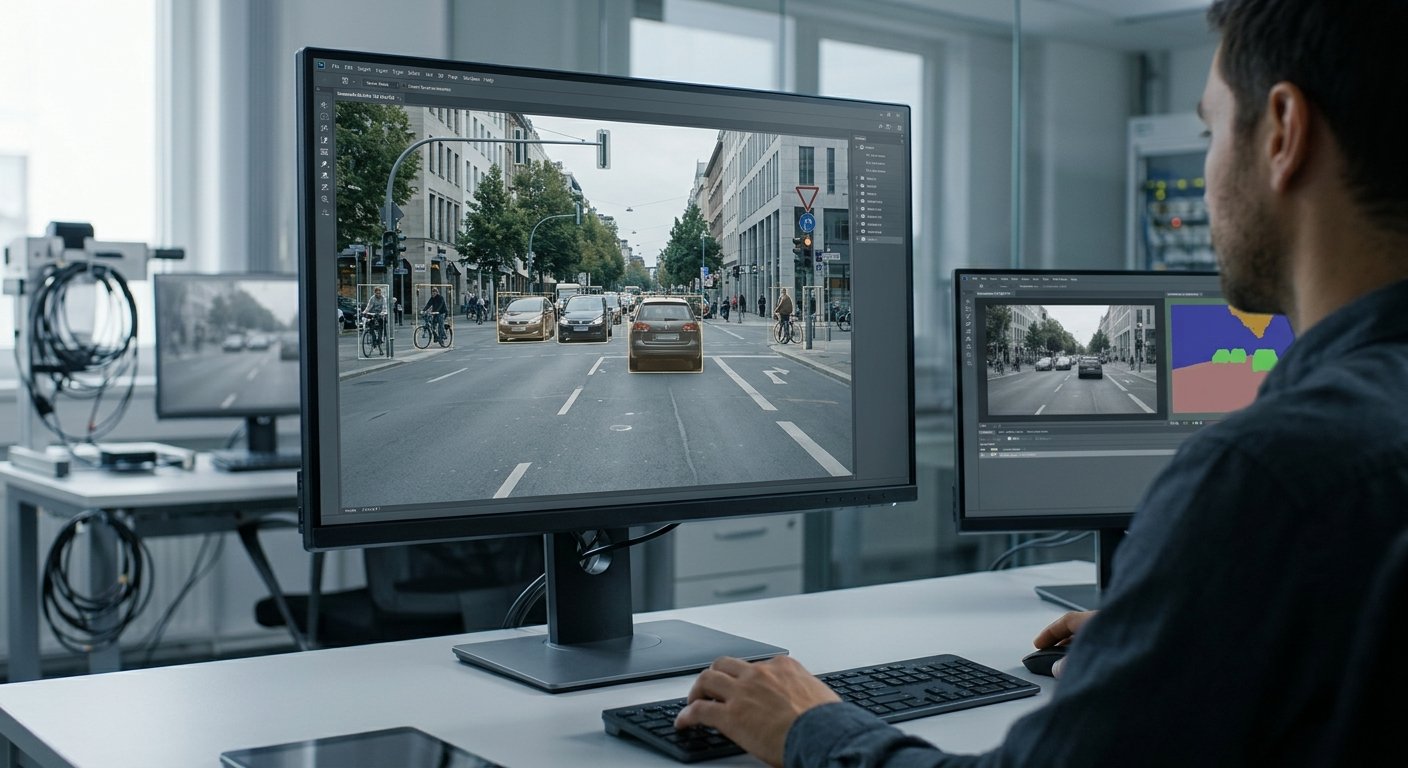
AI developers process information from various sources like databases, surveys, sensors, transaction records, public data, and images. The source needed for a problem differs according to the problem. A retail firm involved in predicting the sales of a particular product could obtain the information about the prices sold, the inventory, the seasons, and past sales of the product. Traffic observations and historical Journey Times by a transport company could be used to predict congestion.
The gathered information generally needs to be cleaned and structured prior to training. These processes include correcting errors, eliminating unwanted duplication, working with missing data and standardising inconsistent formatting etc. The developers could also choose some of the efficient functions, such as the house size and where the property is when forecasting house prices. By preparing the algorithm, you can enable it to process the information in a consistent way and minimize the danger of it learning misleading patterns from bad data records.
Data Labeling
Data Labeling comprises assigning categories or expected outcome(s) to examples. It’s especially crucial in supervised learning, where the model takes in input data and is given the correct answer. For instance, image data may consist of pictures set to dog, cat, and birds, or email data may be marked as spam or legitimate email.
The provision of accurate labels aids in models’ learning about meaningful relationships between inputs and outputs. A system for image recognition might learn the wrong associations with many of the pictures if they are mislabeled. Existing records, automated tools and human reviewers may help with the labeling but quality checks are vital. There are important classification and prediction problems where reliable labels are needed, even though unsupervised learning can be used to find patterns without labeled examples.
Training, Validation and Testing of Data.
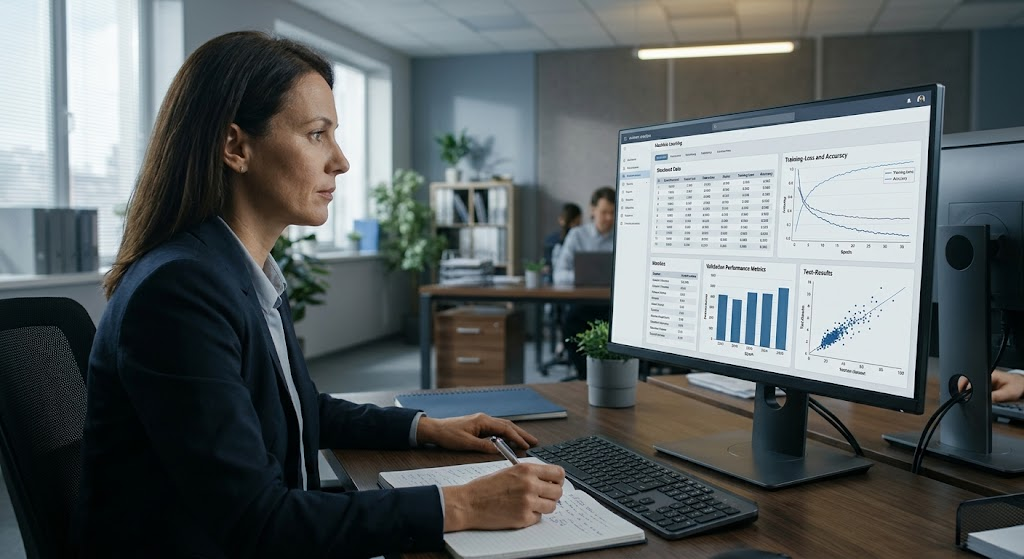
Typically trainer-validation-test sets are generated for machine-learning datasets. The training dataset provides examples for the model to learn from, determining the parameters. The validation data is used to test the model ones to verify that the model is well configured, and choose the best model configuration. The test set is used to test the final model by providing instances not included in the training set or the instances for the model selection process.
For example, 70% of the data might be used for training, 15% for validation, and 15% for testing. These proportions can be flexible and depend on the project. Separate datasets will make it easier to determine if a model is capable of learning new data, or merely recalling examples. If the predictions are made on a time basis (e.g., forecasting sales), dividing it with care is important so that data from the future do not impact the prediction of the past.
How Machine Learning Algorithms Learn Patterns
A type of algorithm that is mathematically used to find relationships in data is machine-learning. For different algorithms, some are better suited for some tasks and others for others. Linear regression can approximate real numbers, decision trees can learn from rules of features, and neural networks can learn from complex relationships based on connected mathematical procedures.
Take into account a model that predicts house prices. It is given historical records of sizes and locations of property, whether old or new, and selling prices. The algorithm is trained to learn relationships of these features and the recorded prices. The trained model solves given a set of information about a new property and what is likely its selling price. The usefulness of data, the algorithm, and the degree of applicability of learned relationships to new properties, determine the quality of the prediction.
The AI Training Process
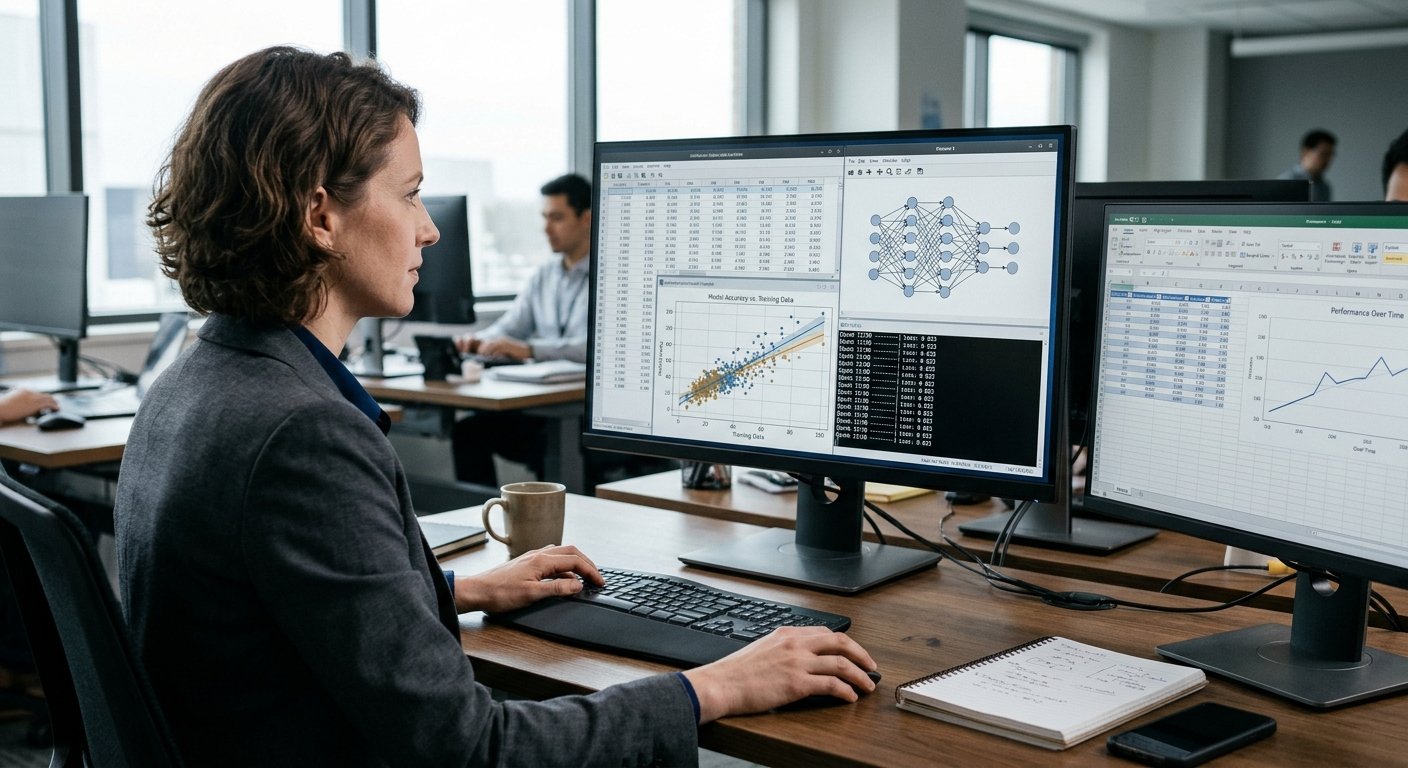
The training stage is where an algorithm is used to adjust a model based on training data. Supervised Learning is when the model makes a prediction and it checks against the correct answer. The difference is measured as a loss function, and in subsequent steps, the parameters of this model are changed in an optimization procedure to minimize that loss.
e.g., A model that is trained to recognize handwritten numbers may initially incorrectly classify the same-digit handwritten numbers. It can eventually adapt its classification by processing the labeled images and adjusting parameters, until it becomes adequate. Training and validation results are watched and recorded by the developers to see if learning is going well. When the model performs well on the training set but poorly on the validation set, it is likely that the model may be overfitting rather than learning patterns that transfer to unseen data.
Types of AI Learning: Supervised, Unsupervised and Reinforcement.
Supervised learning involves predicting a class label or numerical value from a set of labeled examples. It is used in applications like spam detection, image recognition, price forecasting etc. The model self-taught the known-updated information and used these relations to learn the new information. It is based in part on the training examples that it uses and how accurate the labels are.
Unsupervised learning discovers structures in data when there are no predefined target labels. A retailer, for example, can cluster customers based on the purchasing behavior of the customers. Reinforcement learning, on the other hand, is a learning method in which the agent is rewarded or penalized based on the environment which it interacts with. It can enable applications like robotics and perform simulated decision-making. These methods are used for various applications depending on data and tasks.
Predictions by AI and Pattern Recognition.
AI systems can make use of pattern recognition to discover repeating relationships in information. A forecasting model can identify that the electricity demand has certain peaks, or a recommendation system can find out that if a customer buys a product, he is likely to buy another. These patterns assist models to make predictions or classify new information.
When trained a model is used to make predictions when exposed to new inputs (or to infer from a new input). An email classifier might guess whether an email is likely to be spam, and a sales forecasting model can forecast sales. Predictions have not been made as this is not a guarantee. The accuracy may be lowered by unexpected events, inputs that are either incomplete or inaccurate, or changes in the real-world context. Hence, the use of AI outputs must be contextualized based on their usage and limitations.
Accuracy of the Model and Evaluation.
Model accuracy is the rate at which a classification model can make accurate predictions. A system that classifies 900 of 1,000 messages correctly will have a 90% accuracy rate. But accuracy on its own can be misleading if there are significantly more people in one category than another. For instance, a fraud detection model might seem very accurate because it would fail to detect the vast majority of a fraud and but succeed at detecting the overwhelming majority of non-fraud transactions.
Other metrics provide additional insight. Precision refers to the fraction of cases that are predicted as positive but actually turn out to be positive, whereas recall refers to the fraction of cases that actually are positive but are predicted as such. The regression models can be assessed based on things like mean absolute error. Appropriate measures will provide information for the developer to know the strengths, weaknesses, and uses for the model.
Overfitting and Underfitting in AI
Overfitting is when a model learns too much from the training examples, including noise. A model which works well with familiar data but does not work well with new data. For instance, a forecasting model might learn to uphold sales variations that happened just once; it may not learn specific variations in demand.
Under-fitting occurs when a model does not reveal important relationships in the data. This is represented by a model that predicts the same price for all houses from a particular period, irrespective of house size and location. To overcome these problems, the developers can include more data in the models, simplify the models, choose the appropriate features or apply the regularization technique and/or the early stopping technique to the models. The intent is to develop a model that is able to forecast well for the familiar input, but also for new data.
Importance of Data Quality and Quantity in AI Outcomes
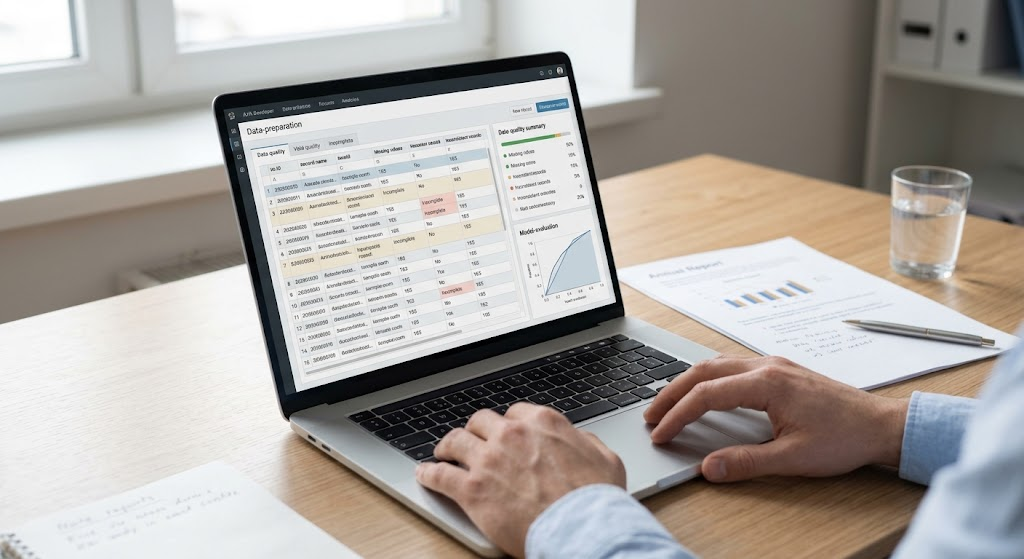
Quality data has a significant impact on AI output. Prediction is not reliable or fair if records are inaccurate, if labels are incorrect, or if groups are under-represented. For example, a speech recognition system that was trained from a small number of accents, might not work as well for speakers with other accents. Greater diversity of the dataset volume can assist the model to be utilized by a wider range of users.
Also with data quantity you have to take this into account, especially if building a more complex model, but more data does not necessarily equal a better model. Duplicate, unnecessary, and obsolete records might be of little value. The most useful datasets have adequate relevant examples and reflect the conditions that the model will be called upon for. The developer needs to concentrate on obtaining good quality data instead of bulk quantity.
Real World Applications of AI Learning.
Spam detection is an example of AI learning from labeled data. A model processes through samples of spam and harvest to find patterns in the information in past messages and other characteristics that are relevant. It then makes use of those patterns on received messages. Spam techniques changing may result in changes to the model for continued effectiveness, and examples need to be updated to do so.
The way people use data is different with regard to recommendations. Websites can track what users bought, how much time they spend looking at specific products and how they engaged with them, to provide helpful suggestions. The model first recognises correlations among products and customers preferences, then proposes suggestions. But, if information is out-of-date or the lack of broader interest in customers can lead to poor quality recommendations. The examples show data’s role in enabling real-world AI use cases and how it can shape their accuracy and value.The examples highlight the importance of data in powering real-world applications of AI and the impact that data can have on their effectiveness and quality.
Managing Challenges and Responsible AI development.
It is not enough to gather numbers and pick algorithms for AI development. Developers need to think about privacy, security, consent, fairness and the impacts of wrongful predictions. There can be biases within historical data that cause a model to simulate discriminatory patterns. Personal information should also be managed suitably and access restricted, while there should be proper protection for it. Following the principles of responsible AI, ethics, bias, and privacy can help developers build systems that handle data appropriately and reduce the risk of unfair or harmful predictions.
When there are scenario changes in the real world, AI models can become less reliable. Fraud methods change, customers change their minds and alter tactics. Therefore, it is important for organizations to be aware of the performance of their models and to research into the identification of decreasing accuracy. They are able to update data sets, retrain models and test the new systems, as needed, before deployment. Responsible development involves constant real-world checking and monitoring to make sure that AI continues to be appropriate for its function.
Conclusion
Data is used to teach AI, with patterns and relationships discovered using machine-learning algorithms. Collection of relevant information, preparation of datasets, labelling of examples if needed, model training, evaluation, and prediction using trained models. The set of data that is used for training and testing allows the developer to assess if the model has the ability to generalise to data it hasn’t seen before, and the training metrics provide clues about its strengths and weaknesses.
True AI of course, is more than just complex computer-implemented algorithms. The outcomes are affected by data quality, quantity, diversity and correct labeling. Developers will also need to take care of these issues as they pertain to overfitting, privacy, equity, and real-world changes. Data, as it relates to training and predictions, will help readers appreciate what and what not AI can and is unable to do.