Introduction
The world of business is changing, and machine learning is playing a big role in changing the way that businesses analyze data, make predictions and automate work. Machine learning algorithms can be used to identify patterns and make informed decisions, such as predicting sales or detecting fraud. Many more steps lie behind creating a reliable model, though. Developers need to take some measures to prepare the data in advance, make predictions, avoid mistakes, and even track the performance of the developed application after the deployment.
A model which has trained well on the given information may not work well if the data presented to it is different from what it has learned. This may become less accurate if the data patterns change, if data quality is not good, or if there is ‘overfitting’. Knowing how models are trained, tested, deployed and improved helps to rationalise the need to evaluate models continuously rather than once when they are trained.
How Machine Learning Model Training Works
Training is the act of teaching an algorithm to learn how to find patterns in data and make predictions. Developers share examples which show a relation between inputs and desired results for the model to learn. In one scenario, a weather forecast program can be trained using past data on the size of a house, where it’s located and its selling price to determine the price of a home.
Machine learning methods have varying learning approaches. In supervised learning, the examples are labeled, while for unsupervised learning there are no labels. In RL, the rewards and penalties will be used to guide the way the agent behaves. In any case, the developer should determine if the model is useful for predictions based on information that has not been seen.
- Data Collection and Preparation
Data collection is the groundwork for machine learning development. Information can be from business databases, customer interactions, data on transactions, sensor data, public data, or any other source depending on use. The data collected should be representative of the problem to be addressed by the model. The algorithm can only learn useful patterns with complete, accurate, up to date and unbiased information.
Once collected, developers process the data in various ways to remove unnecessary duplicates, remove missing values, reformat inconsistent string formats, and transform variables when appropriate. Another way to make more meaningful inputs is by using a feature engineering approach. For instance, in sales forecasting, the sale value may contain indicators of the season and previous sales values. Maintaining good data quality is essential for effective machine learning model training because incomplete, inaccurate, or outdated information can lead to unreliable predictions. It is important for developers to ensure that these features will be available at the time of prediction.
- Data Training, Validation, and Test Sets.
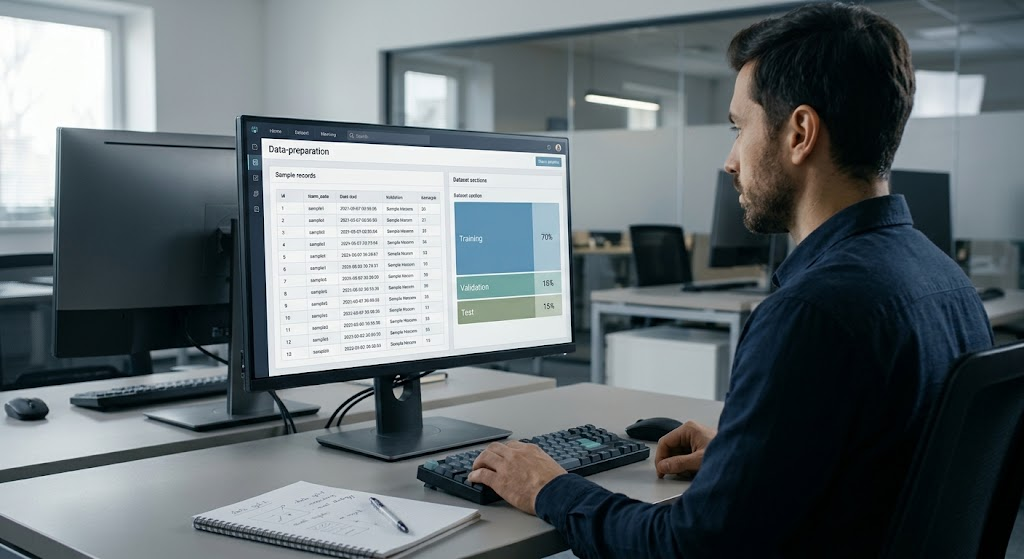
A typical approach used in machine learning development is to divide a dataset into three sets: training, validation, and test sets. Each set serves a different purpose in machine learning model training and evaluation. The training set teaches the model to identify patterns, the validation set helps developers compare models and adjust hyperparameters, and the test set provides an independent assessment of the selected model. Understanding model validation helps developers evaluate whether a model can generalize to new data instead of simply memorizing the examples used during training. A common starting point is 70% for training, 15% for validation, and 15% for testing, although the appropriate proportions depend on the dataset and application.
Random splitting can be misleading when dealing with time dependent problems. The data for training a forecasting model should reflect the behavior observed in previous time periods while the model is assessed during successive time periods. The goal is to make sure evaluations match the situations under which the model will be used.
- Training Dataset
The training dataset is stocked with examples the algorithm learns from. While training, the model makes predictions and adjusts internal parameters so as to minimize errors. This process is continued until the end of the training procedure is reached.
But high training performances do not necessarily mean consistently good predictions. A model could memorize specific examples but fail to discover patterns which apply to new problems. The only way to find this problem is to compare training results with validation and test results to detect it.
- Validation Dataset
The purpose of the validation set is to allow the developers to compare models and work out the hyperparameters (the settings that affect the learning process). Some examples are learning rate, decision tree depth, or the strength of the regularization. Validation results aid in determining the best performing configuration for data not used in the parameter fitting.
It is also possible to perform decision making on the same training data again to see possible overfitting when selecting a satisfactory model. Thus the test data set should be used to test final development decisions rather than for development purposes.
- Test Dataset
The test set is used to assess the chosen model with instances not used to train or select the model. It gives an approximation on how well the model will perform on data which is similar but not identical to the data used in its training.
However, there is no guarantee that the Test Results describe the future performance. The test data might not be atypical or conditions that change in the real world. Test scores provide feedback to the developer in conjunction with knowledge of the limitations of the data and the implications of prediction errors.
Specific Transition Sequence.
In training, an algorithm takes training examples and learns the relationship between the input and output. It determines a loss function that quantifies errors in prediction and learns parameters that minimize the loss. May repeat several times for training (depending on the algorithm, data size, and problem complexity).
It is important that the developers follow-up on the process of learning and check whether learning is taking place according to the set pace. When training performance is increasing, but validation performance is decreasing, the model might be overfitting. This can be resolved by adjusting the complexity of the model, examining different training parameters, or by enhancing the data set.
Overfitting and Underfitting
Overfitting occurs when a model captures what is specific to the train set, such as noise and incidental associations. Such a model might yield superb training performance and fail miserably when used on data that is unfamiliar. In some cases, the image recognition model can learn on the basis of background instead of learning the features of objects.
Underfitting is if a model reads the data loosely and does not learn certain patterns. It can give poor performance on the training and validation data sets. Underfitting can be tackled by increasing features, selecting a different algorithm, or tweaking of training parameters by the developer. The objective is to strike a balance between learning to recognize meaningful patterns and generalizing the learned patterns with respect to new examples.
Measuring Model Accuracy, Precision and Recall
Evaluation for models needs to be based on indices reflecting the task. The accuracy is the number of accurate predictions made as a percentage of the total number of forecasts for that night. It is helpful in many scenarios, but can cause some confusion if one class is much more prevalent than the other.
The precision evaluates the rate of true positive cases compared with the number of predicted positive cases, the recall the rate of true positive cases compared with the number of actual positive cases. Precision in the applications of fraud detection can be used to see how many transactions are truly frauds that are flagged for review, while the recall in the applications of fraud detection can be used to find out how many frauds are flagged for review.
The identification of metrics for developers should depend on what the errors in their prediction would mean. They can also review performance within various groups, places, and periods of time as overall may mask weaknesses in specific circumstances.
Hyperparameter Tuning to Boost Performance
Hyperparameter tuning: searching for proper parameters when training a model. If the learning rate is too high the training may turn out to be unstable and if a decision tree is too complex it might overfit the training set. Use of appropriate settings can enhance both efficiency of learning and generalization.
Grid search, random search, and/or more sophisticated optimization techniques can be utilized among the configurations. These should be tested on the validation data and the test set be held aside for final assessment. It’s not the training score that makes the best configuration, it’s the one that performs reliably on information it hasn’t seen before.
Preventing Data Leakage.
The leakage is when information which does not ‘legitimately’ belong at the time of prediction is used in training or evaluation. This can result in peggers’ records much higher than a real score.
In a customer cancellation model, for instance, a field may be created after the customer has canceled and will be included in the model when predicting customer cancellation. Flows can be prevented from leaking by splitting datasets appropriately and ensuring that preprocessing steps—which have come directly to them during training—are incorporated in their flows, while features capture information when a prediction needs to be made.
Deploying the Model into Production
When the model is trained, it can be deployed for real-world use. It could be a mobile app, a web app, or an application programming interface (API), or it could be a business system. An operating model might be used to sort through customer requests, predict what products customers will be requesting, or detect any transactions that may be fraudulent.
Before the model deployments, developers need to confirm the data is received as desired and the model results are given in a reasonable amount of time. They need to perform security, reliability, and interoperability tests as well. In critical applications where critical decisions have to be made, human user review and controlled releases can assist in mitigating the impact of mispredictions.
Monitoring Model Performance and Drift
The performance of a deployed model may be affected by the changing of actual conditions. Data drift is when the distribution of data that arrives to your model changes, and concept drift involves when the input/output relationship being predicted changes.
A retailer may over–see changes in customer preferences or a competitor launch a new product, causing the sales forecasting model to lose accuracy. Developers need to pay attention to the accuracy of input, the pattern, or the actual performance while producing and when they become available, results to compare it with.
Just because the data changed does not imply that the model has become less accurate at the new values. Teams should explore the data to gain an understanding of if the issue is due to changing circumstances, software glitches, incomplete or poor quality data, or limitations with the model itself.
Retrain the Models to Assure Performance.
Retraining involves modifying or expanding the model with new or new data. It might be required if more examples become available, error rates increase, or the world evolves. Some models are updated periodically, and others are surface updated as monitoring indicates a particular need.
Retraining, however, does not guarantee the improvement of performance. New data may be based on information that is incomplete or simply reflect temporary conditions. The information should be checked by the developers, trained on the candidate model, and examined for consistency with the current model to make sure that the model fulfills the requirements before it is implemented.
Machine Learning Operations (MLOps)
Machine learning operations (or MLOps) refers to the set of practices and tools to manage machine learning models over their lifecycle. It ties development, deployment, monitoring and maintenance together in repeatable workflows.
Machine learning operations help organizations by helping them understand the importance of automated pipelines, model versioning, testing, and monitoring for ensuring consistent model management. These practices enable teams to manage experiments, test new versions, better understand problems and deployments.
Additionally, MLOps facilitates data scientists, engineers, and business teams to work together effectively. Automated checks can detect issues with data quality or stop a model from being put into production if it doesn’t meet desired performance criteria. Human intervention still has its place especially with regard to high-stakes decisions based on predictions.
How to Build Trustworthy Machine Learning Models
Developers can take a number of things into account during the development of their models to make them more reliable:
- Gather substantively appropriate, representative, and precise information.
- Properly split the training and test data sets.
- Watch out for overfitting, underfitting and data leakage.
- Choose the metrics for the test of the model based on the losses from predictor errors.
- Tune hyperparameters with regular validation processes.
- Run tests on models in simulated use prior to deployment.
- Track performance and shifting data pattern(s) post-release.
- Retrain models if evidence provides support for updating models.
- Keep the version log and employ a controlled deployment method.
By heeding to these practices, organizations are able to recognise their weaknesses at an early stage of the process and make informed improvements. ML is only going to be reliable if the data is reliable, if the ML model is appropriate for the application, and if the processes of evaluating and maintaining the system are robust.
Conclusion
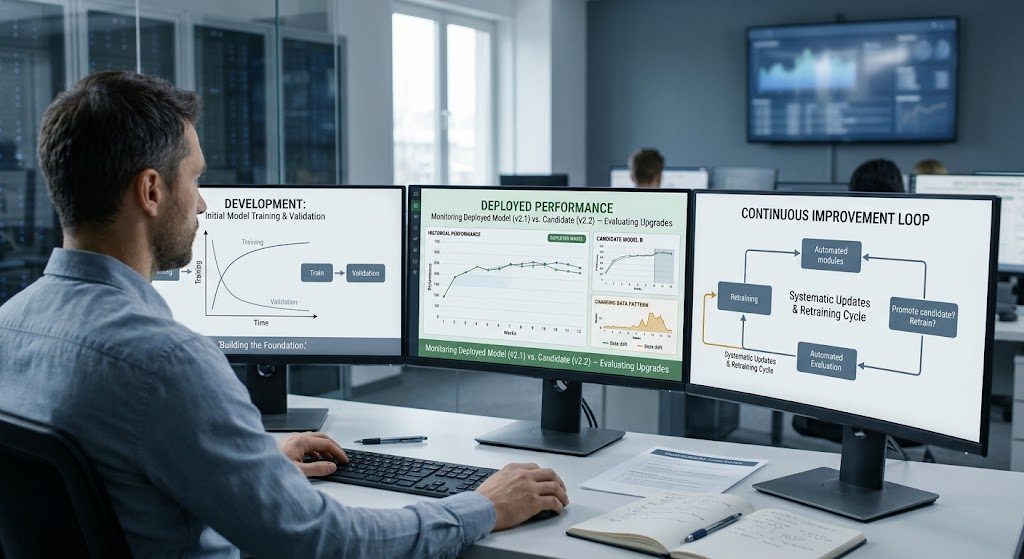
Training a machine learning model is just a step towards building a robust predictive system. Developers need to handle data with care, divide the data into training, validation, and test sets, assess performance, and avoid data leakage and overfitting.
Continuous monitoring is done after deployment indicating performance changes and the need for retraining or other interventions. MLOps provides support in the following ways:The following provides support for this process:
Finally, accurate machine learning is not the result of one successful training. It needs continuous monitoring, maintenance and adaptation based on real-life experience. Organizations can create a machine learning system that will benefit them as they evolve and as their data evolves, their requirements evolve, and their operating conditions evolve by designing the model, as a continuous process.