Introduction
Businesses collect vast amounts of information during sales and customer interactions, financial transactions, manufacturing workflows, and via digital channels. But merely gathering information does not necessarily lead to better business performance. The true value is in comprehending what the information tells you, and then applying it to improve decision-making. By analyzing past data, organizations can find trends and patterns, and make informed predictions about future events, which can help them achieve this.
Data mining is integral in this process as it helps identify meaningful relationships in large amounts of data that would not be noticed otherwise. For instance, a retailer can review past transactions to predict customer buying habits, and a financial institution can analyse repayment patterns to determine the level of credit risk. Data mining combined with statistical modelling and machine learning allows organisations to go beyond mere insights into what has happened and prepare for what may happen.
What is Predictive Analytics and Data Mining?
Predictive Analytics utilizes historical data, current data, statistical methods, and computer-based models to predict future outcomes. It assists organisations to answer questions like which products are likely to be bought by customers, when equipment may need maintenance and which customers may cease using services. Predictive analytics is more about predicting what will happen next, as compared to descriptive analytics, which is about explaining what has happened. It provides results that can help you plan, allocate resources, manage risk and make decisions. Predictive analytics doesn’t remove the need to consider uncertainty, though. Instead, it relies on existing evidence to create an educated guess on what will likely occur and to inform decision makers to plan for scenarios. The accuracy of these estimates is contingent upon the appropriateness of the information, the application of suitable analytical techniques, and how applicable the historical context is in the present context.
Data mining can be used to identify valuable patterns, relationships, and trends in large datasets, which is a key step in predictive analytics. An organization might have years of transaction data, customer information, inventory reports, and measurements of its operations, but it would be inefficient to review all of this data by hand. Now, data mining techniques enable systematic analysis of such datasets to extract information that pertains to a particular business problem. For instance, a supermarket might find that some items are sold more at specific times of year, or that if customers buy one item, they are more likely to buy another. The resulting data can be used as inputs to predictive models. Another important use of data mining is to detect unusual activity, cluster customers by similar attributes, and find relationships between business variables. If these findings are paired with suitable modelling tools, organisations can make forecasts, based on historical evidence, and make decisions that are based on more than just intuition.
How Data Mining Can Help in Predictive Analytics.
- Recognizing trends in the past
Many predictive analytics projects rely on historical data, as past observations can shed light on how different factors are associated with the outcomes. Data mining enables these relationships to be uncovered by analysing data over time, customers, transactions and operational activities. For example, if a retailer sells online, they could observe that sales of products go up during holidays, after a promotion or when a product is popular on social media.
These patterns can be used to gain understanding of demand changes and to inform future forecasting. Likewise, a telecom firm could find a correlation between customer activity, multiple service complaints and customer churn. These relationships do not guarantee that a specific behavior will happen in the future but as evidence they are useful to estimate future behavior. Data mining can identify patterns to help organizations identify factors that should be considered in predictive modelling.
- Preparing Data for Predictive Models
To be predictive, an organization needs to do a careful job of preparing its data. The data gathered from various systems may contain duplicate data, missing values, mismatched formats, old data, and/or inaccurate measurements. Data preparation requires identifying these issues, fixing errors as much as possible, and structuring data to a proper format for analysis. Analysts need also to choose variables that are meaningful to the prediction of the outcome he/she is trying to predict. For instance, the monthly sales of a business could be predicted based on its historical sales, the prices of products, promotions events, seasonal forecasts, and past demand.
These variables are used to identify circumstances indicating various sales results. Good preparation also requires that there be a sufficient amount of information to make a prediction that would actually have been available at the time that it was supposed to be made. If these checks aren’t included in the model, then the model might seem to be doing great while in development, but not so great when it comes to authentic business scenarios.
- Representing a Sequence of Patterns as a Prediction
After identifying patterns in the data and preparing it, relevant data patterns can be used in statistical models or machine learning algorithms to make predictions about future outcomes. A model is used to learn the relation between the chosen input variables and the outcome of interest. It can then use those relationships to apply them to new data and make a forecast or probability. A retailer, for instance, could observe past sales data, the present price of a product, and sales trends for that season and predict a demand for a certain number of the product for the upcoming month. A bank may look at the bank’s history of repayment and other factors to gauge the chance of default. The forecasts generated can help with the purchase decision, financial evaluation and planning of operations. The process is not just to look for patterns in historical data, but also to test if the patterns can help the model to accurately estimate the information it has not been exposed to before.
To gain insight into how prediction accuracy works in easily accessible language, organizations can review the pertinent literature on predictive modelling and the assessment of model performance. Knowing what accuracy means helps decision makers to interpret forecasts correctly, and not to interpret any forecast output as a future event. A good predictive system could be judged by what it is doing, the information it is using, and the ramifications of its mistake. It’s important to note that there are multiple types of prediction problems and evaluation methods. Making an estimation of sales is very different from predicting that a customer will leave a service. Organizations can use predictive analytics more effectively if they choose appropriate methods, and interpret the results accurately.
Relationships between Data Mining, Statistical Modelling, and Machine Learning
While data mining, statistical modelling, and machine learning are closely intertwined, they are distinct and have different roles in a predictive analytics project. Data mining is about finding patterns and relationships in data that are meaningful. Statistical modelling involves mathematical and statistical relations to describe data and to estimate results; machine learning involves building algorithms based on examples and applying them to new situations.
These techniques can overlap and sometimes a single predictive analytics project can involve all three. The process could start by extracting patterns in customer behavior from their records, then analyze statistical patterns of relationships between user behavior and customer withdrawals, and finally learn a machine learning model to predict which customers are at risk of canceling. It is important to understand how these methods work together and what are appropriate analytical methods to use rather than using the same method for every data problem.
The Role of Statistical Modelling
Using statistical modelling, a structured description of relationships between variables and an estimation of how different variables are associated with an outcome can be provided. Commonly used techniques in predictive tasks include linear regression, logistic regression and time-series analysis. For instance, linear regression may forecast a mathematical outcome, e.g. monthly income, from the variables of interest. Logistic regression can be used to predict the likelihood of a binary result, for instance, if a customer is at risk of canceling a subscription.
Time-series techniques are used to analyse data collected over time, looking for trends, periodic behaviour and changes in behaviour. If organizations are interested in knowing how variables relate to predicted outcomes, statistical models can be particularly useful. They can also give information on the uncertainty, depending on the methodology. The effectiveness of their use, however, is dependent on the assumptions and structure of the model selected being a reasonable fit to the problem and the data available.
The Role of Machine Learning
With machine learning, the computer system can learn relationships from examples, not just depending on rules that have been specified by humans. During training, an algorithm is fed with past observations and tunes its internal parameters to enhance the predictions, following a specific objective. Examples are decision trees, random forest, gradient boosting, and neural networks. For example, a decision tree can be trained to distinguish between groups of customers that have different rates of cancellation by learning a sequence of conditions.
Random forests are a collection of decision trees; gradient boosting is a collection of a sequence of models that improve the prediction performance. There are many algorithms, each with its own merits, and complex doesn’t necessarily mean good. There are several factors that organizations need to consider: the data available, the nature of the prediction task, computation requirements, and requiring explanations of model outputs to those who will use the model.
How the Three Approaches Work Together
When data mining, statistical modelling, and machine learning are combined, they can provide a more comprehensive understanding of the data and enable organisations to make better estimates of future outcomes. Data mining can be used to discover interesting patterns and variables that may be relevant to the problem, statistical modelling can give techniques for measuring the relationships, while machine learning can be used to capture complex patterns that might not be easily represented with simpler methods.
For new data not seen before, analysts may compare several methods to find out which one works best. They are also required to think about whether their model’s predictions can be understood, useful, and suitable, for the decision they are looking to make. Sometimes, a simple statistical model can be adequate, and may be easier to understand than a more complex algorithm. The goal is not to find the most advanced technology, but to create a dependable and useful predictive method that meets the unique needs of the organization.
Major Business Applications of Predictive Analytics and Data Mining
1. Sales Forecasting
One of the most widely used cases for predictive analytics is sales forecasting, which involves predicting future sales.Sales forecasting is one of the most frequent uses of predictive analytics, as companies need to have an educated guess on what they will be selling in the future. With data mining, retailers and other companies can discover trends in past purchases, buying habits related to seasons, price changes, promotions and customer tastes. For instance, a clothing store can look at past sales to determine how much they would expect to sell of a specific item during certain seasons throughout the year.
If it has been observed in the past that certain items sell better during festive seasons, this can be factored into the forecast. These trends and other factors can be used in statistical models and machine-learning algorithms to predict future sales. They can then use the outcomes to schedule staff, budget, and coordinate purchasing. However, actual sales may differ from the forecast due to unforeseen shifts in consumer demand, competition, economic conditions, and/or product availability.
2. Customer Churn Prediction
Customer churn refers to when a customer ceases to buy a company’s products or services or cancel a service. This can impact revenue, as well as the resources that will be required to replace customers, which is why churn prediction is useful for subscription businesses, banks, telecoms and online services. Data mining can enable companies to determine patterns of those customers who have left in the past. This may involve repeated complaints, reduced engagement, reduced purchases or declining use of the patterns.
Using the relevant historical data, a machine learning model can be used to predict which of the existing customers might be more likely to churn. The company or organisation can then explore why their customers are not engaging and what measures should be taken, such as enhancing their customer service or tackling any recurring issues with their services. But a high-risk prediction doesn’t imply that a customer will necessarily go. They should be used responsibly by businesses, safeguard customers’ information, and not use statistical forecasts as facts about how a customer will behave.
3. Inventory Planning and Demand Management
Inventory planning is the process of ensuring that an organization has an adequate supply of inventory or materials to satisfy anticipated demand, but without excessive investments in inventory that is not being used. Failure to plan adequately can result in out-of-stock situations, late orders, storage costs, and out-of-fashion products before they are sold. Predictive analytics can be used to forecast customer needs in the future by analyzing patterns in past purchases, seasonal trends, delivery times from suppliers, promotions, and more.
For instance, a grocery store can predict increased sales of specific food items during the holidays season and plan their inventory accordingly. This technique can be applied to a manufacturing company to estimate how many units of a raw material are needed for the estimated production periods. Data mining reveals patterns in the data related to the demand, and forecasting models convert those patterns into estimates that can help with purchasing decisions. Past history cannot predict all future events, so businesses should still take into account a sudden drop in supply, fluctuating prices or any unusual demand.
4. Credit Risk Assessment
When it comes to the financial industry, predictive analytics is used to forecast the probability of borrowers repaying their loans on time and as agreed. It is possible to discover connections between past repayment history, the level of outstanding debts, income data and other appropriate financial variables from a legally and ethically sound basis by data mining. These relationships can be used in statistical models and machine learning algorithms to estimate the credit risk and to assist lenders’ application screening process. For instance, a lender can rely on a validated model to calculate the likelihood of defaulting payments on a loan given specific financial circumstances.
This information is useful for risk management, loan portfolio planning and will help to determine if further assessment is required. But predictions of creditworthiness should be used with caution as an inaccurate or biased model can have an inequitable impact on individuals. Financial institutions need to assess data quality, analyse data performance by relevant groups, secure sensitive data and ensure adherence to relevant laws. A prediction should be part of a fair process not a substitute for proper review and consideration of individual circumstances.
5. Predictive Equipment Maintenance
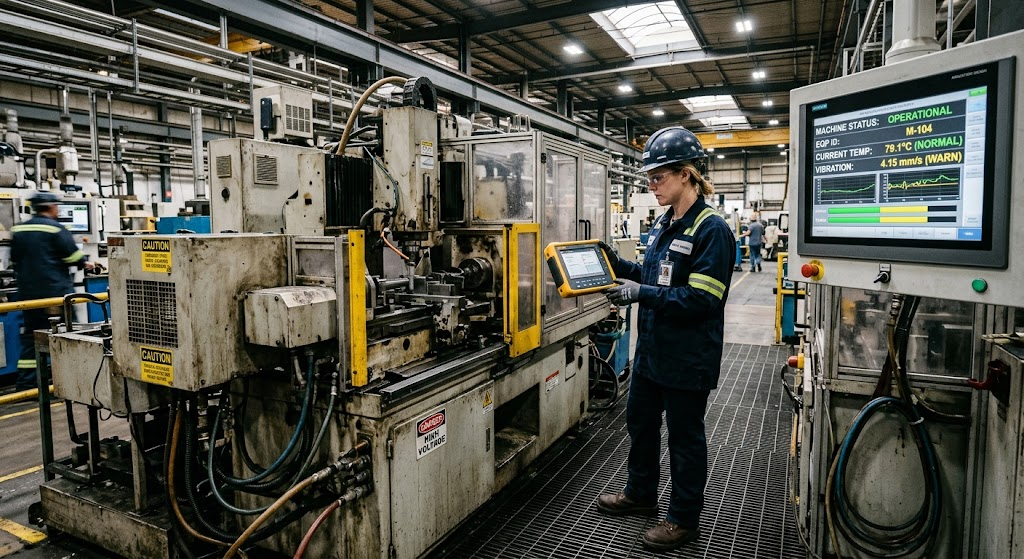
Equipment needs to function dependably for manufacturers, transport companies, energy companies and other organisations. Surprises can be a disruption to manufacturing, a delay in service, and add to repair expenses. Predictive maintenance is based on information gathered from sensors, inspection records, operating history and past equipment failures and uses this data to determine when maintenance needs to be performed to prevent failure. Patterns can be detected from data mining that may relate to wear, abnormal operating conditions such as overheating, unusual vibration, or a change in operating performance.
Machine learning models can then use appropriate measurements to come up with estimates of equipment failure risk and conditions that warrant additional investigation. A factory could, for instance, monitor how vibrations and temperature changes vary across machines, looking for machines whose patterns are very different from the norm. These warnings can be utilized by maintenance teams to investigate problems before they break down. Predictions are still subject to some uncertainty, however, and are only as valuable as a sensor’s measurement, maintenance record and frequent review of model accuracy.
Training Data and Predictive Variables.
What’s Training Data?
Training data is a data set containing historical examples that a predictive model learns from, to map relevant inputs to outcomes. For a sales forecasting project, training data might consist of monthly sales data, as well as the price of the products, advertising budget, seasonality data, and other relevant data. As a result, it might include historical customer activity and information on whether customers later canceled their subscriptions in a customer churn project.
The model analyzes these examples to look for relationships which might help it to predict results of new cases. Training data can be useful only if it is sufficient, of high quality, relevant and representative. If the data set is quite short or does not include all significant customers, the resulting model may not work well in other scenarios. Careful selection of training examples is thus a must, and the information should be representative of the context in which the model is to be used.
What are Predictive Variables?
The data that are fed into a model to predict an outcome are called predictive variables or features, or input variables. The result to be predicted is often referred to as the target variable. If a retailer is trying to predict sales in the future the variables used to make the prediction may be historical sales data, product prices, promotional efforts, and the time of year, and the number of units expected to sell may be the predictive variables. In a credit risk model, an appropriate financial information could be an input and the target could be the occurrence of a default on a payment in a specified time interval.
This is where a knowledge of the business problem and data collection is important: useful variables must be selected. An irrelevant/extraneous variable can decrease the performance of the model, and an important variable not included can cause the model to fail to recognize meaningful patterns. The variables also have to be known when making a prediction, otherwise the model cannot be used in a real situation because there would be no information available at the time of the prediction.
Why Model Validation Matters
Model validation is a procedure to determine if a predictive model is sufficiently accurate to be used for its intended purpose. A model can be a success if it shows good performance on the same data used to train it, but fails on the test data since it has learned all the details, instead of patterns. So, the organizations generally split up their historical data into training and evaluation parts to minimize this issue. Training data is used to train the model and a separate validation dataset can be used to compare approaches and make changes to the model settings.
A final test set constitutes an independent evaluation of performance. In forecasting applications, it is important to maintain the time order of observations; in this case, the model is applied to subsequent observations instead of future information. Validation can be used to uncover if a model can extend beyond the training data to new data and whether the model is accurate enough to make real business decisions.
How Prediction Accuracy Is Measured
Prediction accuracy describes how closely a model’s estimates match the outcomes that eventually occur, but the appropriate measurement depends on the type of prediction being made. For classification tasks, such as predicting whether a customer will cancel a subscription, accuracy can describe the proportion of predictions that are correct. However, accuracy alone can be misleading when one outcome is much more common than another. A business might correctly predict that most customers will remain subscribed while failing to identify many customers who actually leave.
Other measures, including precision, recall, and the area under the receiver operating characteristic curve, can provide additional insight into performance. For numerical forecasts, such as monthly sales, analysts may use mean absolute error or root mean squared error to measure how far predictions differ from actual values. Organizations should select evaluation measures that reflect the practical consequences of errors rather than relying on a single score to judge every model.
Interpreting Predictions Correctly
Even a well-validated model cannot guarantee that its predictions will match future events. A forecast is an estimate based on available evidence, assumptions, and patterns observed in historical data. For example, a model might estimate that a retailer will sell approximately 1,000 units of a product next month, but actual sales could be higher or lower because of changing demand, competitor activity, supply disruptions, or unexpected events. Similarly, a customer assigned a high churn probability may remain loyal, while a customer considered low risk may still cancel a subscription.
Decision-makers should interpret predictions alongside their uncertainty, business knowledge, and the possible costs of making incorrect decisions. Where appropriate, organizations can examine prediction intervals, probability estimates, and alternative scenarios instead of relying on a single forecast. Clear communication about uncertainty helps managers use predictive analytics as a decision-support tool rather than treating model outputs as unquestionable facts.
Challenges That Can Undermine Predictive Analytics
- Poor-Quality and Incomplete Data
The quality of a predictive model depends heavily on the information used to develop and evaluate it. Missing values, inaccurate measurements, duplicate records, inconsistent definitions, and outdated information can distort the patterns discovered through data mining. For example, if a retailer records returned products as completed sales without making the distinction clear, its demand forecasts may overestimate actual purchasing. Similarly, incomplete equipment maintenance records can make it difficult to identify the conditions associated with failures.
Biased sampling can also produce misleading results when some customer groups, locations, or operating conditions are underrepresented. Organizations should establish data quality checks, document how information is collected, resolve inconsistencies where possible, and investigate unusual observations before training models. These practices cannot eliminate every source of error, but they help reduce the risk of building predictive systems on inaccurate assumptions or unreliable evidence.
- Changing Conditions and Outdated Patterns
Historical patterns do not always remain stable. Customer preferences change, competitors introduce new products, economic conditions shift, and organizations adopt new technologies or operating procedures. A model trained on older information may therefore become less reliable as circumstances evolve. This problem is sometimes described as data drift or concept drift, depending on the type of change affecting the model or the relationship between its inputs and outcomes. For example, a sales forecasting model developed before a major change in customer purchasing habits may struggle to estimate demand accurately afterward.
Organizations should monitor actual outcomes against predictions, investigate changes in performance, and retrain or redesign models when necessary. Regular reviews are particularly important when predictions influence high-impact decisions. A model should be treated as a system that requires ongoing evaluation rather than a one-time project that remains reliable indefinitely after its initial deployment.
- Bias, Privacy, and Responsible Decision-Making
Predictive analytics can create risks when models rely on biased information, use personal data inappropriately, or produce estimates that are interpreted without sufficient context. Historical records may reflect unequal treatment or incomplete access to services, and a model can reproduce those patterns if they are not identified and addressed. In credit risk assessment, for example, an inadequately designed model could disadvantage certain groups because of biased data or inappropriate variable selection.
Organizations should evaluate whether their models perform consistently across relevant populations, use personal information only in appropriate and lawful ways, and provide suitable human oversight for consequential decisions. They should also explain the limitations of predictions to employees and other decision-makers. Responsible predictive analytics requires more than technical performance: it involves protecting privacy, examining potential harms, and ensuring that predictions are used in ways that are proportionate to their purpose and limitations.
Best Practices for Improving Predictive Analytics
Organizations can improve predictive analytics by following a disciplined process that connects technical analysis with clear business objectives. First, they should define the decision the model is intended to support and identify what a useful prediction would look like. Next, they should collect relevant data, check its quality, select appropriate predictive variables, and document important limitations. Analysts should compare suitable statistical and machine learning methods rather than assuming that one algorithm will work best for every problem.
Models must then be validated using data that was not used to train them, with evaluation measures chosen according to the task and the cost of prediction errors. Before deployment, organizations should also establish how predictions will be interpreted, who will act on them, and what additional checks are necessary. After deployment, they should monitor performance, review unexpected results, protect sensitive information, and update models when the underlying conditions change. This process helps ensure that predictive analytics remains useful, transparent, and aligned with organizational goals.
Conclusion
Predictive analytics and data mining help organizations transform historical information into practical estimates of future outcomes. By discovering patterns in customer behaviour, sales transactions, financial records, and equipment performance, data mining provides a foundation for models that support forecasting and decision-making. Statistical modelling and machine learning extend this process by estimating relationships between relevant variables and applying those relationships to new information. These methods can improve sales forecasting, customer churn prediction, inventory planning, credit risk assessment, and equipment maintenance when they are developed and used appropriately.
However, successful predictive analytics requires more than selecting an algorithm. Organizations must prepare reliable data, choose relevant predictive variables, validate model performance, and monitor changes over time. They must also recognize that predictions are estimates rather than guarantees and that inaccurate data or biased assumptions can undermine results. When organizations combine sound analytical methods with responsible oversight, predictive analytics becomes a valuable tool for planning ahead, managing uncertainty, and making better-informed decisions.