Introduction
Machine learning is a vital component of current technology, which is used for product recommendations, spammers in emails, fraud detection systems, voice assistants, and house-price prediction. These applications may sound smart, but they rely on some processes that enable computers to recognise patterns from data and to predict based on these patterns. Machine learning is a field of artificial intelligence that allows computers to discover relationships in examples rather than having to be programmed with all of the rules. But, creating a robust machine learning system is more than just picking an algorithm and hoping it will give accurate results. To achieve this, developers need to gather the necessary data, create the datasets, select the useful features, train the models, test their performance and follow their results after deployment. This insight into these phases can help give the answer to why some machine learning applications work well, and others yield inaccurate predictions. It also demonstrates that effective machine learning requires planning, data integrity, the use of relevant algorithms, and ongoing development.
Machine Learning Workflow
The machine learning workflow is a series of actions associated with developing, evaluating, deploying, and maintaining a machine learning model. Every stage adds to the quality of the system at the end, and any errors produced in the early stages will impact all the stages thereafter. For instance, a model that is available for prediction but has insufficient or incorrect data may still make bad predictions. In the same manner, a model with great performance during development can fail to work well with information that the model needs to process after deployment if the data used for development is different from the data that is encountered in real-time.
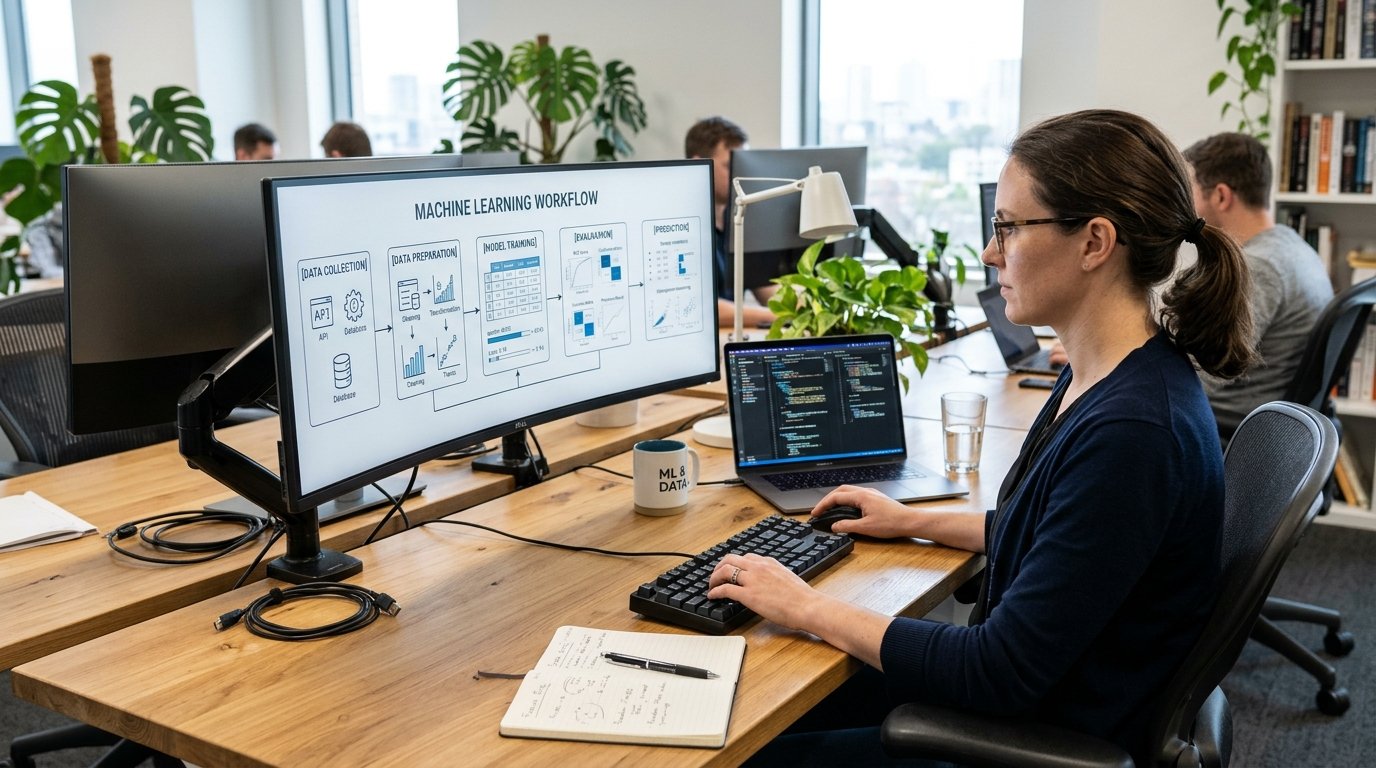
When programming a machine learning system, it is important to see the entire process of machine learning to view this as a formal engineering process instead of a magic technology that always has the right answer. While the process may vary for each project, most will involve data collection, data preparation, feature selection, model training, validation, testing, deployment, and monitoring. These stages are interconnected and are used for converting the raw data into a usable system, which can be used for decisions and solving real life problems. The complete machine learning workflow provides further information about this process.
Why The Workflow Matters
A systematic workflow enables teams to detect problems at an early stage, evaluate various options and to decide if a model is ready to be used in practice. It also prompts developers to document their choices, objectively measure performance results, and think about what would happen if they were to run the system outside of the development environment. For example, a company building a fraud detection model needs to know if the data consists of real transactions, if the features chosen are helpful and if the model will detect fraudulent transactions without blocking too many valid payments.
If key components are not included, the model may look successful while it is being developed but fail when it is put to use by customers. The risks are minimised by having a clear workflow design that splits up the development into smaller steps with clear goals and evaluation criteria. It also allows for improvements to be made a lot easier as the developers can check if this is due to data quality, features selected, algorithm choice, or real world changes.
Step One: Data Collection
The first big step towards machine learning is data collection, for the models need to learn patterns from examples. The information collected will depend upon the problem being solved, the prediction being made and the environment in which the model will run. The model for predicting house prices, for instance, might include data on the size of the house, its location, the number of bedrooms, the age of the building, and data on previous selling prices of the houses. The information may be provided in properties databases, real estate agencies, public records, or transactions that have been confirmed. In contrast, a fraud detection system can leverage on transaction size, time, merchant types, payment geolocation, and fraud history. Gathering vast amounts of data isn’t the entire solution, it must be relevant to the problem at hand and collected responsibly. Developers need to be mindful of privacy, consent, security and relevant data protection laws. They also need to make sure that there are sufficient examples of the dataset to cover different scenarios. All other steps in the machine learning process rely on a well-gathered dataset.
Gathering Data from Relevant Sources
Before gathering information, developers need to identify the prediction that they want the model to make and all the information they might use to generate that prediction. The goal of a house-price project could be to predict the sale price of a home based on features known prior to the sale. Historical sales data would include data on properties and actual sales prices, and property descriptions would include the potential explanatory variables.
It is important for developers to assess for each source whether it is reliable, detailed and representative of the market in which the model will be implemented. The prices for houses might not be representative in some cities and not in others, as infrastructure, demand, and economics vary. Additionally, it’s essential that the information is legally accessible for the use that’s planned. In setting clear collection requirements, teams do not gather too much information and can ensure that the information they collect will reflect the project’s actual goal, rather than irrelevant details.
Step Two: Data Cleaning and Preparation
After information has been gathered it needs to be prepared for effective use in the training process. Data in the real world may have missing values, duplicate records, inconsistent formats, incorrect data, and unusual observations. For instance, the housing dataset may store house sizes using varying measurement units, or have houses without any information about the number of bedrooms, or have an incorrect selling price. Failure to address these problems may result in the learning of false correlations and inaccurate estimates by the model. Data preparation includes detecting these issues, rectifying errors as much as possible, determining how to deal with missing data, normalising data formats and eliminating duplicate data if applicable. Developers need to also explore the unusual values, and not simply remove them as some unusual observations may be legitimate. For instance, even an extremely high-priced property, such as an expensive house, can be considered to be sensible even if it is priced significantly higher than the other properties in the set. Consistency is achieved through effectual preparation, and it helps the machine learning algorithms to interpret the information more easily.

Understanding Data Quality
Data Quality is the appropriateness of data for the specific purpose. Key features of importance are accuracy, completeness, consistency, relevance, and timeliness. Correct data is data that is accurate and complete data is data that is necessary for the task. Consistent data is compatible in format and definition, relevant data is used in making the prediction, and timely data is relevant to the conditions of the time of use of the model. When predicting house prices, the sales data alone may not reflect the market’s prices because of lagged data, and inaccurate house dimensions can skew the correlation between size and price.
Before training, developers should look at these issues, and record the choices made when cleaning the data. They also need to pay attention to the fact that information obtained in the future cannot affect a model that is designed to predict information from the past. This is called data leakage and may lead to an overly accurate model during evaluation, but to subpar performance in production use. Problems can be avoided with reliable data quality practices.
Step Three: Feature Selection and Engineering
Features are the pieces of information that a machine learning model uses to recognize patterns and make predictions. For a project to forecast house prices, it might incorporate features such as the number of bedrooms, location, distance from major transport links, property age and floor area. Feature selection aims to determine the set of variables among the ones available that are most useful for solving the problem. Adding all of the variables that are collected can complicate things without adding value, particularly if some variables provide unimportant data or repeat other variables.
For instance, a place’s identification number typically will not reflect its market value and its location can be important because it gives clues to local demand and services. Developers can leverage domain knowledge, statistical analysis and model-based methods to compare features and to find useful inputs. They should not, however, take it for granted that a feature that is strongly correlated with prices in one dataset is useful. The relationship should be coherent and sensible for the task of prediction and should also be meaningful for new properties.
Feature Engineering in Practice
Feature engineering is the process of deriving or manipulating features to make meaningful patterns more explicit for the model. For instance, developers might be able to determine the age of a property based on the year it was built or the selling price of a property based on the floor area. They could also cluster locations into meaningful neighbourhoods based on the data that is available if that is appropriate. Such changes can aid in the representation of relationships that may not be evident in raw data. Each engineered characteristic, however, should be measured based on data that would actually be available when making predictions.
They should also keep parts of the preprocessing in mind: numerical values may need to be scaled to fit within the appropriate range, and neighbourhood categories might need to be encoded – both this should occur during training and extended to validation, test, and production data sets. This helps to avoid the information in the evaluation datasets from affecting the training process. Carefully crafted feature engineering can help boost performance; more variables are not necessarily better variables to add. The aim is to give inputs that are informative but not too complicated or misleading.
Step Four: Splitting the Dataset
Typically, developers will split the prepared data set into the training, validation, and testing set before training the model. Each part has a specific function to test the model’s ability to generalise from what it has observed. The training set helps the model learn the nature of the relationships between the “input features” and the “known outcomes”. The validation dataset can be used by the developers to compare the algorithms, fine-tune the parameters, and determine which set of algorithm parameters works best. The test data set is held back until the bulk of the project decisions have been settled.
For instance in a housing dataset, 70% of the data could be used for training, 15% for validation, and 15% for testing, but the ratios of the split are dependent on the dataset and the project requirements. The splitting method used must be representative of the problem and must be chosen by the developers. A time-based split may be more suitable than a random split when predicting future prices because you can determine if historical data can predict future prices. Carefully split to make performance measurements more meaningful and minimise risk of inappropriate conclusions.
Step Five: Model Training
Model training is the process for learning relationships that a machine learning algorithm uses to learn from the training dataset. In this process, the algorithm verifies its forecast against a real result and tunes its parameters so as to minimize the difference between its prediction and the real outcome in a specified learning goal. It varies depending on the model being used. For instance, a linear regression model can be used to estimate the relationship between the input variables and a numerical target, which is a good starting point for predicting house prices. More complex models, like decision trees and random forests, are capable of modelling non-linear relationships and interactions between features. The developer(s) will need to choose an algorithm that is appropriate to the problem, the data, and the desired interpretability. In a housing project, the model could become aware that bigger houses tend to yield higher prices, and that location and the condition of the property have an impact on the final estimate. Training does not imply that the model knows about housing in the same way that a human expert does. Instead, it learns mathematical patterns from examples it is given, and the value of the patterns is contingent upon the quality and representative nature of the training examples.
Selecting an Appropriate Algorithm
Different machine learning algorithms present different sets of strengths and which to use is a choice that depends on the problem at hand and its practical requirements. Linear regression puts forth a very simple and at the same time interpretible base line for which to predict numerical values. Decision trees are able to represent more complex relationships via a series of decision rules, also random forests which is an ensemble of decision trees improve predictive performance in many fields. Also we see that gradient boosting which does very well on structured data sets may require more fine tuning.
It is a good practice for developers to first set a baseline model which in turn gives them a point of reference for what improvements which may be obtained from more complex methods. The best algorithm is not the latest or the most complex out there. What is best is the one that does well on data it has not seen before, that also meets the run of the project and which also is maintainable. It is better to train a few good models and go with the results than to choose an algorithm based solely on its popularity or what is thought to be its strength.
Step Six: Model Calibration and Hyperparameter Optimization
Validation is a process which developers use to see how well a trained model will do on data it hasn’t been exposed to which was used in its training. At this stage teams will compare different model sets out and tune hyperparameters which are either set before or during the training process as opposed to those which are learned as part of the model. Examples of this are the depth of a decision tree, the quantity of trees in a random forest, and the learning rate of some algorithms. Also at this point developers will play with different settings using the validation set and choose the models which present a good trade off between performance and complexity.
For instance a very in depth decision tree may fit training examples very well but do poorly on new data. A shall also may do less well on the training set but will put out more reliable results for new properties. Validation helps to identify this issue before going into full scale testing. In the case of small data sets we see techniques like cross validation which run the train and validate processes on different subsets of available training data which in turn gives a more stable performance estimate.
Identifying Overfitting and Underfitting
A model may be too basic or not have enough training to capture important data relationships. For example a model which tries to determine home prices based only on the average sale price will do a poor job of taking into account large differences in size and location.
Developers may look at training and validation performance to identify these issues. A large gap between the two may indicate overfitting, while poor performance on both may point to underfitting or a lack of good info. Appropriate model complexity, useful features, sufficient representative data, and proper regularisation techniques can help to solve these issues.
Step Seven: Model Assessment and Performance Analysis
After choosing a model and going through the primary development stages, we evaluate it using a separate test data set. At this point we are to get an idea of how well the model will do on out of sample data. Testing should only take place after the model structure has been chosen; to put the model through constant change in response to test results does not give a true picture of its performance. What performance metrics to use depends on the type of prediction the model is to make. In house price prediction which is a regression issue we see mean absolute error, mean squared error, and the coefficient of determination (known as R squared) as common.
Mean absolute error reports the average prediction error in the same units as the target variable. If we have a mean absolute error of ₦2 million the model’s predictions are off by that amount on average which is reported in Nigerian Naira. Not that each prediction is off by exactly that amount, some will be higher some will be lower. This is a tool to help developers determine if the model performs well enough for its use.

Accuracy and Prediction Errors
Accuracy is a common term in machine learning but what it means varies by what the task is. In classification issues for instance which we see in fraud detection we tend to think of accuracy as the ratio of correct predictions. So a model which out of 1,000 transactions correctly classifies 950 has 95% accuracy. But also accuracy has its limitations which we see in imbalanced data sets. If for example only a small percentage of transactions are fraud then a model which labels all as non-fraud will have high accuracy but will not detect any fraud at all. Thus it is a good practice for developers to look at other metrics like precision and recall in addition to accuracy when they are assessing classification models.
Precision which in this context is the proportion of transactions identified as fraud that actually are, and recall which is the proportion of actual frauds which the model in fact does identify. For home price prediction which is a regression problem we use a different set of metrics as our goal is to put a value out rather than put something in categories. We should choose the right metrics for what we are trying to do which in turn gives us a more full picture of the model’s performance instead of a partial one.
Step Eight: Model Release into Production
Deployment is the process of putting a trained model to work. As which application it is for will vary a model may be put into a website, mobile app, business platform, internal report tool, or automated system. In the home price example a real estate site may have a feature which allows users to input a home’s size, location, number of bedrooms, and age which in turn gives them an estimated sale price. Once the info is given the application passes the input to the deployed model which in turn looks at the features and puts out a prediction.
Before going live developers must see to it that the production environment does the same pre processing which was done at training time. A model will perform poorly if the application reports different home sizes, handles empty fields in a different way, or uses a different feature order. Also teams should look at response times, infrastructure costs, access controls, data security, and what incorrect predictions may bring. Deployment is not complete once the model is run successfully. The surrounding application has to do its job well and also present results in a way which users can understand that we are giving them an estimate and not a definite result.
Batch and Real-Time Predictions
Machine learning models put forth different prediction methods which in turn depend on the urgency of results. In batch prediction past sets of data are analyzed at set times. For instance a real estate firm may run a process overnight which estimates the values of large sets of properties which in turn updates the companies’ internal database for the start of the work week. Real time prediction produces an estimate as soon as a user or some other system puts in a request. A property valuing site may use this to immediately put out an estimate once a visitor puts in the required info.
Batch processing is best for when an instant response is not required, real time systems do well when predictions are used in the making of interactive decisions. Also both of these do in fact require reliable data pipelines, proper resources, and the model versions to be the same. Also it is a good idea to have in place what to do with bad input, service outages, and abnormal outputs. Which approach to use should be based on business requirements, technical issues, and the issue at hand rather than the assumption all machine learning applications have to be real time.
Step Nine: Management and Model Support
A put into production machine learning model will see its performance change with the real world which is in constant flux. A housing model which was trained on past sales may break down in the face of variable interest rates, the introduction of new transport infrastructure, or shift in demand between neighborhoods. By monitoring we mean that teams will see these changes and determine if the model is still performing to the mark it was intended to. We see developers track prediction errors as real selling prices come in, watch for missing or out of the ordinary inputs, and study if the present set of data is what was used for the model’s training.
Also in this group of changes which indicate data drift, we see that changes in the relationship between input features and actual results point to concept drift. Also included in the monitoring should be operational metrics like response time, service availability, and what we see in terms of technical failures. A model may still do a good job of prediction but if the application is down or very slow the value is lost. Regular monitoring gives teams the info they need to track down issues, maintain the model’s reliability and decide when a model requires retraining or replacing.
Retraining and Growth
Retraining is the process of taking a model and updating it with new or more data which in turn causes it to react to change. In the housing example we see that which developers may do is take in verified recent sales info and check if the improved model does a better job at predicting present prices. But also it is not true that we should retrain just because we have new info. The data has to be of good quality, properly prepared and evaluated to see that the new model does at least as good a job as the present one for the intended use. Also teams should keep what was a proven past model in case a new one does not perform as well.
Also they should document model versions, training data sets, evaluation results and details of what was done at deployment to make it easy to look back. As for continuous improvement this may include changing features, tuning hyperparameters, getting better examples, or trying out a different algorithm. In some cases we may find out that the model we have is still doing fine and does not need to be replaced right away. A disciplined approach to maintenance is what will see that updates are based on what the data tells us and not the assumption that new is always better.

Common Problems in the Machine Learning Process
Machine learning projects also see many issues which are present even as developers use a proven workflow. We see that poor data quality puts forth false patterns, and also that which is not representative in the data used for training sets causes a model to do poorly for groups or situations that are not covered enough in the training. Also, data leakage which is an issue of’ that models perform beyond what is present in the training data sets and we have overfitting which in turn prevents a model from performing well with new and different data. Also teams may put forward metrics which do not in fact represent the business goal or they may roll out solutions without putting in place proper monitoring.
Also of great importance are ethical and privacy issues which play out especially when we are dealing with personal, financial, or location based info. Teams must look at if their data has historical in-built biases and also if in fact the predictions may put some groups at a disadvantage. Also they must look at explainability, accountability and the what if results are wrong. In home price prediction for instance an inaccurate report may play a role in a large financial decision which is why users should be aware of the range of possibility and not treat a machine’s report as a sure thing. Identifying these issues early on gets us toward responsible development and in that way organizations are able to put out systems that are not only from a technical stand point very effective but also appropriate for what they are put to use for.
Conclusion
A model may not present reliable results which is because of the complex algorithm used. Also its success is tied to the quality of the data, what evaluation methods are used, if the system is put in properly and how it is maintained over time. By going through the full process of machine learning you make the field more transparent which in turn helps the audience see what machine learning can do and what it can’t.
In the end machine learning isn’t about producing perfect answers out of thin air; it is about the development, testing, and maintenance of systems which put out good enough results based on what we have available and do so in a consistent manner within a certain known scope.