How machine learning works is easier to understand when you see how computers learn patterns from data instead of relying only on pre-coded instructions. We don’t program the computer to perform a task in each and every situation; instead, we present it with data and pick out a method that will allow the system to identify and use the relationships within that data. This is the base for many of the tech tools we use daily, which include spam filters, recommendation engines, fraud detection, image identification, and predictive models.
Training sets, variables, algorithms, models, forecasts, and analysis are all important parts of machine learning. A machine learning system learns from data, develops a model based on that data, and then uses that model to make predictions on new info. These elements of the process provide a good base from which to study artificial intelligence.
What Is Machine Learning?
Traditional computer programs are a product of programmers’ explicit instructions. For instance, a simple program may be designed to run a certain function at the occurrence of a given condition. In machine learning, we see a different approach. Instead of manual rule writing, developers present the algorithm with examples, which it then uses to identify patterns. A spam filter, for example, which is made using machine learning, will study many emails that have been tagged as either spam or not and, in that study, will determine what features are common in the former.
The product of this learning process is what we call a model. The model puts into form what the training data has identified and also is applied to new info. A business may train a model which looks at customer info to put out a prediction that a person may cancel a subscription. The model looks at info like customer action, use, and past behavior before it puts out a prediction. As the prediction is based on what was learned instead of hard fact, the model has to be very carefully tested.
The Main Parts of Machine Learning
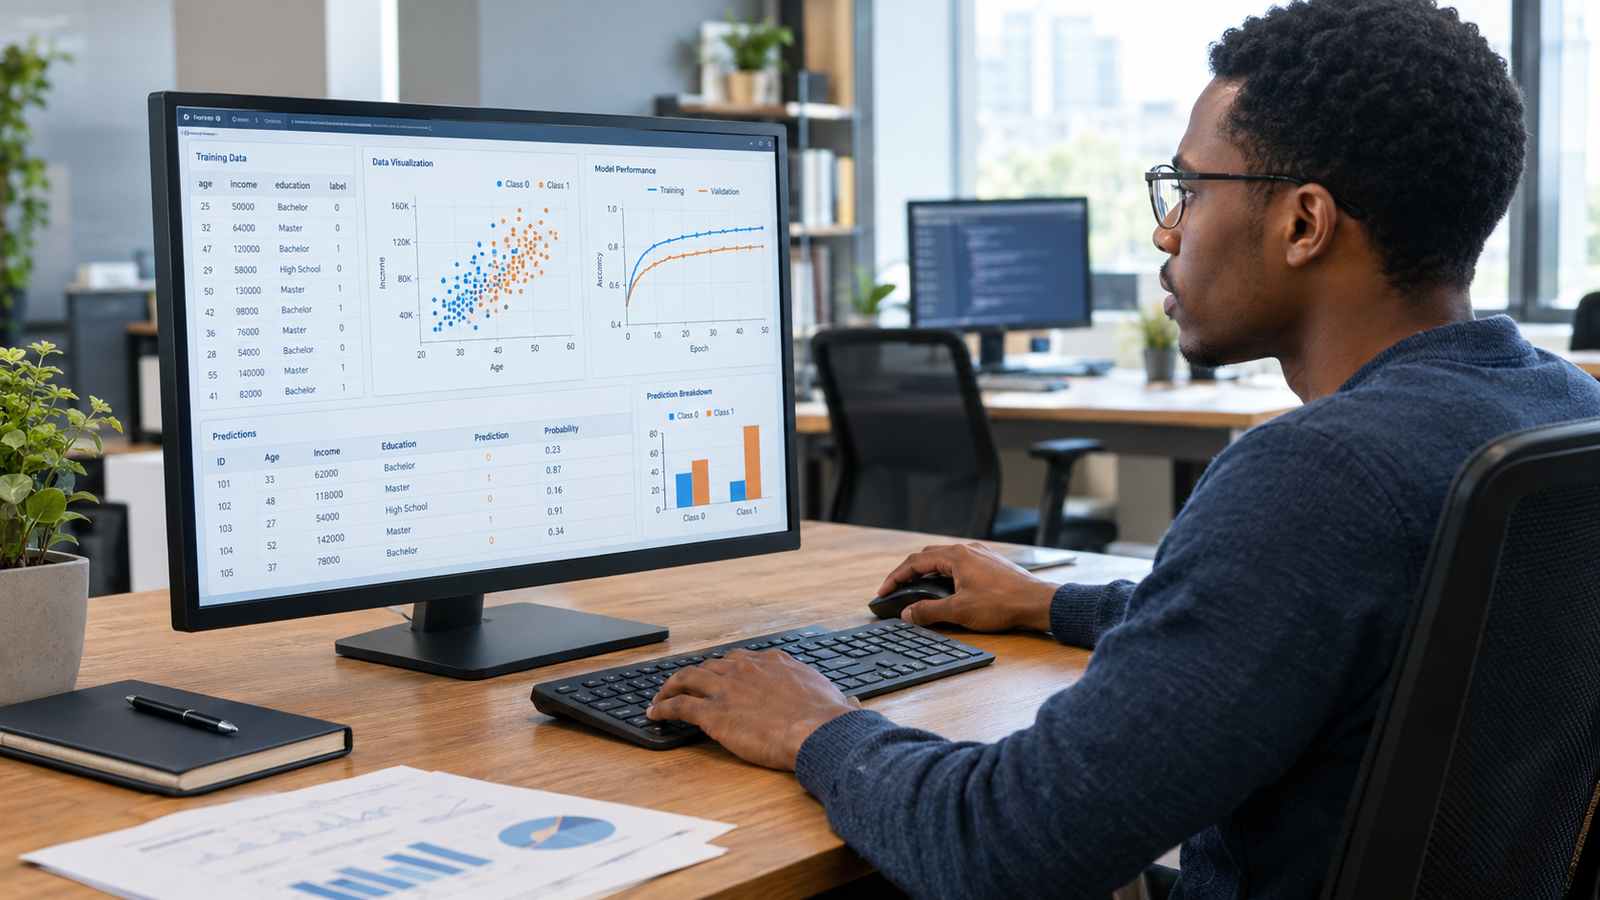
Training data is what a machine learning system is fed to learn from. This can be in the form of text, numbers, images, sounds, customer records, or any other type of info. Features are the elements of data which we present to the model to get it to see patterns. For example, a model that predicts home prices may use location, size, age, and number of bedrooms as features. The algorithm is what we use for the model to identify relationships in the data, and the model is the result of that training.
Good-quality data is key, which in turn allows a model to learn well. If we input flawed data which has errors, is missing info, or appears to be out of the norm, the model may outperform what is seen in the real world. That’s to say, we are not just looking at which algorithms to choose for machine learning. Careful data analysis helps us prepare the data, choose useful features, train the model, and test its performance on new data.
How Machine Learning Works: Learning From Data
Training is when a machine learning algorithm goes over examples and, at the same time, tunes the model, which in turn does better at the task at hand. In a prediction problem, the model puts forth a first guess, which is then checked against the right answer. The algorithm, which is at the core of the machine learning process, then changes the model to reduce the error. This process may be repeated many times till the model is able to learn which patterns are most useful for the task.
Supervised learning, unsupervised learning, and reinforcement learning are three major approaches. In each case, the data is used differently. Supervised learning has, of course, known answers; unsupervised learning goes in to find out what the data is about without us putting in what we expect to see; and reinforcement learning is about taking actions and learning from the results.
Supervised Learning
In supervised learning, the training data includes known results. For instance, think of a computer we are training to recognize spam emails. We may present to it thousands of emails which are labeled “spam” or “not spam.” The algorithm will study these examples and identify patterns which in turn will allow it to tell the difference between the two. Once the model is trained, it is put to use in looking at a new email and determining which group it is from.
Supervised learning is used in classification and regression. We see classification as action which is to put info into categories like spam or not spam. In the case of regression, we are talking of predicting a number out of a set of values, for example, sales, temperature, or house prices. Also, because during training of supervised learning we have known answers at our disposal, we are able to measure its performance by the comparison of predicted results with the real results.
Unsupervised Learning
Unlabeled data is what unsupervised learning deals with. The algorithm doesn’t have pre-defined categories to put the data in; instead, it looks for trends, similarities, or clusters in the info. For instance, a company may use info on its customers to find groups of people which share the same buying trends without first determining what those groups should be.
One very common strategy used is that of clustering; we see which sets of similar data points are put together. This is useful to businesses in terms of looking at customer action, sorting through info, or noting out-of-the-ordinary trends. Also, as opposed to supervised learning, which may present a single right answer, in unsupervised learning there is not always that clear a right answer, which means people have to look over the results and determine what the presented patterns mean and if they are of value.
Reinforcement Learning
It plays out many scenarios and, from that, develops tactics which in turn produce better results.
This kind of learning is applicable for issues which play out over time. We have seen it used in the fields of games, robotics, and control systems. Also, what we see is that the system does not get the right answer for each example as in supervised learning. Instead, it learns from experience and feedback, which makes the issue of reward design very important in this type of learning.
Training a Machine Learning Model
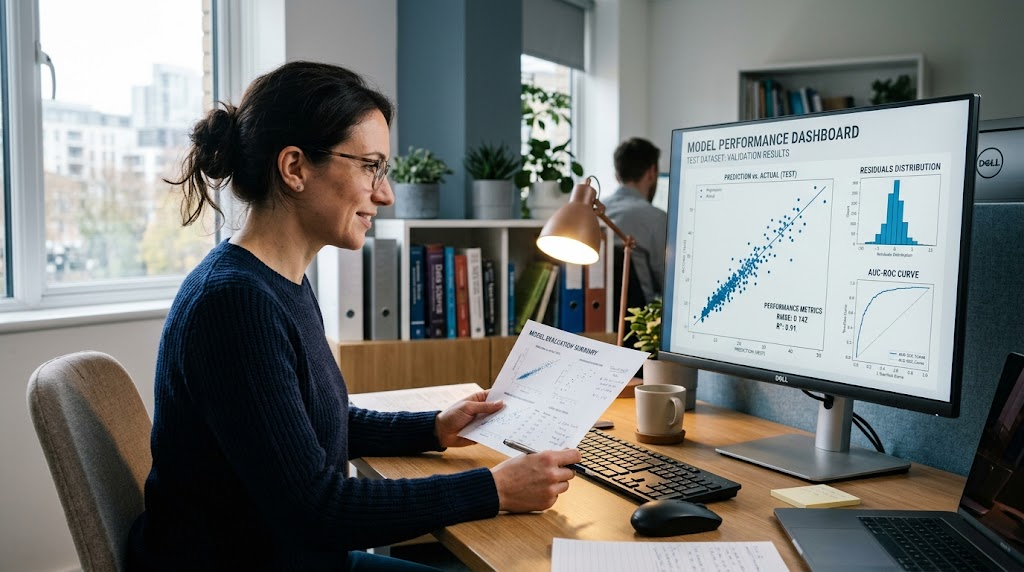
Training is a phase in which the model is improved via the use of data. In supervised learning, the model’s outputs are compared to known results, and the algorithm fine-tunes the model to reduce error. This process may be repeated many times, which in turn sees the model improve its identification of patterns.
However, do not present models which simply recall the training examples. A system that does very well on what it has seen before may do poorly on new information. That is what overfitting is. To reduce that which we see as a risk, developers usually separate data into training and testing sets. The model learns from the training data, and the testing data is used to see how well it does with unseen examples.
How Models Make Predictions
After training, models get to work on fresh input; this is what we call the stage of inference. In the case of a recommendation system, that may look at some past activity of a user and use it to inform a trained model. Also, it could be that the model will present that a certain user may like a new video or a different piece of music. Also, an image-based system, given new images, will run them through a trained model and come out with a prediction as to which set of objects or categories these are.
It can predict which category an email will fall into, spam or not, what the value of a home will be, what object is present in a picture, or that a certain transaction is maybe out of the ordinary. In practice, we see that model results are put to use with other software and also may go over a human’s review before we see any large-scale action.
How Machine Learning Models Are Evaluated
A model has to be assessed, which determines its predictive power. We see that different tasks require different metrics. For classification, we see that accuracy, precision, and recall are common. In numerical prediction, what we look at is how far off our predicted values are from the real ones. These metrics present to us how the model does.
Evaluation also includes how the model performs with new and changing info. A fraud detection system may report on which novel types of suspicious activity it is seeing, at the same time a recommendation system may note shifts in user behavior. As real-world data changes over time, machine learning systems may require being put under watch, tested out, updated, and retrained to keep them relevant.
Why Machine Learning Powers Modern Technology
Machine learning is at its best with the large-scale data sets which today’s applications produce, which people are not able to analyze by hand. We see in spam filters that they recognize patterns in what is unwanted, in fraud detection systems which put out of order what is atypical, and in recommendation systems which identify patterns in what users do. Also, image recognition systems have the ability to go over visual info at a much faster rate than manual inspection in many cases.
Predictive tools, which is what we are seeing, put forth similar concepts to project into the future and to identify which may be issues we should pay attention to. In business, machine learning can help forecast demand, analyze customer behavior, identify unusual activity, and support decision-making. They are powerful, but results from these still do depend on the quality of the data they are given, how they are designed, and how they are put to the test.
Machine Learning and Artificial Intelligence
Machine learning is a key element in what we see in artificial intelligence. AI is a large field which includes systems that perform tasks related to capabilities like language comprehension, object recognition, reasoning and planning, and making decisions. Machine learning supports many of these in that it enables systems to identify patterns in data.
Artificial intelligence is a wide field which in turn includes machine learning as a key method we use to develop intelligent systems. In today’s world, we see that which is often very complex to program in detail, which is why we use machine learning instead. Also, what machine learning does is present a flexible approach to dealing with large-scale problems.
Conclusion
Machine learning is the study of computer programs that identify patterns in data which in turn they use to make predictions and decisions. What it does is present to the computer training data which includes features, which in turn the computer analyzes via algorithms which develop models, which do the predicting, and we in the end evaluate results. In supervised learning, we use examples that are labeled; in unsupervised learning, the computer finds out what the patterns are in data which does not have labels; and in reinforcement learning, we present actions which the computer then uses to get feedback.
These ideas present how machine learning supports a large part of what we see in our everyday technologies, from spam filters and recommendation engines to fraud detection and image recognition. After you have the basics down, more complex topics like neural networks, deep learning, and modern AI systems become much easier to understand.