Introduction
For businesses that rely on digital systems for data storage, payments processing, customer communication, and everyday operations, cybersecurity has emerged as a key concern. As enterprises start to expand their online presence, they create vast amounts of data such as network logs, logins, financial transactions, emails and alerts from systems. These records contain patterns that can uncover cyberattacks, fraudulent trades, unauthorized access and more.
However, that is inefficient, and not always effective at identifying threats quickly enough. One practical solution is the use of data mining for finding meaningful patterns in the large volumes of data and to detect activities that should be investigated further by the security team. The integration of statistical analysis, machine learning, and pattern recognition can enhance organizations’ threat detection, incident investigation, and response capabilities to deal with new security threats.
What is Data Mining in Cybersecurity?
Data mining is a process of analyzing large amounts of data to uncover relationships, patterns, trends, and unusual observations that are useful. In the cybersecurity field, it allows organizations to convert security data into actionable insights. For instance, an enterprise could see thousands of log-ins per hour from which it is hard to distinguish normal user activity from an attack. Data mining systems can analyse login counts, logins from locations, device information, failed login attempts, etc. and detect potentially malicious activity.
These systems can be used to compare current activity to historical data and identify if this is outside of the normal range of activity. This process can be supported by various data mining techniques such as classification, clustering, association rule mining and anomaly detection. These techniques can be used effectively to help security organizations prioritize investigations and make informed decisions.
Key Data Mining Techniques Used in Cybersecurity
Depending on the type of threat sought, and the available information, various analytical techniques are used by organizations. A labelled example is used to train classification algorithms to recognize the difference between categories of items – for example, between legitimate transactions and known fraudulent transactions. Grouping similar records together without needing to categorize each record beforehand, enabling analysts to find new patterns, which they could not have found otherwise. Association rule mining is used to find links between events that occur, such as the occurrence of several unsuccessful login attempts that are followed by an abnormal successful login.
Anomaly detection can be used to detect observations that vary significantly from the “expected” behaviour, and predictive modelling can be used to estimate the probability of specific events occurring using historical data. These techniques can be independent or be used in combination in a security monitoring system. They work best when the information being presented is as accurate as possible, the analytical model is appropriate, and the security professionals are able to properly read and understand the results. No one method is a foolproof way to detect every form of cyber threat.
Data Mining in Anomaly Detection
Anomaly detection is a critical application of data mining to cyber security, since many cyber attacks generate activity that is different from what a system is typically expected to do. A security system can detect if an employee suddenly downloads a lot of confidential information, a server that is making connections to other external addresses, or a user trying to access something that they don’t usually have access to in their work. Data mining models are set up to create a baseline of behaviour from past data and then compare any new events to that behaviour. They can employ statistical thresholds, clustering algorithms, or machine learning models to assign an anomaly score for each activity that is observed. Security teams can analyze top-scoring events to see if they’re signs of an attack or a hacked account or if they’re normal operations. Anomaly detection is especially useful if an attack is not a past occurrence, and while unusual behaviour is not sufficient to show that something is a security incident, it is good to catch it.
Threat Identification and Network Traffic Analysis
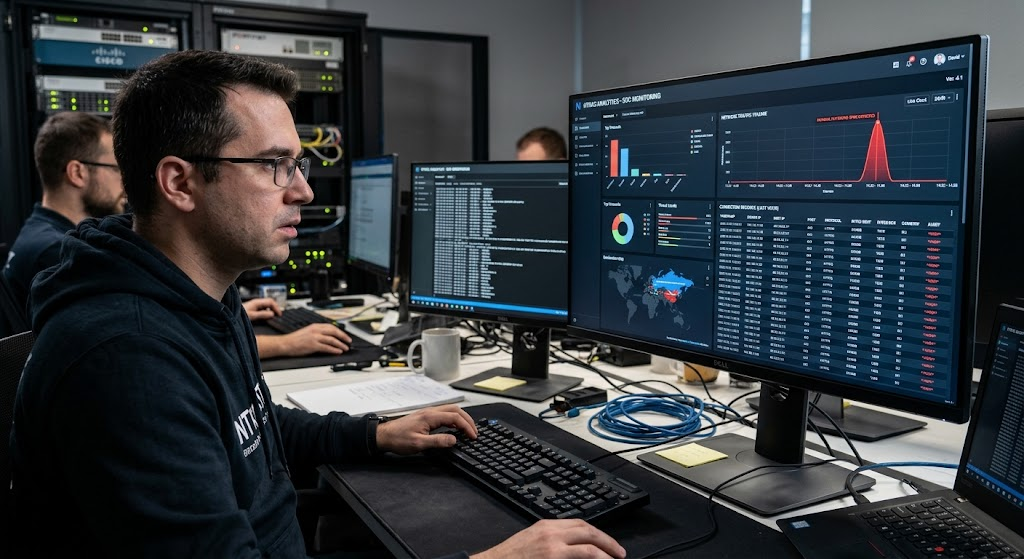
Network traffic analysis is the process of analyzing the communication between computers, servers, applications and other networked devices to detect security issues. Various information is gathered, including connection time, destination address, amount of traffic, communication protocol and duration of connection. These records can be used by data mining systems to detect unusual communication patterns, multiple attempts to connect, unexpected transfers of data, and more signs of suspicious activity.
For instance, if a computer continues to reach out to an external server that it has not encountered before, it might be sending messages to a malicious server, and if traffic to another external port suddenly surges it could be a sign of unauthorized data transfers. Clustering can be used to group devices communicating in similar ways so that analysts can detect machines that are acting in different ways from other machines in the same environment. The other benefit of network analysis is that it can show coordinated activity across multiple devices, which allows you to investigate attacks that may not look like much when seen on a per-device basis.
Behavioural Profiling and User Activity Monitoring
Behavioral profiling assists an organization to understand user (and device) interaction patterns of normal use. A typical model can take into account when people log in, which apps they use often, how much they transact, what devices they use, and the common way they use the resources. If a sudden change in behaviour, an account may be flagged for further verification or investigation. For instance, a typical employee who may work with a limited number of business applications could suddenly try to access sensitive data from across multiple systems with access restrictions.
Likewise, a customer account that typically places a few low dollar orders might suddenly place many large orders. Such changes may be a sign of account compromise, an insider threat, or fraud, but can also be due to legitimate reasons. Organizations that regularly update their behavioural profiling models will benefit most from behavioural profiling. It will also not presume that differences in normal behaviour are a sign of wrongdoing.
Phishing Detection Based on Data Mining
Phishing is a scheme where attackers disguise their messages as legitimate ones and try to trick people into sharing their passwords, banking details or other private information. Suspicious messages can look like a link or attachment from a bank, online service, employer, or someone you know and rely on, and ask you to click on a link or open an attachment. By examining the characteristics of e-mail, sender information, content of e-mail, URL, properties of attachments, and historical reports on threats, data mining aids in the identification of phishing attempts. Classification models can be fed with previously known phishing messages and implement the differentiation between common warning signs and those from legitimate email messages.
Other systems look at unusual message patterns, suspicious domain names and links that lead to unexpected destinations. Natural language processing is also able to detect misleading language, impersonation attempts, and urgent requests that are meant to sway recipients. Phishing detection systems need to be updated frequently, and backed up by email security, anti-attachment scanning, security awareness training, and safe browsing tools, as attackers often change their email messages to evade detection.
Intrusion Detection and Security Log Analysis
An intrusion detection system (IDS) is a computer system that detects intrusions into a network or computer system. Data mining can reinforce these systems by feeding them with the event logs produced by firewalls, servers, operating systems, applications, authentication services and endpoint security products. Analytical models can be used to detect the inter-event relationships that could point to a coordinated attack rather than examining each event individually. For example, if you log in lots of times and then log in successfully it may be followed by using privileged resources and an unusual transfer of data.
Combining these events can help identify an intrusion that only one event wouldn’t necessarily indicate. Security information and event management systems can aggregate relevant logs and analytics can detect suspicious log sequences and rank alerts. Next, the security analysts review the compromised accounts, devices, and network connections to determine how and what has occurred and what action should be taken.
Identifying Unusual Financial Transactions and Fraud
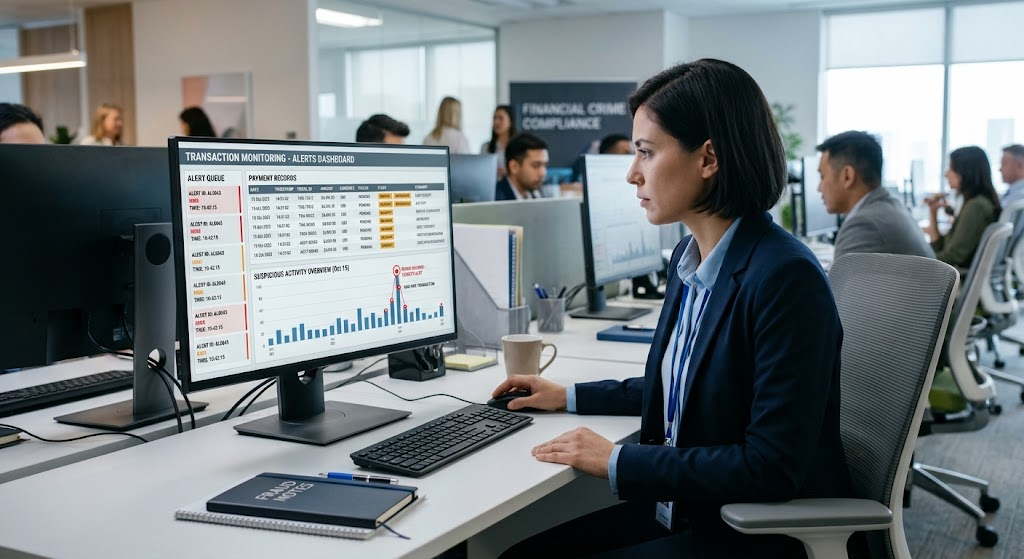
Data mining is used by financial institutions and online retailers, payment processors and others to detect fraudulent transactions. These organizations comb through information like how much you pay, how often you pay, what kind of merchants you pay, what your accounts have been like, what kind of devices you’re using, and where you’re transacting. A fraud detection model could trigger a red flag if a payment amount is much higher or lower than a customer’s usual spending or multiple payments have a similar type of characteristic found in past successful frauds. Anomaly detection can identify abnormal transactions that are not part of known fraud patterns, and classification models can be trained with examples of regular and fraudulent payments to recognize these transactions.
For instance, a single account may make several purchases in a brief span of time, or multiple accounts could be making purchases with similar payment information in questionable activity. These indicators guide organizations to prioritize transactions for further validation, temporary review or even customer validation. An unusual payment does not necessarily mean fraudulent, however; and automated findings must be assessed with proper evidence and risk-based procedures.
Analysis of Large Volumes of Security Data
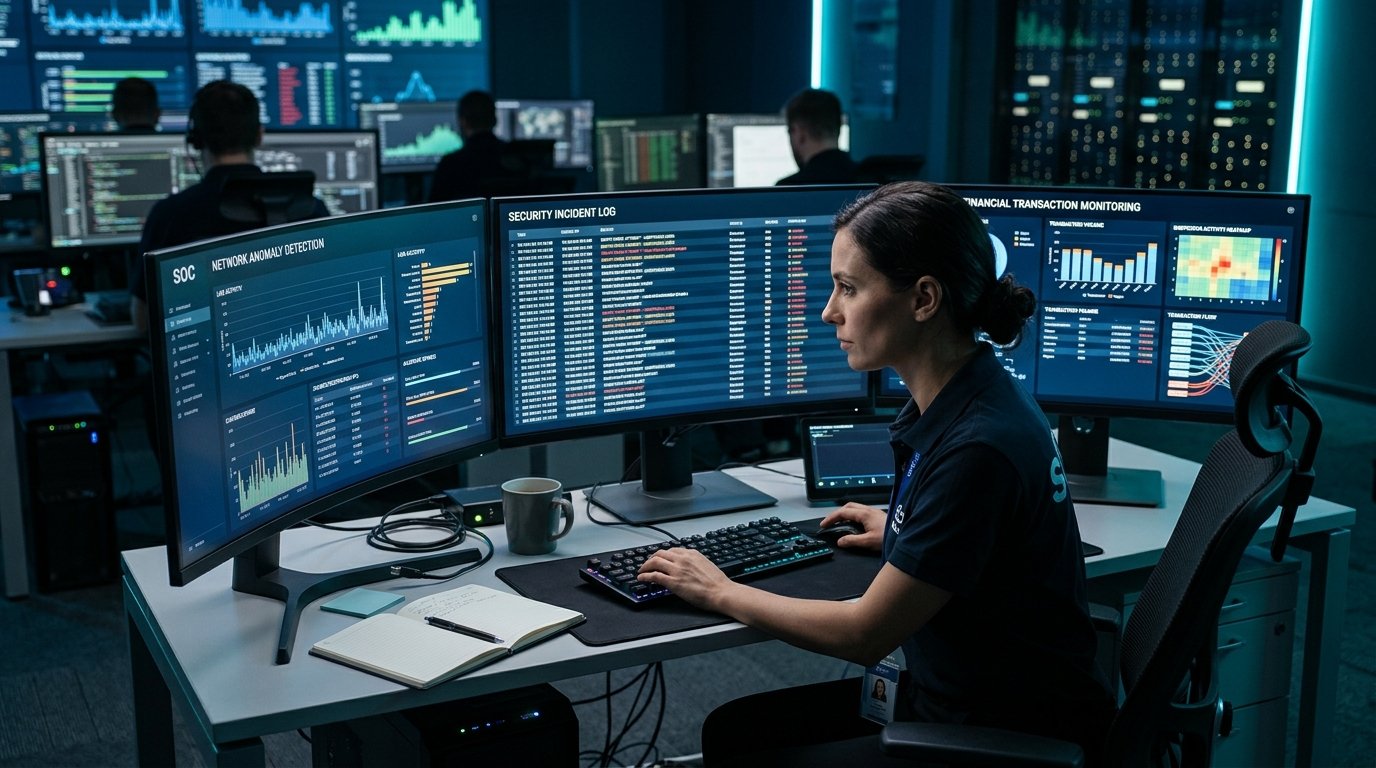
Current organizations frequently produce a great deal more security information than any person can examine on their own. In a large enterprise, millions of network events, authentication logs, application logs and financial transactions could all be recorded on a daily basis from various systems. Data mining is the process of organizing data, extracting features of interest, uncovering regularities and identifying events of interest that makes the information more manageable. Typically, it starts with gathering data from various systems, cleaning the data to fix inconsistencies, deduplicating and normalizing data formats.
The prepared data is then fed into analytical models, which analyze the data to produce outcomes such as anomaly scores, suspicious clusters, or anticipated probabilities of fraud. These findings can be correlated with data from threat intelligence sources and alerts to give it context. Analysts examine the most urgent findings, make notes on what they found and leverage what they know about confirmed incidents to enhance future detection. This method allows organizations to concentrate their finite security resources on events that are most likely to be a threat.
False Positives and the Importance of Accurate Detection
False positives are one of the significant issues when dealing with data mining in cybersecurity. A false positive is when a system incorrectly classifies a legitimate transaction as suspicious, resulting in unnecessary investigations, services being interrupted, or delays in customer transactions. For instance, if a customer has an unusually high purchase while traveling, that purchase could give off a fraud alert even if the payment is legitimate. In the same way, an employee in a business downloading a lot of files for an approved project could be identified as using excessive data.
Likewise, a business worker downloading numerous files for an approved project could be identified as using excessive data. Too many false positives can overwhelm security teams and result in analysts missing critical warnings. This can be mitigated by changing detection thresholds, adding more context to the detection model, frequently checking the model’s performance and enabling analysts to give suggested changes to the model after investigating an alert. Detection systems should focus on accuracy and sensitivity, and not try to detect every anomaly. The tracking also needs to be carried out for false negatives, which is when bad behavior slips through the cracks.
New Attack Techniques and Adaptive Threat Detection Methods
Cybercriminals are constantly evolving their tactics and techniques to evade security solutions, which means that threat detection is not a single off-the-shelf solution, but a continuous process. Attackers can update malicious software, change infrastructure, create attachments looking like real users, spread activity across accounts, or pretend to be a real user. Fraudsters also adjust to new transaction monitoring regulations by financial institutions. As a result, an adoption of a model based on previous incidents could over time lose its effectiveness as attack patterns and typical business activities evolve.
Organizations need to continuously review their models, add accurate data on new threats and retrain systems as needed. Security teams should also study confirmed incidents to determine, which signals were missed and if detection rules need to be enhanced. Yet, automated retraining needs to be managed with care as the data provided to the AI might be contaminated, or the labels could be wrong, or the feedback could be misleading, all of which can impact the accuracy of the model. When paired with up-to-date analytical techniques and knowledge, along with threat investigation, threat intelligence, and proven security protocols, the security team has a better chance of protecting against evolving attack methods.
Data Privacy and Responsible Security Monitoring
While data mining can help in detecting threats, it also calls into question issues of privacy, confidentiality and responsible data use. Personal information, employee activity information, customer payment information, device information, and online behaviour information are some examples of the types of data that may be included in security datasets. This information could be used without proper precautions to pose privacy risks and lead to legal or reputation liability for organizations. Therefore, businesses need to have a set of purposes for data collection, restrict data access to authorized people and keep data only for a reasonable time.
Sensitive records can be protected throughout the analytical process using encryption, access control, data minimization, and secure data storage. Organizations will also want to consider if behavioural models result in unfair outcomes or disproportionately target specific groups, due to bias or incompleteness in the data. If appropriate, anonymization or pseudonymization can help limit the disclosure of personal data, but does not ensure complete privacy. Clear policies, adherence to relevant data protection regulations, and regular privacy reviews ensure responsible and proportionate security monitoring.
How Data Mining Complements Existing Security Controls
While data mining is a useful cybersecurity tool, it does not substitute for basic protective measures against systems, networks and information. Firewalls, multifactor authentication, endpoint protection, encryption, access management, secure software development, patch management and secure backup procedures all continue to be a part of a comprehensive security strategy. While analytical systems can detect suspicious behaviour, they might not be able to detect every attack, especially where information from the system is incomplete or the attack is similar in nature to accepted activity.
Therefore, data mining should be complemented by preventive controls, detection and response mechanisms and periodic security evaluations. For instance, a model can alert to an unusual login attempt, multifactor authentication can add an extra layer of security, and access controls can restrict the resources an account can access. It is important that security teams have a tested plan for responding to incidents in order to limit the impact of threats, investigate compromised systems and restore normal operation. Analytical intelligence and reliable security measures help to diminish the need for relying on one specific technology.
Conclusion
Data mining is becoming an increasingly vital area of cybersecurity that enables organizations to identify suspicious patterns in vast quantities of their security logs, network data, user activity, and financial transactions. Anomaly detection, network traffic analysis, behavioural profiling, phishing identification, intrusion detection, and transaction monitoring gives security teams more information to respond to the potential threats, and helps them to investigate them more efficiently. However, there are drawbacks to these capabilities, like false positives, the changing nature of attacks, lack of data and privacy issues.
Organizations need to assess the effectiveness of the models, safeguard the protected data, improve detection strategies and have qualified users available to examine significant results. Most importantly, data mining should augment and not supplant existing security controls. Combined with robust authentication, access controls, endpoint security, incident response, and responsible data management, it can be a potent weapon in the fight against cyber risks, fraud detection, and safeguarding the confidentiality, integrity, and availability of digital systems.