Introduction
Customers leave reviews, post in social media, send emails, write business reports, publish research papers, read news articles, and discuss online, among other activities, providing organizations with vast amounts of textual information every day. While these documents contain valuable information, reading and analysing thousands or millions of these manually is time consuming, labour intensive and costly. AI can offer practical solutions to this challenge by enabling text mining and natural language processing (NLP).
The technologies enable computers to interpret human language, recognize salient information, detect patterns, and extract insights from unstructured text which are pertinent to decision making. For instance, a company can review thousands of customer reviews to find out what issues are likely to be more prevalent amongst them, and scientists can scan scientific publications to check for new trends. When paired with analytical tools, an automated language processing system can process massive amounts of text in more efficient ways to uncover meaningful relationships and make evidence-based decisions.
What is Text Mining?
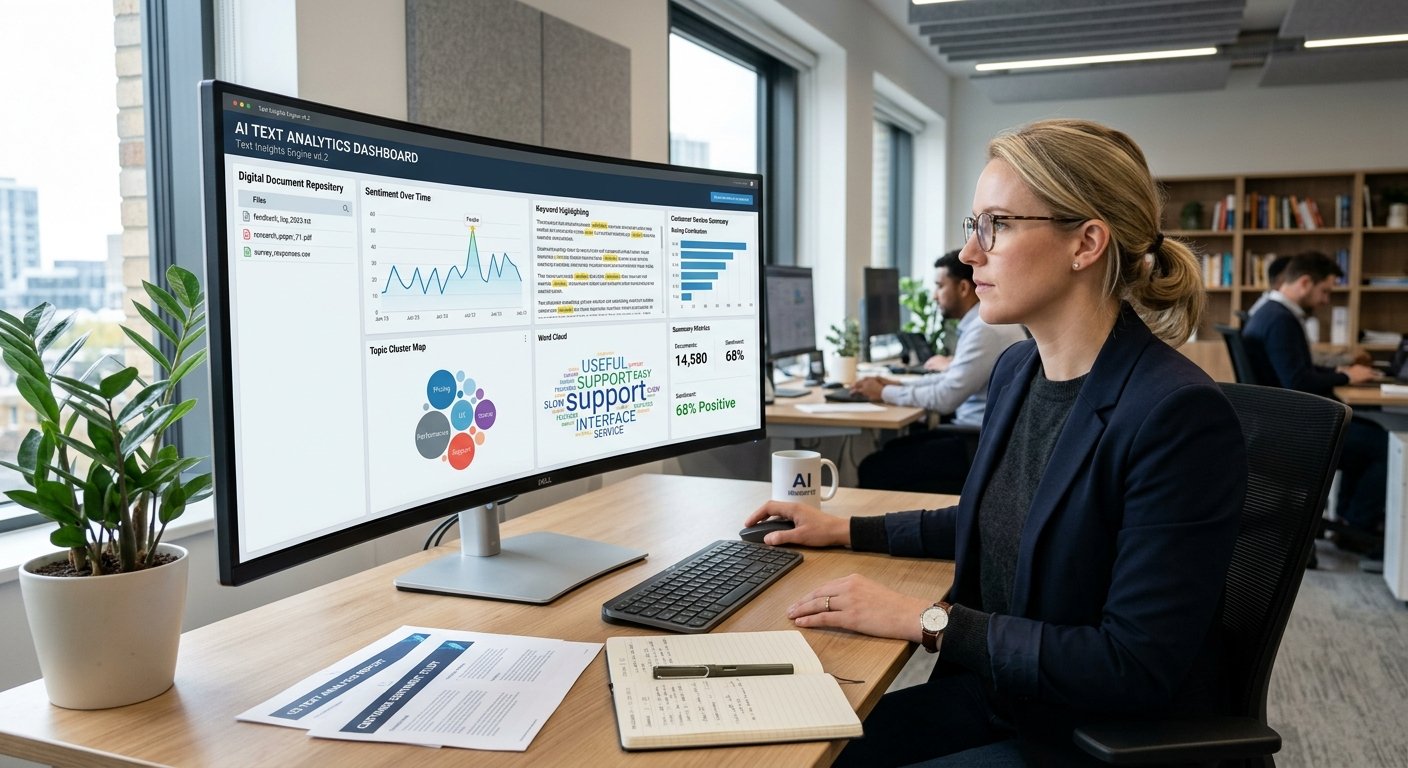
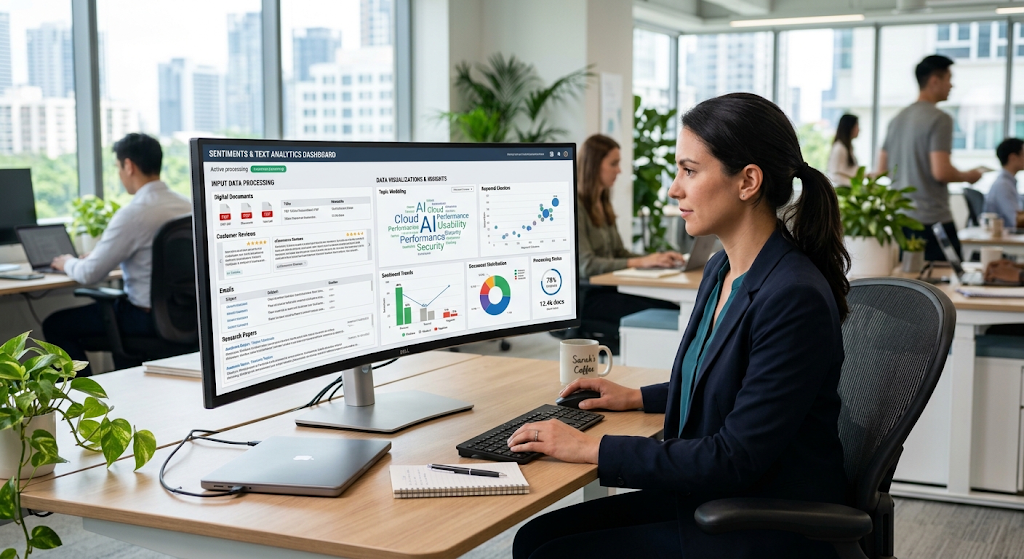
Text mining involves the extraction of information, patterns, relationships and trends from large text collections. It uses methods of artificial intelligence, machine learning, statistics, information retrieval, and computational linguistics to convert unstructured documents into information that can be dealt with in a systematic way. Text mining differs from conventional data analysis techniques that typically analyse data in rows and columns. For example, a set of customer emails might use various expressions to describe the same issue and thus would not be easily analyzed with standard spreadsheets. Text mining techniques can be used to find repeated words, classify similar documents, look for relationships between concepts and uncover information that may be hidden in the text. The wider field of text mining covers techniques for analyzing documents and finding patterns that enable research, business intelligence, understanding of customers and other data-driven work.
The benefit of text mining is that the written data may contain information that cannot be understood from the number alone. While sales may indicate that a product isn’t selling as well as it used to, customer feedback might indicate that it has something to do with the packaging, delivery or the product performance itself. Likewise, a news company can produce thousands of reports on economic conditions, public health, or political happenings, making a big info collection difficult to examine by hand. With the support of text mining, these documents can be systematically analyzed, issues that are often discussed in them are identified, and relationships between different subjects are discovered. It is dependent on the information provided, the analytical techniques employed and the skill of the analysts to interpret the results accurately. Text mining is not meant to be a replacement for human judgment; instead, it’s a useful tool for structuring content, identifying patterns, and guiding people to results that should be explored.
What is Natural Language Processing (NLP)
Natural language processing is a technology that falls under AI that allows computers to handle, parse, understand, and produce human language. It is a blend of computational linguistics, machine learning, and statistical methods, designed to enable computers to interact with text or speech. NLP can be used for various applications including chatbots, translation systems, voice assistants, spam filters, sentiment analysis, and automated document processing.
A computer needs to break down a sentence into words, determine which words are the nouns, verbs, adjectives and adverbs, see how words are related to each other, and infer their meaning in the context of other words. For instance, when processing the sentence “The bank approved the business loan”, an NLP system should understand that the word “bank” doesn’t mean the side of a river. To manage language patterns and meaning, modern NLP systems employ various techniques such as rule-based, traditional machine learning, and deep learning models.
Importance of NLP
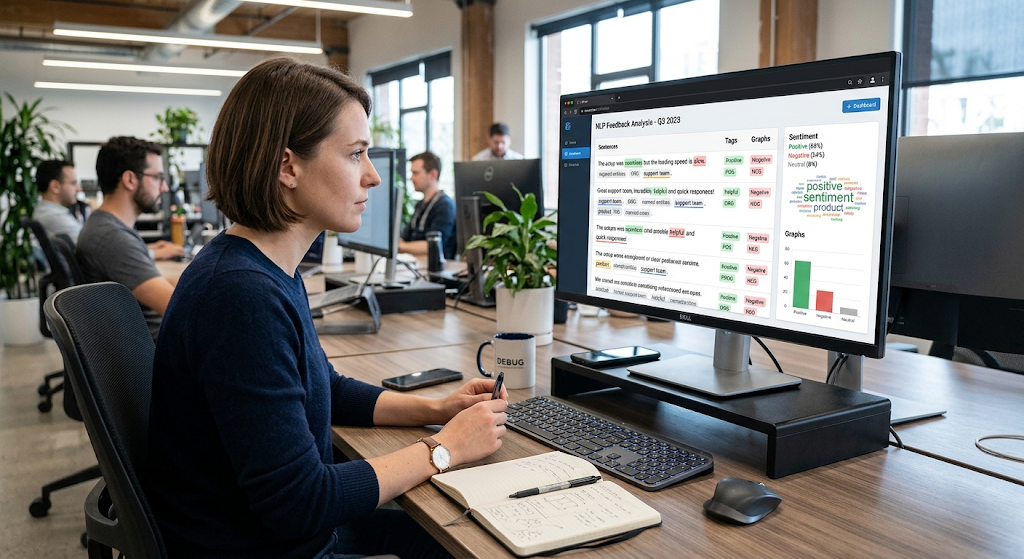
Why is NLP important? The reason is that human language is intricate, flexible, and may even be ambiguous. In writing, people use various forms of expression, abbreviations, spelling variations, idioms, expressions etc., which have context dependent meaning. The customer who leaves a 5-star rating for The service was not bad may be giving a good rating, whereas the one who leaves a 4-star rating for The service was good, but the staff were rude and expressed a positive as well as a negative review.
A good NLP system should take those differences into consideration, as well as just tallying up positive and negative words. NLP techniques can be tokenization, which involves breaking down text into smaller segments; lemmatization, which transforms words into their base forms; named entity recognition, which detects names and other entities; and semantic analysis, which evaluates meaning and relationships. These features enable computers to facilitate the creation of text to be analyzed and lay the groundwork for higher-order systems that extract information from vast amounts of documents.
Text Mining vs. Natural Language Processing
Text Mining and NLP are similar, but have distinct applications in text analysis. The primary focus of NLP is to enable computers to work with human language, its structure, its meaning and its context. The goal of text mining is to identify patterns, relationships and knowledge that are useful in a collection of texts. In brief, NLP enables a computer to process language, and text mining is based on language-processing and analytical methods to extract information from documents. For instance, an NLP system can recognize product names, interpret what customers are saying in the comments, and be able to tell if a sentence indicates satisfaction. Thousands of these comments could then be subject to a text mining process to determine the most common products mentioned, to compare the pattern of complaints by location and to determine what complaints are found to be related to negative feedback.
The application of the two disciplines is often linked and complementary. NLP can clean and prepare textual data, recognize entities, recognize relationships, and convert text to representations that can be processed by analytical systems. These outputs can be used with text mining to classify documents, find recurring topics, find patterns, and compare patterns across large sets of documents. The relationship is not one-way, though: Statistical methods that do not rely on complex NLP can also be used in text mining, and many applications of NLP do not involve mining a collection of large documents. For instance, a chatbot can process a user’s query and generate a reply, even if it isn’t the one that’s most beneficial to them, without engaging in extensive text mining. On the other hand, a simple text mining system can be able to get the most common words based on statistical techniques without going into the essence of the words. It is important that organizations don’t use the terms interchangeably—but that they choose appropriate techniques for their purposes.
Important Techniques used in Text Mining and NLP.
1. Document Classification
Document classification is the act of categorizing documents as per their content into predefined categories. It makes a huge difference for organizations that have to manage large volumes of text, where the need for manual sorting is reduced. By using machine learning models that have been trained on a set of past examples with labels, classification systems can learn to detect patterns that correspond to various categories. For example, a customer service team can assign incoming messages to one of four categories: billing inquiry, technical complaint, delivery inquiry, or refund request.
A financial institution can classify documents as invoices, contracts, loan applications or compliance reports. Another way news organizations can categorize articles is by section, such as business, sports, politics, health, or technology. Post training and evaluation a classification system can be used to consistently process incoming documents and route them to the appropriate department or workflow. It’s accurate only if its training examples are accurate and representative, the categories are well-defined, and it’s able to generalize to new words and topics.
2. Keyword Extraction
Aims to identify words or phrases that best represent the main subjects of a document or a collection of documents. Unlike word counting, good keyword extraction can attempt to separate important words from superfluous ones that are not important to understanding the document. Techniques can be frequency analysis, statistical scoring, linguistic rules and machine learning. A company researching customer feedback for a mobile phone, for instance, might find that some of the key areas of interest are battery life, screen quality, camera performance and charging speed.
Technical words can be gleaned from scientific papers that show the general procedures, ideas, and results described in the article. Document indexing, search results, content organization, and identifying recurring concerns can be enhanced through keyword extraction. But the more common words do not necessarily have more meaning, and the meaning of a phrase can change based on context. Using the other NLP techniques with the keyword extraction will, therefore, yield better results than using frequency alone.
3. Topic Modeling
Topic modeling is an analytical method that is employed to identify patterns among a large body of documents. Topic modeling can segment a collection of words into clusters that occur regularly in the collection, and then apply each of these clusters to represent a potential topic, without specifying each one in advance. For instance, a business that’s analyzing many customer reviews may find a trend on product durability, delivery experiences, cost, and customer service. A news organisation reviewing the reports over a number of months could see the same themes emerge, such as inflation, public transport, environmental issues and healthcare.
Researchers can use topic modelling techniques, such as latent Dirichlet allocation (LDA), to gain insight into such patterns and the evolution of attention over time or across documents. However, it is important to interpret automatically identified topics as they could be a set of related words that do not necessarily indicate a clear or meaningful theme. It is important for analysts to review representative documents, discuss the topic area, and verify their interpretations before applying found topics to support key decisions.
4. Named Entity Recognition
Named entity recognition (NER) is a Natural Language Processing (NLP) method used to recognize and categorize entities present in textual data that are significant. They can be anything from people, organizations, places, dates, monetary values, products, and other application-specific terms. For instance, a technology business has opened up an office in Lagos in the month of October 2026. The NER system could recognize the company’s name as an organization, Lagos as a place, and October 2026 as a date.
This information can be used to structure information, link documents that refer to the same entities and find relationships between people, businesses and events. NER can help researchers locate scientists and institutions in publications, and can be used by businesses to find location, contract partners, suppliers, or customers in documents. Names may be ambiguous and have different spellings, and this can lead to errors in the process of entity recognition. Contextual analysis and specialized training data and procedures to resolve ambiguous references may be necessary to get accurate results.
5. Information Extraction
Information extraction is the process of finding certain facts, relationships and structured information from unstructured text. Named entity recognition can be used to detect named entities, but information extraction is capable of extracting information such as what happened, who was involved, when, and how the entities are related. For instance, a business report can indicate that a business purchased another business for a certain sum on a certain date. An information extraction system may be able to extract acquiring company, acquired company, transaction value and transaction date, and store these information in a structured database.
Likewise, a research organization can take methods of research, sample sizes, measured outcomes and dates of publication from scientific papers. These features can be useful for compliance monitoring, research synthesis, business intelligence and document management. But extraction systems need to include missing information, unclear language, and statements regarding possibilities instead of certain facts. When extracted information will impact legal, financial, scientific, or operational decisions, human verification is still important.
6. Text Summarization
The idea of text summarization is to produce a short version of a document or set of documents that captures the most significant information. It enables them to read and comprehend a lot of written material without having to read it all in its entirety. Extractive summarization involves identifying key sentences or paragraphs from the original text and including them in the summary, while abstractive summarization involves creating a new summary in different words that captures the main ideas from the original text. For instance, when reading many scientific research papers, a researcher can use summarization to gain an overview of the purpose, methods, findings and limitations of each paper.
Lengthy reports may be summarized by a business manager to find key developments, risks and recommendations. Analysts of news can also look at daily news reports, and summarize them to gain an understanding of what happened in the day with each publication. While helpful, summarization can also include missing nuances, inaccurately convey relationships, or present unconfirmed remarks, especially from language models. Where there is a need for evidence, completeness and accuracy, it is advisable to compare summaries with the originals.
Practical Applications of Text Mining and NLP.
- Analyzing Customer Feedback
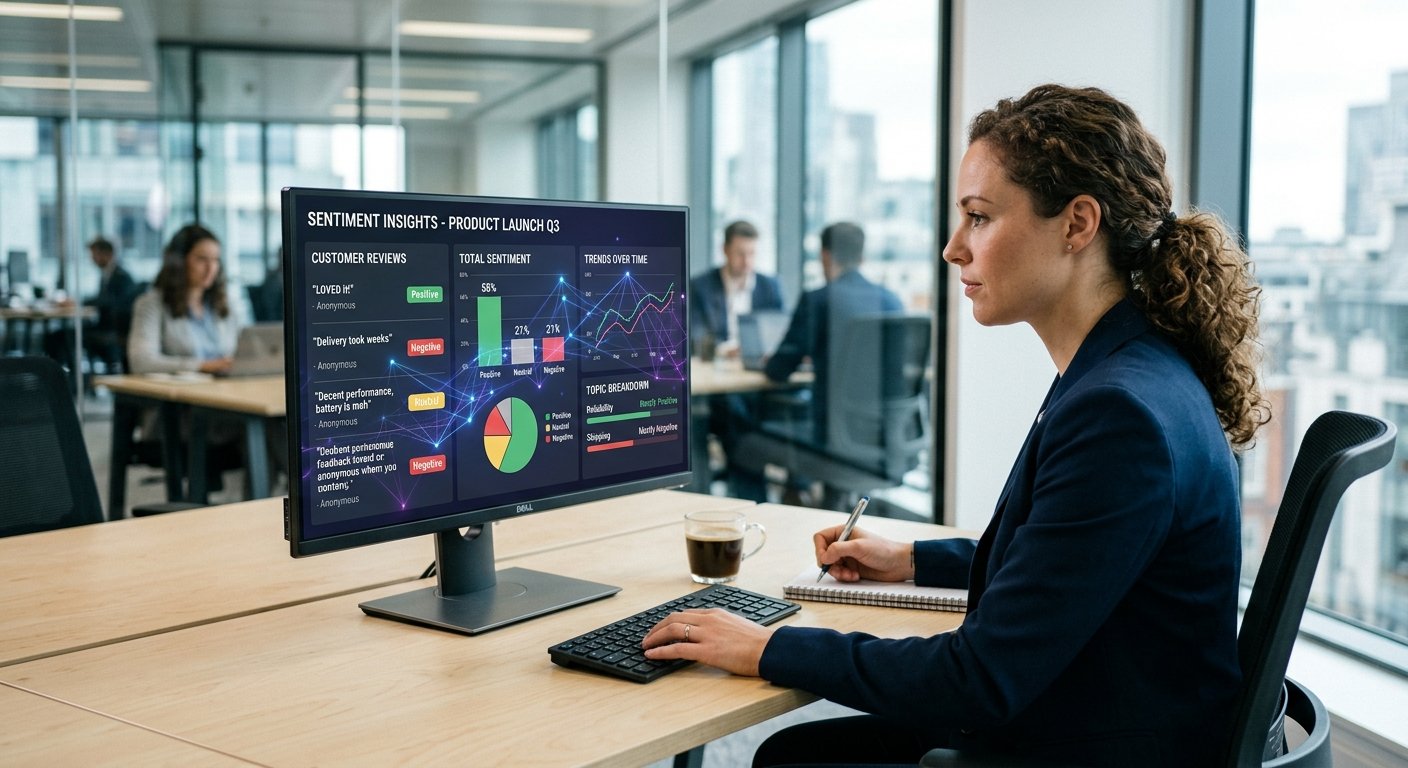
Customer feedback is one of the most valuable sources of information for businesses to gain insight into customer expectations and enhance their products or services. Customer experiences can be described in reviews, survey answers, social media feedback, or support messages and may not be reflected by sales and numerical customer satisfaction ratings. Using NLP with text mining, companies can segment comments by topic, gain insights into common issues, identify products mentioned and gain sentiment analysis. A telecommunications company might, for instance, look at customer complaints in messages to see if the primary complaint is about network reliability, subscription fees, data cap, or customer service.
Managers could then use these themes to highlight at their different locations or in different time periods where they would like to focus on. This type of analysis can assist organizations to focus on the most needed changes, track customer satisfaction, and determine if changes have taken care of the customer issues that were recurring. But automated systems should be able to factor in sarcasm, local language, variations in language, and that online reviewers may not be representative of the entire customer base.
- Reviewing Research Papers
The number of journal articles, conference papers, technical reports and academic publications generated by scientific research is steadily increasing. It is very important for the researchers to read a lot of documents to comprehend what is already known, identify the gaps in the knowledge, compare results, and identify new trends in research. Text mining and NLP can assist this process, by extracting keywords, identifying named researchers and institutions, classifying publications by subject and summarising relevant findings. Topic modeling can identify common themes in a vast amount of studies, and information extraction can be used to identify study characteristics and relationships between concepts.
A researcher looking at renewable energy, for example, might be able to make a list of technology areas that are often studied, of common problems reported in the literature, of topics that are becoming more popular. These tools can facilitate the identification of literature and improve the way researchers can structure their evidence. Automated analysis should be used in conjunction with, but not at the cost of, critical reading, however. A brief summary or automatically generated topic label may not do justice to the important differences in research methods, sample sizes, the quality of the evidence, and the limitations of the studies.
- Organizing Business Documents
Many companies store massive amounts of contracts, reports, emails, meeting minutes, internal communications, policies and more. If these documents are not well organized, staff may find it difficult to find necessary information, determine which records are relevant or complete routine paperwork. NLP and text mining can be beneficial for document management in several ways, such as automatically categorizing documents, extracting dates and names from them, finding keywords, and providing a searchable summary of the document. An entity recognition solution might be applied in a procurement department to recognize supplier names and contract dates, for instance, or a document classification system could be used to classify purchasing contracts from invoices and compliance documents.
Extracted information can then be used by search systems to assist employees in their ability to find relevant documents faster. These applications can help increase efficiency, lessen repetitive tasks, and aid in effective record-keeping. However, organizations need to create proper access rights, maintain accuracy in documents and not miss important documents due to automated classification and use wrong information derived from them.
- Finding Common Themes in News Reports
Large volumes of reports may be necessary to track by news organizations, researchers, businesses, and public institutions to help them keep abreast of the situation and look for patterns. It can be challenging to keep track of all the articles from various publishers, particularly if they’re released throughout the day. Text mining can be useful in identifying topics that are discussed with high frequency, categorize articles by topic, identify the names of people and organizations mentioned and track article changes over time. For instance, if you are looking at economic news articles, you might look at the food prices, unemployment rates, exchange rates and public expenditure to see which news is being given the most attention.
Topic modeling might enable the identification of links between topics of transportation cost and inflation, and named entity recognition might enable the identification of the institutions and locations most mentioned. The prevalence of a topic in news media coverage does not necessarily reflect its importance or prevalence in society, though. When interpreting the results of an analytical research, analysts should also take into account the differences between the editorial priorities and the reporting of the news, the selection of sources, political or commercial bias, and so on.
Advantages of using Text Mining and NLP together.
By integrating text mining with NLP, businesses can manage information in a scale that manual reading couldn’t handle. Patterns can be seen in large amounts of documents and information can be extracted to support analysts in answering questions in an efficient manner using automated systems. This can have a positive impact on employee time on repetitive tasks, and help them concentrate on interpreting data, problem-solving and decision making. The mix also offers better information organization, faster document retrieval, a better ability to analyze customer feedback and more extensive research discovery.
For instance, a company might be able to categorize customer communications, capture product details, determine the keywords of complaints and provide a summary of the most frequent topics in one analytic process. However, automation is not the solution to improved decision-making. The usefulness of results is dependent upon the methods being appropriate for the problem, the data being representative of the problem under study, and the results being interpreted correctly. Organizations should assess model performance, check key findings and make sure that automated analysis enhances and does not override human input.
Challenges and Risks Associated with Text Mining and NLP.
- Information and Data Quality
The quality of the text mining result is heavily dependent on the quality of the documents being text mined. Textual data sets can include misspelled words, repeated data items, missing data, incorrect statements, ambiguous terms, and other poorly formatted text. These issues can make it problematic for NLP systems to see what it’s supposed to see, and can cause text mining algorithms to see misleading patterns. For instance, if a business is gathering customer feedback about their complaints, but a lot of customers are not willing to report their complaints, then the problem is underrated.
Likewise, a review of research with the partial retrieval of publications can either miss valuable studies or focus overly on readily available ones. Data preparation can be beneficial in eliminating duplicate records, normalizing data formats, fixing obvious errors, and recording missing data. But meaningful differences and the original meaning of a document should not be lost through cleaning. Information gathered, sources omitted, and the adequacy of available information for the conclusions being evaluated must also be analyzed.
- Data Protection and Privacy
Personal information, confidential business information, financial records, health information and private communications are all examples of information that may be present in textual information. Organizations that utilize NLP and text mining need to think about how this information is gathered, kept, processed, shared and stored. For instance, customer messages can contain names, contact information, account information, or details of customer circumstances that aren’t required for the analysis being sought. Organizations should minimize data collection wherever possible, avoid collection of identifying information, limit access to authorized personnel only and be careful with the security measures.
They should also set out rules for the storage of data and ensure that data processing is in compliance with the existing data protection legislation and contractual requirements. There are not always valid uses of every part of a dataset for analysis. Organizations should consider having a legitimate interest in processing the information, providing information where required and the benefits of the analysis outweigh privacy risks. These measures are crucial for preserving trust and minimizing the risk of unauthorized disclosure.
- Biased or Inaccurate Conclusion.
The results of text mining and NLP systems may be incorrect if their inputs or methodology are biased. Not all groups and viewpoints are necessarily represented in online reviews, news articles, research publications and business records. Feedback from very happy or very bad customers could be more than from those who had a moderate experience. A news analysis system could be biased towards keywords that are more prominent in specific news publishers, and an NLP model trained on only one language variety could be underperforming on regionally used keywords or on writing styles that might be unfamiliar to the model.
These restrictions can lead to misinterpretation of public opinion, the neglect of crucial issues, and the impartial decision-making process. Another danger is assuming a correlation is a causation. Two topics that do occur together do not imply that one causes the other. Analysts need to review data coverage, test models in various groups, review results in comparison with reliable evidence, and record uncertainty. When results impact people, public policy and big business decisions, human review and independent validation is especially critical.
Best Practices for Effective Text Mining and NLP.
By establishing clear analytical goals and choosing tools or gathering documents, organizations can enhance their outcomes. For a team looking to understand customer dissatisfaction, for instance, they would need to determine what kinds of questions they need to answer, what kinds of feedback is relevant and how the outcome of the feedback will influence business decisions. This is followed by the collection of appropriate data and determining if the data is representative of the topic under investigation. While preparing text, make sure that there are no duplicates, different formatting, or irrelevant text and that the meaning of the text remains the same.
They should then choose techniques that suit their requirements, e.g., classification for routing documents, keyword extraction to search the documents, topic modeling to find themes, information extraction to identify specific facts. Models need to be evaluated on representative examples and errors need to be studied before they are used in practice. A combination of documentation, privacy protection, continuous performance monitoring, and human oversight ensures reliability in the event of evolving data sets and language patterns. These practices provide more transparency for text analysis and improve the chances of usefulness.
Conclusion
The world generates a massive amount of unstructured text information from individuals, businesses, researchers and media organizations, which can be analyzed by text mining and natural language processing. NLP and Text Mining work hand-in-hand in the sense that NLP contributes to the analysis of text through the extraction of entities, context analysis, and meaningful information, while Text Mining is used to analyze text to find patterns, relationships, and trends between documents. They can be used in combination to facilitate document classification, keyword extraction, topic modelling, information extraction, and summarisation, helping to analyse customer feedback, review research papers, organise business records, and find common themes in news reports.
But their value is dependent on responsible implementation. Even a good, complex analytical system can be compromised by poor data quality, missing sources, privacy issues, skewed samples, or faulty analysis. Therefore, organizations should integrate suitable technical approaches with the proper data preparation, holistic assessment, privacy safeguarding, and human knowledge. By adhering to these principles, text mining and NLP can unlock the potential of vast amounts of written data, turning it into valuable information that can drive research, enhance operations, and aid in informed decision-making.