Introduction
Software will always use algorithms to complete actions and processes within its application. However, not all algorithms will perform well or be efficient. Some algorithms will complete actions very quickly while others will take a long time depending on the amount of data. Some algorithms will not require much memory whilst others can cause your system to use a lot of resources. Knowing about these differences can benefit developers as they will know what the best options are for making their application efficient and reliable.
A couple of key concepts that can help us determine the efficiency of an algorithm are time complexity and space complexity. These are related to Big O Notation which gives us a mathematical way of knowing how an algorithm will scale its resources depending on the amount of data it is given. Knowing about this can help developers to make informed decisions when choosing, designing and improving their algorithms.
What Is Algorithm Complexity?
Algorithm complexity is how much resources an algorithm will need to complete its task. This mostly refers to how long the algorithm will take to execute and how much memory it uses. When analysing an algorithm, we want to know how the performance will change depending on the amount of data it is given. For example, an algorithm might work perfectly fine with ten records of data but could cause a noticeable slow down when there are one million records. By analysing the complexity we can see what issues we could have with our algorithm. Complexity looks at how the resources needed will increase based on how much data it is given, rather than looking at how fast the algorithm will run on a specific computer.
There are two main types of algorithm complexity; time complexity and space complexity. Time complexity looks at how the number of operations increases based on the amount of data. Space complexity looks at how much extra memory an algorithm will use. Both of these are important as you may have an algorithm that is very fast but uses up too much memory. Or you could have an algorithm that doesn’t use much memory but takes too long to complete. The best option will be to find an algorithm that provides a good balance between speed, memory usage and what the application requires.
Understanding Time Complexity
Time complexity looks at how long an algorithm will take to execute depending on the amount of data. This isn’t necessarily how long in seconds the algorithm will take to complete, it is more about how many basic operations the algorithm will perform. For example, if you have an algorithm that searches for a specific name within a list of customer records. If it looks at each record in turn the number of operations will increase based on how many records there are. If there are 100 names in the list it may have to look through up to 100 records. If there are 10,000 names it will look through up to 10,000 records. This allows us to describe how the algorithm will scale and provides us with information to see if it will still be efficient for larger datasets.
This becomes very important when dealing with increasing amounts of data within your application. For example, if you have an online shopping application with only a few hundred products you may think that searching through your products will be fast. However, as your business grows and your products increase to hundreds of thousands of products, searching could begin to take noticeably longer. By analysing the time complexity we can identify algorithms which may struggle with increased workloads and replace them with more efficient ones. This will allow your application to perform well.
What Is Big O Notation?
Big O Notation is a mathematical way of describing how an algorithm will scale depending on the amount of data it is given. It is often used for describing the time complexity but can also be used for space complexity. Big O Notation looks at how an algorithm will generally scale, rather than how long it will take to execute or any specific hardware it is being executed on. For example, an algorithm that performs roughly one operation per piece of data will have a linear complexity and will often be described as O(n). An algorithm that performs a set number of operations no matter how much data it is given will have a constant complexity and will be described as O(1). This helps developers to compare algorithms and see how they will scale with larger amounts of data.
One thing to note with Big O Notation is that it looks at the main scaling factor. This means that any smaller numbers and constants will generally be ignored. For example, an algorithm that performs 3n + 5 operations will be described as O(n). This is because as n gets bigger the linear operation will have more of an impact. Similarly, an algorithm with a growth function of n2 + 4n + 10 will be described as O(n2) because as n gets larger the square will have more of an impact. This helps developers to focus on the most important part of their algorithm and makes complexity easier to understand.
Common Time Complexities
Depending on the algorithm you are using, they will scale differently. Some complexities will still be efficient even with extremely large amounts of data. Others will become very expensive as they have more data to process.
Knowing what the common complexities are can help you identify efficient algorithms and what solutions could cause issues. Below are some of the most commonly talked about complexities in computer science.
1. Constant – O(1)
This complexity will occur if an algorithm performs a set amount of operations no matter how much data it is given. For example, if you want to access an item from an array using an index. If you want to select the fifth item in an array, the computer can jump straight to this position without having to look through all the other items. Whether there are 20 items or 200,000 items in your array, accessing by index will generally be constant time. This is one of the best complexities you can get.
Constant time operations can be very useful in many situations. For example, getting a value from a hash table using a key will generally take an average of O(1) time. Accessing an item from an array will also not require you to search through all of the items. However, just because something is constant time doesn’t mean it takes zero time to complete. It just means that the number of operations will not increase based on how much data there is. Developers often try to implement constant time operations within their applications for features that will be accessed often.
2. Logarithmic – O(log n)
This complexity will occur if an algorithm greatly reduces the size of the problem. Rather than looking at all the items, the algorithm will split the search area or problem into smaller parts. A common example of this would be a binary search. This algorithm works by searching through a sorted set of data. It looks at the middle item and if the value is less than this it will ignore the top half. If it is greater than this it will ignore the bottom half. This will continue until it finds the value or there is nothing left to search through. As the amount of data is halved each time, this can be very efficient for large sets of sorted data.
The benefit of this complexity can be seen when considering how much data you have. If you have 1024 sorted items in your data set and you use binary search you will only ever have to split the data up around ten times. If you have over one million items in your data set the number of splits only increase slightly. This makes it very useful for searching through and organising large data sets. However, the data must be sorted for this to work. This can be an issue as you may have to spend extra time sorting your data. Despite this, logarithmic algorithms can be very useful as they generally scale much better than linear searching.
3. Linear – O(n)
This complexity will occur if the number of operations increases in relation to the amount of data. If your algorithm is looking at all the items in the data set at once it will generally have a time complexity of O(n). For example, if you wanted to create a programme to calculate the total sales from a list of transactions you would have to look at each transaction and add its value to the total. If you have 100 transactions you will process 100 records. If you have 10,000 transactions you will process 10,000 records.
Linear algorithms are very common in everyday programming due to many tasks requiring you to look at every item in your data set. This could be counting items, averaging numbers, finding the largest number in a list or searching for a specific value. Whilst these algorithms do require more operations as the amount of data increases, they are often a practical and efficient solution. They are generally predictable as the amount of work will increase at a steady pace. Just because the complexity is higher than O(1) and O(log n) doesn’t mean you should avoid them. In many cases you will have to look at every item to get the correct result.
4. Linearithmic – O(n log n)
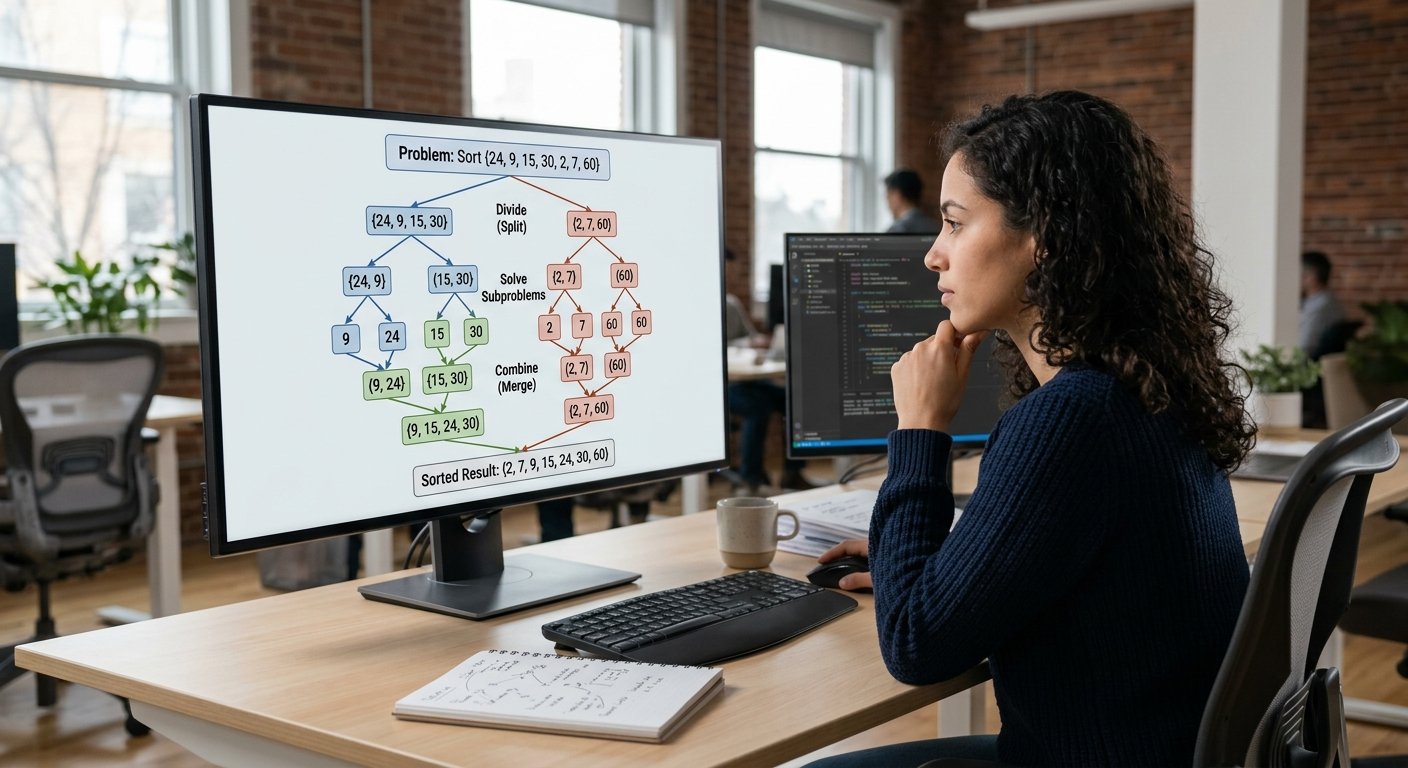
This complexity is a combination of linear and logarithmic and is often shown as O(n log n). This is a common complexity for many efficient sorting algorithms. A popular example would be merge sort. This algorithm works by splitting the data into smaller parts multiple times until each part only has one item. The smaller parts are then merged together in the correct order to sort the entire data set. The algorithm will split the data into logarithmic layers and will then have to do work proportional to the number of items in each layer.
Algorithms with this complexity can be very useful when dealing with large data sets that need to be sorted efficiently. For example, an e-commerce application may need to sort thousands of products by price, popularity or customer rating. Using a simple sorting algorithm with a quadratic complexity could become inefficient. However, using merge sort and other efficient sorting methods generally perform much better with larger data sets. Depending on the implementation of the algorithm, they could use extra memory but they are useful due to their performance.
5. Quadratic – O(n²)
This complexity will occur if the number of operations roughly increases with the square of the data. This is often seen when you have two nested loops in your algorithm. For example, if you have a programme that compares every student in a class to find any matches. If there are 10 students you may only have a small amount of comparisons to do. However, if there are 1000 students in your class the number of comparisons can greatly increase. This is because the amount of work increases much faster.
Whilst this can be an acceptable complexity for small data sets, it can cause serious performance issues as the amount of data increases. For example, if you have an algorithm that roughly performs 100 operations for 10 items you could have around 10,000 operations for 100 items and one million operations for 1000 items. This is why developers often look for alternative solutions when they have nested loops that are constantly processing the same data set. Some algorithms will naturally have a quadratic complexity but others can be improved by using more efficient data structures, sorting methods and problem solving methods. Knowing this complexity will help you to identify potential performance issues.
Comparing Common Time Complexities
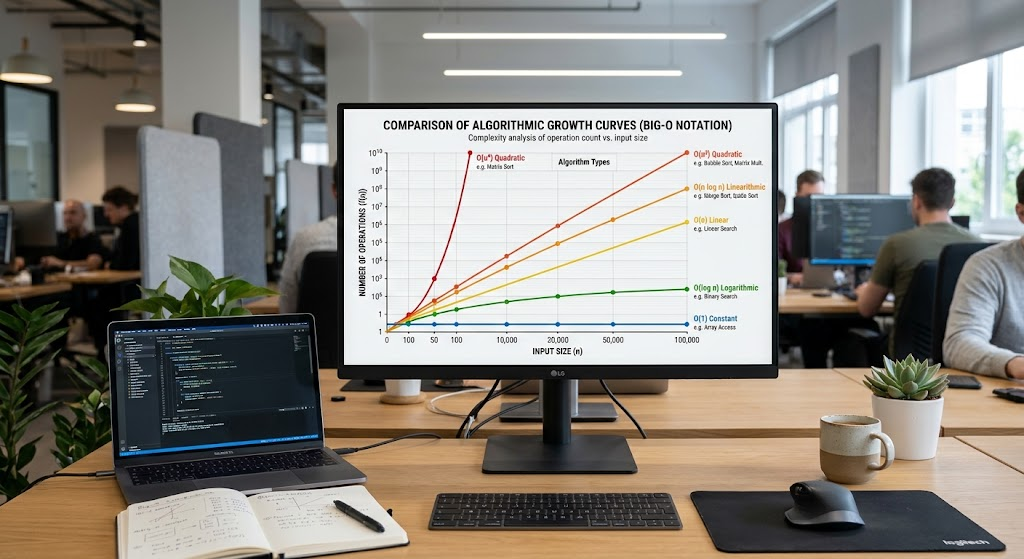
Knowing what each complexity is can be useful but comparing them can give you a better idea of how they will perform. For example, if you have an application that processes thousands or millions of records. An O(1) operation will roughly have the same amount of steps no matter how large your data set is. An O(log n) algorithm will increase slowly as it will reduce the problem each time.
An O(n) algorithm will have an amount of work proportional to the number of records. An O(n log n) algorithm will increase faster but can still be a practical solution for many large tasks. An O(n²) can become very expensive as the amount of work increases very quickly. This can have a big impact on how efficient your algorithms are.
Understanding Space Complexity
Space complexity looks at how much memory an algorithm will use. Memory is an important resource in computing and your application will need space to store the data, temporary values, variables and other information. Some algorithms will only use a small amount of extra memory whilst others will create extra arrays, data structures or recursive function calls. Knowing the space complexity can help developers to understand how the memory usage will change based on the amount of data. This is especially important if your application processes large data sets or runs on devices with limited memory such as smartphones, embedded systems and smaller computing devices.
For example, if you have two algorithms to reverse a list of numbers. The first algorithm would modify the original list by swapping the items from either end until the whole list is reversed. This could have an auxiliary space complexity of O(1) depending on the implementation as it only requires a few temporary variables. The second algorithm will create a completely new list and copy the original items in the opposite order. This will require extra memory proportional to the number of items so will have an auxiliary space complexity of O(n). Both will give the same result but will have different memory requirements. Developers will need to consider this when choosing an algorithm for applications that deal with large data sets.
How The Amount Of Data Affects Algorithm Performance
The amount of data will play an important role in how efficient your algorithm is. Many algorithms will work perfectly when dealing with a small amount of data but could require much more resources as the amount of data increases. For example, if you have a simple search that looks through fifty customer records it may complete very quickly. However, if your application is dealing with five million customer records the amount of work will increase greatly. You shouldn’t just test your algorithms using small data sets. You should understand how they will perform as your application grows and becomes more demanding.
This can be seen when looking at different complexities. An algorithm with an O(n) complexity will increase in line with the amount of data. An algorithm with an O(n²) complexity will increase much faster. If you double the amount of data in a linear algorithm it will roughly double the amount of work. If you double the amount of data in a quadratic algorithm it will roughly quadruple the amount of work. This can affect how responsive your application is. By analysing the complexity you can identify how the algorithms will increase and choose ones that can cope with future increases in data.
Why Algorithms That Work For Small Data Sets Can Cause Issues For Larger Data Sets
An algorithm that works well for a small data set may become inefficient as the amount of data increases. This is because the amount of resources it requires will increase. Often when developing an application, programmers will test it using a small set of sample data. This may not cause any performance issues as there is only a small amount of work to do. However, once deployed and dealing with thousands/millions of records the inefficient operations may become more noticeable. For example, if you have a sorting method with an O(n²) complexity it may sort twenty numbers very quickly. However, sorting one hundred thousand numbers could require an enormous amount of comparisons. You should consider how scalable your algorithm is.
Large data sets can also cause issues with memory. An algorithm that creates a few temporary copies of its data may work fine with a small data set but could use too much memory with millions of records. This could cause your application to run slower or not complete certain operations. This can affect systems such as financial platforms, customer management applications and online services that deal with large amounts of data. By choosing efficient algorithms, not duplicating data unnecessarily and choosing the right data structure you can reduce these issues. Knowing about time and space complexity will make it easier to predict these issues and create applications that will be reliable.
How Time and Space Complexity Affect Software Scalability
Scalability refers to how well an application can cope with increased workloads. As more popularity is given to an application there is likely to be more users, transactions, requests and records to process. Algorithms that work well with a low workload may not be suitable for an application that has increased. Time complexity can help developers understand the amount of operations needed and if this will increase in a reasonable way. Space complexity can help show how much memory will be used with more information being processed. This can be helpful when designing scalable systems. If developers consider complexity when designing then they can avoid any scalability issues that may cause performance issues and expensive changes.
For example, a social media platform may have millions of profiles, relationships, messages and activity logs to process. If the algorithm is not efficient then searching for a user, suggesting new connections or finding information may be very slow. Online banking systems need to be able to process transactions reliably but also manage the computing resources. Choosing the right algorithms can help with increased workloads. Although complexity can help improve scalability, there are many other factors to take into consideration such as network performance, database design, hardware etc. This can give the developer a good foundation to make informed decisions.
How Developers Can Improve Algorithm Efficiency
Developers can improve algorithms by looking into their current code to see what operations are taking up too much time/memory. Looking into nested loops can help as sometimes this can cause quadratic complexity. If possible, the developer can change the algorithm to use a hash table or other data structure instead of searching for information multiple times. Sorting algorithms can also be improved by looking for methods with better growth rates. The right method will depend on what the problem is. Understanding what your algorithm does, what the issues are and what alternative can be used to meet the performance requirements of the application.
Choosing the right data structures can help improve your algorithms. Different data structures have different performance. For example, searching for a value in an unsorted array will take O(n) time, however using an index to find an element will take O(1) time. Using a hash table can reduce the time complexity to an average of O(1). This can be useful if the application needs to find information often using a particular key. Avoid allocating extra memory. Consider if you actually need to store temporary data. Testing the algorithms with different sized inputs can help highlight performance issues. By considering complexity and performance, you can make better decisions when designing your software.
Balancing Time and Space Complexity
Sometimes choosing an efficient algorithm will involve finding the right balance between time and space complexity. A fast algorithm may use more memory. Whereas an algorithm that uses less memory may take longer to complete. You shouldn’t just choose an algorithm based on one complexity. For example, an application that deals with large images may want to prioritise space complexity as having multiple copies of each image may take up a lot of resources. However, if the application deals with frequent requests from users then time complexity may be a bigger priority. It depends on what the application is doing, what hardware is available and what the users expect.
Sometimes using extra memory can help improve the time complexity. Memoization is a technique where previous calculations are stored so they don’t have to be calculated again. This can help reduce the processing required for some problems, however it uses more memory. Caching can also help by allowing the application to store frequently requested information. However, this isn’t always suitable as it uses memory and may need updating when the data changes. Developers should consider the advantages and disadvantages of different methods. Knowing the time and space complexity can help find the right balance.
Conclusion
Understanding time and space complexity is important when considering how efficient an algorithm is. Time complexity describes how the number of operations increases as the input increases. Space complexity describes how much memory will be used. Big O Notation can be used to easily describe how they affect each other. Common complexities include O(1), O(log n), O(n), O(n log n) and O(n²). This can help developers understand why some algorithms are efficient with large data sets and others are becoming increasingly expensive. By considering complexity, choosing the right data structure and testing with different sized inputs, performance issues can be identified.
As software applications deal with larger data sets and more demanding workloads, it is important to ensure the algorithm is efficient. Developers can no longer just consider if the algorithm gives the correct output but how much time and memory it is using. An algorithm that works well with a small data set may not be suitable for an expanding application. Finding the right balance between time and space complexity can help developers create applications that use the computing resources responsibly and reliably. Overall, knowing the complexity of algorithms will give a good foundation to write efficient code, solve computational problems and create adaptable software.