Introduction
Most modern OS systems run multiple processes at once, and often some of these processes must communicate with one another in order to carry out tasks efficiently. Interprocess Communication (IPC) offers ways for independent processes to exchange data, synchronize operations and coordinate activities in UNIX environments. For any application – be it background workers, server processes, databases or local services – selecting a communication method is critical to provide performance and reliability.
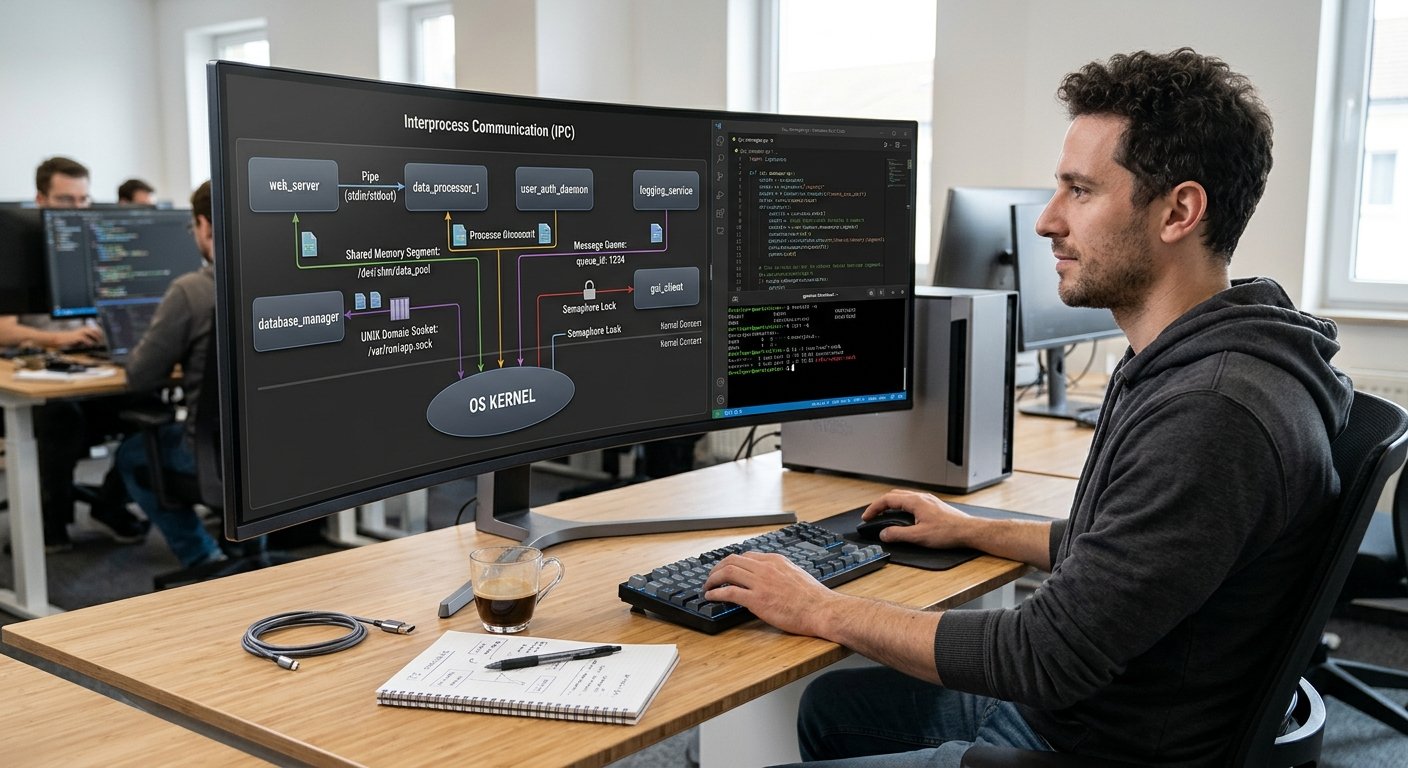
There are several IPC mechanisms provided by UNIX: pipes, shared memory, message queues, signals, semaphores and UNIX domain sockets. There are various characteristics, advantages and limitations of each method and they are suitable for specific requirements of application. Knowing these mechanisms helps to create efficient software architectures, avoid data corruption and manage communication between processes effectively.
What is Interprocess Communication (IPC)?
Interprocess Communication involves the techniques that an operating system gives to separate processes for exchanging information and coordinating their activities. Typically, each process runs in its own virtual address space; that is, a single process can not directly access another process’s private memory. This separation can enhance the stability and security of the system as an error in one process is less likely to affect the other. However, often processes need to cooperate, share the results or react to events created by other processes. IPC makes it possible without breaking the isolation between processes by offering controlled communication channels.
In UNIX and UNIX-like operating systems, IPC mechanisms are part of the operating system’s kernel. They can be accessed by developers via system calls, file descriptors and standard programming interfaces like the POSIX API. For instance, there may be several worker processes running on a web server to process web requests, as well as other processes to handle logging or background operations. These processes require a means to share information and to coordinate operations. IPC enables this communication without having to wait for the end of the other processes. The right mechanism will depend on the communication bandwidth, the size of the data being communicated, the synchronisation requirements, etc., and if the processes are running on the same computer or on different computers.
Significance of Interprocess Communication
The importance of IPC is that modern applications do not usually perform all operations in one process. Multiple processes can provide improved reliability, security, responsiveness and resource management in an application. For example, the request handling, database operations and background processing can be in different processes in a server application. If a problem occurs with one component, the operating system can isolate this failure and run the remaining components if the architecture supports this.
Another significant advantage is enhanced resource coordination. Different processes can require access to information shared resources, like configuration data, processing results, or application state. If there is no communication pathway, it can be challenging to coordinate these operations and lead to errors. IPC has a structure for sharing and synchronizing access to resources. It also facilitates scalable application design where components are independent and communicate through clear interfaces. Software developers can then create software that’s simpler to maintain, extend and troubleshoot. But the choice of the wrong IPC mechanism can add unnecessary overhead, synchronization issues or performance restrictions.
Main UNIX Interprocess Communication Mechanisms.
There are various IPC mechanisms that UNIX offers, for addressing specific communication and coordination issues. Some mechanisms move data directly, others manage access to shared resources or provide information to processes of relevant events.
The differences will help developers choose the most suitable option for their applications.
1. Anonymous Pipes
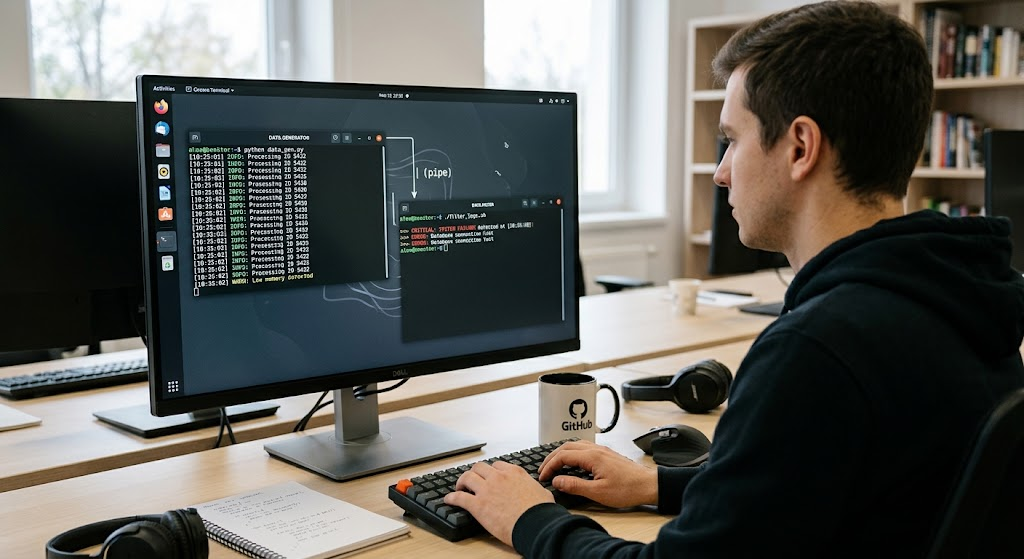
One of the simplest IPC mechanisms provided by UNIX is anonymous pipes. They are a means for one process sending information to another process, typically in one direction. The pipe is generated by a pipe() system call which returns a pair of file descriptors, one for reading and one for writing. One process writes information into the pipe, while another reads the information from it. Pipes are a byte stream and do not maintain message boundaries automatically. The receiving process must be aware of the data format and know the amount of data to be received in each logical message.
Anonymous pipes are very useful when two related processes require communication. The UNIX shell pipeline is one such example: the output of a command is fed into the input of another command. For example, the following command: ls | grep “.txt” sends output from the ls command to the grep command, where it is filtered. The advantage of anonymous pipes is that they are directly supported by the operating system and seamlessly plug into the file-descriptor abstraction. They are, however, normally employed in between procedures that have a relationship, like a parent and its kid. They also lack flexibility since they usually are one-way, and need extra pipes to accommodate two-way communication.
2. Named Pipes (FIFOs)
Named pipes, otherwise known as FIFOs, further the use of anonymous pipes by making it possible for arbitrary processes to trade between each other. Named pipes have known entries in the file system whereas anonymous pipes are pipes through file descriptors through related processes. They are created by the developers with the system call ‘mkfifo’, or the shell command of the same name. After it is created, various processes may access the FIFO for reading or writing, even if they are not related via a parent-child relationship.
Named pipes are useful for applications that must communicate locally but do not necessarily need to be on a network. For instance, a background monitoring service can write status updates into a named pipe and another application reads and displays the status updates. This enables the programs to run separately, but share information via a shared communication point. The other advantage of named pipes is that it is a very familiar file-descriptor interface, making them relatively easy to implement. But they are normally not message-oriented, and copying the data and using the kernel to send it may impact their performance. As with any other blocking operation, developers need to be careful not to block while opening or reading a FIFO that has not yet been opened by the other process to which they want to communicate.
3. Shared Memory
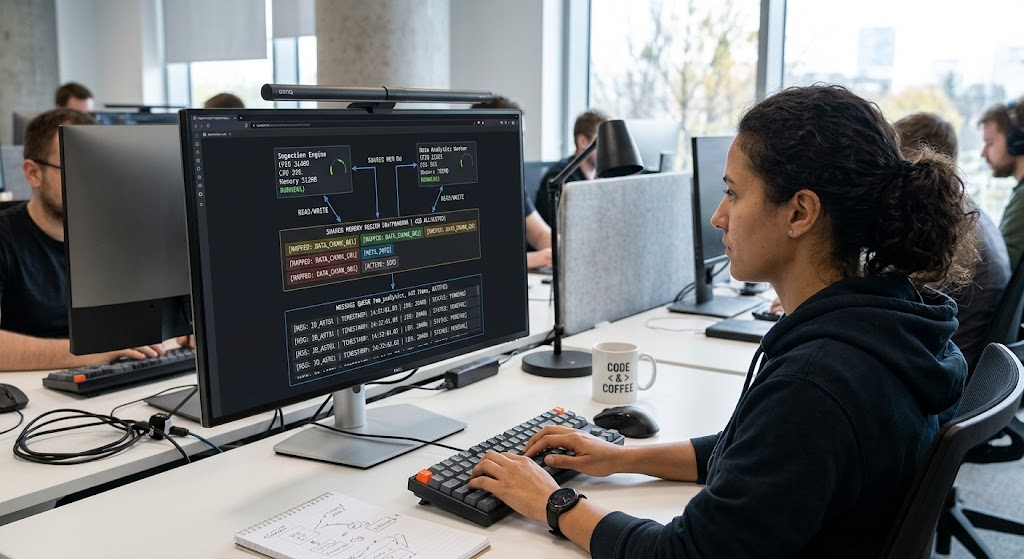
One of the fastest IPC methods in UNIX systems is the shared memory that lets several processes access the same area of memory. Processes use a shared memory address space, thus avoiding the frequent need to pass data back through the operating system kernel. After establishing the sharing of the same memory, one process is able to write data that another process can read directly. Shared memory can be implemented in UNIX systems like POSIX shared memory interface, which is typically achieved using functions like shm_open() and mmap().
When processes require the sharing of large volumes of data or frequently accessed data, this is especially useful. For instance, a video processing application could employ shared memory to enable multiple processes to access the image frames without having to move the entire image data structure between them. This can greatly cut down on communication overhead and enhance performance. Shared memory, however, may pose synchronization problems because several processes can try to access or modify the same memory at the same time. If not coordinated, one process might be overwriting data while another process is reading it. Developers thus have to use the shared memory in conjunction with synchronization tools like semaphores or process-shared mutexes. Careful management of memory allocation, access permissions, initialization and cleanup are also needed in shared memory.
4. Message Queues
Message queues provide a way for processes to communicate via a structured message carried in messages stored and managed by the operating system. While a pipe processes data as a stream of bytes, a message queue stores each message with their own boundary. A sending process is used to enqueue a message, a receiving process to dequeue a message when required. UNIX offers several different types of message queues, such as System V message queues and POSIX message queues. The functions mq_open(), mq_send(), mq_receive(), and mq_close() are used for POSIX message queues.
When processes have to communicate asynchronously, the use of message queues is particularly convenient. For instance, one might have an online ordering system that queued up customers’ orders while separate background queues were used to pull and process the orders. It is not necessary for the application that receives the orders to wait until every order is completed to accept another order. Based on the implementation, the message may also include identifiers or priority information. This makes message queues useful in a task distribution system and event-driven systems. But queues have drawbacks: They impose limits on the size of messages, they have a limited storage, and there is extra kernel overhead. The developers have to be aware of what happens when queues are full, when a process waiting for messages is delayed, and when a receiving process dies unexpectedly.
5. Signals
Signals are notifications sent to one process from another to indicate some event. Signals aren’t intended for moving large amounts of application data, unlike pipes, shared memory, or message queues. Rather, they convey the need for something to be done. UNIX offers signals for certain exceptional conditions, interruption of a process, and terminating a process. Examples are SIGTERM for terminating a process and SIGINT, usually sent when Ctrl+C is pressed in a terminal.
Processes may send signals via functions like kill(), and signals may be handled via functions like sigaction(). An administrator may send a SIGTERM to a server process, for instance, when the administrator asks the server process to terminate. The server may react by denying further requests and doing cleanup operations prior to its termination. Signals can be helpful because they offer a lightweight notification mechanism without the need to set up a dedicated data channel. They are, however, of limited information carrying capacity and must be handled carefully due to the possibility of signals interrupting normal operation. Developers also need to be aware of signal masking, signal behavior, and limitations on the operations that are allowed to be performed within signal handlers.
6. Semaphores
Synchronization methods to coordinate access to shared resources are called semaphores. They are often spoken about in the context of IPC mechanisms, but they are not used for the transfer of application data. Rather, they coordinate the activities of processes and ensure that no conflicting operations occur. Semaphore is a mechanism which keeps a counter that counts the availability of a resource or how many operations can happen simultaneously. This counter is decreased or increased by processes performing operations that acquire or release access.
For instance, if multiple worker processes have to access a common memory area with application data. If no synchronization is provided, more than one worker may be modifying the same record at the same time, leading to inaccuracies. A semaphore can be used to prevent more than one process from accessing a protected area at any one time. To implement semaphores, POSIX includes the functions sem_open(), sem_wait(), and sem_post() to open, wait for, and post a semaphore. Semaphores are very useful in producer-consumer applications, shared memory applications, and multi-process server architectures. But, misusing semaphores can lead to deadlocks, waiting indefinitely or synchronization errors. Clearly defined rules must be implemented for acquiring and releasing semaphores and processes must be designed to deal with failure.
7. UNIX Domain Sockets
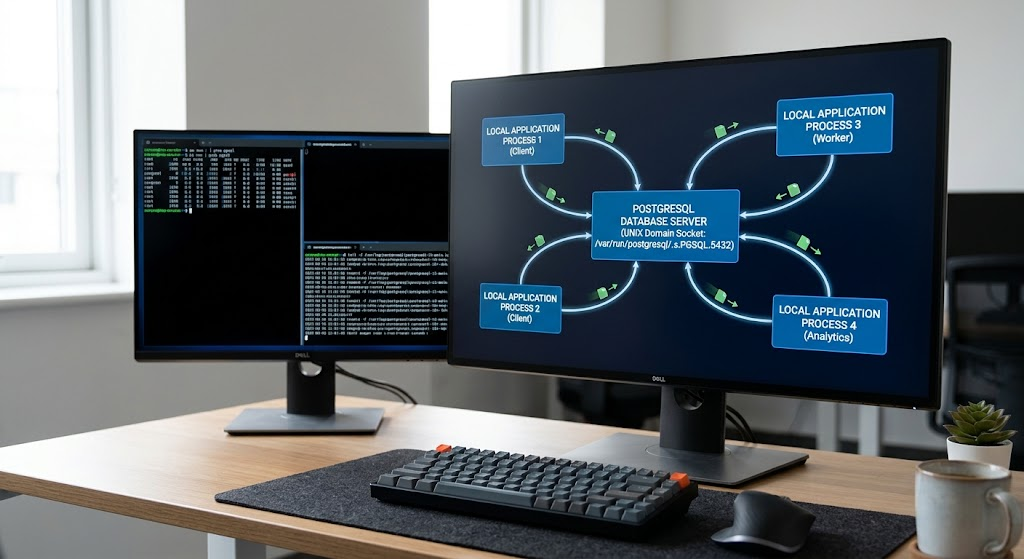
UNIX domain sockets are a flexible way of communication between processes that are running on the same computer. They provide communication via socket interface akin to that of network applications. UNIX domain sockets are different from regular network sockets, in that they don’t require communication to be sent across an external network interface. They can use filesystem paths, or abstract socket addresses on the operating system. They are typically created by functions like socket(), bind(), listen(), accept(), connect(), and send().
UNIX domain sockets are of special value for local client-server applications. One instance of this is to have a database service listening on a UNIX domain socket and application processes connecting to it to run queries. They can be used as a stream socket or a datagram socket, depending on the socket type. Stream sockets give an assured, connection oriented byte stream, and datagram sockets maintain individual messages. If the relevant facilities are provided, then UNIX domain sockets can also be used for sending and receiving file descriptors and credentials. They have the most significant benefits of being flexible, efficient in local communication, and easily compatible with the socket programming paradigm. But these are typically confined to the same machine and involve relevant connection management, permissions and error handling.
An Overview on UNIX IPC Mechanisms
All these mechanisms are used for interprocess communication or coordination, but each has different design and usage. Anonymous pipes are good for communicating between related processes, and named pipes are good for communicating between independently started processes. When large sets of information can be shared between processes, shared memory can be used for high-speed access to shared data. Message queues are useful for structured communication, especially in an asynchronous environment.
Signals are more appropriate for notifications than for data transfer, and semaphores provide coordination of access to mutually shared resources. UNIX domain sockets offer a locally flexible communication mechanism for client-server applications. Knowing this difference makes it easier for developers to not overcomplicate their use of mechanisms where it might not be necessary.
Comparison of UNIX IPC Mechanisms
| IPC Mechanism | Primary Purpose | Main Advantage | Main Limitation |
| Anonymous pipes | Data transfer | Simple and efficient communication between related processes | Usually used between related processes and commonly one-way |
| Named pipes (FIFOs) | Data transfer | Allows unrelated local processes to communicate | Byte-stream communication; blocking behavior requires care |
| Shared memory | Data sharing | Very fast access to large amounts of shared data | Requires synchronization to prevent conflicting access |
| Message queues | Structured data transfer | Preserves message boundaries and supports asynchronous communication | Queue capacity and message-size limits; kernel overhead |
| Signals | Event notification | Lightweight way to notify a process about an event | Carries very little application data |
| Semaphores | Synchronization | Coordinates access to shared resources | Incorrect use can cause deadlocks or indefinite waiting |
| UNIX domain sockets | Local process communication | Flexible communication for local client-server applications | Generally used for communication between processes on the same machine |
| IPC Mechanism | Primary Purpose | Main Advantage | Main Limitation |
| Anonymous pipes | Data transfer | Simple and efficient | Tends to be used between two related processes. |
| Named pipes | Data transfer | Allows unrelated local processes to communicate | Limited flexibility and byte-stream communication. |
| Shared memory | Data sharing | Extremely fast communication speed | Requires synchronization. |
| Message queues | Structured data transfer | Preserves message boundaries | Queue capacity and maximum message size are limited. |
| Signals | Event notification | Lightweight notifications | Limited data transmission. |
| Semaphores | Synchronization | Controls access to shared resources | Deadlocks may occur if not used correctly. |
| UNIX domain sockets | Local process communication | Flexible client-server communication | Typically used only on a single machine. |
Synchronization in UNIX IPC.
Synchronization is used to coordinate multiple processes in a way that they work correctly with each other, sharing resources or exchanging information. If not synchronized, processes can perform at the same time in unpredictable ways, leading to race conditions. A race condition is when the result of a transaction varies depending on the sequence of processes running concurrently. For instance, two worker processes may try to increment, in almost the same time, a shared counter. When both read the value before either writes its update, the second one could end up getting overwritten.
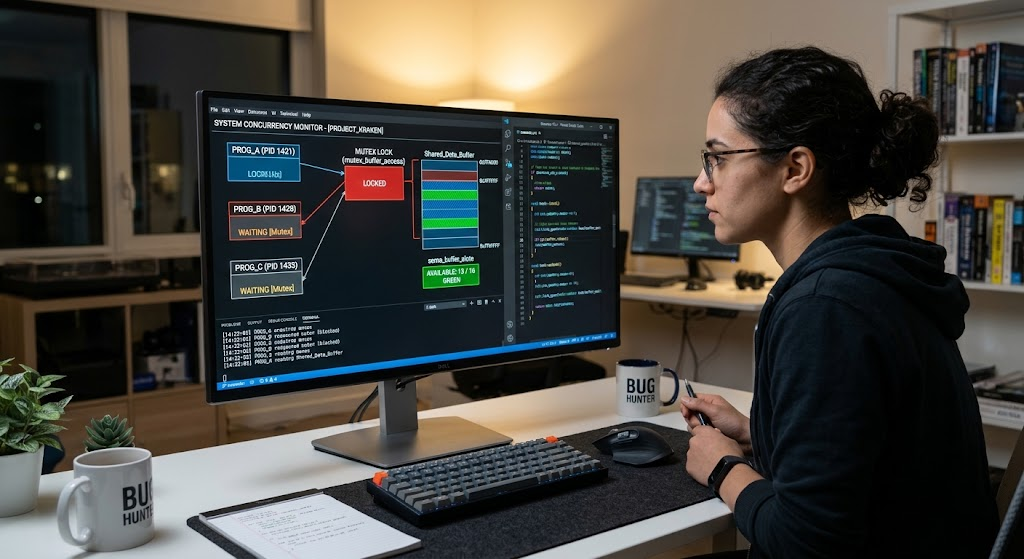
The various synchronization tools available in UNIX are semaphores, mutexes, condition variables and file locking mechanisms. When used in a process-shared manner, a mutex can be used to ensure that only one process or thread is allowed to enter a protected section at a time. Semaphores can be used to synchronize access to resources, or to limit the number of processes accessing a resource simultaneously. Condition variables are used to wait for a condition to be satisfied, usually in conjunction with a mutex. The right kind of synchronization to use is dependent on the communication architecture and resources being shared.
Understanding Race Conditions
In applications that have multiple processes using shared data, race conditions are a common problem. Think of an application involving the banks where two different processes try to modify the same balance in the bank account. If both read the balance before either finishes updating the balance, they could compute inaccurate information. This can lead to an incorrect final balance since one update would overwrite the other.
Developers need to make sure that operations related to this problem are performed safely. A way to do this is to create a critical section protected by a mutex or semaphore. A critical section is a segment of a program that accesses shared resources that must be executed exclusively by a single operation in the program. This way, a single process can execute a specific update at a time, minimizing data inconsistencies. Other methods of maintaining correctness when dealing with shared information are provided by database transactions and atomic operations.
Preventing Data Corruption
Data corruption is the result of processes changing data without coordination. When using shared memory, more than one process can write to the same memory region directly and this becomes significant with this problem. It is important for the developers to define ownership rules, to secure critical sections and to keep data structures consistent when they are updated.
Another practice that should be used where applicable is atomic operations. Atomic operations are executed as a whole – no other process or thread can observe an incomplete update. Developers should also check the messages received from other processes, catch up on unexpected termination and do not assume that a communication operation always succeeds. If the application needs to exchange information reliably, then it is necessary to define message formats, deal with the communication errors and set up proper recovery methods. With the appropriate synchronization tools, these practices can be used to ensure data integrity and increase the reliability of the application.
Practical Examples: Selection of the appropriate IPC Mechanism
The choice of IPC mechanism is dependent on the communication needs of the application, the amount of data to be communicated, the performance requirements and the architecture of the application.
What works for a simple command line tool may not be suitable for a high speed server. Processes should be designed with an awareness of one-way versus two-way communication, maintaining message boundaries, and whether the processes are local or networked.
Example on how to communicate between shell commands
Anonymous pipes are also good to use when piping processes together in shell scripts. A command might list files and send the output to another command for filtering or processing, for instance.
This way, no temporary files are created and multiple commands can interact with each other from a continuous data stream.
Example on the use of Background Task Processing
Message Queues: Good for distributing tasks to independent background workers. An application can put tasks in a queue, with multiple workers getting them from the queue and working on them in parallel.
This is more flexible as task submission and task execution do not have to be performed in the same process.
Example 3: High-Speed Data Sharing
Shared memory can be helpful when processes need to share large amounts of data regularly. This can be useful for applications in image processing, scientific computing or real time data analysis.
But to handle this situation, developers need to put in place the synchronization to prevent the processes from altering the shared information concurrently.
Example 4: Local Client-Server Applications
When two different local applications need to communicate with each other in a client-server architecture, UNIX domain sockets are suitable. A local socket, for example, can receive connections from several application processes using a database service.
This could simply be a communication interface that does not depend on an external network.
Example 5: Process Management and Notifications
Signals can be used when a process wants to let another process know that something has happened.
A process manager could signal the service with SIGTERM to ask it to gracefully terminate. The receiving service is responsible for receiving the notification and cleaning up as needed prior to its exit.
IPC in Server Software and Modern Application Architectures
The importance of interprocess communication in server software lies in the fact that many servers break their operation into a variety of processes. Each worker may serve one client request, and other processes may be used for logging, caching, communicating with the database and other background tasks. IPC enables these parts to pass information without having to run in a single, big process.
UNIX domain sockets are a convenient means of communication between independent programs for local services. Use of shared memory can be beneficial for high speed data access, and message queues can be beneficial for distributing tasks asynchronously. In a more complicated distributed application, network sockets and other communication protocols enable processes running on separate machines to communicate with each other. It is important for the developer to note that while UNIX domain sockets are used for communication between two computers on the local area network, Internet domain sockets are used for remote communications across networks (typically over TCP or UDP). Selecting the right mechanism facilitates effective communication and ensures the organization and independence of the application’s components.
Security Considerations in UNIX IPC
Application-sensitive information can be revealed via communication channels, or unauthorized access can be gained to shared resources while designing IPC systems, so that security should be considered. Developers should ensure that only allowable processes are allowed to use communication endpoints. The permissions of filesystems, however, can be used to limit access for named pipes and UNIX domain sockets to any processes or users. Access rights to prevent unauthorized access to data in shared memory and message queues must be set up appropriately.
However, the applications should validate incoming data, not taking the word of untrusted messengers for granted. This is particularly relevant if more than one user or independent service can access the IPC interface. Developers should also refrain from unnecessarily displaying sensitive data and should make sure resources are freed up when processes are terminated. Careful use of synchronization mechanisms should be used in applications using shared memory to ensure that only intended modifications are made. By implementing IPC design with security in mind, you minimize the chances of unauthorized access, data corruption, and unexpected behaviors of your application.
Best Practices for Designing Efficient UNIX IPC Systems
By choosing mechanisms that best suit their applications, developers can enhance IPC performance and reliability. Simple communication tasks should usually employ simple mechanisms like pipes, and not be unnecessarily complicated. Shared memory might be useful for applications sharing a lot of data, and message queues might be useful for applications that need to communicate asynchronously and in a structured way.
Before implementing communication features, it is also important to design synchronization and error handling procedures. It is important to consider how to handle a process that unexpectedly ends, a full queue and an unavailable communication endpoint. They should also refrain from taking a lock for a longer time than needed, as this might lower the performance level and increase the occurrence of deadlocks. Testing communications in parallel workloads can expose problems that can’t be discovered while running a simple program. Last, tracking resource consumption, identifying the format of messages and defining responsibilities for shared resources can help to make IPC systems more manageable as applications develop.
Conclusion
UNIX interprocess communication allows the developer several powerful tools for developing applications that consist of separate parts that communicate within each other. The anonymous pipes and named pipes allow for simple data communication, and shared memory allows for quicker access to common data. Structured asynchronous communication is made possible by message queues, event notification by signals, and resource sharing coordination by semaphores. UNIX domain sockets provide flexible communication for local client/server applications.
All of these mechanisms have their pros and cons, and choosing the appropriate mechanism involves understanding the performance, synchronization, security and communication needs of the application. Another important aspect for developers is avoiding race conditions, using and handling shared resources wisely, and having sound error handling practices. Developers can create efficient, secure, and maintainable UNIX applications using local services, background processing systems, and server software by using the proper IPC mechanisms and effective synchronization methods.