Introduction
With the rise of artificial intelligence (AI), we’re seeing computers become smarter through improvements to how they process information, understand human language, and search for relevant data. As AI becomes more advanced, traditional databases are being supplemented by vector databases. Vector databases are a special type of database that stores numerical data in the form of vectors.
They are an important part of AI systems as they help with semantic search, machine learning, recommendations, and retrieval of Augmented Generation. Vector databases allow computers to search for information based on the meaning rather than specific keywords. Having an understanding of how vector databases work can help developers create smart solutions.
What is a Vector Database?
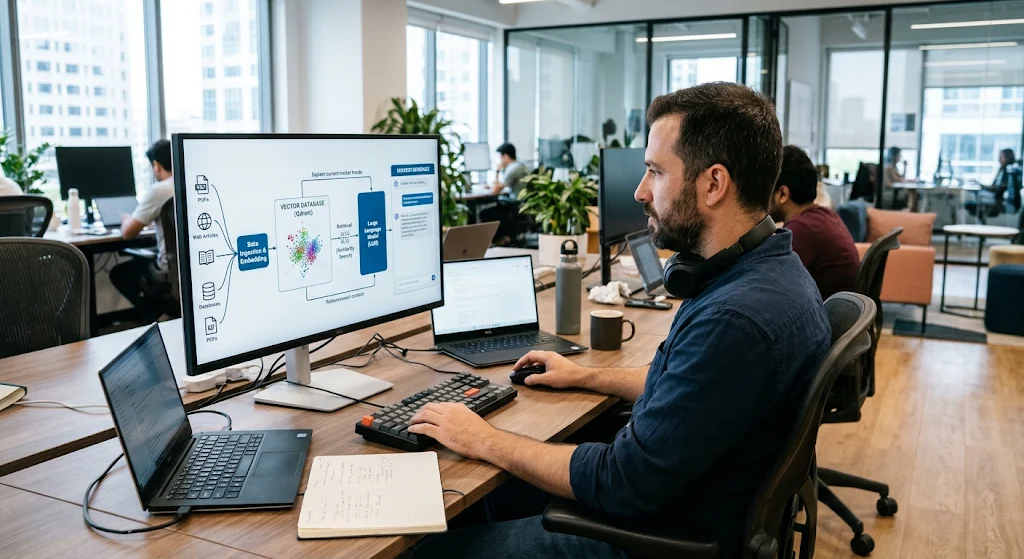
What Is A Vector Database is a special type of database that stores vector embeddings. These are numerical data created using machine learning models. Vector databases are designed to store and search for vectors rather than traditional databases that simply store data in rows, columns and tables. Instead vector databases store high dimensional numerical data that represents the attributes and meaning of objects. Objects could be text, images, audio, video, and other digital sources. Vector databases will take a search query and convert it to a vector and match it against others to find the most similar results.
They are a useful tool to use as modern AI applications deal with huge amounts of unstructured data. This is data that does not have a particular structure that can be searched through easily with traditional databases. For example, if there are thousands of customer reviews, product descriptions, images, and support documentation that need searching through intelligently; a Vector Database can store vector embeddings of these to search for relevant information based on the meaning of the request. Vector databases can also make use of metadata to filter results and have advanced indexing techniques.
How Vector Embeddings Work
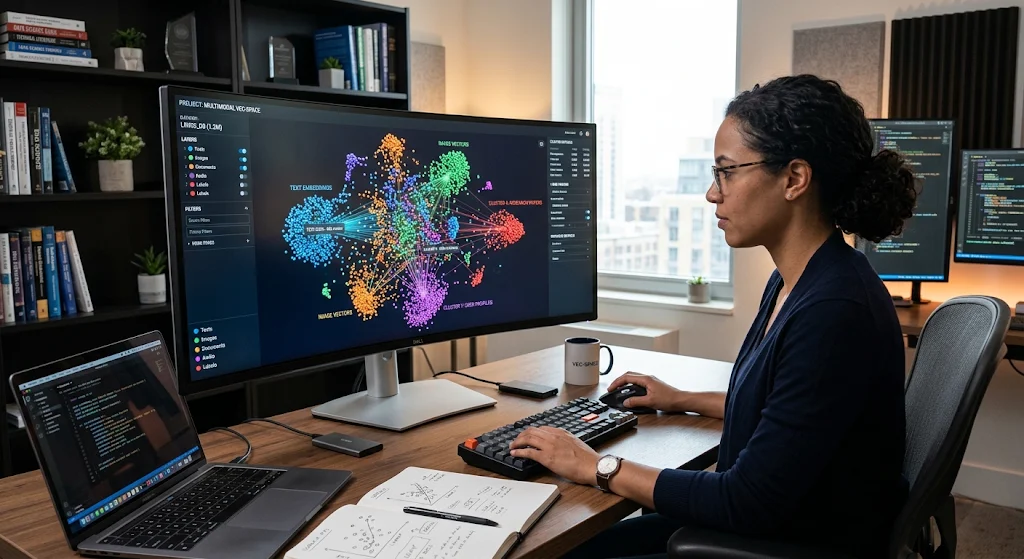
Vector embeddings are numerical data that allow computers to understand the relationship between different pieces of information. An embedding model will take an input like a sentence, image, or audio and convert it into a list of numbers known as a vector. The numbers represent the different attributes of the information in a mathematical space.
Information that has similar meanings will have vectors that are close to each other. For example, if someone searches for “How can I improve my computer’s performance?” and “Ways to make a computer run faster”, these have different words but are similar in meaning. An embedding model can create vectors to show how similar these sentences are and allow a Vector Database to search for related information.
How To Create Vector Embeddings
To create vector embeddings you will need an embedding model. Once you have your information you want to store such as documents, images, or audio files, the embedding model will process this information and create a vector (a list of numbers) with a set number of dimensions.
This vector will then be stored in a Vector Database. When a search is made the same or a compatible embedding model will be used to convert the search query into a vector. The vector will then be matched with the vectors already stored using mathematical calculations. This could be cosine similarity, Euclidean distance and dot product.
Different Types of Information
Vector embeddings can be created for more than just text. Modern machine learning models can create vector embeddings for different types of digital data. Vector databases can be used for multi-modal applications. Text can be embedded to understand the meaning of words, sentences, and documents. Images can be embedded to understand the attributes such as objects, shapes, colours and patterns.
Audio can be embedded so recordings can be searched for based on similarities. Videos can be embedded by using the individual frames, descriptions, or other attributes. This can help create systems that can link information together. For example, an AI application can allow someone to search for an image using text.
10 Ways Vector Databases Are Changing Artificial Intelligence And Searching For Data
Vector databases are becoming an important tool to use as they allow you to search for data in modern AI applications. Vector databases can find similar numerical data which can be used across many industries and technical areas.
They help applications process information more effectively. Below we have listed 10 key reasons why vector databases are changing artificial intelligence, machine learning, and searching for information.
1. Improve Semantic Searches
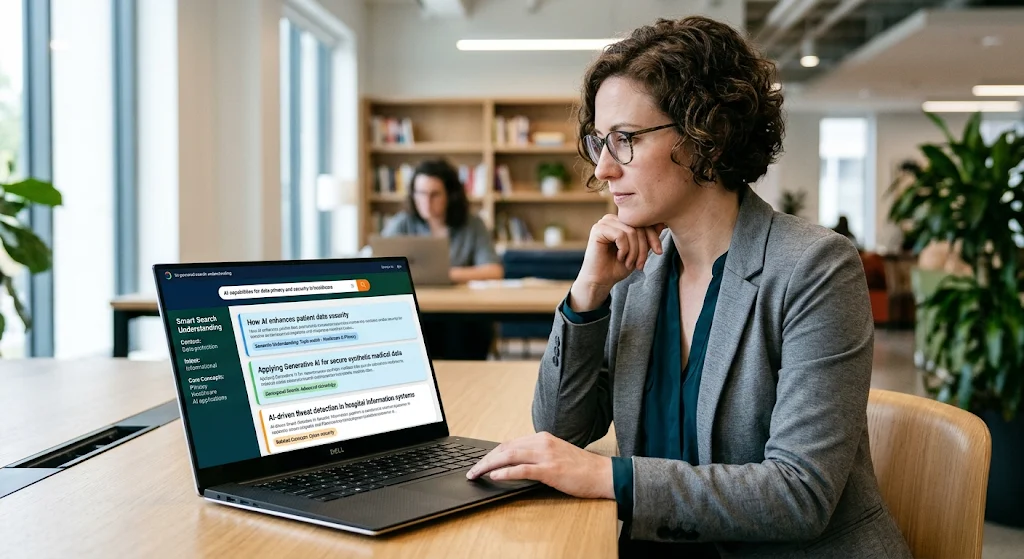
Traditional search engines often rely on keywords to find relevant information. Whilst this can be useful, it can be problematic if someone describes something differently. Semantic search solves this by searching for the meaning and context of a search. Vector databases help with semantic searches by using vector embeddings. For example, if someone searches for “affordable ways to travel” they could get information about budget holidays, cheap accommodation, and cheap transport.
This makes searching for information much more flexible. Semantic search can be used by businesses to help improve their search functionality, customer support, digital libraries, and enterprise information.
2. Intelligent Recommendations
Recommendation systems help people find products, services, entertainment, and other information that they like. Traditional recommendation systems often rely on categories, ratings, and user activity. Vector databases can be used by comparing vector embeddings of products, users and preferences. For example, an online shopping site can create vector embeddings of product descriptions to find items that have similar attributes to what the customer has viewed.
Streaming platforms can also use vector similarity to search for films, programmes or music with similar attributes. This means recommendation systems can take into account similarities that may not be apparent from basic categories. Vector databases can help businesses create more intelligent discovery systems by finding relevant items quickly.
3. Retrieval Augmented Generation (RAG)
Retrieval Augmented Generation is a type of AI architecture that uses information retrieval. Large language models can use external knowledge sources. Vector databases are a key part of many RAG systems. They store vector embeddings and allow relevant information to be found. When a query is sent to the system, an embedding model will convert the question into a vector.
This will then be matched against the vectors of the documents. Relevant passages will then be found and sent to the language model. This will help generate responses based on specific information rather than just relying on information from their training. RAG can be used by businesses to create document assistants, enterprise search applications, research tools, and customer support that can answer questions using their own information.
4. Intelligent AI Chatbots
AI chatbots are becoming a popular way to answer questions, provide customer support, and help with everyday tasks. However, if a chatbot does not have access to specific information to answer a question it can be problematic. Vector databases can help by providing access to relevant information. For example, a customer service chatbot can search through product manuals, FAQs, company policies, and previous support documents.
When a customer asks a question, the system will search for relevant information and send it to the language model. This makes the chatbot more informative. Vector databases can also be used to create memory within conversations by helping find relevant information from previous interactions.
5. Improve Image Recognition
Image recognition uses machine learning models to identify objects, patterns, and attributes in photos and images. Vector databases can help by searching for similar images. An image embedding model will convert photos into numerical data that includes important visual attributes. These can be stored inside a Vector Database.
When a user uploads an image or describes an image they can search for similar images. This can be useful in e-commerce to find similar products to an image that has been uploaded. It can also be used in digital asset management, image libraries, medical research, and organisation. Vector databases can help applications search for visual information based on similarities.
6. Multi Modal Search
Modern AI applications often need to process information from multiple sources. Multi modal search can be used to find related information from text, images, audio, and video. Vector databases can be used by storing vector embeddings from different sources.
For example, a media platform can allow users to search for videos using text descriptions. A digital archive can also be used to link images to related documents and audio. This will depend on the embedding models and indexing techniques. As multi modal AI continues to develop vector databases can be a key part of creating search applications.
7. Improved Personalisation
Many businesses will have lots of information on what their customers are interested in, their preferences, and what they have browsed. This can help organisations provide more relevant services by analysing this information. Vector databases can help by creating vector embeddings of customer interests and available content. This can be matched to find products, articles, services, or information that could be relevant.
For example, an education platform can recommend resources based on what subjects the student has previously looked into. An online retailer can also find products with similar attributes to what the customer has shown interest in. This can create more relevant digital experiences. However, businesses should ensure they have the correct privacy, access, and responsible data practices in place.
8. Intelligent Document Search
Many organisations will have lots of documents to store such as reports, technical manuals, contracts, research papers, and policies. Finding specific information can be difficult. Vector databases can help by searching for documents based on semantic similarities. Before documents are indexed they can be split into smaller sections and converted to vector embeddings using the appropriate model.
Metadata can be added to show where the information came from, what category it is in, and other relevant information. When an employee searches for information, the system will find sections of documents that have semantic similarities. This can be useful for enterprise knowledge management, legal research, academic libraries, and internal information. It can make it easier to find useful information.
9. Fraud Detection
Fraud detection uses data analysis and machine learning to find anomalies. Vector databases can be used by storing vector embeddings of transactions, user behaviours, or other relevant information. Complex data can be converted to numerical data using machine learning models so similarities can be found. For example, a financial institution can use vector embeddings to identify transactions that are very different to usual behavioural patterns.
This can help analytical systems identify unusual activities. Vector databases on their own will not provide an effective fraud detection system. However, they can help create more advanced machine learning applications by organising and finding similar patterns. This can be useful in financial services, cyber security research, and risk analysis.
10. Speed Up AI Application Development
When developing modern AI applications it is important to have infrastructure in place to handle large amounts of information. Vector databases can help by providing developers with tools to store vector embeddings, create search indexes, add metadata filters, and include search functionality. Many platforms will have APIs, SDKs and integration with machine learning models to make it easy to implement.
This means development teams can focus on creating features for their application. They can also experiment with different embedding models. As businesses invest in generative AI, intelligent search and automating information vector databases can be a useful piece of infrastructure. They are flexible and can help create applications that can cope with increasing data sets.
Popular Vector Database Technologies
There are many Vector Database technologies available. They all have the same goal of storing and searching for vector embeddings but they vary in their architecture, deployment, indexing, and features.
Depending on the size of your data set, performance requirements, infrastructure available, developer experience, and complexity of the application you may want to choose a certain platform.
Pinecone
Pinecone is a managed Vector Database that can be used for similarity searches and AI applications. It provides infrastructure to store vector embeddings, index information, and search for relevant information using APIs. As it is managed it reduces the amount of infrastructure you will need to manage. This can be useful for semantic searches, recommendations, and retrieval of Augmented Generation.
Embeddings can be stored along with metadata and filtered to narrow down results. Pinecone can be a good choice if you want to create AI applications without having to manage all aspects of a Vector Database. It can be useful if your organisation requires a dedicated vector search service.
Milvus
Milvus is an open source Vector Database that can be used for high performance similarity searches. It provides different indexing and searching options. Milvus can be used to manage vectors along with structured metadata. It is commonly used for semantic search, image search, recommendations, and RAG.
It can be deployed on self hosted and managed options. It has been designed to handle increasing data sets and distributed workloads. This can be useful for organisations creating large scale AI applications. It can also be integrated with embedding models and machine learning models to create search systems.
Weaviate
Weaviate is an open source Vector Database that can be used to search for objects using vector embeddings. It allows developers to store objects along with vector embeddings and search for information based on semantic similarity. Weaviate can also be used for hybrid searches which combine vector similarity searches with keyword searches.
It can also be integrated with embedding models and generative AI tools. This makes it a good choice for intelligent searches, recommendations, document searches, and RAG. The ability to combine different search methods can be useful if you want your application to understand context whilst also searching for specific keywords, product names, or technical terms.
Chroma
Chroma is an open source database that can be used to easily store and search for information within AI applications. It provides tools to manage embeddings, documents, and metadata. It is popular amongst developers who want to experiment with AI applications and RAG. It can be used with different embedding models and provides features such as metadata filtering, dense and sparse vector searches, and multi modal searches.
It is easy to develop, making it useful for prototyping, local applications, and projects that require an easy to use search infrastructure. It can be used to organise document collections and find relevant information for AI assistants, chatbots, and other applications that require external knowledge.
Qdrant
Qdrant is an open source Vector Database that can be used for efficient similarity searching. It allows you to store vectors along with additional information known as payloads. This can be used to search for vectors with specific categories, dates, locations, etc.
It can also be used for hybrid searches, different vector types, and indexing. It can be useful for recommendation systems, semantic searches, AI assistants, and RAG. It can be deployed using self hosting or managed options. The ability to search for vectors and filter using metadata makes it a good choice for applications that require context based searching and specific searches.
Vector Databases Vs Traditional Relational Databases
Traditional relational databases and Vector Databases are both very different. Relational databases store information in a structured format. They contain rows and columns, with a set structure for relationships, data types and query language (SQL). They are great at looking up precise information in your application or updating transactions. Vector Databases are designed around storing information in vector form. Using similarity metrics they can look up information with similar values to the query. This means they are great at working with unstructured data and AI powered searches.
The main difference between the two is how they are used. If you wanted to find out how many customers were signed up in a certain time frame or what products cost a certain amount, you would use a relational database. Whereas if you wanted to find documents that talk about a certain topic, you would use a vector database. However it is not always necessary to use just one type of database. The two can work together. You could use a relational database to keep track of your customers, products and transactions. While also using a vector database to look up semantically related documents, descriptions etc.
How They Work with AI and Machine Learning
Vector Databases work closely with AI and Machine Learning. The vectors are created using embedding models. Machine Learning models identify patterns in the data and convert them into vectors. These vectors are organised into a vector database. This helps the application quickly look up information. In Generative AI applications, the language model may need to look up external documents or knowledge. Instead of adding all of the information into the model, the application can look up only the most relevant information using a vector database. This makes the information more manageable.
Another aspect is how you can improve your AI. You can try different embedding models, indexing and similarity metrics to improve the search. You can also add traditional keyword searches and metadata to your vector search to get more relevant results. However Vector Databases cannot understand the information. The quality of the embedding models, organisation of the database and how you search will affect its performance. If your embeddings aren’t created well or your documents are not organised correctly you could get irrelevant results. Therefore it is important to ensure your data is prepared properly, you choose the right model and test it. This will ensure your AI applications are successful.
Benefits of Using a Vector Database
Vector Databases can offer many benefits for an organisation creating modern AI applications. They can help give you more relevant search results. They can also search multiple types of unstructured data such as text, images, audio etc. depending on what embedding models and database you are using. They also use specialised indexing to quickly search large amounts of vectors. Many platforms also offer metadata filters, APIs and integrations to make development easier. This can be useful for organisations creating recommendation systems, intelligent assistants, enterprise search and generative AI applications.
They can also complement existing data. You can still use your traditional databases but add in vector searches to your application. This helps you improve existing systems. They can also help you create flexible applications. You can try using different embedding models and search methods depending on your project requirements. However you must also consider the cost, infrastructure, security and data issues. Depending on your application, you may not need to use a vector database for every AI application.
Issues with Vector Databases
There are some technical issues that you need to consider when using Vector Databases. Firstly, embedding quality. Since the Vector Databases use similarity searches based on numeric values, using the wrong machine learning model can cause irrelevant results. Secondly, using large amounts of high dimensional vectors can be computationally expensive and take up a lot of space.
As your data grows you may need extra infrastructure to ensure your search remains fast. How you split your documents, organise your metadata and use similarity metrics can also affect the quality of your search. Finally, they may not always give you the exact information you need. For example if your query is dependent on specific names, IDs or numbers. You can overcome some of these issues by using keyword searches.
Security and Data Issues
Security and data issues. The embeddings are created from the original data so should not be considered fully anonymous. You need to consider who has access to your vectors, what data they represent and whether any sensitive data needs extra protection.
You should implement proper authentication, authorisation, encryption and access controls. When using Vector Databases you must also consider how accurate your search results are. This is very important in industries that deal with sensitive customer data, financial data, healthcare data or internal data. Ensuring you plan and test your Vector Databases will ensure you are using them responsibly.
Future of Vector Databases in AI
As AI applications develop, Vector Databases will become more important. With developments in multimodal AI, you can now create applications that can link text, images, audio and video using similar or compatible embeddings. Hybrid searches are also becoming more important. Combining semantic searches with keyword searches will help you get more relevant results. AI agents are requiring new methods of searching for information from various sources. Vector Databases can help this by providing relevant documents, historical data and knowledge.
Vector searches are becoming more integrated into databases and cloud. Rather than having to use a specialist database, you can now use vector searches with wider data management systems. This will give you more flexibility. Improvements are also being made to the indexing, distribution, filtering and searching of Vector Databases. This means they can handle increasingly demanding tasks. However, how quick they are to search isn’t the only thing to consider. How accurate they are, secure they are, how scalable they are and how easy they are to integrate will all play a part. As AI continues to develop, Vector Databases are likely to remain an important part of your infrastructure.
Conclusion
Vector Databases are revolutionising AI and information retrieval. They allow you to search for information based on numeric values. Using vector embeddings, computers can compare text, images, audio etc. They can be used for a variety of uses including semantic search, recommendation systems, retrieval augmented generation, intelligent chatbots, image recognition, multimodal search and enterprise knowledge management.
There are many options available including Pinecone, Milvus, Weaviate, Chroma and Qdrant. Although there are some issues with data quality, storage, security and search accuracy, they can offer many benefits. They can complement your relational databases and help create advanced machine learning applications. This is helping create more intelligent, responsive and contextual experiences.