Machine learning is a field which has grown to become a base for what is today’s AI. What we see different in machine learning when compared to the past is that instead of us having to program in each and every possible issue, present-day systems are designed to identify from data the patterns which in turn they use to carry out a given task. Also, we tell the machine learning models what to study, what relationships to see in that data, and in return, we get it to put out predictions or to decide things about which we present it with. Today, this is used in a very wide range of fields which include business, finance, health care, transport, education, search engines, recommendation systems, and also many more digital services.
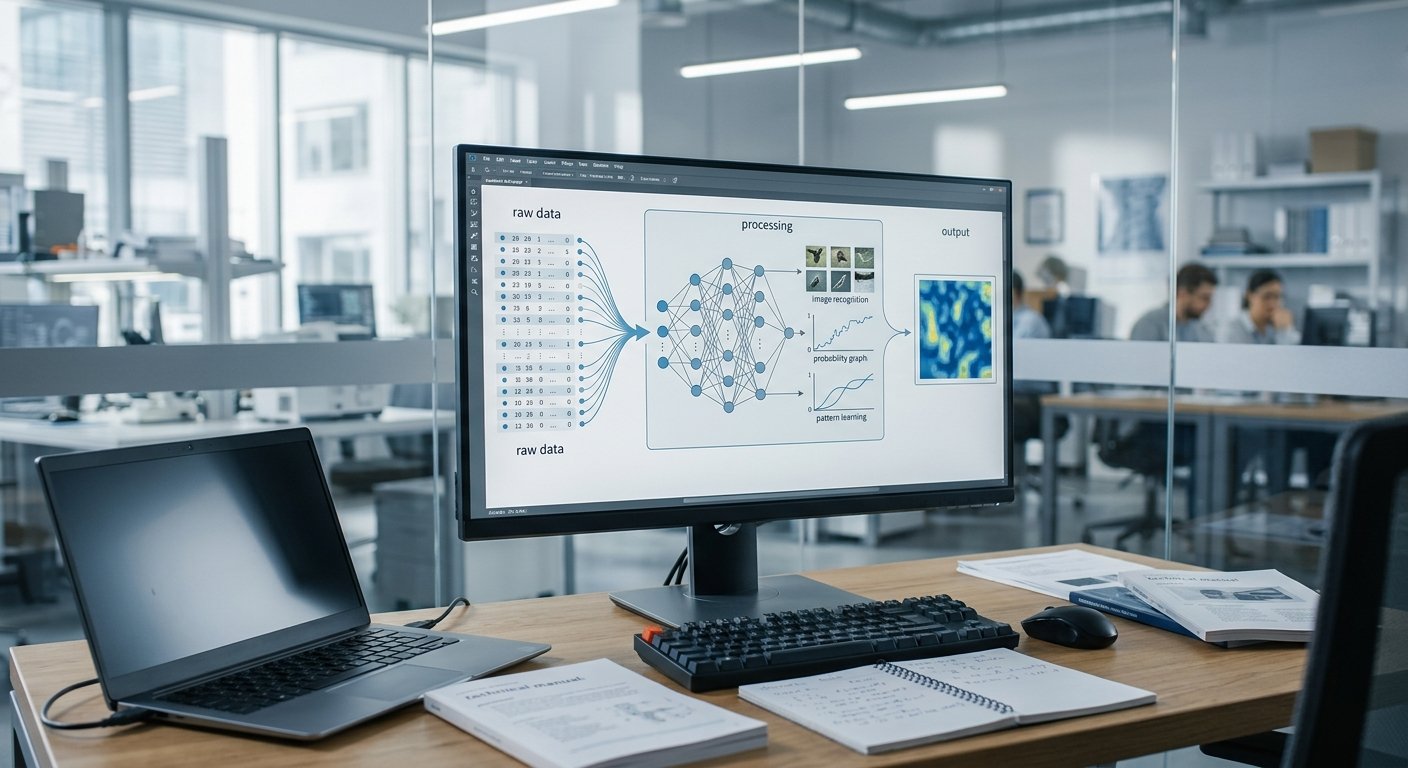
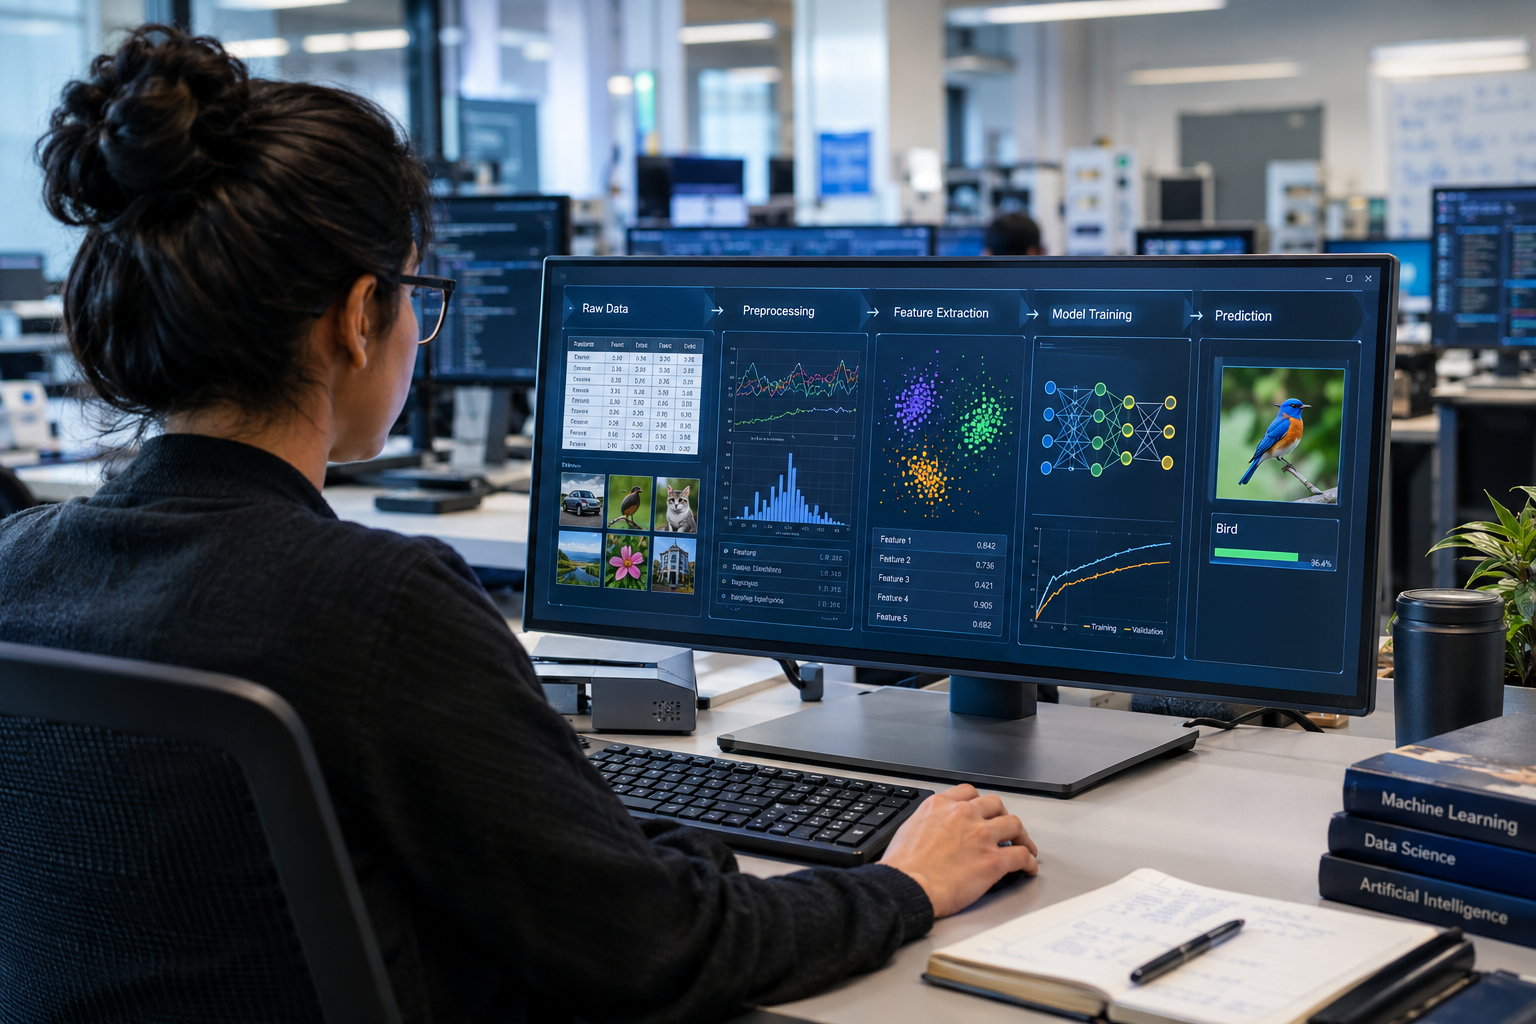
Data, algorithms, models, and predictions. Data provides what a system learns from; at the same time, an algorithm puts forth the math behind identifying patterns in that info. What comes out of this learning process is a model which then looks at new data and puts out a result. The quality of the result is based in large part on the quality of the data, the algorithm which we use, how the model is trained, and how we go about testing its performance.
What Is Machine Learning?
Machine learning is a segment of artificial intelligence which allows computers to identify patterns from data, which in turn does away with the need to program in very detailed instructions for each and every situation. We no longer tell the computer how it should react to every single input; instead, we present it with data which it uses to determine relationships within that info. For example, a system may analyze thousands of emails tagged as spam or non-spam, which in turn it uses to develop rules to put new emails into categories.
Computers do not replicate human learning in the exact sense. What they do is present mathematical models and use statistics to determine which patterns are relevant to the issue at hand. In the case of a model that is trained to predict vehicle prices, it will see associations between things like age of the car, how many miles on it, its general condition, and the price. After the model is trained, it then uses the information it “learned” to put a value on another car.
How Computers Learn From Data
The Role of Training Data
Training data is what we use to teach machine learning systems. What you put in that data varies by what you are trying to do: images, text, numbers, audio, financial transactions, sensor reports, customer action, etc. For a system which identifies objects in photos, we use image data; for a system which forecasts sales, we may use past sales info, price data, and which season it is. The examples you include in your training data are what the algorithm uses to identify which patterns are meaningful.
The quality of training data is very important. We see that data which contains errors, is missing info, has irrelevant examples, or does not represent real-world conditions will in fact put model performance at risk. Thus, prior to training, data which is to be used may need to be collected, cleaned up, organized, and labeled. Also, we find that good-quality training data gives the algorithm a better base from which to learn relationships, which in turn will also improve performance when the model is exposed to new information.
Machine Learning Algorithms
A machine learning algorithm is what we use in math to identify patterns and structure in data. We have different algorithms for different tasks which include classification, prediction, grouping, and anomaly detection. At training time, the algorithm looks at examples and changes the model, which in turn improves the results for the task. For instance, a model which we are training to predict used car prices may at first put out poor results, but with repeated training, we see improvement in its accuracy.
The algorithm is a key element in the learning process, but it is not the only issue which determines performance. Developers also pay attention to the quality of the data and the information put into the model and how the resulting system is tested. Very complex algorithms do not in and of themselves produce good results if the training data is of poor quality or is not appropriate for the issue at hand. In machine learning development, we see a process of training, testing, evaluation, and improvement.
Main Types of Machine Learning
In terms of categories of machine learning—supervised, unsupervised, and reinforcement learning—which they are. These fields of study are in learning what a system does and how it gets info back. In supervised learning, we use examples which have known results; unsupervised learning goes in to find patterns in data which we don’t predefine, and reinforcement learning which is about action and feedback. Also, it is that each of these has best use in certain types of issues and applications.
Understanding these methods also explains why machine learning has application across a large number of fields. A financial company may use supervised learning for detecting transactions characteristic of fraud. Also, a company could use unsupervised learning to find groups of customers whose actions are the same. In environments that play out in an issue of making decisions, a system may use reinforcement learning, which it will use to determine what set of actions play out the best.
Supervised Learning
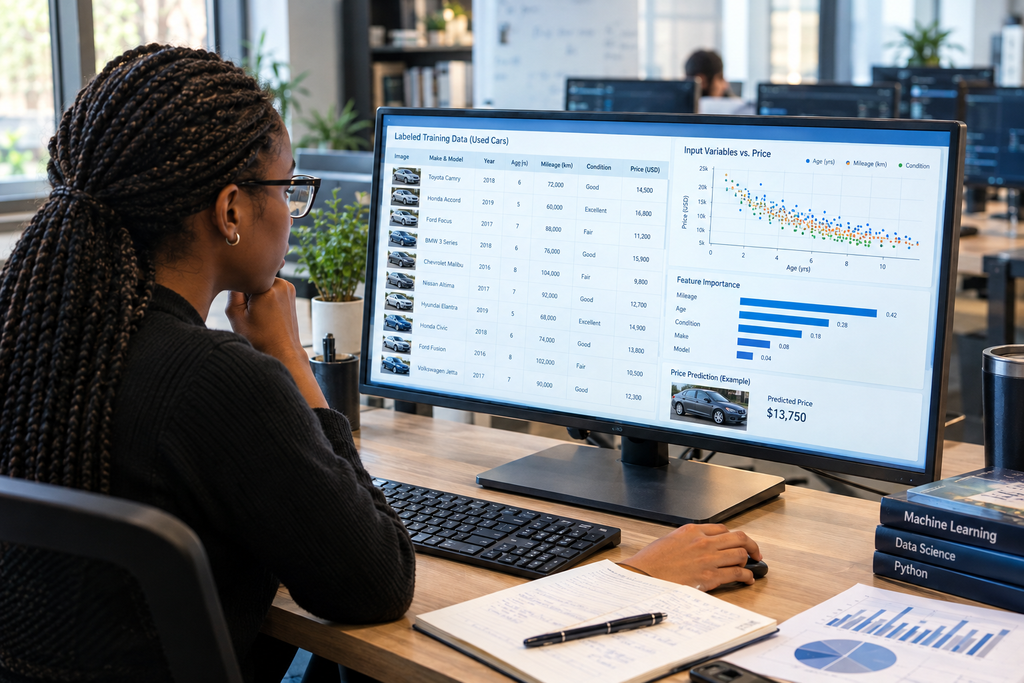
Supervised learning models are provided sets of input and their corresponding known results, at which point they are trained. From that training, the model is able to determine the relationship in what it is shown. For example, a system may be trained on a set of medical images which have been annotated with what issues were present. Also, in the financial world, we see systems trained on past transactions that are tagged as either legitimate or as an anomaly. Once trained, the model is put out into the field to analyze new info and to predict based on the trends it identified during the training phase.
Classification, and out of that which is a category of supervised learning tasks, is putting info into groups like determining if an email is spam. Regression, which is also a supervised learning task, is about predicting numbers, for instance, future sales or the home’s price. As we train the model, we use it to make predictions which are then checked against known results, which in turn allows us to see the error and improve the model.
Unsupervised Learning
Unsupervised learning is when you don’t have training examples which come with answers. Instead, the algorithm looks at the available data for patterns, similarities, relationships, or groups. A common example is in customer segmentation, in which a business may use an algorithm to identify groups of customers with similar purchase behavior without first putting those groups forward. The system looks at data characteristics and identifies what structures are present based on the methods it is given.
This approach works well when large sets of info are present but the specific patterns within them are unknown to the organization. Unsupervised learning, which in turn may put out of which we can identify groups of data, which may include odd observations, and also bring out relationships that require more in-depth look into. But what the system puts out still has to be looked at closely, as a group of data put out by an algorithm does not necessarily translate to a relevant real-world-based explanation.
Reinforcement Learning
Reinforcement learning is a method of learning through action in which a system is put into an environment and it performs tasks. We don’t just program in what is right or what is wrong into the system; instead, the environment which the system is placed in will give it feedback for its performance. That feedback may be positive, which in turn reinforces the action that was taken which brought about that result, or it may be negative, in which that action is deterred from being repeated. Over time, what we see is the system associates certain actions with success and with failure.
This approach works well in situations that require many decisions. A system may try out various actions, see the results, and then base its next move on that which was reported back to it. Also, unlike a basic prediction problem, reinforcement learning is in a series of decisions which at one time may play out over a long period and in which the present action may also have a role to play in what comes later. It is used in fields such as robotics, games, control systems, and other mathematical models of the environment.
From a Model to a Prediction
After that an algorithm has gone over the training data, it puts out a trained machine learning model. In this model are the learned math relationships which in turn are applied to new info. By task type, the model may produce a category, number, recommendation, or probability. Also, the model structure may go from quite simple math relationships to very complex systems which include large numbers of parameters.
When presented with new data, the trained model will put out a result that is a function of what it was trained to learn. We see this process also referred to as inference. For instance, a fraud detection model may be used which, from what it learned of past transactions, will identify a new one as suspicious or not. Also, a recommendation system will study a user’s actions and present to them content similar to that which it identified in other, related instances. In effect, the prediction is a sum of the model’s past learning.
How Machine Learning Models Improve
Testing the Model
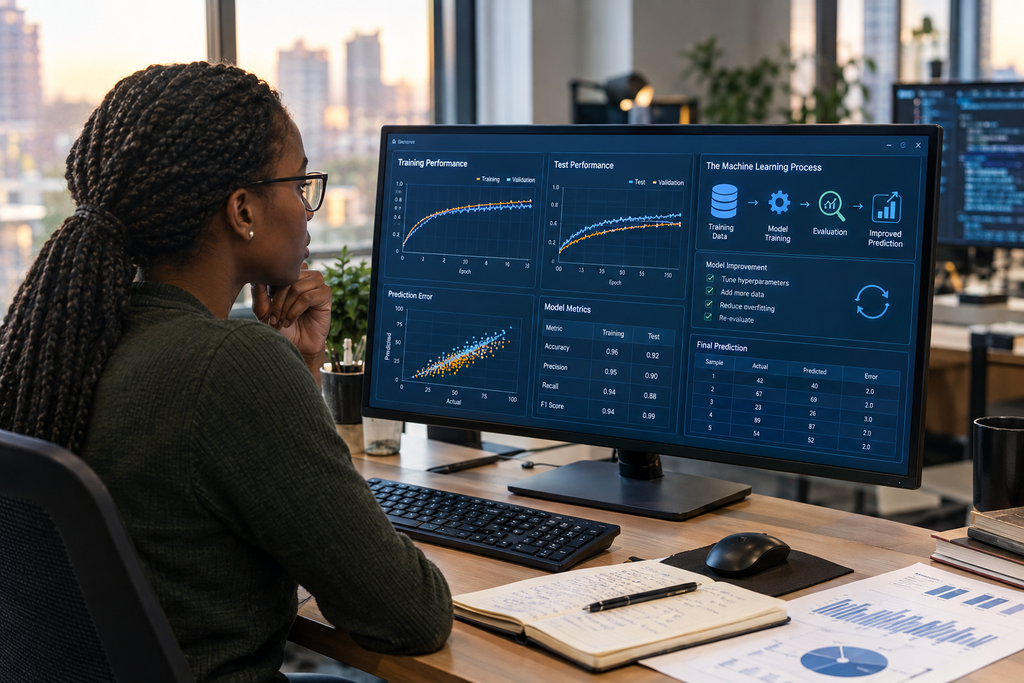
A model that does well on the training data may also not do well at all with new info it has not seen before. That is when a model has too greatly tailored itself to the training examples, which we call overfitting. To reduce this, we have to evaluate models with data which did not go through the training process. That in turn gives us a better idea of how the model will do in new and unseen situations.
Different tasks require evaluation methods. For a classification model, we look at true and false positives and negatives, but for a model that puts out numbers, we look at the prediction error. Through the process of testing, developers are able to see the model’s flaws and decide if it requires more fine-tuning before putting it into a live setting.
Improving Performance
Improvement of a machine learning system may include the addition of better-quality data, removal of that which is a poor fit, tuning of models’ parameters, a shift to different algorithms, and we put in better-quality info for the model to work with. We may go back and forth between training and testing the system to see what changes, if any, improved performance. We are not just out to complicate the model but to get it to recognize what is useful and which also applies to new sets of data.
Machines also, at times, models may be updated after going live as real-world settings do indeed change. Customer actions, the economy, traffic flows, and so on can play out in very different ways over time. That which was very accurate at the time of the model’s creation may over time lose its accuracy if what is putting out the patterns into the environment changes very much. But to have a healthy, functioning machine learning system which is reliable over time, monitoring performance and, at the drop of a hat, retraining models when needed can very well be a key component.
How AI Uses Machine Learning
Machines in many of the AI applications which people use daily, machine learning is employed. In search engines, machine learning is used to analyze queries and put forth relevant results. Recommendation systems study trends in user behavior to put forward products, videos, music, and other content. In the business world, machine learning is used for demand forecast, customer study, fraud detection, and operational planning. They process large amounts of info and identify patterns which would be hard to see by eye.
Different industries are using machine learning in different ways. In finance, we see its application in transaction analysis and fraud prevention. In health care, it is used in analysis of medical images and research data; also, we see it in transport for improving traffic flow, which includes route optimization and travel time estimates. Also, ed tech is using machine learning to analyze how students learn, which in turn gives us recommendations or identifies what may need more attention. Tech companies, in turn, are using it for language- and image-based tasks, security, voice systems, and other digital solutions that increasingly depend on effective data analysis.
Why Machine Learning Matters
Machine learning is important because we see in many real-world problems that they are too complex to be solved via the manual writing of rules for all the different situations out there. A computer program may have to look at thousands or millions of different info sets. As opposed to coding up a separate rule for each of those info sets, machine learning is what we use to analyze examples, and in that process, it also finds the math which in turn helps it do the job.
However, we can’t count on machine learning to always produce the right results. Models may still get things wrong, take in what we don’t want them to from the material they are trained on, or do poorly when the real world changes. That is at which data quality, testing out models, monitoring their performance, and human input is still very much in play. Also, consider that machine learning is a tool for computers to identify what is useful in sets of data and to use that information in new situations.
Conclusion
Machine learning allows computers to grow their knowledge from data, which in turn reduces dependence on manual programming. We present training data which serves as examples, algorithms which facilitate the learning process, and models which in turn identify patterns that we use for prediction and other outcomes. In supervised learning, we work with labeled examples; in unsupervised learning, we see patterns in data without predetermined answers; and reinforcement learning which is a result of action and feedback.
These present-day technologies have applications in business, finance, health care, transport, education, and tech. As for machine learning which is able to go through great volumes of data and identify complex trends, what it puts out is only as good as the data it is given, the learning method which is used, results of proper testing, and continuous improvement. By familiarizing yourself with these basic tenets, it is easier to see how modern AI systems use info and turn that info into useful predictions and decisions.