The advent of Artificial Intelligence (AI) has revolutionized the way people search, communicate, learn and perform their daily activities. Large language models (LLMs) is one of the technologies that is driving this development. These models are used to create AI chatbots and applications that can answer questions, summarize documents, translate between languages, generate content, and help with programming. The technology that underlies their answers is machine learning, neural networks, mathematical calculations, and patterns that they’ve discovered in large sets of information.
LLMs don’t interpret language as we do. Instead they work with text by breaking it down into smaller numeric components, understanding relationships between words and anticipating which words are likely to follow. The knowledge of their training process, and how they respond can help to explain what they can and cannot do and why they are important in modern technology.
What is a Large Language Model?
Large language models are AI systems that comprehend and produce human language. They leverage machine learning methods, notably deep learning, to uncover patterns and relationships within large sets of textual data. The models have millions or even billions of numbers, or numerical parameters, which affect how the model works and how it responds to the information passed to it.
Large language models enable AI systems to handle various language-related tasks without the need for multiple models. For instance, an AI chatbot can provide explanations for scientific concepts, rewrite paragraphs, summarize reports and create computer code. These skills are developed through word-sentence, and subject word relationships. But, LLMs do not have verified knowledge of everything they talk about. They produce their answers based on learned patterns and predictions, and sometimes give false answers.
How Large Language Models Learn from Data.
Training Data
Training data are the information the LLM is trained with to understand language. The datasets can be books, articles, web pages, educational resources, research papers and programming examples. The model relies on these resources to identify relationships, patterns, sentences, word meanings, and grammar.
The information may also be prepared before the training begins to remove duplicate content, filter out inappropriate information, and correct formatting issues. The quality of the data used for training is important as inaccurate or biased data can affect the model’s behavior. Hence, the quality of the data sets is important for the developers to think of, not just volume.So the accuracy, diversity and suitability of their data sets should be taken into account, rather than just their size.
The Model Training Process
When training a language model, it will learn from predicting missing or next parts of text. This technique is known as next-token prediction. For instance, if the model gets the start of a sentence, “The sun rises in the”, it will be able to predict that the next word is probably “east. It will make comparisons between the predicted text with the real text and fine-tune its internal parameters to reduce errors.
This is done for vast amounts of training data on high powered computing hardware. The mathematical calculations needed to update the model are done by specialized processors such as graphics processing units. Through the process of these changes over time, it also gains a greater understanding of the patterns of language and how to respond. The model does not just store the sentences it has been trained on, but it forms numerical relationships which allow it to create new combinations of language.
Role of Tokens in AI Models’ Text Processing.
What Are Tokens?
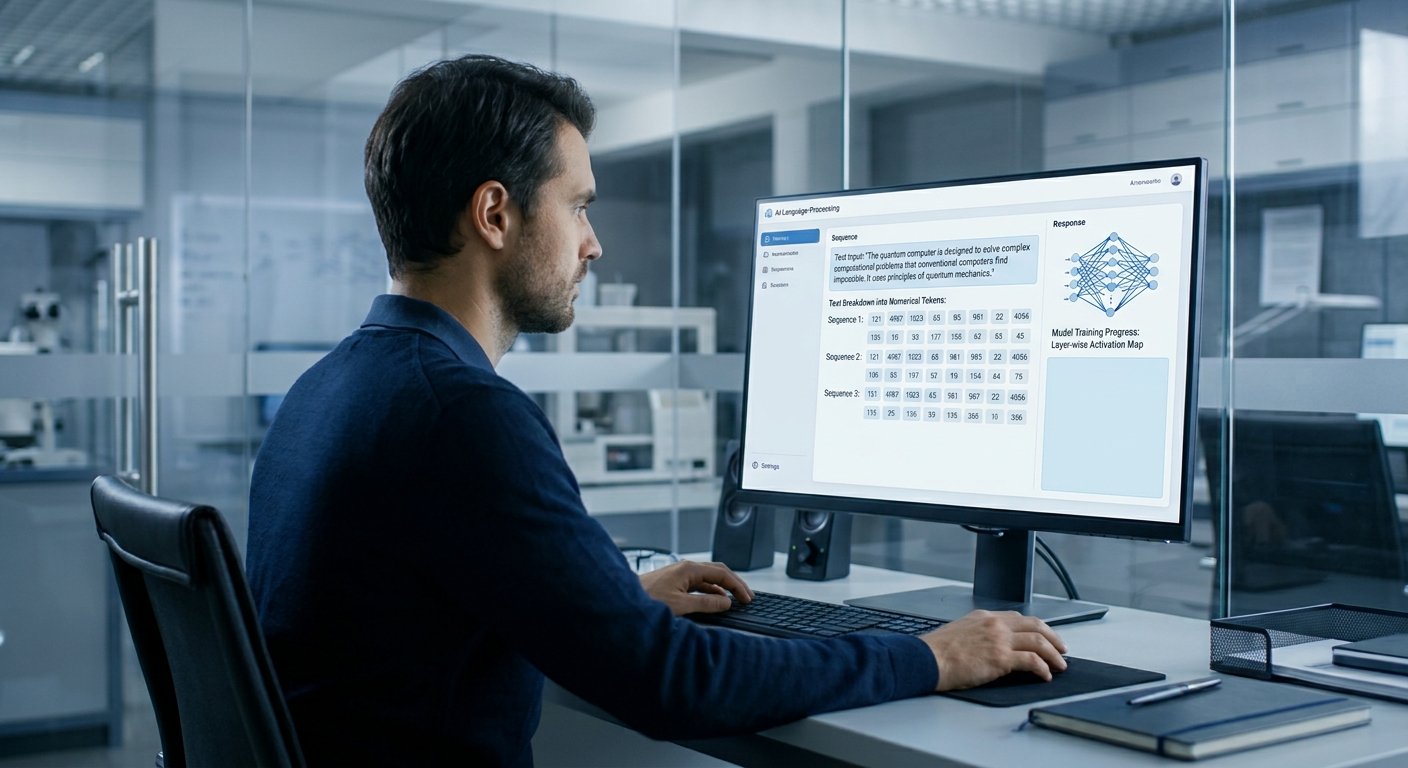
To make use of regular text by a large language model, the information needs to first be broken down into smaller items known as tokens. A token can be a whole word, a fragment of a word, a punctuation mark or some other text element. Words that are common can be broken into individual tokens, and longer and/or unfamiliar words can be divided into multiple smaller pieces.
The model is given a number identifying each token. These identifiers are turned into numerical representations known as embeddings, which enables the neural network to identify relations between various components of the text. Tokenization is thus a crucial process that links the human-readable language and the mathematical functions that AI models perform.
Why Tokenization Matters
Tokenization impacts the quantity of data that a model can take in and the speed at which it can produce answers. Typically, the input and output capacity of AI systems are measured in tokens, which are used instead of word counts. So even a long document could be beyond a model’s processing capacity if it doesn’t have a substantial word count.
Tokenization also can have an impact on the models’ behavior towards rare words, numbers, technical terms, and various languages. Words that are not known can be broken up into smaller parts, and the model must understand the words based on the context. This is why some AI systems may find spelling variations, less common expressions, or complex numerical data difficult to comprehend.
How Neural Networks Process Language
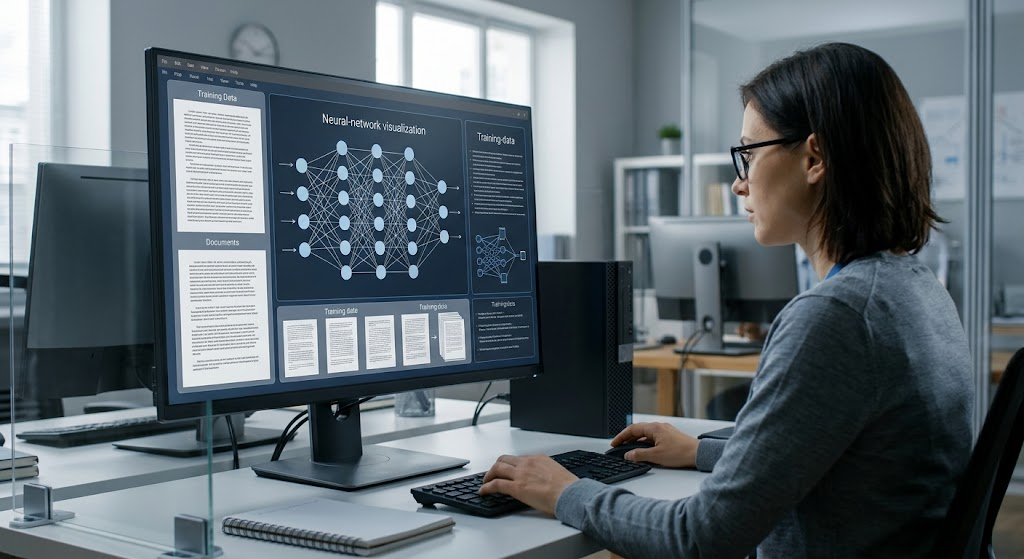
Large Language Models are based on artificial neural networks, computational systems modeled after the structure of the information-processing in biological nervous systems. Such networks have layers that execute mathematical operations on information in these layers. A popular structure is the Transformer, which can learn connections between the various components of a text sequence.
The attention mechanism is one of the key components in a Transformer. It assists the model to understand how the words or tokens are relevant to each other in a specific context. In the case of a sentence with a pronoun, the model can look at the words around the pronoun to determine what it might be referring to. This skill enables it to understand longer sentences and to respond suitably to them.
Understanding Model Parameters
Neural network parameters are numerical values within a network that affect the behavior of the network. Weights and biases are trained to fit the model and are included in the model. These values are modified as the system learns through examples, enabling it to identify patterns of grammar, word usage and relationships between ideas.
The size of a model is sometimes expressed by the number of parameters, however, the more parameters the more does not mean the better performing. The quality of the training data, the architecture of the model, the computing power and other training methods also have an impact on its performance. Parameters are thus seen as the numerical values which enable a neural network to learn from examples.
How Large Language Models produce AI Answers
One Token at a Time – Prediction
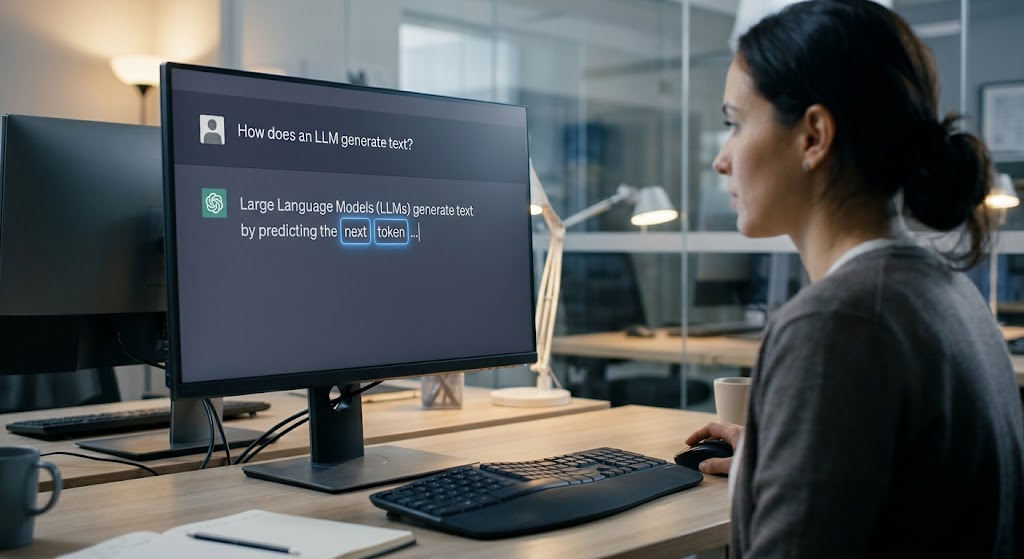
When a user asks a question, the model tokenizes the text and passes it to its neural network. It looks at the context it has to work with, and derives the likelihoods of various tokens following. A token is chosen and the developing response is expanded with that token, and the process is repeated until all the tokens have been used.
For instance, if a student asks “Why do plants need sunlight?” The model detects patterns that involve plants, sunlight and photosynthesis. It then produces an explanation by predicting the appropriate words and sentences sequentially, one token at a time. With this process, AI-powered chatbots can create full paragraphs and in-depth answers based on relatively brief instructions.
Probability and Response Variation
A language model might have several different alternatives for the continuation of a sentence with different probabilities. It chooses the next token as per its selection process. That is why when asking the same question to the same AI system, you may get different answers.
Temperature is one of the factors that affects this process. Generally, the lower the temperature, the more predictable the response, and the higher the temperature, the more variation there will be. There are other methods besides top-k and top-p sampling that also impact token selection. These techniques assist the developer in determining the consistency and variety in responses, depending on the application.
Understanding Context Windows
For a language model, the context window is the number of words that can be used in one processing. It is expressed in tokens and can contain the present question, past conversation messages, instructions and provided documents. Context is relevant since the model will require context to understand questions and give relevant answers.
Context windows, however, have their limits. If there is too much content in a discussion or document, you can eliminate it, summarize it, or analyze it in another document. This can impact the ability of the model to draw on information from previous conversation. A longer context window does not mean the model will know everything, rather it will have more information to take into account when responding.
Instruction Training
Training trains the model to identify language patterns, but more training may be needed to get it to be useful for conversations. Fine-tuning is one such method, where a pre-trained model is trained for more specific instances to boost its performance in specific tasks.
Instruction tuning is a technique to instruct the models to better adhere to users’ requests. Models learn how to respond to a question, restate information, explain ideas, and stick to formatting guidelines by examples of instructions and appropriate responses. The enhancements significantly boost the potential of AI chatbots in educational, communication, research, and business contexts.
Human Feedback and Alignment
AI developers also employ methods to enhance the quality and appropriateness of AI answers. For instance, reinforcement learning from human feedback (RLHF) involves human evaluators assessing the quality of the model’s responses and giving feedback to the model. This feedback can be used to update models for more useful and suitable responses.
Supervised fine-tuning, preference optimization, and safety training are some other strategies. These techniques facilitate the ability of models to respond to instructions, communicate more effectively and responsibly to some requests. But they can’t catch all the errors. A model could still provide the correct but misleading information, and that is where humans’ judgment and verification come in.
Applications of Large Language Models (LLMs)
Solving problems and summarising texts
One of the most prevalent uses of LLMs is question answering. You can ask questions on a variety of topics including science, technology, education, business and more. The model takes in the request, and returns an explanation from learned information and what it knows about the request.
These models have the potential to summarize longer texts, identify key points, and generate concise explanations. This is helpful for students reviewing information they have learned, employees trying to understand reports, and researchers examining large quantities of information. However, large language models can sometimes omit important details or misrepresent the meaning of the original material. Developing digital literacy and information verification skills can help users assess online information, identify reliable sources, and check AI-generated claims against original materials. Therefore, it is important to verify significant information by referring to trustworthy sources and the original documents.
Assistance in translation and programming.
By identifying patterns in the multilingual training data, large language models are able to translate text between different languages. They can also define and interpret words and phrases that are not familiar to them and modify written text for different audiences. But the translations that may involve idioms, cultural expressions and technical terms may need human intervention to make sure that they are accurate.
Another useful application is programming assistance. Large language models can provide code snippets, explanations of programming principles, potential bug fixes, and suggestions for code improvement. For beginners who want to understand how these tools relate to actual coding, learning programming concepts for beginners can provide additional background on the fundamentals of software development. However, there could be errors or vulnerabilities in AI-generated code. Before using the generated code in real-life applications, developers need to test and review it.
Why Large Language Models Sometimes Provide Wrong Answers
An important constraint of LLMs is their capacity to produce believable but wrong information. It is often referred to as an AI hallucination. This occurs when a model generates statements that seem reasonable, but include invented details, explanations that are inaccurate, or claims that are not supported.
These errors may arise because models do not test all statements themselves, but are merely a statistical prediction of responses. When the training information is outdated, the context is not complete, questions are not clear or the training data is flawed, this can also lead to an incorrect answer. Beyond that, if the words are confident, this does not imply that they are factual. Users are therefore advised to check for important information from reliable sources particularly in relation to technical, educational and professional decisions.
The Future of Large Language Models.
As researchers continue to refine their architectures, training methods, and the way they handle various types of information, large language models are evolving. Today, more and more AI systems integrate language processing with image recognition and audio processing, and external tools. Their wide range of applications are growing in the education, research, communication, business and software development sectors.
But there’s more to improve in the future than model size and response quality. These will remain critical points in terms of accuracy, privacy, security, bias, transparency and human oversight. With increasing adoption, it is important for individuals and organisations to know what these technologies can and cannot do to ensure that they are responsible for their use.
Conclusion
The key components of large language models include training data, tokenization, neural networks, parameters and statistical prediction.The major parts of large language models are training data, tokenization, neural networks, parameters, and statistical prediction. At training, they look at huge amounts of information, and change their internal parameters so as to match the pattern they see. They process tokens, take into account the context they have, and generate an answer by predicting one token at a time when answering the user.
The processes above give us an idea of how AI chatbots can resolve queries, summarize documents, translate languages, and help with programming. Their statistical predictions, however, can also yield information which is convincing but false. By grasping the workings of LLMs, users can better value their potential, but also remember to conduct fact checks and apply human judgment and responsible AI practices.