Introduction to Database Normalization
Database normalization is one of the most important principles used when designing relational databases. It is a systematic way of structuring information into tables in order to store information logically, avoiding unnecessary repetition and making relationships between the different pieces of information easier to handle. If the database is poorly designed, the same information can be stored in several different rows, leading to inconsistencies and updates that are hard to make. For instance, the customer’s address is saved in hundreds of orders, and if it needs to be updated, then there are hundreds of updates to be made. When a record is lost, information could be inconsistent in the database. Normalization solves these issues by decomposing large and complex tables into smaller, related tables and establishing meaningful relationships between them. It is based on a series of rules, the most widely introduced ones being First Normal Form (1NF), Second Normal Form (2NF) and Third Normal Form (3NF).
Database normalization is especially important to students, software developers, database administrators, and anyone who uses a relational database. Normalization isn’t just about breaking up tables into smaller ones, it’s about determining which data belongs to each piece of the table and making sure that each fact is recorded in the right place. A well-normalized database may make inserting, updating and removing information more reliable due to each vital fact having a clear and regular location. It can also simplify the understanding of the structure of a database by allowing it to model certain entities or relationships in the form of tables instead of having to try and fit every possible piece of information into one. While it may be more complex to obtain information from highly normalized databases, the benefits of consistency and maintainability may make it a must for good relational database design.
Importance of Database Normalization
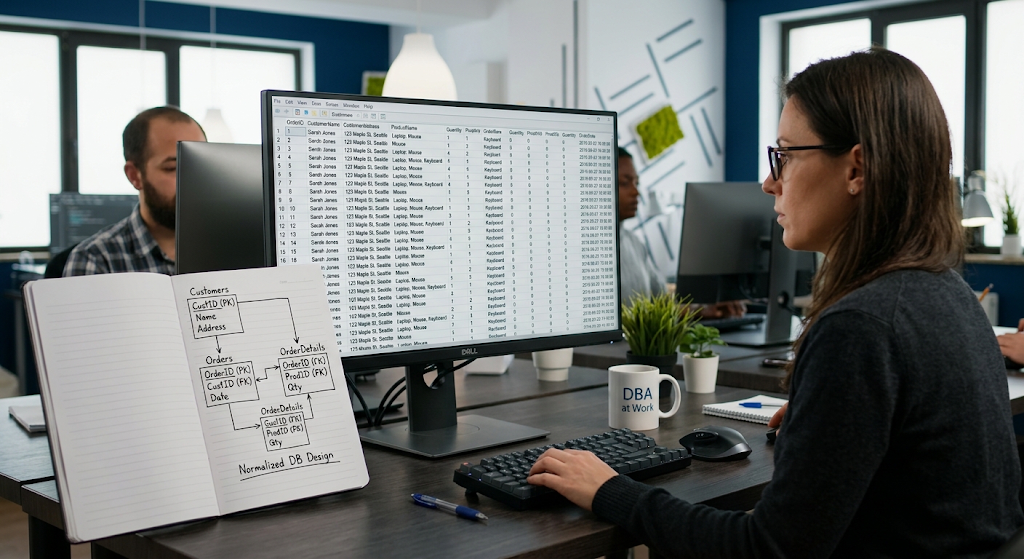
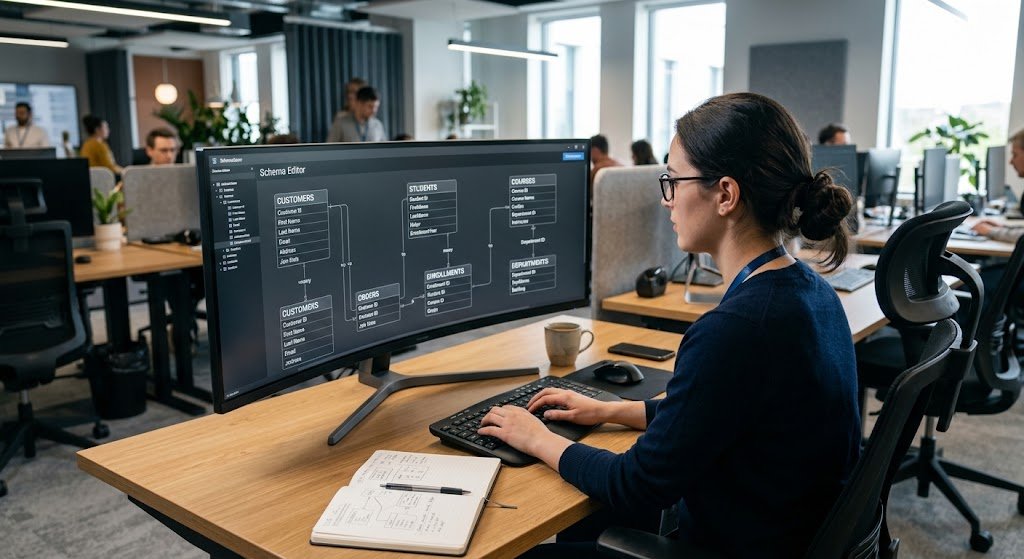
Normalization is useful primarily for minimizing data duplication and avoiding data anomalies. Redundancy when the same fact is stored in unneeded places. While it may seem like redundant data is no big deal, it can be quite the issue as the database expands. Imagine a university database contains a student’s name, email, department and course data all repeated in a single huge table. A student may be listed in up to five different rows if they are taking five courses. This means that if the student’s email address changes, it will take five changes rather than one. If one row happens to be left the same, then the database has two copies of the student’s information. This helps minimize it when the information is broken up into its own tables by student, course, department, and enrollment.
Normalization also avoids three common types of anomalies—insertion anomalies, update anomalies, and deletion anomalies. An insertion anomaly is when there is a structure to a table that makes it impossible to add useful information without having to have extra information as well. For instance, a database could not allow a new course to be entered into until there is at least one student enrolled in that course. Update anomaly is when the same fact is recorded in several rows but needs to be updated in all of them. Inconsistent data will be produced when one is changed and another is not. A deletion anomaly happens when a record is deleted without its other valuable information. For example, if you add one student to a course, but then delete that student, you might end up losing all the information that you saved about that course. Normalization is an effort to structure data to minimise these problems.
First Normal Form (1NF)
The first normal form, known as 1NF, is the first step towards the normalization of databases. A table is mostly in 1NF if each cell in the table contains only one value; that is, if the values in a cell are not a list or a collection of values. It is also important that the table has a clear structure, and that the records are clearly distinguishable. Suppose a poorly designed customer table was created with columns CustomerID, CustomerName, and PhoneNumbers. A row might contain a customer ID of 101, the customer’s name, and a PhoneNumbers value such as “08012345678, 08198765432.” In this design more than one telephone number will be stored in a cell. While human readable, it causes problems with searching, updating, sorting and validating individual phone numbers.
These repeating values should be broken up so that each field has one value, to make this table more like 1NF. There are several ways to do this, one of which is to have a Customers table with CustomerID and CustomerName, and a CustomerPhones table with CustomerID and PhoneNumber. The customer with ID 101 then might have two rows in CustomerPhones, one for each of the Customer’s phone numbers. If the database design allows the phone number to be part of the same relationship, then another option might be to make a new row for each phone number. The key point to remember is that the database shouldn’t rely on comma-separated lists or other collections within a single field. Imposing atomic values gives relational data a purer base for writing queries and extracting information; it also sets up the database to support the higher normal forms that it needs.
Example of a 1NF Transformation
Suppose that there is an online store with the following poorly structured table:
| OrderID | CustomerName | Products |
| 1001 | David | Keyboard, Mouse, Monitor |
| 1002 | Sarah | Laptop, Bag |
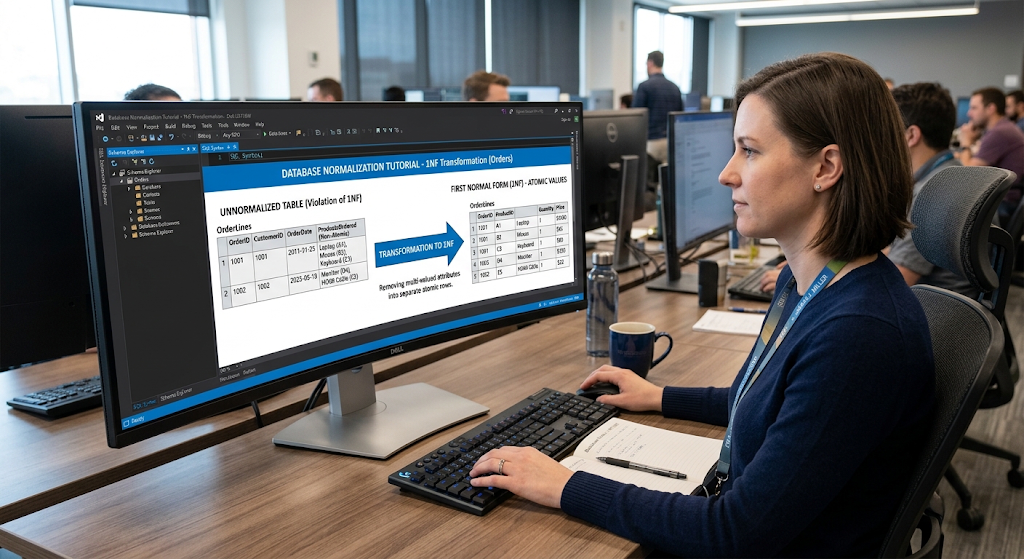
There are multiple values within each cell in the Products column. This makes it hard to identify each product, quantify products or relate each product to a specific product record. A better 1NF-oriented design would be to have each product represented individually. For instance, OrderID 1001 might be listed in three separate rows, with Keyboard, Mouse and Monitor. The final step in a better relational design is to split orders and products into their own tables and create an OrderItems table that would contain information on which products are linked to which orders. This way, product identifiers, quantities, prices and other properties can be stored without using text lists within a single field.
Second Normal Form (2NF)
Second Normal Form or 2NF, extends the requirement of 1NF. In other words, a table needs to be in 1NF before it can be in 2NF. Partial dependencies will be avoided in 2NF. A partial dependency is when a non-key attribute is dependent on only a portion of a composite primary key. This will typically be found in tables that are used to express relationships between multiple entities. Suppose you have an Enrollment table having StudentID and CourseID as its composite primary key. StudentID, CourseID, StudentName, CourseName, and Grade are possible in the table. Grade is dependent upon student and upon course, since a student’s grade is a representation of his or her performance in a specific course. But StudentName is only dependent on StudentID and CourseName is only dependent on CourseID. Thus those attributes are independent of the full key.
To meet second normal form (2NF), attributes that rely solely on a portion of a composite key should be transferred to additional tables. For the enrollment example, a Courses table can contain information about courses, and a Students table can contain information about students. The Enrollment table can then be broken down to the student/course relationship, which includes the StudentID, CourseID and Grade. By this design, a student’s name is only entered once into the Students table, not multiple times for each course that they enroll in. In the same way, a Course name is not repeated per student, but is stored only once in the Courses table. This yields a structure that eliminates the duplication and simplifies the changes. In the event of a name change the database administrator does not have to search through all the enrolment records, just the Students table.
Let’s Consider a Student Database, for Instance
Consider a student database, for example.
Suppose the school has this information about its enrollments at the beginning:
| StudentID | CourseID | StudentName | CourseName | Grade |
| S01 | C01 | Daniel | Database Systems | A |
| S01 | C02 | Daniel | Web Development | B |
| S02 | C01 | Maria | Database Systems | A |
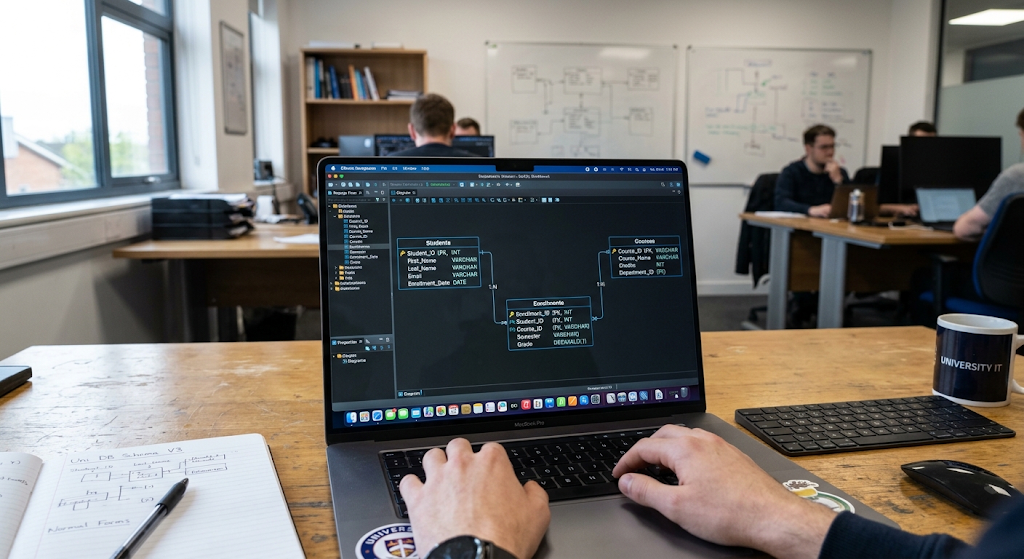
StudentID and CourseID together is the composite key. StudentName is only dependent on StudentID and CourseName is only dependent on CourseID. So, it is redundant to have both attributes in the enrollment table. A normalized design would make a Students table with the attributes StudentID and StudentName, a Courses table with the attributes CourseID and CourseName, and an Enrollments table with the attributes StudentID, CourseID and Grade. The Enrollments table then stores the relationship between the students and courses (without descriptive information that belongs to the individual entities). With this separation, the database is easier to maintain and can give a better visualization of the relationships between data.
Third Normal Form (3NF)
Third Normal Form, also known as 3NF, extends normalization to become even more strict, by resolving transitive dependencies. A table is generally in 3NF if it is already in 2NF and the non-key attributes in the table are not dependent on other non-key attributes. Simply stated, information should not be indirectly dependent on another field, but should be dependent on the key field of the table. Let’s say that you have an Employees table with the following columns: EmployeeID, EmployeeName, DepartmentID, and DepartmentName. EmployeeID is used to identify an employee and these are dependent on EmployeeID. But that’s not exactly a description of the employee as such, the one whose name is DepartmentName. This is a description of the department specified by the DepartmentID. So, the department name is indirectly dependent on employee id by department id. The following is an example of a transitive dependency.
In a 3NF design, the department information should be stored in a separate table, Departments. The Employees table would have EmployeeID, EmployeeName, and DepartmentID and the Departments table would have DepartmentID and DepartmentName. Now, the DepartmentName is stored in just where it should be: in the table describing DepartmentNames. This will not repeat the department name for each person working in that department. If the department’s name is changed, the database administrator only has to change one record in the Departments table and not hundreds or thousands of employee records. This is an important rule of Normalization: Every attribute should describe the entity that is represented by its table. When facts are not directly related to each other, they can be separated to avoid duplication and greatly simplify the logical structure of the database.
Example of 3NF Transformation
Suppose the following table is given:
| EmployeeID | EmployeeName | DepartmentID | DepartmentName |
| E01 | John | D10 | Finance |
| E02 | Alice | D10 | Finance |
| E03 | Michael | D20 | Marketing |
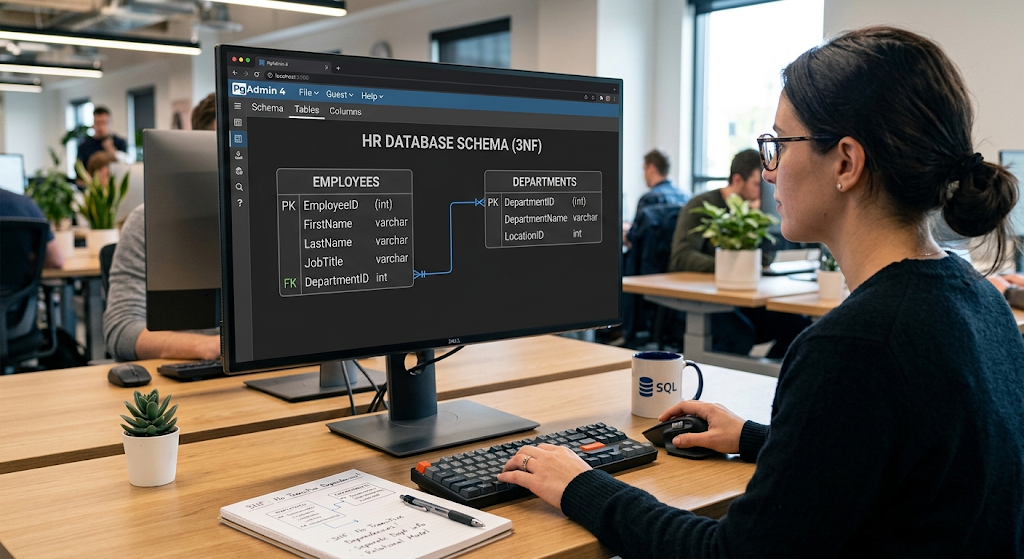
DepartmentName is not directly dependent on EmployeeID, but rather on DepartmentID. If the Finance department name is changed, all Finance employee records which are associated with D10 may need to be changed. This results in an update anomaly. The 3NF design would have an Employees table with the fields: EmployeeID, EmployeeName, DepartmentID and a Departments table with the fields: DepartmentID, DepartmentName. DepartmentID is the relationship between the two tables. This will ensure that information about the department is centralized. It also provides better predictability for future operation, as you can remove an employee without deleting all the information about the department, and create a new department before adding a new employee to it.
Beyond 3NF
1NF, 2NF, and 3NF are the three most widely known normal forms, but there are other normal forms possible. Boyce-Codd Normal Form (BCNF) is an even stronger form of 3NF, that eliminates some dependency situations that may occur after a table is put into 3NF. There are other forms of redundancy and complicated relationships such as Fourth Normal Form (4NF) and Fifth Normal Form (5NF). The advanced normal forms are especially important in complex database designs in which several independent relationships may result in redundant data. But not all databases must be normalized to the max. When designing a database, the needs of the application are typically taken into account, such as integrity, complexity of queries, performance, and future maintenance.
Also, it is crucial to recognize normalization is not a sacred obligation that every database must adhere to: the more small tables, the better.Also, it is crucial to recognise that normalization is not a sacred obligation that every database must adhere to: the more small tables, the better. In some cases, too much normalisation can result in a complex query that may need a lot of joins, with performance implications or making some reporting operations more complex. Some systems intentionally include a bit more redundancy in the form of a process known as denormalization, which is used for performance or reporting. Normally denormalization is not a necessary consequence of poor database design, but rather a deliberate design choice. The first step in designing a good database is to determine how the entities are related and what the normalized structure of the database is before determining whether there is some operational reason to duplicate information within the database. The aim is not just to make as many tables as possible, but to make the right number of tables that are consistent, clear, maintainable, and perform well on application.
Database Normalization in the Real World
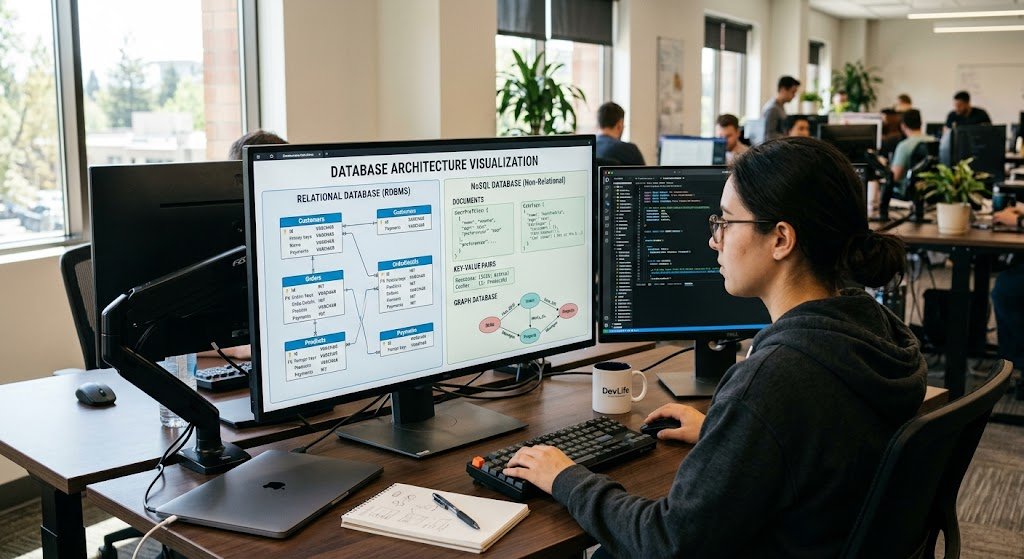
Because most software systems require accurate storage of related data over time, database normalization is used in a variety of software systems. Imagine a web-based retailer that stores its customers, products, orders, payments and shipping data. Some normalization would see Customers stored in a Customers table, Products in a Products table, Orders in an Orders table, and individual products per Order in an OrderItems table. Information about payments and shipping can also be divided based on their connections with orders and customers. This organisation prevents duplication of a customer’s personal information in each order, and does not repeatedly store product descriptions into each order item. The Products table may also store the correct product information without being dependent on the historical order records, depending on the business rules of the application, if the price or description of a product changes.
The same rules are applicable to banking systems, hospital information systems, university databases, inventory applications, social platforms and business management software. A University may have separate Students, Courses, Instructors, Departments and Enrollments. A hospital may have Patients and Doctors, but then it may also have Appointments, Treatments and Departments. An inventory system can have separate Products, Suppliers, Warehouses, and StockTransactions. In both scenarios, normalization clarifies the meaning and places of the relationships to be stored in the database, assisting the database designer. The exact structure will depend on the business requirements, but the goal is always the same: related information should be shown in a clean way, without having to repeat the information unnecessarily. The larger the amount of data stored, the more reliable the database will be.
Advantages and Limitations of Normalisation
Normalization has one great benefit: data consistency. In the case of a fact in the right place, its opportunities for conflicting copies are reduced. There is also an easier way to update the data with normalisation, since changes can be made in one place. The other benefit is better data integrity, for relationships between tables can be enforced through primary keys, foreign keys and other constraints within the database. Normalized structures can also allow databases to be more easily expanded. It’s possible to add new customers, products, departments, or other entities often without generating unnecessary “placeholders.” A good relational design can help the developer to understand the logic of the application from a development point of view because he/she knows which table is responsible for the information of each type.
The normalization process can also cause problems, however. The decomposition of a large table into a number of closely related tables may require applications to utilize joins when accessing information. Some queries that involve multiple tables can be more challenging to write and may need to be carefully indexed and optimized. In more complex systems, it is sometimes necessary to normalize parts of the database for performance reasons. What is crucial is that normalization and performance don’t have to be mutually exclusive. Indexing, query design, caching and other optimization strategies can be used in a normalized database. If denormalization is required it should be done intentionally, and with an understanding of the consistency problems that this entails. An important consideration in good database design is the use of normalization principles for the practical needs of the system.
Conclusion
Database normalization is one of the basic approaches for building reliable relational databases. It groups information into logical tables, minimizes needless duplication and supports the elimination of insertion, update and deletion anomalies. First Normal Form is about atomic values and the elimination of repeating groups, Second Normal Form is about partial dependency on composite key, Third Normal Form is about eliminating transitive dependency with the primary key of the right relation. These principles offer a systematic approach for converting poorly structured tables into clearer and more maintainable designs in the relational model. The knowledge of identifying entities, attributes, keys and dependencies helps database designers know where data goes and how tables can be related to each other.
Knowing what normalization is is a great start for students, developers, and those who want to become database administrators. The examples with customers, students, employees, departments, courses, and orders illustrate that normalization is not just a theoretical construct, but a real-world issue when vast amounts of structured information have to be stored and managed. Advanced normal forms and denormalisation would be appropriate in certain specific cases, but 1NF, 2NF and 3NF give a good starting point. A well planned normalization process may yield more consistent data, fewer maintenance issues and a manageable database structure that will be easier to understand as an application scales up. Eventually, the goal of effective normalization is to have each fact represented in exactly the right place, and the relationships in the system be represented clearly so that the relational database can be organized, reliable, and easily maintained in the long run.