Introduction
Natural Language Processing (NLP) is a field within artificial intelligence that computers use to understand, interpret, analyze, and generate human language. It is a key element in today’s tech which includes chatbots, virtual assistants, translation tools, search engines, and automated writing systems. Over the years NLP has grown out of simple rule based systems into very complex technologies which are able to produce human-like text and which in turn are able to respond to very complex instructions.
These changes have transformed how we interact with computers, how we find info, and how we go about our daily tasks. As AI advances we see NLP more and more tied in with generative AI, neural networks, and large language models. These are to improve communication, to automate routine work, and to make info more available across many industries. But also they bring up issues of accuracy, privacy, fairness and responsible use. Thus the future of NLP is in the balance between what it can do for us and the issues it presents which we as a society must address.
1. The Growth of Natural Language Processing.
The evolution of NLP has gone through many stages which each brought in new methods for computers to process human language. In the early days of NLP we saw mainly rule based systems which were the handiwork of linguists and programmers. These systems used dictionaries, grammatical rules, and very detailed instructions to analyze sentences and put together responses. While rule based approaches did a good job for very defined tasks they had issues with out of the ordinary expressions, spelling errors, and sentences which had multiple meanings. As researchers tried to develop more adaptable systems we saw the rise of statistical methods. Rather than rely totally on man made rules these statistical NLP systems learned from large sets of text. They were able to determine word associations, do document classification and recognize common language structures. This approach did very well in areas like speech recognition, spam identification, and machine translation which improved performance greatly although the systems still had issues with in depth understanding of word and sentence relationships.
The outsize step forward was seeing the implementation of machine learning and neural networks in language processing. Neural networks are able to identify complex relationships in large data sets which in turn allows NLP systems to identify patterns which traditional methods may overlook. We saw the adoption of Recurrent Neural Networks (RNNs) and Long Short Term Memory (LSTM) networks which improved on the processing of sequential info and thus made them very useful for language modeling, translation and speech recognition. That said these models did have issues with long term info retention and also had training efficiency issues. In 2017 we saw the introduction of the Transformer architecture which used an attention mechanism to determine word relationships within a sequence. What the Transformer did was to improve efficiency of language processing and also its ability to capture context. This was a very large breakthrough which in turn became the base for many of today’s NLP systems and also played a key role in the growth of very powerful generative AI.
2. Exploring Generative AI and Large Language Models.
Generative AI is a term used for artificial intelligence which creates new material out of patterns it has learned from training data. What we see in these systems is a wide range of output including text, images, audio, video, and computer code. In NLP we see generative AI which writes essays, sums up reports, answers questions, drafts email, explains complex ideas, and supports conversation. Also as opposed to that which traditional language based tools do which is mainly to classify or extract info, generative systems are able to put together new responses to instructions given to them. Their flexibility has made them an asset in education, business, research, software development and customer service. At the same time though it is important to note that just because a system is able to generate fluent language does not mean it理解了 it may not interpret every statement correctly or produce accurate info. Output has to be looked at in terms of the task at hand, the evidence available, and the results of any error.
In the present digital age large language models (LLM) are at the fore of what makes generative NLP work. We train these models on very large sets of text and related language data which in turn teaches them statistical relationships, structures and patterns. They in turn produce text by forecasting what the best next elements of that which we may term words, parts of words, or punctuation will be. In this way they put out coherent pieces of work, follow through on instructions, and they answer a great many types of questions. For a more in depth look into the tech behind it all readers are directed to studies of large language model architecture, training methods, what they do well and where they fall short. While it is true that some of these models are trained on a broad enough range of material that they do not need separate training for each task they take on, their performance is a product of the quality of that training, the model’s design, the given instructions, and access to relevant info. Also some systems are able to use external tools or pull from documents which in turn they use to answer questions which require very specific or up to date information.

3. Transformative Role of Transformer Architecture in the future of NLP.
Transformer architecture has come to be at the core of what we do in the field of language technology because of its ability to study the relationship between elements in a text. It has an attention mechanism which allows a model to determine which words or which tokens are key as it processes a given expression. For example in a sentence with a pronoun the model may use info from earlier words to determine which person or thing the pronoun refers to. That is a more flexible approach than that of independent word processing. Also they scale well on current hardware which in turn makes it practical to work with very large data sets. These benefits have seen improvements in translation, text generation, summarization, document analysis and in conversational AI. As research goes on into the future we may see language systems do a better job at following complex instructions, maintaining relevant context, working with longer documents and bringing together info from many sources.
In another key area we see the growth of multimodal AI which will work with many different types of data at the same time. Instead of just text these systems may include the use of images, audio, video and other media. For example a student may put forth a question regarding a graph and a business professional may use voice commands to analyze a report. Also a researcher may present written questions along with graphs, tables and audio of interviews to draw out what is relevant. These features may in turn make digital tools which are better and more accessible in situations which do not suit typing or which have info presented visually. Also we may also see improvement in models which use external software, which are able to pull up documents and which do structured tasks. At the same time though, multimodal systems bring in issues of their own in which they interpret errors in images, recordings, documents which in turn may affect the final product. As a result their development has to put forward not only what they do but also on issues of reliability.
4. Rising Applications of NLP.
4.1 Chatbots and Digital Assistants.
Conversational AI is a very present form of modern NLP. We see in chatbots and virtual assistants a way for people to have a natural language interaction with computers instead of using menus, buttons or specialized commands. Early chatbots had set out conversation which they would follow and they responded to a narrow set of what the user asked. Today’s systems do a better job at having more flexible conversations, at interpreting what is asked of them, at maintaining relevant context and in giving back personalized responses.
Also we are to see them used more for answering the most common questions, to give out product info, support online services and help users get their way around digital platforms. In the future these systems may do a better job at multi step tasks like finding info, comparing options, putting together documents, and setting up appointments. At the same time though, companies must see to it that there is a way for customers to get to a live person when an issue requires judgment, empathy or access to info that the AI does not have.
4.2 Cross cultural communication and translation.
Language differences are still a large issue in communication, education, international business, and access to info. We see via NLP we are able to reduce this issue through machine translation, multilingual search, speech recognition, and automatic transcription. Today’s AI models are better at translating which takes into account the context of the sentence which in turn makes the output more natural as compared to earlier which were a word for word approach. Also they are able to enable people to break language barriers by turning speech into text and then translating the response.
These features are very much in demand in countries like Nigeria which has a great deal of language diversity which includes the use of English, Nigerian Pidgin and many indigenous languages. At the same time the quality of language tech is very much a mixed bag between languages. Very well represented languages do much better because researchers have access to more training data, but smaller languages and regional variants get left behind. Thus going forward NLP research should put more focus on diverse data sets, community input, and better evaluation methods in order to make multilingual tools more inclusive and accurate.
4.3 Auto Summarization.
As we see an increase in the amount of digital info out there it is a challenge for people to go through every report, article, email, or research paper in full. We have NLP powered summarization tools which address this issue by identifying what is important and present it in a more compact form. These tools put out executive summaries, meeting notes, research overviews, and short takes on large documents. Some systems pull out key sentences from the source material and some which put together new sentences that communicate the main points.
As the tech improves we may see users have more input into the length, audience, writing style and level of detail they want. A student may ask for a very basic take away from a text book chapter and a manager may need a very brief take away from a large business report. While there are many pros to this service some cons include that important notes may be left out, tech specific terms may be misinterpreted or unsupported claims may be introduced. It is thus important for users to check back with the original source when accuracy is an issue in legal, medical, academic and financial settings.
4.4 Document analysis and information extraction.
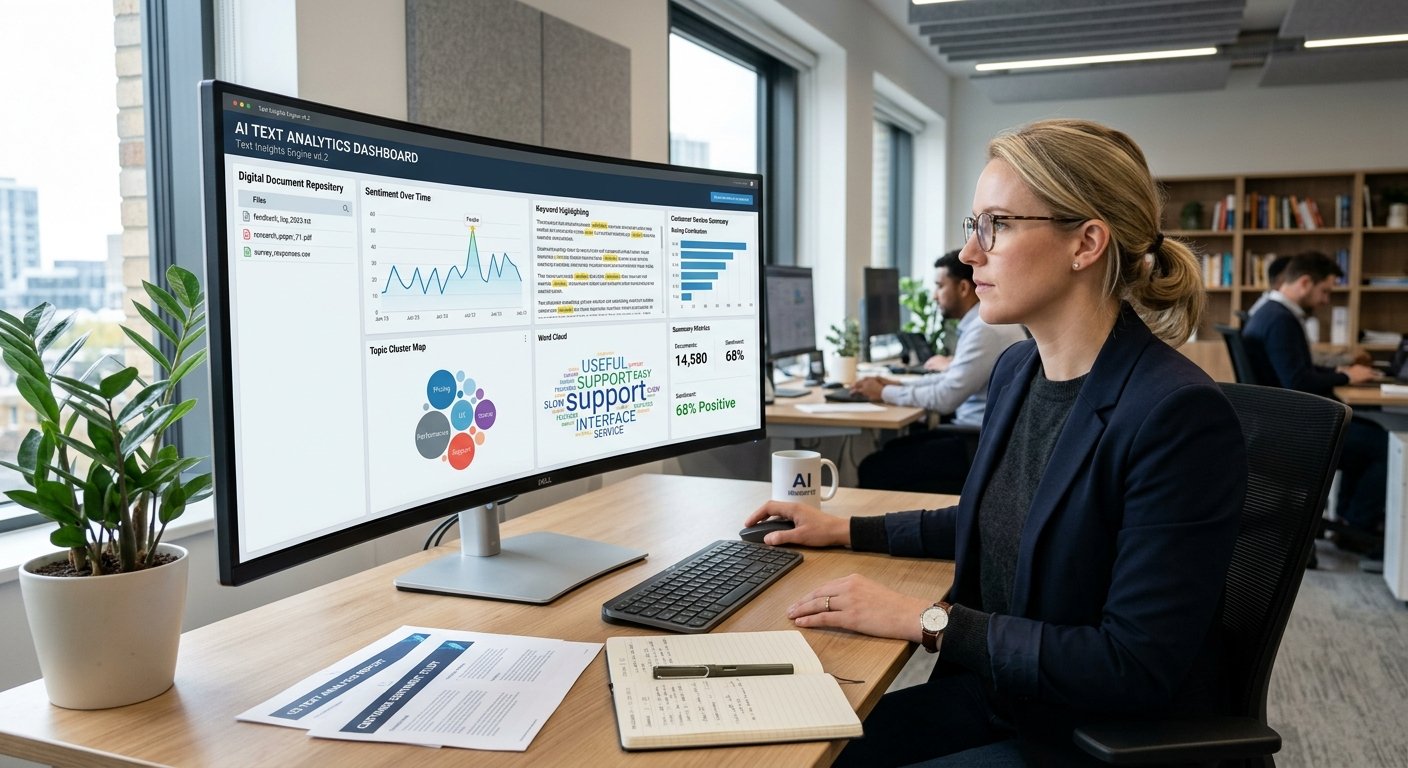
In the field of document analysis, which is a growing application of NLP, we see that companies produce large scale contracts, invoices, policies, applications, research papers, e-mails, and reports. We see that manual review of these docs takes up a great deal of time which grows when the info is in hundreds or thousands of files. NLP in this space helps out by identifying names, dates, figures, topics, issues, and the relationships between info. Also they do the task of classifying docs, comparing versions, finding out relevant passages, and in answering questions related to what has been uploaded.
For example a business may use an AI to find out specific terms in a contract, also a researcher may put together a set of papers related to a certain issue. In the future we may see systems that combine document retrieval with language generation to present answers that are supported by the relevant passages. At the same time it is important to note that auto analysis should not take the place of expert review in cases where large scale errors may have serious results. Also very clear citations, document level verification, and proper access controls are a must for reliable use.
4.5 Voice Enabled Interfaces and Voice Based Technology.
Speech tech includes many areas of AI such as automatic speech recognition, NLP, and text to speech. Speech recognition turns what is said into text, NLP determines the meaning of the words, and speech synthesis changes written responses into spoken word. Together these tech support voice assistants, automated phone systems, dictation software, access tech and hands free device control. We see in the future systems that do a better job at identifying different accents, telling who is speaking, handling background noise, and natural conversation.
This will benefit people who have trouble with a keyboard, workers that need hands free help, and individuals that prefer to speak. At present though speech recognition does very well with familiar accents, single languages in quiet settings and common vocab but does poorly with foreign accents, mixed languages, noise, and specialized terms. Also we must protect recorded and transcribed info as people may share private info in these systems. For effective growth we will need improvement in accuracy, in what we ask for permission for, in security, and in what we support in terms of a wide range of speech.
4.6 AI based Research Tools.
AI powered research tools are transforming how people do research, organize info, and analyze data. Researchers are using NLP systems to identify relevant studies, sum up papers, compare arguments, extract data, and organize large collections of docs. Students may use them to grasp new terms or to put together a base for in depth study, while professionals may use them to go over industry reports and to see what is trending. Some tools which include language models with search engines or doc databases are able to put together info before they generate a response.
This is making research more efficient and also helps users to get through large amounts of material. But an AI put forth answer is not to be taken as factual info. Models may make up info, misinterpret data, or present uncertain info as definite. Researchers should check out key claims in the primary sources, look at the quality of the info, and follow academic integrity rules. The best research process uses AI as a support to investigation which in turn supports your critical thinking rather than AI taking over.
5. What the Future of NLP Holds for Major Industries.

5.1 Education and Study.
In the field of education NLP has the ability to make learning a more interactive, accessible, and personalized experience. AI tutoring systems which serve up information on difficult topics, design practice questions, give feedback on writing, and also adapt what they present to the level of the student’s understanding. Also students may use conversation tools to research topics out — at the same time teachers may use these tools to put together lesson material, create assessment questions, and to put in order educational resources. We also see translation and speech technologies to be supported for students that have language barriers or other access issues.
Also we project that educational systems may in the future put together student questions, learning material and progress info to give more tailored support. But also schools must address issues of academic integrity, data security, unequal access to tech, and the issue of students’ over reliance on auto generated answers. Also students should be taught to eval AI, put forth info, to check facts and to develop their own lines of reasoning. When used responsibly NLP can support teachers and students’ needs without which I said the human elements that make education what it is go away.
5.2 Customer Service and Business Operations.
Customer service to put out will see large scale changes as AI in conversation forms improves. AI assistants will be able to answer common questions, go over product features, walk users through basic troubleshooting, and have customers find what they are looking for at any time. By taking care of routine issues these systems may reduce wait times and also allow human staff to focus on complex issues. Also we see in customer service that which language models put out can do analysis of customer feedback, bring to light what is an issue with many customers, do a better job at summing up what went on in a conversation and help companies to better understand what their customers want.
In some business functions language models can write reports, sort email, do meeting notes, and get info out of internal docs. This will improve productivity when the systems are put into present work flows. But also companies shouldn’t think that all issues are best left to automation. Sensitive issues, unusual situations, and those which require an account of what was done may still need human input. Also it is up to companies to use measures of performance like accuracy, customer satisfaction, security, and service quality instead of just the number of automated interactions.
5.3 Programming Development.
Software development is a field that is seeing inroads from generative AI and NLP. We see that developers are able to put forward a programming task in natural language and in return get code suggestions, info on foreign functions, help with debugging, or have a go at writing out documentation. Also we have that language models are able to write unit tests, do code review, translate between programming languages, and make sense of large code bases. This may in turn reduce time spent on repeat tasks and see to it that new developers pick up on programming concepts. In the future we may see systems that do better at working across full projects, which in turn will improve dependency tracking and support for complex dev workflows.
At the same time what we see is that putting out code from these models may have security issues, logic errors, out of date practices, or poor performance. Developers must still put what is put out through a testing phase, review what is being put into the code base, and have a working knowledge of what they are using. Also organizations should be aware of issues related to intellectual property, protected source code, and the security of the development tools. NLP is to make software development more accessible and efficient but at the same time professional judgment is key to put out reliable products.
5.4 Business Info Exchange and Knowledge Management.
Business communication is a field which deals with a large volume of messages, reports, presentations, proposals and internal documents. NLP systems are tools which help employees to put together professional emails, sum up discussions, translate communications, and organize info which in turn makes it easy to access. Also they play a role in knowledge management by enabling staff to search internal policies, product documentation, training material, and project records via natural language questions. Instead of going through multiple folders an employee may put in a request to a system to find a procedure and go over the relevant steps.
We may see in the future more personalized support based on a user’s role and what info that role is authorized to access. At the same time businesses must put in place clear rules around what is confidential data, have a look at what the AI is putting out and also see to it that systems do not expose info to unauthorized users. We will still see value in maintaining a professional tone, in passing along the intent of the communication and in determining what requires human input. We will see great results from the use of NLP if we integrate it into well thought out processes as opposed to using it without defined goals.
6. The Future of NLP.
6.1 Performance and Delusions.
Despite great progress in the field, NLP systems still put out inaccurate info which sounds very convincing. Large language models base their replies on what they have learned which in turn may include wrong facts, made up references, instructions that were out of context or a mix of unrelated info. Also this is what we call hallucination. It is a large issue when people use AI for research, education, legal info, financial analysis and other fields that require a high degree of factuality. In the future we may see these issues reduced via better training methods, using trusted sources for retrieval, external fact checking, and we will also see development of specialized evaluation tools.
Also it may improve at recognizing when it doesn’t have enough info to properly complete a task and to ask for more. Also it is true that no single solution will ever fully solve these issues. What we should do is to fact check the important results, ask for support behind big claims, and to have in place processes for correction of errors. Also in addition to a natural flow of communication a reliable NLP system should also be free of error and appropriate in its level of certainty.
6.2 Privacy and Information Security.
NLP systems handle personal info in emails, conversations, medical records, financial documents, customer service issues, and company reports. Should that info be collected or processed improperly it may present issues of privacy breach, identity theft, or unauthored [see original text for word author didn’t type fully out. Also Training data may include personal info which may not have been meant to be included at all or which needs special care. As language tech grows in its role in the workplace and in day to day services privacy protections will become more and more key.
Organizations should put out what info they need for a task, limit access to private records, secure stored data, and also pay attention to what AI providers are doing with what they put in. Also they should be open and clear with info on what they are collecting and for how long they will keep it. When appropriate use of methods like data minimization, restricted access, and privacy protective training can lower those risks. Robust privacy practices are the base for public trust and to make sure the benefits of NLP are not achieved at the cost of individual rights.
6.3 Issues of Bias and Fairness.
NLP models learn from information provided by people, institutions, and online communities, as a matter of fact they use for training material which in turn may present stereotypes, social inequalities, offensive language, and unequal representation of various groups. That which is learned out of such material without proper protection may cause a system to produce biased results, misclassify some languages, or give poorer service to underrepresented users. Also the issue of bias may present itself when the set of data used to test a system’s performance does not include the diversity of its intended audience.
This is a problem which goes beyond the removal of a few out of many offensive elements in a data set. What developers have to do is look at what is the source of the training material, test how different groups perform, include affected communities, and put in place processes for the report and correction of harmful behavior. In multi-lingual settings also we see that people put forth different forms of communication based on their region, culture and language. In the future of NLP we should see to it that we build out systems to do a good job for diverse populations instead of which we assume one cultural or language standard to fit all.
6.4 Computer Resources and Environmental Impact.
Training and to run large language models in depth requires great compute power, specialized hardware, electricity, and technical know-how. We see large scale training as expensive and also that which serves millions of users has ongoing infrastructure costs. These requirements may put very powerful AI at the expense of small organizations, researchers, schools and developers which have tight budgets. Also we see the issue of energy use in terms of carbon footprint of data centers as a concern. In the future progress will in part depend on the development of more efficient models, better hardware use, reduced unneeded computation, and the use of smaller systems when they do the job.
We are also seeing research into methods that trade off performance for cost and energy. Making NLP more efficient will expand access to useful language tools and also reduce waste. It is not just a matter of building ever larger models but to put in place which models which do the job well but also do it in a responsible use of resources.
6.5 Responsible AI Deployment with Human Oversight.
Responsible deployment of AI means we put into practice safety, transparency, and adherence to human rights and organizational responsibilities. Even the most technical AI model will have issues if it is put out there without first looking at how it’s going to affect the end user, what its limits are, and what kind of environment it will run in. For instance an AI which we use to do outreach and issue redress may play a role in what opportunities a person has if that AI is giving out biased info. Orgs should identify what the risks are before going live, test out the systems in real world settings, put out what those limitations are, and give in to users how they can get in touch with human beings to review.
Also they should put in place who is responsible for what AI influenced decisions. In high impact settings AI should not take the place of expert human input without first doing a very thorough evaluation and putting in the right safeguards. Also we must inform employees and users when to trust AI info and when to go get 2nd opinions. Also in the continuous evolution of data, user behavior and business requirements responsible deployment includes constant monitoring. Human oversight is not a break in progress, it is a requirement we have to have in order for NLP systems to be useful and trusted.

7. Trend in Language Models
The out looking trends in NLP are toward better reliability, efficiency, and adaptability as well as the machines’ ability to use external info. We see that retrieval augmented generation is a very promising field which includes the model in which the language model pulls out relevant info from documents and other knowledge bases before it produces an answer. That which does is increase response’s connection to present evidence does also bring up issues of retrieval error and incorrect interpretation. Also in the works are the systems that can make use of different tools, which in turn will have them to perform multi step tasks as well as interact with software all of this under proper control. These changes may put large scale language tech into play which goes beyond single stand alone answers and really aids the users through full scale processes. Also in the research is the design of the smaller more specialized models which do certain things very well and so in turn will lower the cost of AI and also make it easier to put in place in a controlled environment. Also we will see growth in multilingual learning, speech input, and multi modal reasoning that in total will increase access to this tech. But at the end of the day progress should be based on how the tech does in real world situations, what the end user gets out of it and the overall safety of the system instead of just in terms of cool demos.
Another key issue is the development of what we may term “context aware” language systems. What we put across to each other through language is a complex affair that goes beyond the actual words used. Into the picture come our past experiences which we share, the tone we use, cultural allusions, what is left unsaid which is in fact often the point, and our social conventions. Also in the works should be NLP systems that combine context based language processing with relevant background info and which also have in play very specific interaction designs. For instance a virtual assistant may identify that a vague command is in fact a request for more info before it goes ahead to give an answer. Also we may see the emergence of multi-lingual systems that take into account regional idiosyncrasies instead of which at present they put out as errors everything that is not a universal term. At the same time it is also true that what we put into language is very flexible and social settings are ever variable. Also at issue is that we cannot assume a model’s fluid response is the same as in depth understanding. Going forward research, wide scale testing, open about what we don’t know, and input from real world users will be key to the creation of better language systems which in turn will better meet human needs.
Conclusion
The outcast of what is to come in Natural Language Processing is that we will see the improvement of generative AI, transformer architectures, large language models and systems which integrate language with external info and other data types. In health care, business, education, software development, and beyond NLP is breaking ground for how we as a whole interact with tech and handle info. We will see better in context and improved language generation which in turn will make digital services more accessible, reduce routine work, and help individuals and organizations better use info.
But also we have issues at hand which include inaccuracy of responses, privacy issues, bias, high computing cost, and the issue of responsible deployment. These we must research more of, carefully evaluate, put in proper regulation, and have in place human oversight. Also at the end of the day the future of NLP shouldn’t be seen only through the computer’s ability to produce that which sounds human. What will determine its value is if these technologies really do what they are put to do, do they respect the user, do they support diversity, and do they solve real world problems. When done and put out into the world in a responsible way NLP has the chance to be a very large part of a more connected and info driven world.