Introduction
Machine learning is a crucial technology today used to help companies, health care providers, finance institutions and online platforms to better leverage data. Machine learning is a type of artificial intelligence that allows a computer system to recognize patterns, learn from examples, and make predictions or suggestions without having to have programmers define all the rules. It can be used to identify fraudulent financial activities, suggest a product to customers, and assist research in the medical field and in predicting business demand. These capabilities have the potential to enhance efficiency, accuracy and decision-making. Machine learning, however, also presents its challenges, and companies need to understand them before they adopt it. It is dependent on the data fed into the models, its algorithms and its environment. The pros and cons of machine learning can be studied to see where the technology is beneficial and where it needs some extra protection.
Machine Learning and How does it Work
Machine learning is a subset of AI that uses data to identify patterns and apply them to new scenarios. A machine learning model is based on examples and responds by recognizing patterns among variables and then generating a result like a classification, prediction, recommendation or estimation. For instance, a model that was trained on the historical data of houses sold might learn about how location, size, and other properties correlate to selling price. Likewise, an email filtering system can be trained to recognize probable spam emails from real emails by examining patterns of the spam-labeled emails.
The typical procedure for learning is to first gather data, then format it in a suitable way for analysis, identify a suitable algorithm, train a model with it, and finally test it on data other than the data used for training. Depending on the application, the developers can choose supervised learning, unsupervised learning, or reinforcement learning. While these approaches can be effective for addressing complex problems, they will require the right data, assessment techniques, and post-deployment monitoring.
Benefits of ML.
i. Finding patterns in large datasets that are complex
One of the biggest benefits of machine learning is that it can uncover patterns and relationships that might not be noticeable to humans. These days a wealth of information is created in enterprise organizations with every business interaction with customers, every online interaction, every business transaction, every scientific experiment and every digital service. It can be labor-intensive to analyze them individually, and it may be statistically impossible to uncover interesting patterns between several variables. Machine learning algorithms can analyze many different features, recognize patterns, and discover relationships that warrant further examination.
For instance, a retailer can look at the past sales data to find that certain items are often sold in combination, or a manufacturer can analyse readings from equipment sensors to determine conditions that are linked to equipment failure. The information gathered can aid in the planning, intervention, and decision making process. However, when a statistical pattern is found, this does not necessarily prove causality. Organizations should apply models with caution, determine if the relationships found in the model are meaningful and be aware that not all the correlations they find are necessarily true of real-world phenomena.
ii. Efficiently process large quantities of data
Machine learning can be used to process data that would normally be time consuming to analyze. Traditional analytical methods involve predefined rules, spreadsheet calculations, or manual review. These techniques can be effective for many operations but become challenging when the data becomes more complex, voluminous and frequent. After the development and deployment of a proper machine learning system, it can repeatedly treat the information received and generate results within the time spans of the operation. Transaction patterns can, for example, be analysed by the financial institution to determine if there is any activity that may warrant a fraud investigation. By examining delivery records, traffic data, and demand projections, logistics companies can make more informed decisions about their routes. Machine learning can also be leveraged by scientists to analyze massive sets of experimental data, picking out observations that can be promising for further study. This capacity for processing large amounts of information can help to eliminate analytical bottlenecks and assist organizations in making faster decisions about adapting to shifting circumstances. But the more information is processed, the better the conclusions will not be, either. Inaccurate data, inconsistent data logs, inaccurate models, and inadequate computing infrastructure can impact efficiency and result in unreliable findings.
iii. Use predictions to make informed decisions.
Another key benefit of machine learning is its capability of using the past information to predict future results or the possibility of specific events. Predictive models can be used to forecast customer needs, estimate equipment maintenance needs, identify a customer’s potential credit risk, and predict inventory needs. For instance, an online retailer might look at previous sales, trends and what is in the shopping cart to predict what new products may be in demand. Researchers from a hospital can study patterns in patient records that might be linked to health outcomes as long as the model is properly validated and applied in appropriate health protection measures. These forecasts can assist with planning by providing more information for decision makers to consider in conjunction with their professional experience and other information available to them. However, predicting accuracy is never a sure bet. Historical patterns may not be as helpful when unexpected economic changes, unusual events, inaccurate records, and changes in customer behaviour occur. Organizations should therefore consider predictions relative to actual results, explicitly acknowledge uncertainty, and avoid making key decisions solely based on the model outputs.
iv. Performing repetitive analysis and routine tasks with automation
Machine Learning can help cut down on manual work on repetitive information, data categorization, or routine analytical tasks which can save time for employees. It can be used for categorizing customer support inquiries, detecting duplicate entries, extracting valuable data from documents, spotting odd transactions, and arranging incoming emails. These activities can be automated to free up employee time to focus on tasks where judgment, communication, creativity, and specialized expertise are needed. Interested organizations can discover more about automating repetitive analysis and how AI-powered tools can be utilized to help with regular analytical processes.
However, automation must be implemented with knowledge of the task, the risk of mistakes, and the need for human oversight. A classification system that misroutes a customer complaint can result in inconvenience, whereas a classification system that is in an automated process in a high impact situation can have more serious consequences. The key to effective automation is to test the system, have escalation plans, consider the results, and give a means to correct errors. The goal should be to enhance productivity and consistency not eliminating human participation from all processes.
v. Enhance consistency and minimise some human errors
If well-designed and well-maintained, machine learning systems can follow the same analytical process on a multitude of cases without becoming fatigued or distracted, as a human reviewer may. This uniformity can be useful in repetitive work such as transaction screening, document classification, quality checking and information retrieval. For instance, computer vision could be used by manufacturers for the detection of visible defects in the product, based on specific criteria, assisting inspectors to find issues across high volumes of product. Machine learning can help a financial organization identify transactions that deviate from their patterns and direct the investigators’ attention to potentially suspicious transactions.
These types of systems can help eliminate some types of supervision and also put in place standardized functions. Consistency does not mean correctness or fairness, however. A learning model based on incomplete information may continue to yield the same incorrect answer again and again, and an algorithm that mirrors historical discrimination may continue to apply an unfair pattern. Sometimes human error can be minimised by automation, sometimes algorithmic error can be repeated at scale. Consistent testing, unbiased review and accountability are still required.
vi. Design Digital services and customer experiences that are personalized.
Machine learning contributes to personalization by analyzing user interactions, preferences, and past behaviour to make relevant recommendations. Websites that people visit and buy from and services such as video streaming might recommend products based on what they have browsed and purchased online or they might recommend videos or music based on what they have watched or listened to. Machine learning can also be utilized by search engines to enhance the relevance of the results, and digital learning platforms could suggest educational content based on a learner’s development. Personalization can also help services be easier to navigate, shorter to find helpful information and enable the organization to deliver content that aligns with individual needs.
These systems can also be leveraged for businesses to gain insights into customer preferences, which can then be used to enhance the delivery of these services. However, personalization can cause issues when platforms gather too much data, make wrong assumptions about users or when they keep showing the same content over and over again. The algorithms behind the recommendation systems can also restrict access to other ideas or products that you haven’t been familiar with before. Organizations should therefore take into account privacy, transparency, user control, and the implications of personalized recommendations as metrics of success, in addition to engagement and sales.
Disadvantages/Limitations of Machine Learning
i. Dependence on High-Quality Training Data
One major drawback of machine learning is the need for high-quality and appropriate data to create a machine learning model. Patterns learned by algorithms depend on examples presented to them, so if those examples are incomplete, incorrect, out-of-date, or unrepresentative, then the algorithm’s results are unreliable. Data preparation might involve removing duplicate data, fixing inconsistencies, filling in missing data, ensuring a consistent format, and evaluating if critical groups or scenarios are represented. A significant investment of time and resources can be spent on these activities prior to training the models.
For instance, a recruitment model based on previous hiring processes can be trained to learn patterns from previous hiring decisions, instead of understanding the factors that actually make for successful hires. Likewise, a prediction model for a population of a few patients may not be very effective on a population of other patients. To address these issues, more data does not necessarily solve the problem if the new data has similar issues. Organizations should evaluate where the data is from, its appropriateness, and the limitations which may affect the outputs from the models.
ii. High cost of operation
Building and running machine learning systems may be an expensive and demanding task that requires specialized software, computing power, data storage, and technical skills. While simple models can be efficiently handled on a normal computer, complex models that involve large-scale data sets or a large number of neural networks may need to use powerful processors, specialized hardware, or cloud computing services. There are also costs involved in preparing data, training models, assessing their performance, deploying applications, and system maintenance over time. These additional costs may include electricity, cloud service fees, software licensing fees, employee training, and more. These requirements can be challenging for smaller organizations, especially if they don’t have access to skilled machine learning engineers or a well-developed data infrastructure. In addition, the money saved from a model may not be as great as expected when the base business issue is not well defined and/or when the system must be changed often. Organizations should evaluate the potential ROI and the total cost of ownership and determine if a simpler statistical solution or traditional automation or an existing software solution can deliver the same result at a lower cost.
iii. Fair and unfair outcomes, decisions, and actions
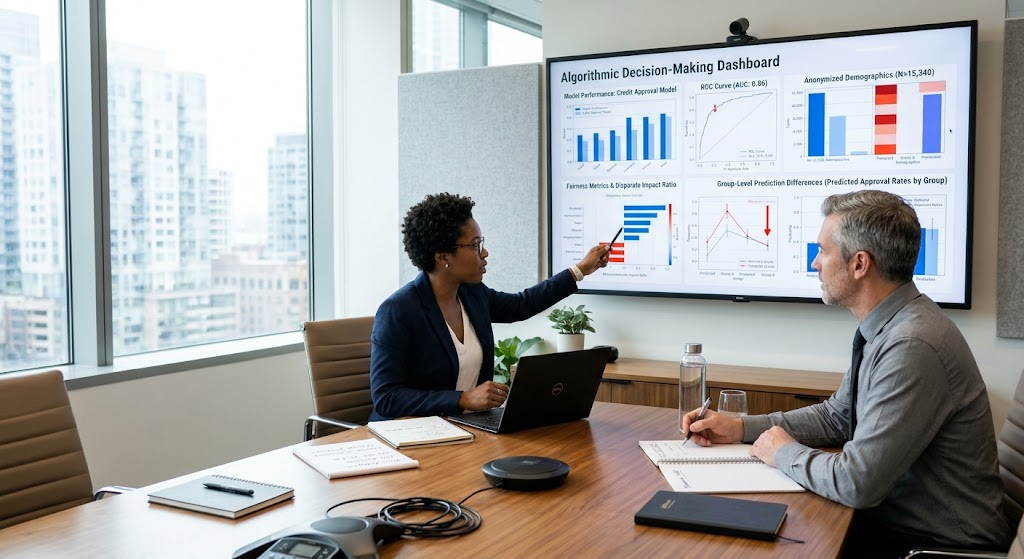
Bias can be reproduced or amplified in machine learning models if the data they use for training, their design, or their evaluation process is biased. Bias can occur if there is an imbalance between groups, historical decisions are based on discrimination, or if a variable of a model indirectly represents sensitive characteristics. This poses significant issues in fields such as employment, lending, health-related services, education and public services. For instance, a hiring decision model built on past hiring patterns might prefer candidates with backgrounds that mirror those of those who were previously hired, regardless of the fact that other candidates might have skills as relevant. A credit assessment system could also yield less accurate forecasts for groups that have weak representation in the system’s training set.
The exclusion of sensitive characteristics does not guarantee discrimination will not occur if other factors are used as indirect indicators of discrimination. To manage these risks, attention should be paid to the quality of the data, to the testing of the performance of the models on the different groups of which they form a part, to the documentation of the limitations, and to the participation of experts in key decisions. Organizations need to also have processes in place to contest wrong results and rectify inequities. Machine learning should be used to inform an equitable and responsible decision-making process, not to make discriminatory decisions easier to miss.
iv. Issues with Privacy and Data Protection
Information regarding people, businesses, transactions, communications or online behaviour is often vital to machine learning applications. This information can be used to raise privacy concerns, particularly if users are not aware of what they are being collected, why it is necessary, and how long it will be stored. For example, an online platform could use Internet browsing to tailor a recommendation based on the individual’s browsing history, and a health organization could use patient records to look for patterns of disease. While these applications can have a beneficial use, the information contained in them could be sensitive and could be released as a result of security incidents, inappropriate access, or sharing. Depending on the design and usage, some machine learning systems can also provide information about their training data under certain conditions.
Organizations should collect only information that is essential for the purpose for which it is collected; ensure that access to collected information is appropriate for this purpose; take actions to ensure that collected information is protected while it is stored and transmitted; and comply with relevant data protection requirements. There are specific techniques like data minimization, anonymisation, and privacy-preserving analysis that can help mitigate specific risks, but these techniques don’t completely address all privacy concerns. Responsible adoption relies on privacy being a fundamental design principle and not just something that is dealt with after deployment.
v. Limited Interpretability and Explainability
Machine learning models can be hard to understand because a prediction depends on a combination of many factors. A simpler model might give relatively clear explanations, whereas an advanced model might be able to make some useful predictions, but with a model that is not easy for people to understand. This becomes problematic when a company has to explain a decision, investigate an error or a consequence, to the concerned parties. If a lender has a complex process for evaluating credit applications, for instance, he or she might have to provide a reason for a credit application to be denied, and the factors that played a role in the decision.
A healthcare professional may also need to see evidence of reliability of a predictive system before using the output of a predictive system in a clinical context. Influential variables or summary of model behaviour can be identified using explanation tools, but such tools are not necessarily comprehensive or definitive in describing how a prediction was made. Organizations need to select models that are suitable for the effects of the task, record significant assumptions, and provide explanations as required. In heavy duty applications, insight into, challenge to, and review of a decision can be as critical as its predictive capabilities.
vi. Performance Degradation when Real-World Conditions Change
Technology also provides a model based on machine learning that could be accurate in the development environment, but not in the real world, because the world is not static and real-world data can differ from the data used to train the model. This may happen when there are changes in customer’s preference, economic conditions, the type of fraud, medical practices, or the features of incoming data deviate from the features used during training. Data drift or concept drift, depending on the kind of change, are common terms used in the context of such changes. A financial fraud detection model trained on transaction patterns from the past, for instance, might not be effective if fraudsters start using alternate patterns.
An online recommendation system can also be less significant as the people evolve in their interests or if the platform changes the content. To mitigate these risks, organizations should keep an eye on the quality of their input data, the performance of their models, and investigate unusual changes or update or retrain models when necessary. But, retraining needs to be done carefully as newer data can introduce new bias or can lead to deterioration in the performance of the already well handled cases. Machine learning should thus be considered as an ongoing operational duty, not a one-off development project.
vii Overfitting, Incorrect Predictions, and Uncertain Results
At times, the models trained with the machine learning algorithm can achieve highly accurate results on the training set but not on new cases. Overfitting happens when the model memorizes the patterns or noise in the training set rather than learning generalizable patterns that are applicable to new data. This risk is mitigated by the use of suitable validation techniques, testing models on independent data sets, choosing the model complexity appropriately etc. Another difficulty is that the quality of the predictions of machine learning is not always the same. With incomplete information in the input or significantly different circumstances to those the model was trained with, a model can generate convincing results.
In healthcare, this might be that a system fails to deliver its best performance on an unknown patient population. In business forecasting, when there are unforeseen disruptions, it may not be possible to rely on the previous trends. Organizations should convey uncertainty, test models in realistic scenarios, and put in place rules on how to deal with uncertainty in predictions. Human review and other decision procedures should continue to be available where errors might cause significant harm. The intention is not to have no errors at all, which may not be achievable, but to understand, measure, and manage uncertainty appropriately.
Practical Examples of the Pros and Cons of Machine Learning.
i. Machine Learning in Recruitment
One such use of machine learning is in recruitment, where it can provide benefits to operations but also raise fairness issues. Companies can use their computer systems to prioritize and organize applications, search for skills, sort resumes, or assist recruiters in handling a large number of candidates. These tools can cut down on admin tasks and streamline team data processing. A recruitment model, however, can be trained based on a past set of decisions in which recruiting may have been biased or based on subjectively preferred candidates. It might be more likely to show interest in some educational experiences, job backgrounds or language usage, even if these are not good predictors of future results.
Candidates who have not followed a traditional career path might be overlooked and recruiters might rely too heavily on automated rankings. Testing systems for discriminatory outcomes, analysis of relevance of selected criteria and meaningful human oversight are all necessary for responsible use. Employers should also ensure there is some room for correcting and creating opportunities to verify inaccurate information and make sure that automated suggestions do not become final decisions. While machine learning can help in recruitment, it cannot be used to make a complete judgment about a job candidate’s potential, professionalism, or ability to perform a job.
ii. Machine Learning in Finance
Fraud detection, transaction monitoring, credit risk assessment, customer service, and forecasting are all uses of machine learning in financial institutions. Models can analyze past transactions and other pertinent data to detect unusual patterns that require further investigation, and prioritize work for the analyst. These capabilities can help speed fraud screening and enable more uniform and effective risk assessment. However, financial applications can give false positives, label legitimate transactions or customers as suspect. Fraudulent activity that mimics normal activity may also result in false negatives.
A credit model could discriminate against people with short credit histories or those with credit records that are not included in training data. Also, it can be challenging to explain the reasons for some transactions or apps being flagged in complex systems. Financial institutions need to quantify the advantages and disadvantages of model mistakes, guard customer data, track model performance, and offer an adequate review system. Financial decisions can be made with a degree of automation, but to achieve the highest impact, accountability, procedures and adherence to relevant legislation and regulation are essential.
iii. Machine Learning in Healthcare
The possibilities of machine learning and the need for proper validation are demonstrated in healthcare applications. These systems can be utilized by researchers and medical institutions to examine medical images, study disease patterns, aid in clinical research and even make some health risk predictions. If properly designed, validated and implemented in clinical practice, these applications can support the identification of information that requires a closer look. But, medical data may be incomplete, inconsistent or not representative of populations on which a model is intended to be used.
Implementation of a system in one hospital may not be as effective in another with different equipment, patient populations or clinical methods. The limitation of this model, which may be misinterpreted by the user, or the recommendation lacking support can have a negative impact on decisions. Healthcare organizations have to carry out comprehensive validation, safeguard patient privacy, assess performance on relevant groups of patients, and provide proper clinical control. While machine learning can assist in healthcare research and decision making, it should not be considered a substitute for medical knowledge, clinical judgement or known best practices.
Use online platforms to implement machine learning.
Machine learning algorithms are employed by online platforms to suggest content, to rank search results, to identify spam, to moderate harmful content (where applicable), and to customize advertising. These systems can assist a user in the ability to navigate large collections of information, and can also enable the platforms to manage activity at a scale that would be challenging to manually review. Automated decisions, however, can be inaccurate about the content, miss the context, or continually promote content that is likely to drive engagement, but may not be of interest to users’ overall interests. Recommendation algorithms can also limit what information users see, and personalisation mechanisms can pose privacy problems if they are based on too much information collection.
There are situations where the meaning of an automated comment relies on cultural context, irony, linguistic variation, or the context in which a comment is given, such as when text is used sarcastically.Situations in which the meaning of an automated comment relies on cultural context, irony, language variation or context of use, such as when text is used sarcastically. Platforms shall assess the accuracy of the models, offer means to challenge consequential decisions, ensure privacy protections and use automated systems in tandem with human review, as appropriate. Measuring engagement, operational efficiency, and fairness, user well-being, transparency, and the broader impact of automated decisions are essential for effective platform governance.
How to mitigate the risks of machine learning in organizations
To maximize the value that organizations can get from machine learning, its adoption should be treated as a structured decision-making process and not as a problem that needs to be solved with AI technology. First, the business or operational problem needs to be clearly defined and measurable outcomes identified that would help to indicate success. Decision-makers need to then decide if relevant data is available, if there are potential privacy and fairness concerns, and if machine learning is simpler. The models should be analyzed with suitable data and performance criteria during development as it aligns to the impact of various errors. For instance, a fraud detection system might require a certain level of suspicious activity detection in order to prevent most fraudulent transactions, but pay a cost in terms of inconvenience when legitimate transactions are falsely flagged.
Organizations should set up accountability, document limitations, test security controls, and decide when human intervention is needed before sending it out. They are to track performance after deployment, investigate complaints, identify changes in data incoming and update systems when evidence indicates it is warranted. There is also a need to train staff to understand model outputs and also to identify cases where predictions might be unreliable. The measures do not eliminate all risks, but they can assist in making informed choices and minimizing unnecessary harm in an organization.
Is Machine Learning Worth Adopting?
Machine learning is most useful when a clearly defined problem involves patterns, predictions, classifications, or analytical tasks that can benefit from learning from data. Organizations with suitable datasets, measurable objectives, and the resources to maintain their systems may find that machine learning improves operational efficiency or provides insights that conventional approaches struggle to deliver. However, adoption may be unnecessary when a straightforward rule-based system, spreadsheet, or established statistical method can solve the problem more cheaply and transparently. The potential consequences of errors should also influence the decision. A recommendation error in a shopping application may cause minor inconvenience, whereas an inaccurate prediction used in healthcare, recruitment, lending, or access to essential services may have much more serious consequences.
Organizations should compare expected benefits with development costs, operational requirements, legal obligations, and potential risks. They should also consider whether affected people can question or correct automated decisions. Ultimately, the right question is not whether machine learning is technologically impressive, but whether it provides a demonstrable improvement over available alternatives while meeting appropriate standards of reliability, fairness, privacy, and accountability.
Conclusion: Balancing the Benefits and Risks of Machine Learning
Machine learning offers significant advantages, including the ability to identify complex patterns, process large datasets, support predictions, automate repetitive analysis, and personalize digital services. These capabilities can help organizations improve productivity, make better use of information, and investigate problems that would be difficult to address through manual analysis alone. At the same time, machine learning has important limitations involving data quality, computational costs, biased outcomes, privacy, interpretability, and changing real-world conditions. Its predictions can be inaccurate, and its outputs may reflect weaknesses in the information or assumptions used during development.
Examples from recruitment, finance, healthcare, and online platforms demonstrate why automated systems require careful evaluation and appropriate human oversight. Successful adoption therefore depends on choosing suitable applications, establishing realistic expectations, protecting sensitive information, testing for unfair outcomes, and monitoring performance throughout a model’s lifecycle. Machine learning should be viewed as a tool that can strengthen human capabilities rather than a technology that guarantees correct decisions. By balancing innovation with responsible governance, organizations can pursue its benefits while managing the risks and limitations that accompany its use.