Introduction to Discrete Probability
Probability is a basic branch of mathematics that enables individuals to comprehend uncertainty and foresee the possibility of various results. Probability is used in everyday life to help guess whether it will rain, to help people know how likely they are to win a game, to help people understand the risks to their finances, and to make decisions when they can’t predict what will happen. Probability is also important in computer science, since computer systems are often required to manage incomplete information, to analyze events that may be random, and to make decisions from information that may be uncertain. Discrete probability deals with situations where the outcomes are countable, like the possible values on a die, heads or tails on a coin, cards drawn from a deck, or a random number. This mathematical concept is the basis for developing algorithms, artificial intelligence, cybersecurity, data analysis and computer networking. Students will be able to use mathematical skills to learn to calculate probabilities, to understand possible outcomes, and to interpret uncertainty, all of which will equip them with mathematical skills essential to understanding how modern computational systems work.
Discrete mathematical systems are closely related to discrete probability; they use mathematical structures involving discrete and countable elements, rather than continuously changing quantities. They are represented as integers, graphs, logical statements, sequences, sets or finite sets of objects. To add another dimension to discrete mathematics, a measure of the likelihood of certain outcomes when there are multiple options is given in probability. A computer program that creates a random password, for instance, would need to take into account what combinations of characters that password could be made from and what chance do you have of being given that password? Likewise, an AI program could determine the likelihood of an email being spam, depending on its attributes. In both scenarios, the discrete probability provides a way to quantify uncertainty. The topic of the problem is mathematical formulas, but there are simple examples that convey the concept of the problem. By understanding these concepts, readers can identify problems involving probabilities, calculate the various possible outcomes, and understand the importance of probabilistic reasoning in the field of computer science and in making decisions based on data.
Essentials of Discrete Probability
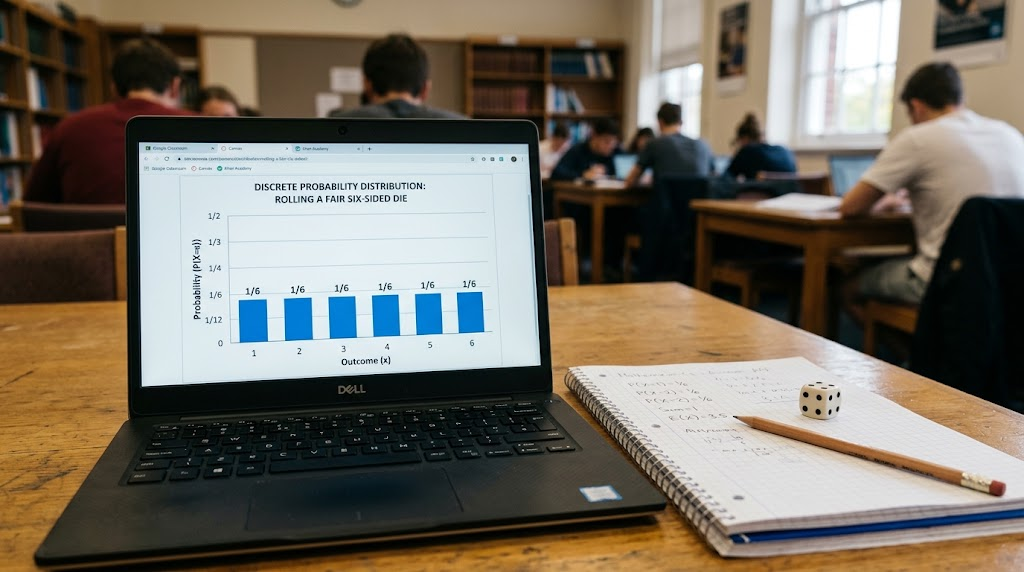
A discrete probability is a measure of the probability of the outcomes occurring in an experiment in which the outcomes are distinct and countable. Probability experiments are not necessarily laboratory experiments; they can consist of any process that yields an outcome such as flipping a coin, drawing a playing card, selecting a database record, or running a computer algorithm that generates a random number. There are various possible results for each experiment and probability gives a numerical value to reflect the chance of an event. Probability ranges from 0 to 1 with 0 indicating that an event will never occur and 1 indicating that it will always occur under the given conditions. A 0.5 probability means a 50% chance and a 0.25 probability means a 25% chance. Depending on the context, these can be quantities of fractions or percentages. The meaning of probability values is crucial because it enables people to understand and interpret uncertainty in the same manner, and compare the probability of different events.
The easiest probability computation is where all the outcomes are equally likely. When this happens, the probability of an event is determined by dividing the number of outcomes that can be done well by the number of possible outcomes. Suppose we have a fair 6-sided die numbered 1, 2, 3, 4, 5, 6. Let P(A) be the probability of the event A. The number of favorable outcomes for rolling a four is 1 and the number of possible outcomes is 6. Therefore, P(rolling a four) = 1/6, which is approximately 0.167 or 16.7%. There are three outcomes that meet the condition (2, 4 and 6), so the probability of rolling an even number is different. This gives the answer 1/2, or 50%. The examples highlight how probability calculations can be used to convert a set of possible outcomes into a measure of likelihood. But the formula for equally likely outcomes should be used with caution as it does not necessarily apply if outcomes are not equally likely.
Concept of Sample Spaces and Events
The set of all outcomes of a probability experiment is called a sample space. It’s typically denoted with the letter S and is where probabilities are identified and calculated. For instance, the sample space of tossing a fair coin once is S = {Heads, Tails} since these are the only two possible outcomes. When a standard six-sided die is rolled, the sample space is S = {1, 2, 3, 4, 5, 6}. In some probability models, the sample space may be a finite set of outcomes, or a countable set of outcomes in a discrete model. For example, the positive integers could be used to represent the number of attempts needed for a computer program in order to successfully connect to a server. The sample space is important because it allows for understanding of what outcomes are possible, which prevents important outcomes from being ignored and assists in determining the appropriate denominator when computing probabilities. Sample spaces are useful in computer science for analysing random algorithms, testing software behaviour, considering potential events in a network and considering the different states a program can enter when it is executed.
An event can be a specific outcome or a set of outcomes within a sample space. Events will be typically denoted by capital letters like A and B, and the probabilities of events will depend on the outcomes of the events. If a fair die is thrown, let event A be the event of getting a number on the die larger than 4, what is the probability of event A occurring?If a fair die is thrown, let event A be that the number on the die is greater than 4, what is the probability of event A? The event is A = {5, 6}, so its probability is P(A) = 2/6 = 1/3. An event may also have one outcome, for example: 3 or it may have multiple outcomes, for example: an odd number. Operations similar to those used in set theory can be used to combine events. The union of two events, A and B, is the set of outcomes that are in event A or in event B; the intersection of two events is the set of outcomes that are in event A and in event B. For instance, if the first die is rolled, the event of rolling an even number is {2, 4, 6} and the event of doing better than rolling the number three is {4, 5, 6}. Their intersection is {4, 6}, while their union is {2, 4, 5, 6}. The relationships can be used to describe more complex probabilities involving two or more events.
Basic Rules of Discrete Probability
There are some basic rules that govern probabilities of calculation and allow us to solve problems consistently. The first one is that the probability of any event is within the range of 0 to 1.The first is that the probability of any event is between zero and one, inclusive. Second, the probability of the entire sample space is always one since there must be some outcome in the sample space that occurs under the model being considered. Third: The sum of the probabilities of an event and its complement is one. The last principle is referred to as the complement rule and is expressed as P(not A) = 1 − P(A). The probability that an operation on a computer system is successful is 0.95. The probability that the operation fails is 1 − 0.95 = 0.05 = 5%. Complement calculations are particularly helpful when it is easier to find out the probability of something not occurring than the probability of finding out the ways in which it could occur. These rules are the basis of more advanced probability concepts and are useful to avoid mistakes when interpreting the probability of events.
Another major rule is called the addition rule which is important when considering the likelihood of either or both of two events taking place. For two events A and B, the general formula is P(A ∪ B) = P(A) + P(B) − P(A ∩ B). The intersection term has to be subtracted as it would otherwise be counted twice if included. If neither event can happen at the same time, the probability of both events occurring is zero and the formula becomes P(A ∪ B) = P(A) + P(B). Think of using a fair dice and asking for the probability of getting a one or a six. These outcomes are mutually exclusive so their probabilities add up to 1/3 = 1/6 + 1/6. The addition rule can also be used when computing probabilities in computational applications, such as the probability that a transaction will have one of a number of possible failure modes, or that a network request will fail for any of a variety of reasons. The first step in applying this rule is to correctly identify whether events overlap or not.
Discrete Probability Distributions
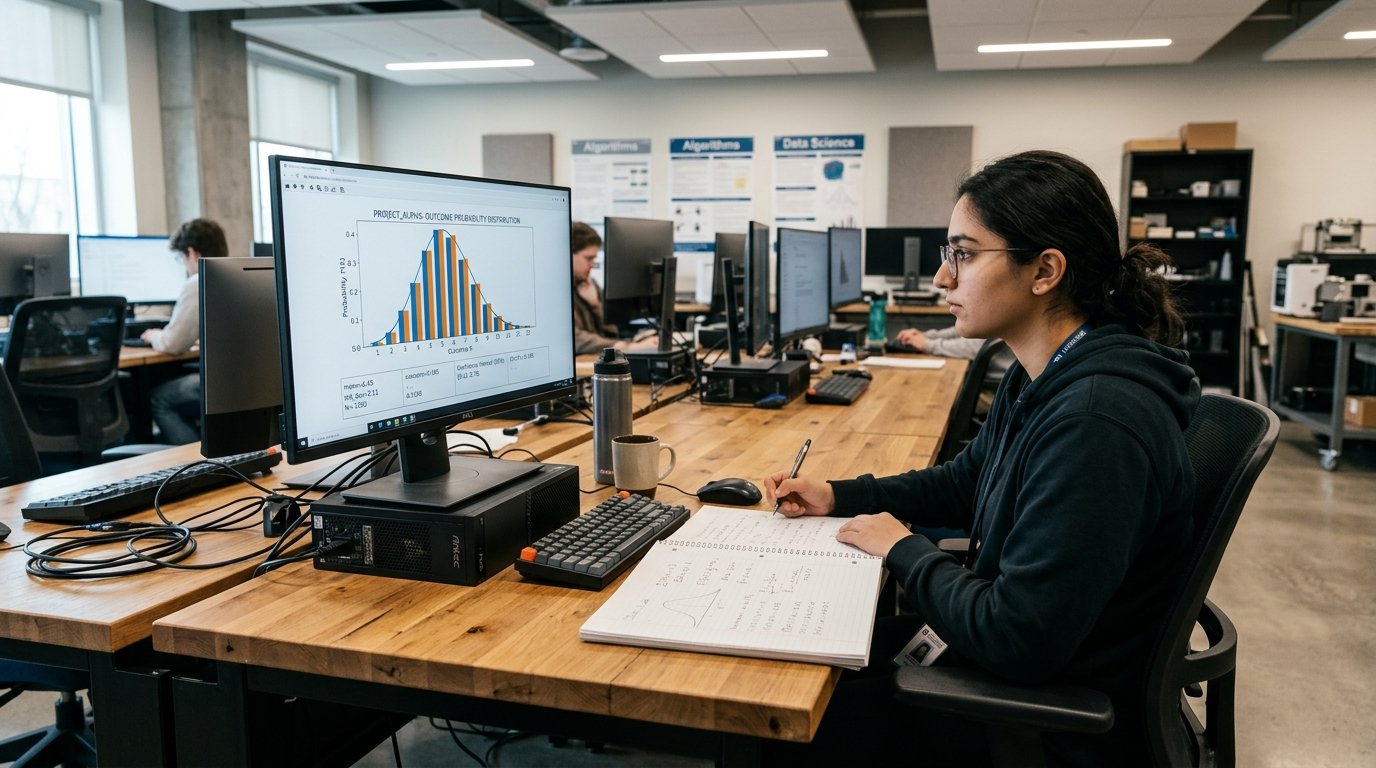
A discrete probability distribution is a function that gives the distribution of the values of a Discrete Random Variable and assigns a probability to each value. Random variable: A numerical value X (usually) representing the result from a random experiment. It can be used to indicate the number of heads, for instance, if a coin is flipped three times X can mean the number of heads. The set of possible values of X are {0, 1, 2, 3} with some probabilities associated with each value of X. Two properties of a valid discrete probability distribution are: each probability must be between zero and one and the sum of all the probabilities must be equal to one.
Discrete probability distributions give a framework for summarizing uncertainty without having to look at each possible outcome individually. They are employed in statistical analysis, simulations, machine learning, quality control and performance evaluation. Analysts can use their understanding of a distribution to determine what outcomes are likely to occur, what outcomes are unexpected, and the amount of uncertainty in a specific process.
Bernoulli and Binomial Distributions
One such distribution is the Bernoulli, which describes an experiment with two possible outcomes, typically success or failure. Success could be returning a completed network request, clicking an ad by a customer, or correctly classifying an example by a machine learning model. The binomial distribution is another important distribution that is the distribution of the number of successes in a fixed number of independent trials, with a constant chance of success at each trial, which is p.
The probability formula of its is P(X = k) = C(n, k)pᵏ(1 − p)ⁿ⁻ᵏ, where n is the number of times the experiment is repeated, k is the number of successes that are desired, p is the probability of success, and C(n, k) is the number of ways to choose k successes from n trials. Ten independent requests, with a success probability of 0.9, can be modeled by the binomial distribution for the system that tests them. The binomial distribution is especially useful in the analysis of repeated processes having distinct outcomes.
Poisson Distribution
Poisson distribution is another popular discrete probability distribution. It describes the number of events that occur in a given time period in an environment with independent events with a constant average rate under suitable assumptions. The interval can be a time interval, a length of network traffic or a specified region. It has a probability formula of P(X = k) = (e⁻λ λᵏ)/k! where λ is the average number of events in the interval, k is the number of events in question, e is the mathematical constant, and k! is k factorial. A typical service might get 3 requests per second and a Poisson model could make an estimate that the probability of seeing 5 requests in a second is 0.183 with the reasonable assumptions used in the model.
This distribution can be used for the analysis of arrivals of customers, traffic to servers, and some types of system failures. But, its usefulness relies on the degree to which the real process resembles the model assumptions. These assumptions should be tested and not assumed for all datasets based on a count.
Concepts of Conditional Probability and Independence
Conditional probability is the probability of an event, given that another event has already occurred. Conditional probability is computed over restricted sample spaces (those consistent with the given condition). It is denoted by P(A | B), probability of A when B happens. When P(B) is greater than zero, the formula is P(A | B) = P(A ∩ B) / P(B). For instance, suppose that there are 100 users of a computer and that 40 of those users use a certain application while 20 of those users use the application and are also set to use a security feature. Suppose that one of the users who uses the application was randomly chosen, the probability that the user has enabled the security feature is 20/40 = 0.5 = 50%. This is a different probability from the probability of selecting a user with the security feature out of all the users, which is 20/100 = 20%. The relevance of conditional probability is that more information may alter the probability of an event.
Artificial Intelligence, medical data analysis, fraud detection, cyber security, and decision making systems are some practical applications of conditional probability. A spam filter, for instance, might guess that an email is junk because it contains a specific word, URL or format. If someone logs into a website from an unfamiliar device, a security system might assume that it is a form of unauthorized access. These estimates are valuable for systems making decisions with available evidence, as opposed to assuming that all situations are equally likely. The use of conditional probability is, however, a careful one as one can only say that an observed relationship implies causality, but not necessarily. A system can observe that two events tend to happen together with no need to show that one event directly causes the other. Thus, the quality of the data, the nature of the assumptions on which the probability model is based, and the potential for the presence of other factors affecting the observed relationship need to be recognized in the process of reliable analysis. Knowing these limitations makes the probabilistic systems more useful and helps avoid misconclustering.
Independence
Another key probability concept is independence, which relates two events. Two events are independent if the probability of one event does not affect the probability of the other event. Given two events A and B, A and B are said to be independent if P(A ∩ B) = P(A)P(B). If P(B) > 0, then P(A | B) = P(A) is an equivalent statement. The two tosses with the fair coin are independent if they don’t affect each other. The odds of getting heads on the second toss are still 50/50 because the first toss doesn’t affect the second.
But, independence does not imply because things happen at other times or with other objects. Two of the network requests might be using the same failing server, and two security incidents might be the same with the same compromised account, so the results of the two requests are related. Dependence is relevant in the modeling of system reliability, estimation of system cumulative risks, and in repeated computational operations. Predictions based on a probability model may be significantly too high or too low if the model fails to account for dependency between the events.
Expected Values and Why They Are Important
Expected value is the average value of a random variable over long runs of repeated observations, assuming that the distribution of the underlying process is still applicable. If X has possible values x₁, x₂, etc., then the expected value of X is given by: E(X) = ΣxP(X = x) with the summation being over all the possible values of X. Simply put, each possible value multiplied by its probability and the products are then added up. Let’s think about a six-sided dice. Because every face has a probability of 1/6, the expected value is (1 + 2 + 3 + 4 + 5 + 6)/6 = 3.5. Note that this does not imply that the die will roll a 3.5; a die isn’t constructed with a 3.5 on it! Rather, 3.5 is the average outcome from numerous rolls. The expected values provide a summary of the “average” result of a random process and have many applications in statistics, economics, computer science, operations research, and decision analysis.
Expected value, in computer science, may be used to approximate the average cost, time, or number of resources required for an algorithm. Some algorithms’ running times depend on the input or random decisions made while running. Developers can use the expected number of operations to compare the approaches and select the one that is expected to run efficiently under certain assumptions. The expected value is also helpful in simulations, where you are modelling a complex system by running the simulation many times with random outcomes. For instance, an ecommerce company can predict how many people will fail to sign up for a newsletter during an hour, or a data analyst can predict the number of people that respond to a campaign. Decision makers may use probabilities to estimate the chances of various outcomes, and then determine the value of the expected outcome, to make a decision about possible benefits or costs. But EV doesn’t capture all aspects of risk. There can be two situations with the same expected value but very different variability and rare but serious outcomes can be masked by an average. When making decisions, therefore, it is important to take into account the distribution of possible outcomes, in addition to the expected value.
Counting Methods for Solving Probability Problems
Counting methods for solving probability problems.Counting methods for solving probability problems.
Counting techniques are ways to find the number of possible outcomes without listing them one by one. They are particularly useful in discrete probability when some problems involve combinations and arrangements, and some selections which are repeated. The multiplication principle is if one step can be done in m ways and another step in n ways for each of the m ways of completing the first step, then the two steps together can be done in m × n ways. In the case of a simple code of one letter and one number, the repetition being allowed, there are 10 numbers and 26 letters. The total number of codes is 26 × 10 = 260. Counting techniques can be used for analysing possible configurations in algorithms, estimating search spaces, designing experiments and calculating the number of possible passwords or identifiers. It is important for a counting method to be a valid method for counting the outcomes of an experiment and to determine that the outcomes are equally likely before calculating a probability using the ratio of favorable outcomes to total outcomes.
There are two major methods of counting – permutations and combinations. A permutation is used when order is important and a combination is used when order is not important. P(n, r) = n!/(n − r)!, or n factorial divided by the factorial of the difference between n and r, is the number of ways to arrange r distinct objects from among n distinct objects, where the factorial is indicated by a “!”. C(n, r) = n!/[r!(n − r)!] is the number of combinations of n objects taken r at a time. If the order in which the members are selected does not matter, for instance, choosing three people from a group of 10 players can be done in 120 different ways by using the formula C(10, 3) = 120. The order and role of the assignments are different if three individuals are assigned to three different jobs (chairperson, secretary, and treasurer): P(10, 3) = 720 arrangements. The following methods are useful in the analysis of potential selections, random sampling, lottery probabilities and combinatorial algorithms. They are also useful in providing an understanding of why some problems of probability may have many outcomes despite having a small number of options.
Discrete Probability as It Is Used in Computer Science
Probability in Algorithms
In algorithms, probability is used when decisions in the algorithm are based on random selections. Randomized algorithms can use random elements, pick pivots, or take a random sample to enhance performance or make computation easier. Examples include randomized quicksort, a sorting algorithm which can choose pivots in a random fashion. Its performance is tied to the way the input is partitioned around the pivot and randomizing can make it less likely to consistently get bad partitions for some kinds of input. One such technique is randomized search – a search that utilizes sampling or other random decisions to efficiently solve a large problem.
Probability serves as a tool for answering questions about the expected running time of algorithms, to estimate the probability that the results of an algorithm will be undesirable, and to compare different algorithmic strategies. But a good expected running time is no guarantee of a fast execution time. Even if they are rare, some randomized algorithms may have a poor outcome. Knowing the appropriate probability distributions and assumptions enables the developer to make a more realistic performance evaluation, and ascertain whether an algorithm is suitable for a specific application or not.
Probability in Cybersecurity
Cyber security is the process of safeguarding computer systems, networks and information against unauthorized access, alteration or destruction. In this area, probability plays a role in assessing risks, spotting unusual activity, and assessing the security of the system. A security monitoring system, for instance, could determine the probability that a string of logins is legitimate or that it is a possible attack. Counting and probability also come into play as far as password security is concerned, since the number of possible combinations can influence the difficulty of the password to be guessed given a given password guessing model.
When the password is chosen at random from a given set of possible passwords, the probability of guessing the correct password is 1/n, where n is the number of possible passwords. However, real password selections are not equally distributed as people tend to pick predictable words and patterns. Security analysts need to consider actual users’ behaviors, not the far-fetched possibility that they are using every possible password. Probability can also be used in conjunction with robust security designs, testing and suitable protective measures for use in anomaly detection, fraud prevention and reliability analysis.
Probability in Artificial Intelligence
Probability is often employed in AI systems to express uncertainty in the model, to learn from data, and to make predictions. Machine learning models can predict whether an image is likely to belong to a specific category, whether a message is spam or whether a customer will click on a recommendation. Probabilistic classification can be helpful when evidence is limited or when there are several different interpretations. For instance, an email classifier can try to analyse the words in the message, the sender details, and the structure of the message to gauge the likelihood of it being spam.
Probabilistic graphical models are used to model relations between multiple variables and Bayesian methods provide one approach to updating probabilities when new evidence is available. These are methods by which AI systems can apply evidence to make decisions instead of adhering to a set of rules. However, a degree of certainty or proof of the correctness of a prediction is not ensured by a predicted probability. The quality of the model is reliant on the training data, assumptions, calibration and evaluation. Knowledge of probability enables developers to make sense of predictions, to detect uncertainty and to decide when to refrain from the unsupported conclusion of an AI system.
Probability in Data Analysis
Data analysis uses probability to distinguish meaningful patterns from random variation and to draw conclusions from observed information. Analysts often work with samples because collecting data from every member of a population may be too expensive, time-consuming, or impractical. Probability provides the foundation for estimating population characteristics, measuring uncertainty, and conducting statistical tests. For example, a business might survey a sample of customers to estimate the proportion who are satisfied with a product. Because the sample may not perfectly represent the entire customer population, the estimate contains uncertainty.
Probability-based methods can quantify some of this uncertainty through confidence intervals and hypothesis testing. Discrete probability distributions are particularly useful when the data involve counts, categories, or binary outcomes, such as the number of product defects or the proportion of users who click an advertisement. Analysts must also consider sampling bias, missing information, and the suitability of their statistical assumptions. Applying probability correctly helps organizations interpret data more responsibly and make better-informed decisions without treating every observed difference as meaningful.
Probability in Computer Networking
Computer networks involve many events whose outcomes can be uncertain, including packet loss, delays, connection failures, and variations in traffic volume. Probability helps network engineers estimate the frequency of these events and evaluate the performance of communication systems. For example, a network administrator may estimate the likelihood that a packet fails to reach its destination under a particular model of packet loss. If packet losses are independent and each packet has the same probability of being lost, probability calculations can estimate the chance that several consecutive packets are lost.
Real networks, however, may experience bursts of loss because multiple packets are affected by the same congestion or hardware problem, so independence cannot always be assumed. Probability distributions can also be used to model the number of requests reaching a server within a specified period or to estimate the variation in response times. These analyses help engineers plan capacity, identify bottlenecks, and evaluate redundancy. Probabilistic modeling does not eliminate network uncertainty, but it provides a structured way to anticipate problems and compare possible improvements.
Probability in Simulations
Computer simulations allow researchers and developers to study systems by representing their behavior through mathematical models and computational experiments. Probability is especially important in Monte Carlo simulations, which use repeated random sampling to estimate numerical quantities or investigate complex processes. Instead of calculating every possible outcome directly, a simulation generates many representative trials and examines the resulting patterns. For example, a researcher could simulate customer arrivals at a service center to investigate waiting times or model network traffic to estimate the likelihood of congestion.
Simulations can also help test algorithm performance, compare resource-allocation strategies, and investigate uncertain scenarios that would be expensive or impractical to reproduce in the real world. The reliability of a simulation depends on the quality of its assumptions, the random-number generation method, and the number of trials performed. Increasing the number of trials often reduces sampling variability, but it does not automatically correct an inaccurate model. Probability provides the mathematical foundation for designing, interpreting, and validating simulations so that their results can support meaningful conclusions.
Common Mistakes When Working with Discrete Probability
One common mistake is assuming that all possible outcomes are equally likely. The basic probability formula based on counting favorable and total outcomes applies directly only when outcomes are equally likely. For example, a fair die gives each face the same probability, but a weighted die may favor certain numbers. Another frequent mistake is confusing independent events with mutually exclusive events. Independent events do not change one another’s probabilities, whereas mutually exclusive events cannot occur together in the same trial. These concepts describe different relationships and should not be treated as interchangeable. People also sometimes overlook overlapping outcomes when applying the addition rule, causing probabilities to be counted more than once. Other errors include confusing the probability of an event with the probability of its complement, using a distribution without checking its assumptions, and interpreting an expected value as a guaranteed result. Avoiding these mistakes requires clearly defining the experiment, identifying the sample space, stating assumptions, selecting the appropriate formula, and checking whether the final probability is mathematically reasonable.
Another important issue is the interpretation of probability in real-world applications. A probability of 90% does not mean that an event is guaranteed to occur, nor does a probability of 10% mean that it cannot happen. These values describe uncertainty under a particular model and depend on the information and assumptions used to calculate them. In data analysis and artificial intelligence, probability estimates may be unreliable if the training data are incomplete, biased, or no longer representative of current conditions. In cybersecurity, a low estimated probability of an attack does not necessarily justify ignoring the risk if the potential consequences are severe. Similarly, network engineers should not rely solely on average performance when rare delays or failures could have serious effects. Good probabilistic reasoning combines numerical calculations with an understanding of context, data quality, model limitations, and the consequences of possible outcomes. This approach helps people use probability as a practical decision-making tool rather than treating mathematical estimates as unquestionable facts.
Conclusion
Discrete probability provides a mathematical framework for understanding uncertainty when outcomes can be counted individually. Its fundamental concepts, including sample spaces, events, probability rules, discrete distributions, conditional probability, independence, expected values, and counting techniques, help explain how random processes behave and how their outcomes can be analyzed. Although these concepts may initially appear abstract, they have direct applications in computer science and everyday computational systems. Probability helps developers evaluate randomized algorithms, security professionals assess risks, artificial intelligence models estimate likely outcomes, data analysts interpret samples, and network engineers understand uncertain traffic patterns.
It also supports simulations that allow researchers to investigate complex systems under different conditions. Learning discrete probability does not require advanced mathematical expertise at the beginning; a clear understanding of basic definitions, formulas, and practical examples provides a strong foundation for further study. As digital systems become increasingly dependent on data and automated decision-making, the ability to reason about uncertainty remains an important skill for students, developers, researchers, and professionals working across technology-related fields.