Introduction
Large language models (LLMs) which are what we term AI systems that understand and produce human language. In many AI powered applications like chatbots, writing assistants, document summarizers and customer support systems you will find them. Also they are used for question answering, explanation, text translation and content creation. While their responses may have a human quality to them they are in fact the result of math and pattern recognition based on very large data sets, and do not have true human understanding.
LLMs have transformed how humans interface with computers, which now they do in their own language. These models are able to put together responses to a wide range of questions which in the past required developers to write out separate answers for each issue. From what they were trained on, what we know of neural networks, tokens, transformer architecture etc. this is the basis which explains their performance and what they are not able to do.
What is LLM? What does it stand for?
An AI system that has been trained to recognize patterns in language and put forth its own text based on what it has learned is what we term a large language model. These systems use great amounts of training data, large scale computation power, and large model parameters which is what gives them their size designation. Parameters are numerical values which the model fine tunes during the training process in order to do a better job at prediction.
LLMs are used for a wide range of tasks including writing in articles, giving answers to questions, to sum up documents, and in fact producing computer code. What they do is present what they have learned in terms of word and concept association which in turn produces the response. Also, the answers provided are not at all times accurate, it is the end user’s role to check out that which is put forth as fact.
How Large Language Models Work: A Step-by-Step Explanation
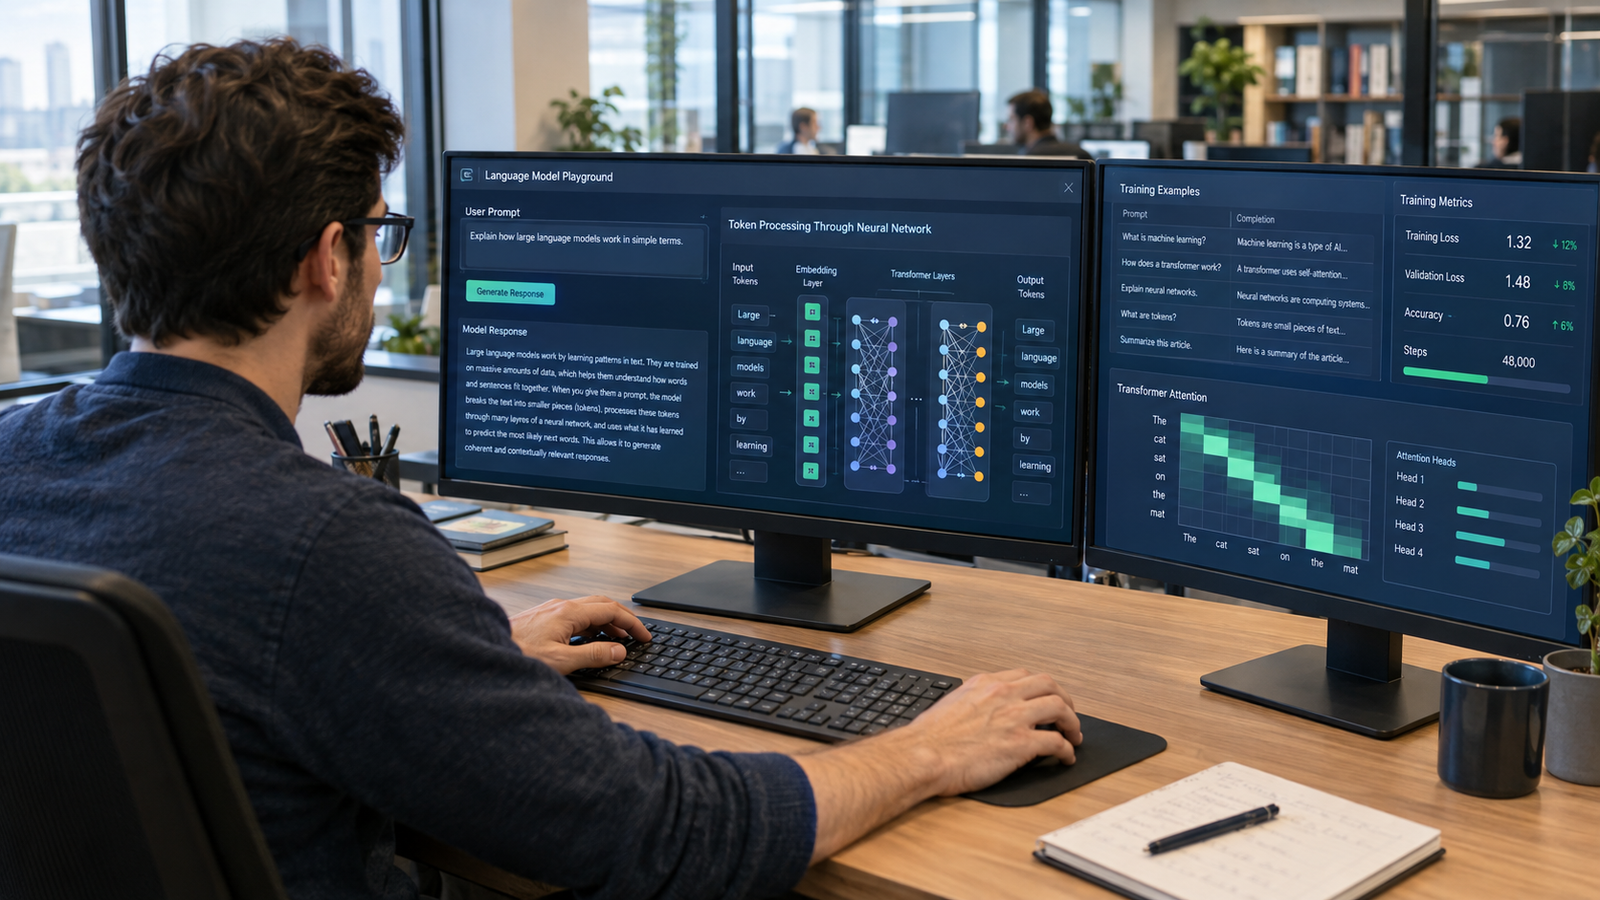
LLMs take in text which they break into tokens, then transform those tokens into numbers which are put through a neural network. The network which is trained to learn specific parameters uses those to determine the relationship between input and output tokens. From this the model puts out a response which is also a single token at a time based on these calculations.
In the course of training the model is exposed to many text examples which it uses to identify patterns. It uses that context to form answers. It is able to respond to a wide range of questions and does not have to fall back on memorized responses although it may not have answers to all possible questions.
What LLMs use for Training
Training data which help a language model to learn the rules of language are for example books, articles, websites, educational materials, documentation and other relevant text sources which it is exposed to. What we see is that diverse sets of material the model is given access to enables it to learn grammar, common turn of phrases, relationships between concepts, and how best to put things forward.
Training performance is an issue of training data quality. If info is bad, biased, or out of date it will in turn feed the model poor data. We see many methods for preparing and cleaning training sets which do a good job at removing issues but none which are able to catch them all. A model does not have to include all training material verbatim in a live database; a great deal of what it learns is in the adjustment of the models’ numbers.
What are Tokens?
Text is what we call the smallest entity in which language models operate that which we also term as tokens. A token may be a full word out of a larger word, a piece of a word, a punctuated mark or a stand in for a section of text. For example, a large word may break into multiple tokens rather than be entered in whole.
Tokens play a key role in that they determine text representation and the amount of info a model can process. What LLMs can put into account at any given time is limited which includes the input and conversation history. Also some services charge for use based on the number of tokens and in turn that also plays a role in processing time. It is also true that tokens are not the same as words which means the count of tokens in a document may vary greatly from the word count in that document.
What Is a Neural Network?
A neural network is which we have a series of interconnected mathematical processes that it uses to process info. In a language model the parameters are what determine how input info is transformed into output predictions of the network. We tune these parameters to improve the model’s performance at predicting text and the statistical relationships.
Large neural networks are composed of many layers which in different ways process the data. They are able to identify in grammar, context, sentence structure, and between concepts, patterns through training. Also it is at times very hard to fully interpret what goes on within them and that which they determine as patterns does not always correctly play out.
What does Transformer Architecture do?
The Transformer is a neural network architecture that has been implemented in many present day language models. It did see a rise in importance especially in its ability to identify relationships between the tokens in a sequence of text which is very important for these models. This is what enables the model to grasp the context in which sentences are used to in turn better interpret them and put forth relevant responses.
1. Understanding Attention
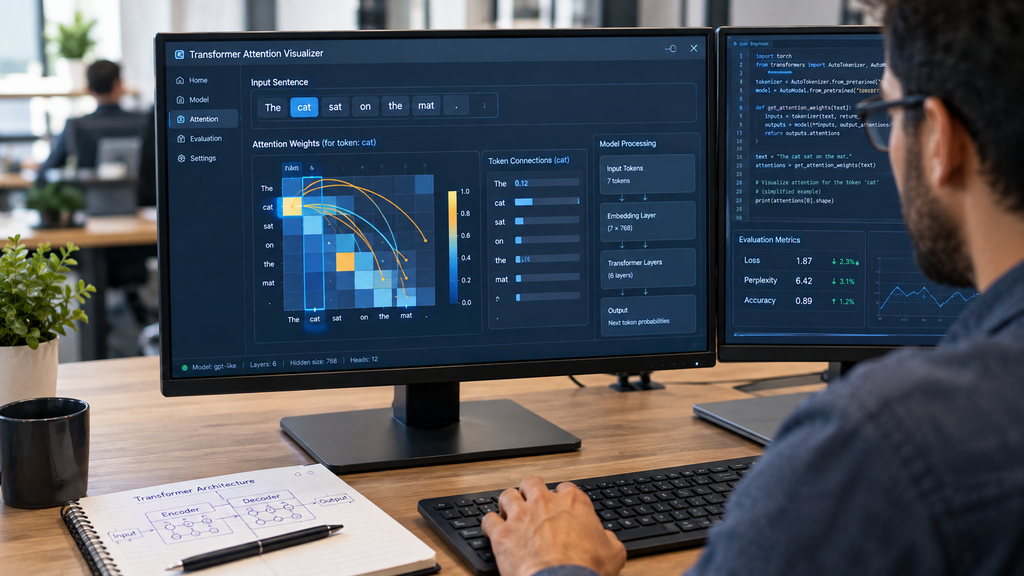
A model’s attention mechanism puts focus on which part of the input text is relevant when it looks at a certain token. For example a pronoun may require info from a past sentence in the sentence. Attention enables the model to make connections between these elements and it also provides context as it works with them.
2. Explain why Transducers are effective
Transformers present large language structures and many token relationships very well in their output. As for structure, which is how they are arranged to get out different info from a text. Also in all we see that a larger model does not in fact do better in terms of accuracy. Also what the model is trained on, the model’s design and evaluation methods.
What is Next Token Prediction?
To a very large degree, present day generative language models use what is known as a probability prediction of the next token. They look at the run up sequence of tokens which come before and from that base a high probability of what the following token will be. For example the model is given the prompt “The sun rises in the” it then puts “east” as the most likely option. It goes on to predict what the next element in the sequence will be till it forms a full sentence.
The model produces text based on the probabilities it has calculated and through this process it forms paragraphs, gives explanations, creates summaries and other types of text. See what is known as next-token prediction. Also note that this is in contrast to the task of determining factuality which is what causes large scale language models to present very convincing but false information at times.
Process Training vs. Inference
Process training: In the training phase which is the model’s learning from examples, the model puts out a prediction which we then check against the expected result and use that to fine tune the model’s parameters for better performance in the future. We do this with many data sets which also is very often done on specialized computing equipment. As you give the model more training its performance improves and it does a better job at following instructions and responding to the user.
A trained model will perform at the task which is what we call inference. If a person puts a request for a paper report to the AI the AI will use what it has learned to present back to the user. Also during the inferential process the model in general does not update what it has learned. In a presentation the info you present may change the other person’s view point but not always the AI’s database.
Large Language Models’ abilities.
LLMs used in a wide range of language based tasks. They will write out emails, do text summarization, break down complex issues, do translation, come up with ideas and help with computer programming. Also they may be used by businesses to answer repeatable customer questions and by students to grapple with new topics and to organize study materials.
Large language models support a wide range of tasks, including writing emails, summarizing documents, explaining complex topics, translating text, generating ideas, and assisting with programming. These capabilities make generative AI applications useful in education, business, research, and everyday work. For a broader explanation of how these systems create content, explore generative AI, including its role in text generation and other forms of AI-generated content.
They which you use for handling other requests which have the same base structure. As to what results they produce that is determined by the direction and context in which they are put forward. Although clear prompts do improve relevance, users should still go over the info they put out to see that it is accurate, that nothing is left out, and that which is presented is supported.
Which errors do LLMs make?
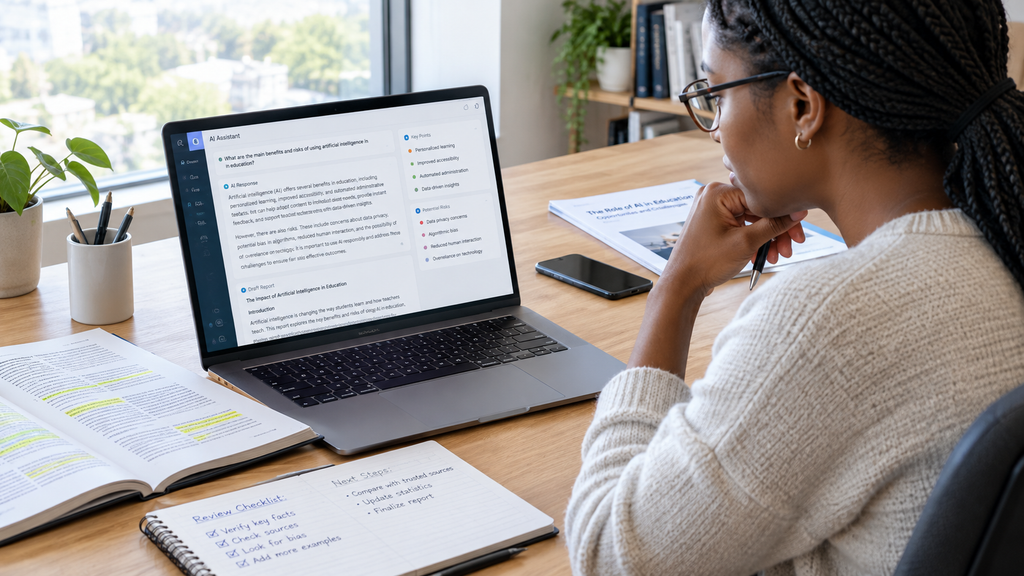
LLMs present false info which we call hallucinations. What happens is the model will take up a text pattern and reproduce its statistics but does not fact check what it puts out. We see this issue in lack of context, vague questions and low quality training material.
Bias exists in models that at time of publication may also be out of date and which may present inaccurate results. While some systems do improve on this with the use of search engines, databases, we also have not found that to be a complete solution. We suggest that people check the claims made in reports through use of trusted sources before they base large scale medical, legal, financial, or other very important decision making on what is reported in these models.
What to Expect from Large Language Models.
LLMs’ incorporation of external tools is a growing area which also we see in terms of architecture and training methods. Some systems into image as well as text recognition; also we see some which research out info and some which use special software which is a part of the answer. All of which are putting forth new options and approaches for the use of AI in education, industry, research and daily life.
As large language models become more widely integrated into applications, research tools, and business systems, concerns about accuracy, privacy, and security become increasingly important. Users should understand when independent verification is necessary, while developers should evaluate model performance and address potential weaknesses. Learning about data privacy and online security can also help readers understand why personal information must be handled responsibly when using AI-powered services.
All we have seen is improvement in these areas which at the same time has brought to light issues of accuracy, privacy and security which also play into issues of accountability. We as users must pay attention to when independent verification is required; also developers should look at model performance and root out their flaws. These tools do better and produce more accurate results when used in association with human input and reliable info in addition to AI.
Conclusion
LLMs are AI models that have had large volumes of text used to train them in which they identify patterns and in turn base their output on what they see from that data. They are created from training data, tokens, neural networks, transformer architecture and next token prediction. What the model’s parameters do is that they are determined through the training process and once the models are live they respond to prompts based on what they have learned.
LLMs produce a variety of text from writing to summarization but we see that they may not always be reliable. We know that users are aware of the models’ strengths and weaknesses and this is a step in the right direction. While Generative AI is a useful resource for user’s work, it is also a means to bring up the issue of misinformation, which we think is resolved through a critical eye and the use of known reliable sources.