Introduction
Data mining is a crucial tool for conducting scientific research, communication, healthcare, financial services, education, and business. There are numerous examples of patterns and trends being identified by organisations from vast amounts of information collected and analysed, to understand customer behaviour, detect fraudulent activity, make better decisions and predict future trends. These possibilities have been enhanced by artificial intelligence (AI) and machine learning, which allow systems to analyse intricate data sets and identify patterns that would be missed by traditional analytical approaches. But as more and more data about individuals and organizations is collected, there are important issues of privacy, security, fairness, transparency, and accountability. Data used to enhance an organization’s services may be the source of discrimination, surveillance, identity theft or unethical profiling for individuals if miscollected or misused. However, it takes more than just precise algorithms and supercomputers to be able to data mine. Businesses need to set ethical guidelines, adhere to relevant privacy regulations, safeguard sensitive data, and ensure analytical practices uphold privacy and privacy rights and provide value to the business.
Ethics of Data Mining.
These are principles that are used for collecting, analyzing, interpreting and using data in a responsible manner. Ethical data mining asks, “Does a company have a good reason to gather specific data? Is the subject aware of how the data will be used? Are the outcomes of the data mining likely to harm individuals unnecessarily?” Data privacy is about people’s rights and expectations regarding personal data – how it is collected, stored, accessed, shared and deleted. Data security, on the other hand, is the technology and management practices utilized to safeguard information from unauthorized access, modification, disclosure, destruction, or loss. While these are related, they are concerned with distinct duties. While an organization may protect its database from hackers, it can still over-collect personal data, thereby breaching privacy expectations. Likewise, a business may acquire customer data with an agreement and neglect to secure it from unauthorized access and use by cybercriminals. Organizations need to tackle the issue of ethical, privacy, and security concerns as one, and not as separate administrative tasks.
Ethical data practices also impact an organization’s reputation, customer relationship, and long-term sustainability. When businesses transparently communicate their data practices and responsibly manage personal information, customers are more likely to have trust in the business. They are more likely to buy into workplace analytics if they know what they are and where they fall short. Councils and business partners could also seek from organisations that they uphold standards in data processing and adhere to the applicable law. Poor practices can lead to financial losses, legal issues, reputational damage and the decisions that favour some individuals and communities while harming others. The implications of these consequences make it clear the importance of including ethical issues in the data mining process from the beginning of the project rather than at the end. Those who integrate analytical innovation with responsible information management will gain insights and mitigate risks in more data-driven operations.
Importance of Informed Consent and Transparent Data Collection
Informed consent is the most basic requirement for responsible data collection, in that individuals need to be able to feel they possess the information that an organization will be seeking to collect and what it will be used for. There’s more to meaningful consent than providing a long privacy policy that users accept without reading. Organizations should address their purpose in clear language, identify the categories of information that are relevant and will be shared, describe pertinent sharing arrangements, and communicate significant risks. For instance, if a person visits a shop to buy a product, the application could be used to store their purchase history and then recommend similar products for their next visit; or if a person visits a health care facility to get a medical diagnosis, the application could then be used to record medical data to help with treatment or research. They should be made aware of these purposes and have the chance to provide informed consent if it is the right legal basis for processing. Organizations should also be aware that there are other legal bases for processing personal information in other jurisdictions and contexts than consent. Other legal bases can be necessary or allowed according to the law. Transparency thus means making the purpose of the processing and the related rights of the data subjects understandable.
Organizations should also refrain from using deceptive consent mechanisms which can obscure the understanding and control of information. But a service should not make it seem like it can’t be done without including unnecessary tracking, or that it’s a requirement without actually being a requirement. If consent is relied upon, it must comply with relevant laws such as being free, clear, informed and properly documented. Organizations should offer easy ways to withdraw consent where required by law and explain the consequences of withdrawal. Organizations should implement the protection mandated by relevant laws for children or other people who might need extra protection. Communicating with transparency should be ongoing because changes in data practices over time should be reflected in the data. If an organization processes information for a new purpose, disseminates its information to other organizations, or implements a significantly altered analytical methodology, it should consider if extra notice, consent, or other legal actions are required. These practices help build trust and minimize the risk of people finding out that their data has been used in a different way.
Principles of Data Minimisation and Purpose Limitation
The principle of data minimization encompasses gathering and storing as little personal data as possible, only what is essential for a specific and legitimate purpose. This principle aims to minimise the risk of privacy being compromised due to a security breach or through the actions of an employee, contractor or third party. For instance, if a company is studying the general purchasing habits, it can collect purchase dates, product types, and purchase totals, but not need the whole residential address or personal identification numbers of the customers. There is a cost associated with adding more information that might be needed later, but hasn’t yet been determined.This is because there is an added cost to collecting all the information that may be useful in the future, but not now. Organizations must thus formulate the questions that they want a data mining project to answer beforehand, before information is gathered. They should also look at existing data sets to find out if all the fields are really needed in the desired analysis. Retention schedules should provide guidance for the safe disposal or even appropriate anonymization of information when it is no longer needed, while taking into account relevant legal requirements.
Purpose limitation is used in conjunction with data minimization and involves considering whether the information is being used for the purpose for which it was collected or for a legally allowed reason. Information gathered to enhance customer service shouldn’t be used for activities unrelated to that, like employee monitoring or political profiling or targeted advertising. While the amalgamation of datasets can provide beneficial relationships, organisations should consider whether the proposed amalgamation is proper, legal and in line with the reasonable expectations of individuals. They should set out what the processing is for, develop procedures for the approval of new uses and evaluate the need for further safeguards. Data minimization and purpose limitation should not stifle innovation but rather help organisations to consider analytical projects more carefully in relation to their specific purpose. A well-designed data set can eliminate unnecessary complexity, enhance data quality, reduce processing expenses and minimize access to sensitive data. Organisations can then identify the value that data mining provides and differentiate it from data mining that creates risks for the organisation and doesn’t provide value.
Anonymization and the Protection of Personal Information
One of the key privacy protection methods is anonymization which aims to stop information being linked to a specific individual. In an analytical process, instead of relying on specifically identifying information throughout the process, organizations can transform their data so that individuals might not be reasonably ascertained from that information. Typical methods include the removal of direct identifiers, generalisation of specific identifiers, consolidation of records and suppression of information that might be used to identify individuals. For instance, a hospital that is researching the prevalence of disease in the region may report on the totals, rather than individual patient names, contact information, or personal medical records. Researchers and businesses can learn about wider trends without having to routinely access information which identifies each person. For more details on what this means in this context, organizations can refer to the anonymization guide for an overview of anonymization in data.
But anonymity does not simply occur when names and identification numbers are deleted. Sometimes the anonymous individuals can be reidentified by merging them with other data sets that are available. Information stored in a database that includes a rough age, work place or location history, and an unusual pattern of activities could allow an individual to be identified from other public records or commercial databases. Therefore, caution should be exercised before releasing or sharing anonymized information, especially data with location records, health data, or other sensitive attributes that could be reidentified. They can mitigate these risks by abstracting away unique attributes, modifying the specificity of the data they release, restricting access to additional data sets that support the data, and by asking if realistic combinations of external data can identify individuals. Additionally, if appropriate, privacy-enhancing methods like differential privacy can be used to publish statistical results while minimizing the extent to which the results reveal information about any specific person. Anonymized data is also different from pseudonymized data, and organizations need to be able to tell the difference. Pseudonymization is the process of replacing identifying information with codes or other identifiers; information can still be considered personal data if the individual is identifiable with additional information. The method used must be appropriate for the analysis one wants to conduct, the context in which the information is used and the legal parameters that apply.
Algorithmic Bias and Unfair Data Mining Decisions
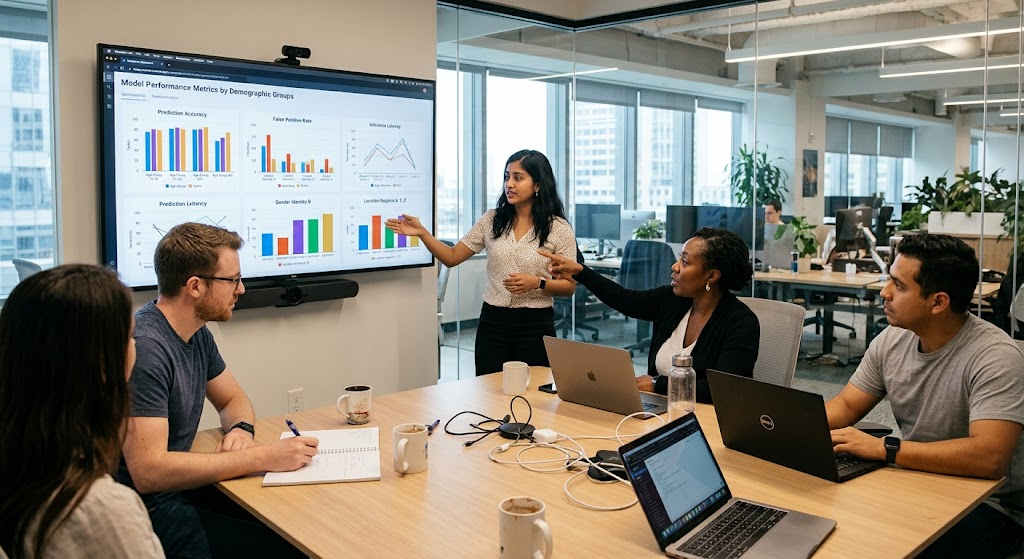
Algorithmic bias is the systematic undesirable or unfair result that occurs for specific people or groups with data mining systems. These issues may stem from missing data, historical bias, incorrect assumptions, non representative sampling, and the analysis methods themselves not taking into account important differences. For instance, a recruitment process which was trained on past hires might be biased towards hiring candidates with similar past experiences. An unequal distribution of financial services in the data that is used to train a credit assessment model could disadvantage certain communities. When the algorithm is not explicitly based on sensitive characteristics (disability or ethnicity), other characteristics may also be proxies. Therefore, automated decisions can reinforce inequalities and give the impression of being objective, as they are based on mathematical models.
One way to mitigate algorithmic bias is to review the data sets used before training models and to test the performance of the models on the various population groups. Data quality checks should detect missing data, incorrect labelling, out-of-date data, and trends which could indicate past discrimination. In development, teams should evaluate the variables chosen and the need for the purpose and whether these variables are using inappropriate proxies. Once deployed, organisations should check the results, explore surprising differences and tweak systems if they are not functioning as well. When AI-generated information can impact hiring, loan eligibility, admissions, medicine, or other critical services, human oversight is especially crucial. There should be suitable opportunities for individuals to challenge consequential decisions and ask for explanations when necessary in accordance with the law. But fairness is not strictly a number, as sometimes different fairness criteria may clash under different circumstances. Organizations should thus establish their notions of fairness, record key trade-offs, engage relevant parties, and hold individuals accountable for decisions they make when using algorithms.
Avoiding Unauthorized Profiling and Excessive Surveillance
Profiling is the process of using data on a person to assess or forecast interests, preferences, behavior, financial situation, and/or likely future actions. Proficient profiling can facilitate valuable services such as fraud detection, personalized recommendations, and unusual account activity detection. However, profiling is a problem ethically when its use involves special attention to the personal data in ways other than intended, is intrusive, discriminatory, or inadequately justified. A company could use its knowledge of a person’s browsing behavior, their purchasing habits, where they live and what their age and gender are to draw inferences about their personal characteristics. Even if these inferences are legally collected, the organization can be harmful if its use in decisions about purchasing, exclusion from opportunities, or making other consequential judgments is not adequately safeguarded.
Organizations need to have clear guidelines on profiling and the use of inferred information. These rules should clarify what is and is not allowed, limit high-risk or sensitive inferences as necessary, and mandate further consideration where profiling might have a substantial impact on people. Organisations should also ask whether people know what the activity is doing and whether laws are in place to protect them from some types of automated decision-making. There should be checks on the predicted outcomes of profiling systems and no employee should take it for granted that a predicted characteristic is correct just because it was generated by an algorithm. Inferences are not always complete, correct, or correlational. Only staff members who have a legitimate need to access profiles should have access to them and organizations should not keep on holding behavioral information without any time limit. Organizations can make effective use of analytical data without turning the process of collecting data into an unjustified spying, by analysing the necessity, proportionality, transparency and potential harm.
Information Security Risks and Data Breaches Concerns
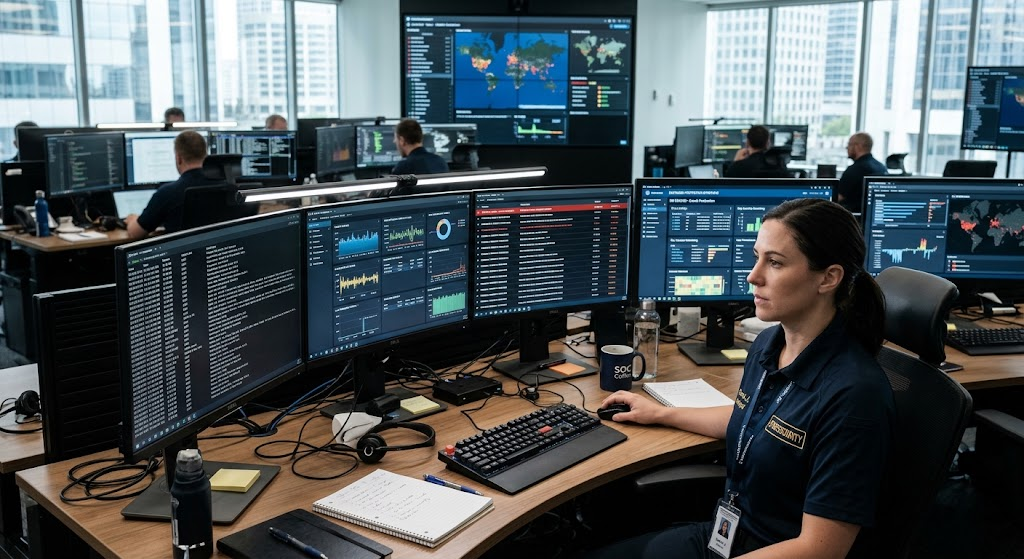
One of the biggest concerns with data mining is data breaches, as data mining systems tend to store large amounts of valuable data in databases, the cloud and in interconnected applications. A breach could reveal customers’ names, employees’ records, money, business plans, or secret research. They could make use of weak passwords, software that is not patched, insecure application interfaces, phishing attacks, misconfigured cloud storage, or excess user permissions. Another way that insider threats can occur is when a user with permission to access the system makes an unauthorized use of it or inadvertently reveals confidential data. Impacts can range from identity theft and financial fraud to disruption to operation, legal penalties and loss of public confidence. Organizations with robust security systems can still be compromised if their staff is not adequately trained, or if their data handling processes are not secure.
Security needs to be multilayered in order to be effective, not just a technical solution. Businesses should ensure that sensitive data is encrypted at rest and in transmission, employ multiple-factor authentication on critical systems, apply security patches as quickly as possible and have good backup systems. Access control should restrict usage to those who have a need to know, and should only allow users access to the data and functions needed to fulfill their duties. Monitoring and logging can be used to detect unusual activity, and frequent vulnerability scans and penetration testing can uncover vulnerabilities before they can be exploited by attackers. Organizations should also create incident response plans that will designate who is responsible for each incident, how communication will be handled and how affected systems will be contained and restored. In the event of a breach, they are required to determine the cause of the breach, understand the type of information impacted and preserve relevant evidence, and notify relevant regulators or individuals as required by applicable law. Security needs to be reviewed periodically as threats, technologies and organizational needs evolve.
Responsible Information Sharing – Third Party Access
Information sharing enables companies to work with researchers, suppliers, service providers, business partners and public institutions. Scientific discovery, public service, fraud detection and discovery of insights that might not be found by a single organisation can all be achieved through proper management of sharing. But there’s also issues about sharing information with others: unauthorized use, wrongful purposes, lack of adequate security, and additional disclosure. A company that transfers customer information to an analytics service could find its data ownership rights limited when it comes to access, use, and aggregation with other data sets. When information crosses borders to other nation states, and/or goes through multiple subcontractors, problems can become more complicated. The value of a proposed partnership, plus the privacy, security, legal, and ethical considerations, are therefore issues to be considered when evaluating responsible information sharing.
Organizations are advised to first determine the purpose of the transfer, the information needed for the transfer, and determine if the recipient can properly protect the information. Specific policies and plans should be established in writing that outline allowable uses, security requirements, privacy and confidentiality requirements, time limits, how to delete files from the system and how to report incidents. Organizations may define the roles of controllers and processors, as well as others, with respect to applicable privacy legislation. They should also consider if further protection is needed for cross-border transfers. While the sharing of individual-level data may also be necessary, exposure can be mitigated by either sharing aggregated data or using appropriately anonymized data; in either case, there is a risk of reidentification that must be taken into account. Third party relationships should be periodically reviewed, the compliance to contractual obligations checked, and access terminated when the partnership is to be broken or there is a legitimate need not to maintain it. These measures safeguard the sharing of information in a way that adds value but does not lead to the uncontrolled flow of personal information.
Establishing Effective Data Governance Policies
Data governance provides the organizational structure needed to manage information responsibly throughout its lifecycle. It establishes who can collect data, who owns particular decisions, how information should be classified, which quality standards must be met, and how privacy and security obligations will be enforced. Without effective governance, different departments may adopt conflicting practices, retain unnecessary records, use inconsistent definitions, or grant access without adequate justification. A comprehensive governance framework should assign clear responsibilities to relevant personnel, including data owners, data stewards, security teams, privacy professionals, legal advisers, and business leaders. These roles should work together to ensure that data mining projects meet organizational objectives while respecting legal obligations and ethical standards.
Organizations should begin by developing written policies covering data collection, consent, classification, access, retention, sharing, quality management, and incident response. They should maintain inventories of important datasets and document where information originates, how it is transformed, who can access it, and which purposes justify its use. Privacy impact assessments or other appropriate risk assessments should be conducted before introducing projects that involve sensitive information, extensive profiling, or potentially significant effects on individuals. Governance policies should also establish approval procedures for new analytical projects and define circumstances requiring additional human review. Employees need regular training on privacy responsibilities, secure data handling, phishing risks, and appropriate information sharing. Senior management should oversee implementation, provide adequate resources, and investigate repeated failures to follow established rules. Governance becomes effective when policies influence everyday decisions rather than remaining documents that employees rarely consult.
Restricting Access to Sensitive Information
Access control is a central component of data governance because not every employee or system requires access to every available dataset. Excessive permissions increase the likelihood of accidental disclosure, deliberate misuse, and unauthorized changes. Organizations should apply the principle of least privilege, granting each user only the access necessary to perform assigned duties. For example, a marketing analyst may need aggregated customer purchasing patterns but should not automatically receive access to individual medical records or complete payment credentials. Similarly, a database administrator may require technical access to maintain a system without needing permission to use its contents for unrelated analytical purposes. Separating responsibilities can reduce the risk that one person will collect, approve, export, and distribute sensitive information without independent oversight.
Organizations should use role-based access control, multifactor authentication, encryption, and secure data environments to protect information from unauthorized users. Permissions should be reviewed regularly, especially when employees change roles, contractors finish assignments, or third-party agreements expire. Temporary access should have defined expiration dates, while emergency access should be logged and reviewed afterward. Sensitive information should not be copied into personal devices, unsecured spreadsheets, or unapproved cloud applications simply because doing so makes an analytical task easier. Where possible, analysts should work with masked, aggregated, or appropriately anonymized datasets rather than identifiable records. Automated monitoring can flag unusual downloads, unexpected access attempts, and large transfers of information. Combining technical restrictions with clear policies and employee accountability helps organizations reduce exposure while allowing legitimate analytical work to continue.
Maintaining Data Quality and Reliability
Data quality is essential to responsible data mining because inaccurate or incomplete information can produce misleading conclusions and harmful decisions. Errors may originate from outdated records, duplicate entries, inconsistent formats, incorrect labels, missing values, or information collected through unreliable methods. When such problems enter analytical models, they can distort forecasts, undermine research findings, and contribute to unfair treatment. For example, an organization that uses outdated customer addresses might incorrectly identify fraud patterns or deliver services to the wrong locations. A healthcare model trained on inconsistent patient records may produce unreliable predictions that affect clinical decisions. Data quality is therefore not merely a technical concern; it is an ethical responsibility whenever analytical results influence individuals, communities, or organizational operations.
Organizations should establish measurable data quality standards covering accuracy, completeness, consistency, validity, timeliness, and uniqueness. Validation rules can identify impossible values, while duplicate detection can prevent repeated records from distorting analysis. Teams should document data sources, transformation procedures, known limitations, and assumptions that influence interpretation. Regular audits can reveal problems that automated checks miss, particularly when errors are systematic rather than obvious. Organizations should also avoid filling gaps with unsupported assumptions or presenting uncertain predictions as established facts. When datasets do not adequately represent the population being studied, analysts should communicate that limitation and consider whether additional data is necessary. Maintaining reliable information requires ongoing monitoring because datasets can become less useful as circumstances change. By treating data quality as a continuous process, organizations can improve analytical accuracy while reducing the risk of decisions based on defective evidence.
Complying With Privacy Regulations and Legal Requirements
Organizations that collect or analyze personal information must identify and comply with the privacy and security requirements applicable to their activities. These requirements vary according to jurisdiction, the nature of the information, the individuals concerned, and the organization’s role in processing it. In the European Union, the General Data Protection Regulation (GDPR) establishes requirements concerning lawful processing, transparency, data minimization, individual rights, security, and accountability. In Nigeria, the Nigeria Data Protection Act 2023 provides a legal framework for protecting personal data and regulating its processing. Other countries maintain their own privacy laws, sector-specific rules, and requirements for international data transfers. Organizations operating across several jurisdictions should not assume that compliance with one country’s requirements automatically satisfies every other applicable law.
A practical compliance program should identify the organization’s data processing activities, determine the relevant legal obligations, and assign responsibility for meeting them. Depending on the circumstances, organizations may need to provide privacy notices, identify a lawful basis for processing, respond to requests from individuals, conduct data protection impact assessments, or implement additional safeguards for international transfers. They should also establish retention schedules, maintain appropriate records, and create procedures for responding to data breaches within legally prescribed timelines. Some organizations may be required to appoint a data protection officer or fulfill other specific governance obligations. Because legal requirements can change and different provisions apply to different situations, organizations should seek qualified legal or privacy advice when necessary. Compliance should be integrated into project planning, procurement, system development, and routine operations rather than treated as a final checklist after a data mining system has already been deployed.
Balancing AI-Powered Data Mining With Individual Rights
Artificial intelligence is making data mining more powerful by allowing organizations to analyze complex datasets, detect subtle patterns, automate predictions, and generate recommendations at greater scale. These capabilities can support earlier disease detection, improve fraud prevention, optimize transport systems, and help businesses respond to changing customer needs. Nevertheless, AI systems can also make it easier to combine information from unrelated sources, infer sensitive characteristics, and automate decisions that affect large numbers of people. The scale and speed of these systems can magnify existing weaknesses in privacy, security, fairness, and accountability. Furthermore, complex models may make it difficult for individuals to understand why a particular decision was made. Organizations must therefore evaluate not only whether an AI-powered data mining system produces accurate results but also whether its use is necessary, proportionate, fair, and consistent with individual rights.
A responsible approach begins with privacy and ethics considerations being incorporated into system design from the outset. Development teams should assess risks before collecting data, use privacy-preserving techniques where appropriate, and evaluate whether the expected benefits justify the information required. High-impact applications should receive stronger oversight, including documented testing, meaningful human review, and procedures for addressing complaints or correcting harmful outcomes. Organizations should monitor deployed models for performance deterioration, unexpected behavior, and discriminatory effects. They should also explain important limitations to decision-makers and avoid treating statistical predictions as unquestionable facts. In some circumstances, the most responsible decision may be to reject a proposed use of data because its risks outweigh its likely benefits. Balancing innovation with individual rights does not require abandoning advanced analytics; it requires ensuring that technical capability is accompanied by proportional safeguards, transparent decision-making, and clear accountability for the consequences.
Best Practices for Responsible Data Mining
Organizations can strengthen responsible data mining by translating ethical principles into practical procedures that employees and technical teams can follow consistently. First, every project should have a clearly documented purpose and an assessment of the information necessary to achieve it. Second, data collection and processing should comply with applicable legal requirements, with appropriate transparency and consent mechanisms where required. Third, organizations should classify information according to sensitivity and apply suitable access controls, encryption, retention limits, and deletion procedures. Fourth, they should evaluate whether anonymization, aggregation, or other privacy-enhancing techniques can reduce exposure without undermining the analytical objective. Fifth, datasets and algorithms should undergo quality checks and fairness assessments before deployment, with continuing monitoring afterward. These measures should be supported by documented responsibilities, staff training, independent review where appropriate, and clear procedures for reporting suspected misuse or security incidents.
Organizations should also measure the effectiveness of their safeguards instead of assuming that written policies guarantee responsible behavior. Useful indicators include the number of unresolved access-control weaknesses, completion rates for employee training, the time needed to respond to privacy requests, the frequency of data quality errors, and the outcomes of algorithmic fairness assessments. Security incidents and complaints should be investigated to identify their underlying causes, while lessons learned should inform policy updates and technical improvements. Management should periodically review whether data mining projects continue to serve their original purposes and whether changing circumstances introduce new risks. Involving privacy specialists, security professionals, data scientists, legal advisers, and relevant stakeholders can help organizations recognize problems that a single department might overlook. Responsible data mining is an ongoing process of evaluation and improvement, not a one-time approval obtained before a project begins.
Conclusion
Data mining offers substantial opportunities for organizations to improve decision-making, identify emerging trends, strengthen security, and develop more effective services. However, these benefits depend on collecting and analyzing information in ways that respect privacy, protect sensitive records, maintain fairness, and comply with applicable legal requirements. Informed consent, data minimization, anonymization, algorithmic accountability, and restrictions on unauthorized profiling help reduce the risks associated with personal information. Strong security controls, responsible information sharing, reliable data quality practices, and effective governance further protect individuals and organizations from misuse, discrimination, and data breaches.
As artificial intelligence expands the scale and sophistication of analytical systems, organizations must remain attentive to the consequences of their decisions and provide appropriate oversight of automated processes. The most sustainable approach combines technological innovation with transparency, accountability, and respect for individual rights. By making ethical and privacy considerations part of every stage of the data lifecycle, organizations can extract meaningful insights while maintaining public trust and reducing the potential for harm.