Introduction
From online transactions, mobile applications, social media, our connected devices, scientific research and our daily business, organizations create vast amounts of information. But gathering data does not necessarily yield valuable knowledge. For businesses, the ability to identify meaningful patterns, to know the trends that are changing and to draw on their findings to make informed business decisions. Big data mining comes in handy here.
Big data mining is the analysis of very large and complicated sets of data to find correlations, identify unusual behavior, forecast future trends, and aid in decision making. Big data mining is different from conventional data analysis, where the sets of data involved are normally smaller and more structured. If done properly, it can help organisations gain efficiency, gain insight on their customers, uncover potential risks and uncover opportunities that can be missed in the vast amount of data.
Big Data and its Characteristics
Big data are sets of data, which are too large, too complex or grow too quickly to be efficiently managed or interpreted with traditional data management techniques. These datasets can be millions or even billions of records from various data sources over long periods of time. Volume, velocity and variety are often used as the three key concepts to explain the concept. Some other attributes such as veracity and value further describe the reliability of data and the benefits that an organization hopes to gain by analyzing it.
The National Institute of Standards and Technology states that to handle large amounts of data, big data demands scalable architectures. As a result, not only the quantity of information that is collected, but also the speed of its arrival, the variety of information types, and how well systems can convert information into actionable knowledge must be taken into account. An awareness of these characteristics is essential for the choice of suitable mining method and related technology.
Data Volume
The volume is the amount of information which an organization collects, stores and processes. Today’s companies can collect a lot of data from customers, web interactions, finances, satellites, medical data, to industrial sensors. For instance, a logistics company might have years of data on vehicles’ locations and usage, delivery records, transactions at warehouses, and fuel used. This information when taken as a whole can show patterns that smaller samples may not. But, they need adequate data storage, computing power, and data management processes to handle such a vast amount of data.
Distributed Storage Systems are options that distribute information among multiple machines, rather than a single server, that could be necessary for organizations. They should also have policies for keeping copies of valuable information and discarding copies of unimportant information. The main idea behind volume management is that it guarantees that large datasets can be analysed without leading to unacceptable storage expenses or overwhelming the infrastructure used for processing the data.
Velocity: The Speed of Data Generation
Data velocity is the speed of data creation, movement, and analysis. A lot of organizations are getting information on a continuous basis, not just on a periodic basis. Financial transactions, GPS signals, Internet purchases, website visits and equipment sensor readings may come in quick succession. Here, it might be best to examine information a few hours or days after it is posted. A payment provider, for example, might have to review the transactions and see if there is any fraudulent activity immediately so that more money isn’t lost.
Likewise, a delivery company is better off being given timely traffic updates when determining if vehicles should take alternative routes. Organizations can use stream processing technologies to analyze information that arrives continuously and generates results in a timely fashion. However, not all of the data sets need immediate analysis. It is important for businesses to understand the difference between a task that would be better served by real-time processing versus one that can be done in a batch-oriented manner, weighing speed, accuracy and computational expenses against the business needs.
Varieties of Data
Variety refers to the diversity of formats, structures and sources of information organizations need to analyze in conjunction with each other. Structured data consists of data that is stored in a tabular format, like customer details, transaction logs and inventory lists. Semi-structured data is provided in formats like JSON documents and application logs, and unstructured data is found in photographs, videos, audio recordings, emails and social media posts. These various formats may provide supplementary information.
A manufacturer might, for instance, use the equipment sensor data with the maintenance records and production schedules to analyze why some machines have multiple failures. To derive any meaningful insights, methods for processing each format and linking information that refers to the same events, customers, or processes need to be used. These connections can be set up with the help of data integration tools, metadata management, and suitable storage systems. If it can be done right, companies can gain a more complete picture of their activities than if they were able to rely on one database.
Major Techniques used in Big Data Mining
Big data mining is the process of using statistical analysis, machine learning, pattern recognition and large-scale computing to extract useful information from large data sets. The choice of technique will vary, depending on the goals of the organization, the nature of its data, and the information desired. Classification, for instance, assigns records to a group of labels which are established a priori, while clustering clusters records together without using labels already provided. Association analysis finds relationships between events or items, while anomaly detection raises observations that are quite different from the normal pattern.
Predictive modeling involves analyzing past data to identify potential future trends or outcomes, such as equipment failures or shifts in customer demand. These methods are more complex if there are billions of records, or if the data is regularly updated. As a result organizations look to efficient implementations and parallel computing for getting analyses done within practical time constraints. Choosing the right solution is key as even the most advanced algorithms can only provide limited business value, if used to solve the wrong problem or if they are based on the wrong data source.
The Concepts Distributed Processing and Parallel Computing
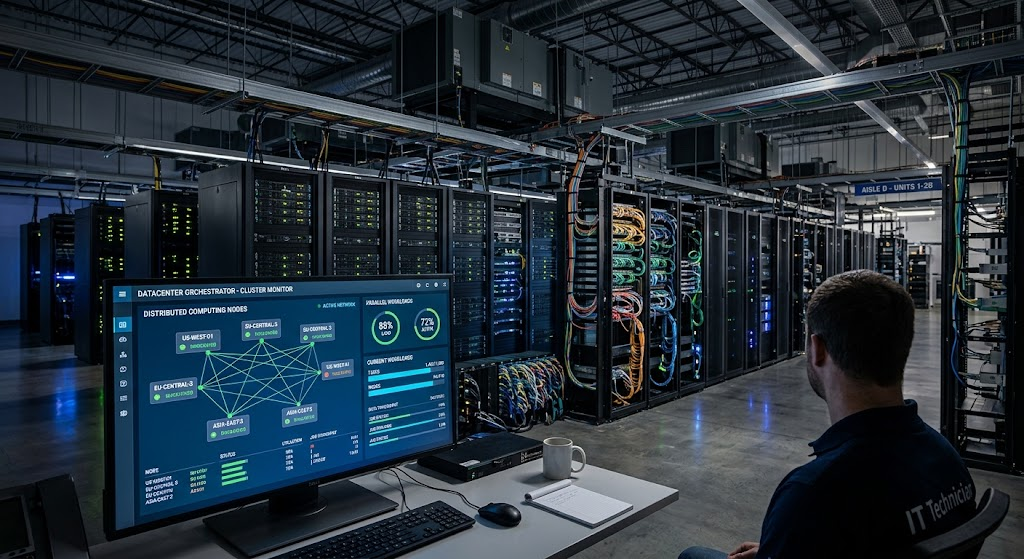
In distributed processing, the large computational task is broken down into smaller sub-tasks and then the sub-tasks are carried out by several interconnected computers. A distributed system would break up a large set of data into smaller chunks and send each one to a different machine which then would be able to work concurrently. They then arrive at some results which are then merged to form the final output. Distributed data processing and large-scale analytical workloads can benefit from frameworks like Apache Spark, which can help manage the increasing computational demands that traditional systems fall short of.
For instance, a retailer with a lot of years of buying data can share the data across a cluster and use parallel processing to determine buying trends. Distributed systems can also grow with more computing nodes as workloads grow. Their effectiveness is reliant on communication between machines, workload distribution, fault tolerance, and efficient data movement management. Unstructured processing tasks could lead to bottlenecks, especially when there are a limited number of nodes with very heavy workloads or a large number of nodes that need to communicate a lot of data back and forth.
Scalable Mining Algorithms
A scalable mining algorithm is one that is designed to ensure good performance with the increase in size and complexity of data sets. They enable an organization to find patterns without the need to expand the computation of the organization without end as new information arrives. Scalable methods can be parallel computing, use of efficient data structures, sampling, incremental learning, or distributed training of the model. The incremental methods are especially beneficial in situations where new records are constantly being added, because they can add to and modify results as they are received.
Sampling can also decrease computation costs if a judiciously selected sample can contain enough information for an analytical problem without violating important features of the underlying data and numbers. This research resource provides a technical background on scalable mining algorithms which organizations interested in efficient analytical approaches can study. The best algorithm for a specific problem is of course dependent on the data set, the desired accuracy, the computing budget, and the desired time for delivering useful results.
Cloud Data Platforms and Storage.
Cloud data platforms deliver computing, storage and analytical services via infrastructure that can be accessed over a network. Instead of buying and running all servers on their own, companies can take advantage of cloud resources to store extensive information, run processing jobs and support analytical applications. Cloud data warehouses are especially beneficial for structured data and reporting, and data lakes support a broader variety of raw and processed data formats. Some organisations integrate these strategies into a larger data architecture. Cloud platforms may also enable the ability to scale up and down computing resources as needed during high-traffic periods and during downtimes.
This versatility is important if businesses have varying analytical needs across the year. But, lower costs and better performance do not necessarily mean cloud computing. Increased costs from data transfer fees, storage retention, resource configuration, security requirements, and inefficient queries.The costs of data transfer fees, storage retention, resource configuration, security requirements, and inefficient queries. But organizations need to keep track of resource usage, and choose services to best fit their workloads, and not assume that offloading data to the cloud will solve all data analysis problems.
Stream Processing and Real-Time Analytics
Stream processing can process information as it is received and help organizations recognize significant changes without the need to wait for a complete set of data to be collected. It can be particularly valuable if the response is time-sensitive based on the discovery. For instance, a bank might analyze incoming transactions for unusual patterns and an industrial monitoring system might examine sensor readings to determine if there are any unusual equipment activities. Incoming events are often organized, transformed, stored and used to generate alerts or analytical results within streaming systems.
Some applications implement streaming and batch processing at the same time, so that immediate events can be analysed in conjunction with the historical patterns. This mix enables companies to react swiftly and yet have a wider overview of patterns. However, there are some challenges with real-time analytics such as network latency, missing data, duplicate messages, and evolving data structures. Systems need to also decide what to do with information that is received late or out of order. To ensure reliable stream processing, careful design, continual monitoring, and the ability to guarantee results despite temporary failures from individual components are required.
Real-world Applications of Big Data Mining.
- Logistics and Supply Chain Management
Big data mining is utilized by logistics firms for enhancing delivery arranging, stock management, vehicle utilization and supply chain transparency. They can merge GPS data, traffic, delivery information, stock levels, weather forecasts and order data from customers. These sources can be used in conjunction to establish any common bottlenecks, delivery time estimates and which routes are linked to higher fuel consumption. Predictive models can also be used to predict demand at various locations, which can enable businesses to have inventory closer to customers who may be interested in specific items.
For instance, a distribution company might look at delivery time in the past and traffic data to determine which routes are often congested. It could then recommend alternate scheduling or routes to the drivers. Warehouse records could also indicate what products are seen as out of stock often or unused for long periods of time. These applications can help logistics companies increase the reliability of their services, minimize wasteful operating costs, and optimize transportation and storage resources.
- Healthcare Research and Patient Outcomes
The healthcare industry produces a vast amount of data in the form of electronic health records, laboratory data, medical imaging, clinical studies, genomic information and public health monitoring. By using big data mining, researchers are able to study relationships that span these sources and to explore the big data that can’t be easily investigated through small datasets. For example, the relationship between demographic variables, treatment experiences, and specific health outcomes can be examined. Similar patient populations can be identified using pattern recognition and predictive models can assist in studying the progression of disease and the need for healthcare services.
Large-scale analysis can also help public health officials keep track of trends in the diseases and identify changes that might need to be looked into further. Healthcare data, however, stands out as having even more stringent protections and safeguards due to its potential to include sensitive personal information. Before conclusions can be reached, researchers need to take into account issues of consent, access, privacy, data quality, and possible bias. The analytical results should also be assessed by expert health care workers and substantiated by relevant research techniques. Big data mining can bolster medical research, but it doesn’t create any magic bullets – or prove that a noticed connection is a cause.
- Financial Services and Fraud Detection
Payments, customer interactions, loan applications, and account activities are all examples of the sheer amount of information that financial institutions deal with daily through digital banking. The use of big data mining can assist these organizations in recognizing suspicious transactions, evaluating monetary risk, spotting unusual account activity, and comprehending the requirements of customers. Anomaly detection systems can identify transactions that do not follow typical patterns and classification models can predict the risk of specific transactions being fraudulent, using relevant historical information.
These systems are capable of processing several signals such as transaction time, total purchases amount, account activity, previous confirmed cases etc. But an unusual transaction doesn’t necessarily equal fraud, and alerts typically must be verified. Wrong predictions also have real-world implications for financial institutions, such as the loss of legitimate customers or the extra need for consumers to go through review processes. Ongoing model evaluation can help spot performance issues and evolving fraud trends. With proper human supervision, safe data management, and transparent investigation processes, big data mining can enhance the effectiveness of fraud detection and accelerate the detection of new fraud risks in financial institutions.
- Social Media and Customer Insights
Social media platforms create information by posting, commenting, reacting, sharing, searching, and interacting with digital content. Organizations can use this information to gain insight into customer preferences, track customer conversations about products, analyze marketing initiatives and identify new trends. Natural language processing can be used to categorize comments by topic or sentiment, and clustering can be used to group users or discussions based on their characteristics. For instance, a business introducing a new product might be able to scan online reviews and determine popular concerns, common complaints, and issues that need to be addressed in their advertising.
The results can help with product optimization and customer service. However, the data collected from social media platforms is not necessarily representative of an entire population due to the disparities between the participation rates of users of different platforms and communities. Analytical accuracy can also be impacted by sarcasm, slang, language differences, automated accounts and misleading posts. Thus, it is critical for organizations to carefully interpret findings, adhere to platform rules, and safeguard personal information. Social media mining can be used responsibly to give immediate feedback that can supplement surveys, in addition to customer interviews and other methods of research.
- Industrial Manufacturing and Predictive Maintenance
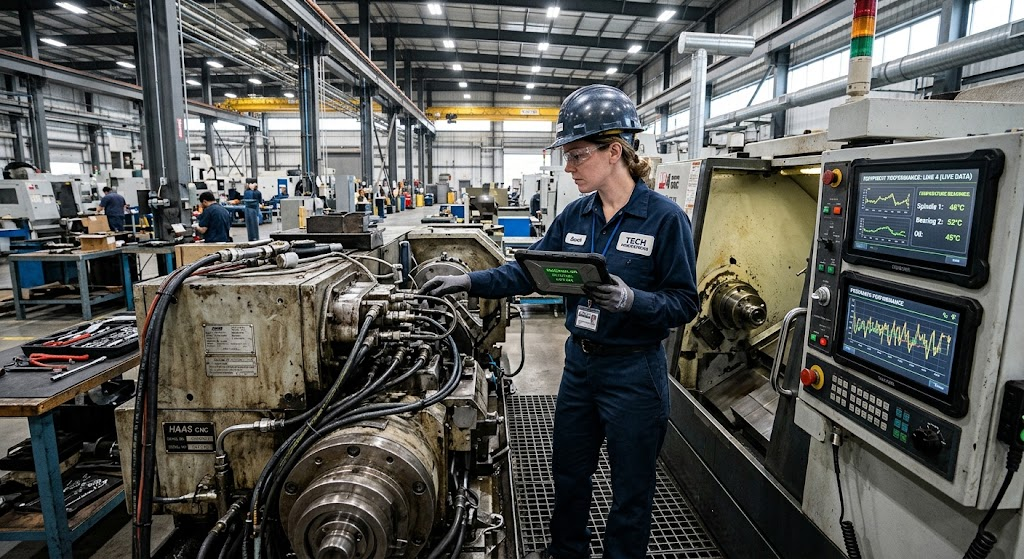
Industrial operations are increasingly being monitored with the aid of connected sensors, production equipment, inspection systems and inventory software. These sources produce vast amounts of data that can show patterns that relate to issues with products, machine performance, energy usage, production delays, etc. Through big data mining, manufacturers can look into these patterns and determine what conditions are propelling the challenges for their operations. One of the applications is predictive maintenance. Analysis of past data from the sensors, maintenance history, vibrations, and temperature variations can help a manufacturer spot indicators of equipment decay.
This enables maintenance personnel to preemptively find out if there is a problem and take the necessary steps to avoid a significant interruption. Quality control systems may also be used to compare the production measurements with the specified measurements to locate abnormal variations that should be addressed. Additionally, companies can compare energy use throughout the production process to find ways to be more efficient in their processes. The benefits rely on the correct readings from the sensors, correct analytical models, and the integration of these systems into the current industrial system. When predictive results may impact worker safety or product quality if the equipment fails, they should be validated prior to making maintenance decisions.
Major Challenges in Big Data Mining
- Data Integration and Interoperability
Businesses can gather data from various departments, software, vendors, and other platforms. Different file formats, naming conventions, identifiers, measurement units and definitions may be used in these systems. It can therefore be more difficult to merge their information than just storing it in one place. For instance, a logistics company could have a delivery date in one system, a shipment identifier in another and a customer reference in a third. If they can’t be matched correctly, the analysis may be incorrect and lead to a false impression of delivery performance.
Data integration is the process of extracting data from various data sources, converting it into a usable format, cleaning the data for consistency, and importing it into an existing data environment. This process can be facilitated by organizations with documentation of data standards, metadata management, shared identifiers, and automated validation rules. They should also be able to trace the sources of information and the changes in information as it is processed. Good integration practices minimise duplication, increase the consistency of the analyses and make it easier to appreciate how conclusions were reached.
- Storage Costs and Data Management
You won’t need to buy enough disk space. Backups, disaster recovery, access, transferring data, processing needs and information retention times are all factors that must be taken into account. Storing all records for eternity may incur unnecessary costs, especially if some records do not have much of an analytical or operational value. While cloud storage can eliminate the need to maintain physical infrastructure, there are still a number of ways that costs can increase along the way, such as frequent data access, large volumes of data processing, multiple copies of data and long-term retention.
The first step in effective storage management is to identify the requirements of the business and classify information based on its value, sensitivity and likely usage. High-speed data storage may be needed for data that is accessed on a regular basis, but historical data can be stored in lower-cost data tiers. It is also important for organizations to have schedules for retention and to delete redundant information as needed. Legal requirements, contractual obligations and research requirements all must be taken into account when making these decisions. A good storage strategy is making large scale analysis more sustainable by taking into account accessibility, reliability, security and cost.
- Data Quality and Reliability
The quality of the information analyzed is the most important factor in determining the accuracy of the analytical results. There are many cases where the data in large datasets are missing, containing duplicate records, incorrect timestamps, inconsistent labels, outdated information, or measures taken under varying conditions. Such issues can misrepresent statistical relationships and lead to poor predictions by statistical models. For instance, if a manufacturer gets inaccurate sensor data in its system, it can assume that the equipment is functioning properly or that the machine needs maintenance when it actually does not. Data quality management includes checking the integrity of the incoming data, identifying inconsistencies, normalizing the data, eliminating duplicate data, and recording any data limitations.
Organizations should also differentiate between true abnormal behavior and recording errors as they could both be outliers. Automated checks may help recognize frequent issues right away and periodic audits can assess the consistency of info over time. Importantly, cleaning data should not be a process of automatically removing any unusual observation. In some rare instances the most important data for fraud detection, scientific research or equipment usage is found. It’s important to strike a balance when mining that’s reliable, between correcting errors and preserving meaningful evidence.
- Infrastructure, Security, and Privacy
Processing big data effectively requires infrastructure capable of supporting storage, computation, networking, monitoring, and reliable access to information. Depending on the workload, this may include distributed computing clusters, cloud services, streaming platforms, databases, data pipelines, and tools for model development and deployment. Organizations must ensure that these components work together and can handle increases in data volume without unacceptable delays or failures. They also need skilled personnel who can manage data engineering, analytics, cybersecurity, and system operations.
Security is equally important because large datasets can contain financial records, medical information, customer details, or commercially sensitive information. Appropriate safeguards include encryption, access restrictions, secure authentication, monitoring, and tested recovery procedures. Privacy protections must reflect applicable laws and the sensitivity of the information involved. Organizations should collect only the data they need, establish clear rules for its use, and prevent unauthorized access. Infrastructure investments are most effective when they support specific business objectives rather than pursuing scale for its own sake.
Best Practices for Effective Big Data Mining
Successful big data mining begins with a clearly defined problem. Organizations should determine what they want to improve, what evidence is needed, and how analytical results will influence decisions. This approach helps prevent unnecessary data collection and ensures that technology investments address genuine operational requirements. The next step is to establish dependable data pipelines that collect, validate, integrate, and prepare information for analysis. Businesses should then select mining techniques that match their objectives, whether they involve classification, clustering, forecasting, anomaly detection, or association analysis. Testing is essential because models that perform well on historical datasets may become less reliable when real-world conditions change.
Organizations should evaluate accuracy, computational cost, fairness where relevant, and the practical usefulness of the resulting insights. Continuous monitoring can reveal data drift, changing patterns, and infrastructure bottlenecks that require corrective action. Finally, analytical findings should be communicated clearly to decision-makers and reviewed against measurable outcomes. This combination of sound objectives, reliable data, suitable algorithms, responsible governance, and ongoing evaluation creates a stronger foundation for sustainable big data mining.
Conclusion
Big data mining enables organizations to extract meaningful insights from datasets that exceed the practical limits of conventional analytical methods. By examining volume, velocity, and variety, businesses can identify the technological and organizational requirements of their data environments. Distributed processing, cloud data platforms, stream processing, and scalable mining algorithms help them analyze information efficiently, while classification, clustering, predictive modeling, and anomaly detection reveal patterns that support better decisions. Applications in logistics, healthcare research, financial services, social media, and manufacturing demonstrate how these capabilities can improve planning, strengthen research, identify risks, understand customers, and support more reliable operations.
However, achieving these benefits requires organizations to address data integration, storage expenses, information quality, infrastructure capacity, security, and privacy. The most successful approach is not simply to collect more data but to ensure that information is reliable, relevant, and analyzed with appropriate methods. When technical capabilities are combined with clear objectives and responsible data governance, big data mining becomes a practical tool for turning complex information into measurable organizational value.


