Introduction to Machine Learning Algorithms
The world of machine learning is gaining significant traction in the modern world and it has a significant impact on the way the business world works, how consumers obtain information and the decisions that organizations make. Machine learning allows computers to analyze data and make predictions or decisions based on patterns.Machine learning can be used to analyze data and make predictions or decisions based on patterns, for example, in the field of streaming services, it can be used to recommend movies to users based on their viewing habits, or in the field of banking, it can be used to detect suspicious transactions. The core of this technology is machine learning algorithms are the mathematical models that enable computers to learn from examples and enhance their performance on particular tasks. Machine learning systems don’t just execute pre-programmed instructions, but can learn from past data to create models for identifying patterns, categorizing data, and forecasting results. AI and data science students, future data analysts and software developers will need to understand these algorithms.
While machine learning is a mathematical and computational approach, it can be grasped more easily using examples from everyday life. Consider an actual real estate firm that would like to predict the price of real estate, an email company that would like to identify spam messages, or a retailer who would like to classify customers by their buying behavior. Every organization has its own issue and might require a different learning approach. There are algorithms that can predict numerical values, classify information by categories, and others that can find hidden structures in information sets. This tutorial presents seven popular algorithms, discusses their conceptual understanding, and explores their advantages, disadvantages, and real world applications. For more details about the types of machine learning algorithms used to create machine learning models, readers can check out IBM’s overview of machine learning algorithms.
Basic Types of Machine Learning.
It’s helpful to learn the big picture of how machine learning systems learn before looking at individual algorithms. Such methods dictate the information that is fed into an algorithm during training and the sorts of issues the algorithm can resolve. While these are the seven algorithms discussed in this article, supervised learning, unsupervised learning and reinforcement learning are the three broad categories of machine learning discussed. In the supervised learning approach, the training data is labeled; that is, each example that is fed into a model has an associated outcome or target. Unsupervised learning is used when the data does not contain specific labels for the target and tries to find patterns or relationships in the data. Reinforcement Learning is a type of learning where an agent interacts with an environment, receiving rewards or penalties based on the nature of the interactions. Beginners should know that these differences exist in order to identify why a specific algorithm might be advantageous for one task and not for another.
When there are examples in the past and you know what you want the output to be, supervised learning is used. For example, if you have a house dataset with information on the size of houses, their location and their selling price, you can use this information to train a model to predict the price of a different house. Likewise, a set of e-mail messages with labels of “spam” or “ham” can be used to train a classification system. When organizations wish to use data to identify new categories where they have no prior knowledge of the data, unsupervised learning can be helpful. It could be used by a retailer to identify clusters of customers whose shopping patterns are alike. Reinforcement learning, on the other hand, can be used when the system is being trained by taking multiple actions and receiving feedback from them, such as controlling a robot arm or making decisions in a simulated environment. The learning approach will be determined by the data available, the project goal, and the desired product or outcome of the project.
Linear Regression: Forecasting Numbers
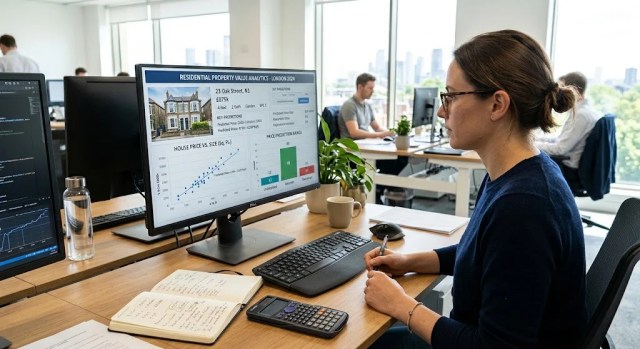
Linear regression is one of the most commonly used machine learning algorithms used for forecasting continuous numerical values. It’s based on the idea that there’s a link between one or more inputs and a number. The algorithm tries to fit a line into the data points observed so that the values predicted by the line are close to the actual values. For instance, a real estate firm may employ linear regression to predict house values by considering the size of the property. History indicates that there is a relationship between house size and selling price, and the model can learn this relationship and estimate the selling price of a house whose size is known but the selling price is unknown. Other input variables that may be useful are the number of bedrooms, property age or distance from key facilities. When training the model, the available examples are considered and the model will guess the relationship between each of the input variables and the price it predicts.
The first benefit of linear regression is that it is simple. The model is simple to understand and easy to compute and can serve as an initial model for many predictive projects. The values of its coefficients can be used to understand the link between the input variables and the output, as long as the analyst pays attention to the assumptions used in the model and the nature of the data. Linear regression has its drawbacks, however. It could work poorly when there are strong nonlinear relationships between variables and the target variable, or when there are important factors that are not included in the data set. An outlier can also have an impact on the fitted line; it may even cause the line to bend the opposite direction, which can lead to poor predictions. For instance, the price of houses could be influenced by the neighborhood, the economy, architecture, and demand from home buyers, etc., in a manner that can’t be captured by a linear equation. Even with these restrictions, linear regression is a useful option for forecasting quantitative results and comprehending relationships in data.
Logistic Regression: Categorizing Information
Although the word regression is in the name, logistic regression is actually the first regression that is used for classification not just for prediction of natural numbers unconstrained by the regression. It predicts the probability of an observation being in a given category and assigns a predicted category based on a decision threshold. For instance, the possibility of an incoming message being spam may be predicted by spam-related characteristics of the message (e.g., words that are likely to appear in spam, unusual links, content of the sender, and message structure). When the probability is above the probability threshold set by the system, the email can be considered spam; when the probability is lower, then it can be treated as valid email. The threshold level of probability can be made to suit the implications of the various errors. A fraud detection system could be designed to identify as many instances of fraud as possible, or the system could focus more on minimizing false alarms.
One of the reasons for the popularity of logistic regression is that it is relatively efficient, highly interpretable, and good for many classification problems. The estimated probabilities can be used to understand how a model calculates its probabilities of various observations, and the model’s coefficients can be used to gain information about the relationship between the input variables and the model’s prediction under the assumptions of the model. It may be especially helpful in situations where the relationship between the inputs and the log-odds of the outcome is reasonably linear. However, logistic regression might not be well suited to handle the more complex patterns if no features or transformations are added to the algorithm. The quality and representativeness of the training data are also important factors that affect the performance of it. For example, if a spam filter is trained with old spam, it may not be able to identify newer spam types. For other problems, like email classification, customer churn prediction, or some types of fraud detection, logistic regression is a practical choice because it is often important to have an understanding of the factors involved and requires less computing power.
Decision Trees: Prediction by Rules
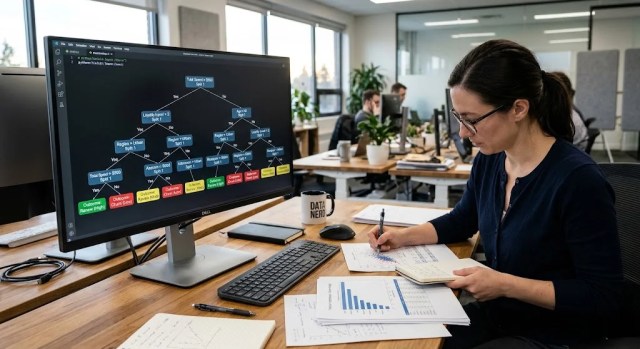
A machine learning algorithm that makes decisions by structuring a series of questions into a tree is a decision tree. Every node in the tree corresponds to a decision made based on a feature, every branch represents a possible answer, and every leaf is a prediction. This structure is similar to a flowchart, as there is a sequence of decisions then results. Imagine a bank that is trying to determine if a customer might be eligible for a specific type of loan. Some variables that can be explored in a decision tree are income, existing debt, how the debt is paid back, and job stability. It may first split applicants by income, look at the debt of those income groups and then come up with a prediction based on other characteristics of the groups. The algorithm is trained by choosing splits which contribute to the separation of observations by target value or class. This leads to a model which can be represented by a set of easily explained decision rules.
The most important advantage of the decision tree is that its learning rules are easy to understand. In many cases a relatively simple tree can be inspected visually, and thus gain an understanding of how it arrives at a prediction, without being as complicated as some of the other trees. Decision trees can also model non-linear relationships and interactions between variables, without having to be added on a case by case basis. They can be employed in classification and regression problems and their use can vary with the type of input features, depending on the implementation. But single decision trees may be unstable and over-fitting. Overfitting is when a model learns too much information out of the training data and is not able to identify a pattern that can be applied to other examples that it is not already familiar with. A very deep tree could give an accurate prediction on the training set of observations, but give poor predictions on new observations. Reduce this problem by techniques like limiting the depth of the trees, minimum number of observations in each leaf, pruning unnecessary branches etc. While useful in environments where explanations of the rules are important, decision trees need to be kept simple to ensure that they provide reliable predictions.
Random Forests: Multiple Decision Trees
Random forests overcome many of the drawbacks of single trees by aggregating predictions from a forest of trees. Rather than training a single tree, the algorithm learns several trees from different subsets of the training data, and different subsets of features. This provides diversity in the trees, and decreases the chance that the entire model would rely excessively on a specific set of observations or decision rules. In a classification problem, like detecting if a financial transaction is suspicious or not, the forest can vote as a whole to reach a conclusion. For regression, it usually takes the average of the trees’ numerical forecasts. The model uses multiple decision structures, so that sometimes it gives more stable predictions than one tree. Random forests are generally applied to tabular data, which is characterized by having rows for observations and columns for variables.
One of the greatest strengths of the use of random forests is that they can be used to model complex relationships without prespecifying interactions between variables. They can also deal with overfitting, which can be a problem with a single, unrestricted decision tree, and are generally effective over a broad spectrum of classification and regression problems. A random forest could be used in business to predict the likelihood of a customer churning, to determine the factors that lead to loan defaults, or to flag unusual financial transactions. The algorithm may also provide feature importance scores that can be used by analysts to determine which features affect the accuracy of the predictions, but these scores do not necessarily indicate cause and effect. Random forests come with their drawbacks too. They tend to use more memory and computing power than a single decision tree, and can be hard to understand the collective logic of several trees. They may also need more effort in the case of predictions to be explained to nontechnical people. However, for many practical machine learning applications, random forests have the valuable advantage of being powerful, flexible and robust.
Support Vector Machines: Effective Decision Boundaries.
A supervised learning algorithm known as support vector machines (SVM), is developed mainly for classification, although variants can be used for regression. The central idea is to determine the decision boundary that is able to classify between classes but also maximizes the distance between the boundary and the observations in the training set. These closest observations are known as support vectors as they aid in deciding where the boundary is placed. Suppose you have a dataset of examples of two categories of email, and that each message is a set of numerical features. An SVM tries to find a boundary which is as good as possible at separating the two groups. The bigger the margin, the more it can extrapolate onto new data, but the performance will vary based on data set and settings. In cases where a straight boundary is not enough, some SVM implementations can use kernel functions to represent more complicated separation patterns, without explicitly forming all possible transformed features.
In high dimensional datasets, especially when the number of features, n, is significantly greater than the number of observations, N, SVMs can be useful. They have been applied to text classification, document categorization, image recognition and other pattern-recognition problems. Moreover, they are the flexible tool for representing nonlinear boundaries if the appropriate kernels are chosen. But there are many hyperparameters (like the type of kernel, regularization level) that may affect the performance of the support vector machines. Sometimes feature scaling can be important because variables can have very large ranges and could have a disproportionate effect on the model. Depending on how it’s done, training may be expensive for very large datasets. Also, the predictions of an SVM might be more difficult to interpret than a small decision tree, and standard SVMs are unable to provide calibrated probability estimates without further techniques. The main thing to note for beginners is that an SVM learns a boundary of class separation; when one wants to distinguish between classes, the input data must possess meaningful patterns that distinguish the classes.
K-Means Clustering: Identifying Groups in Data
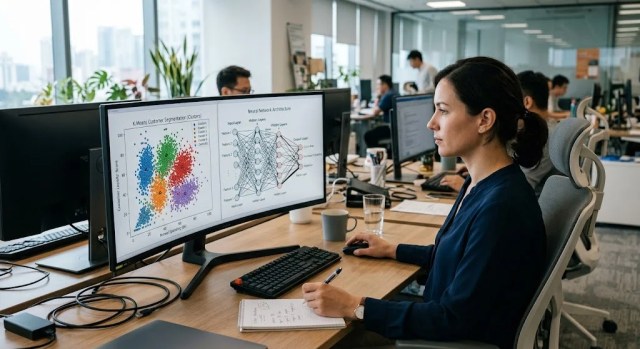
K-means clustering is an unsupervised learning technique that classifies observations into clusters based on their similarities. It does not need to have a correct category (the right class) specified for each instance, unlike supervised algorithms. Instead, the user sets the number of clusters (K) and the algorithm will try to classify observations into K clusters. It starts with the cluster centres, which are usually initialized using a technique like k-means++, assigns each observation to the cluster centre with the closest distance, and then re-calculates the cluster centres based on the observations assigned to each cluster. The above steps are repeated until assignments or cluster centres become stable or a stopping criterion is satisfied. In a retail store, say, it might be used to represent customers by means of information on purchases made, the amount spent and the kind of product bought. K-means could find clusters of consumers who have similar buying habits and into these clusters, the business can explore and create marketing strategies that are more relevant.
The advantages of K-means are that it is relatively easy to understand, is efficient for certain numerical datasets, and can be used to divide large amounts of observations into meaningful groups. It can be used for customer segmentation, exploratory data analysis, image compression and other tasks where finding similarities is more important than predicting a known label. There are important limitations, however, to the algorithm. The user has to select K in advance and the answer may differ depending on the initial cluster centres. Like other methods, k-means is also easily affected by feature scaling and outliers, and it is an approach based on distance and so works best if the clusters have relatively regular shapes. It might not work well if the groups are large, dense or have oddly shaped borders. The analysts can use techniques like the elbow method or silhouette scores to compare candidate values of K, but these techniques are not always able to give an objective answer. Most importantly, the clusters should be used in context; a mathematical cluster does not necessarily indicate a meaningful type of customer or provide an explanation as to why customers act in a certain way.
Neural Networks: Learning Complex Patterns
A neural network is a type of machine learning model that is inspired more generally by the interconnectedness of biological nervous systems. They are made up of layers of computational units, or neurons, that convert an input into an output. The simplest neural network consists of an input layer, a single or multiple hidden layer, and an output layer. When the network is trained, the numerical values between the units are tweaked in order to make the predictions more accurate, according to a chosen objective. This procedure typically includes a method called back-propagation that works out how the changes in parameters relate to changes in prediction error, and an optimization method that adjusts the parameters. The mathematics may be complicated, but the principle is that a neural network can be trained to find useful patterns of features by examples. An example of an image-recognition model is being able to learn patterns to recognize objects, while a language model learns statistical patterns between words and other components of text.
Neural networks are particularly well suited for tasks that deal with complex patterns, large amounts of data and unstructured data like images, audio, or text. Deep learning: Techniques that leverage multi-layer neural networks that can learn more complex representations. They are used in applications like speech recognition, image classification, language translation, recommendation systems, and various contemporary artificial intelligence applications. However, neural networks are frequently data-intensive and need many computational resources, especially if they are complex or used for more complex tasks. They can also be hard to understand if they make predictions that rely on numerous interdependent variables as opposed to a set of clearly-stated rules. They rely on the quality of training data, architecture, training algorithm and the metrics for evaluation. Neural networks are thus not necessarily the right solution for all problems. In the case of a smaller structured dataset, a simpler algorithm can yield competitive results without a ton of overhead complexity and resources. It is essential to choose an appropriate model for the task, not necessarily the popular technique.
Comparing Machine Learning Algorithms
Beginners will be able to select a reasonable starting point for a project with an understanding of the differences between these algorithms. Linear regression can be used to predict a numerical result and logistic regression can be used to predict the probability of being in a class. Random forests are an ensemble of decision trees for predicting stability and accuracy; they use branching rules to create predictions in decision trees. SVM learns to learn good class boundaries and k-means learns to learn good clusters without using labeled examples. Neural networks generate complex representations by making use of layers of interconnected computational blocks and can be trained on a wide variety of problems. These descriptions have been included to emphasize the main goal of each algorithm but should not be interpreted as hard and fast rules. There are algorithms that can be used for multiple operations, and they may have dramatically different performance based on the data, implementation, and training configuration. The same approach that has worked well in one organization can be ineffective in another, even when the two organizations are from similar industries or have comparable goals.
| Algorithm | Main learning approach | Typical task | Example application | Main limitation |
| Linear regression | Supervised learning | Regression | Predicting house prices | May not be able to identify or explain complex nonlinear relationships |
| Logistic regression | Supervised learning | Classification | Identifying spam or regular emails | May require some extra features for complicated patterns |
| Decision trees | Supervised learning | Classification and regression | Assessing loan applications | May overfit on the training data |
| Random forests | Supervised learning | Classification and regression | Identifying suspicious transactions | Less accurate than a single tree |
| Support vector machines | Supervised learning | Classification and regression | Categorizing documents | May be costly in large scale data sets |
| K-means clustering | Unsupervised learning | Clustering | Using purchasing behaviour as a grouping attribute | Needs a selected amount of clusters |
| Neural networks | Typically directed but also in other learning modalities | Classification, regression and other tasks | The identification of objects in pictures | May need significant data and computing resources |
The table below is just a starting point because selecting an algorithm isn’t simply a matter of what kind of prediction you need. When choosing an algorithm, analysts should also take into account the number of observations available, quality of features, what the wrong predictions mean, whether interpretability is required, and the resources that can be dedicated to development and maintenance. If they had a relatively small property set and small business, they may start out with linear regression and then compare that with a random forest. Before using a spam filter, an email service can try logistic regression, decision trees, and other classification models. A retailer interested in understanding customers’ behavior might apply k-means to find useful segments and investigate if the segments are informative for business decision making. Fitting appropriate models to the same data set well prepared facilitates the comparison of the models and gives an indication as to which model provides the best compromise of accuracy, efficiency, and explainability.
Selecting Appropriate Machine Learning Algorithm.
The first step in choosing the right algorithm is to understand the problem. When prediction involves a number, for example, the price a property will be sold for or the amount a customer is likely to spend, regression algorithms can be used. Classification algorithms are more relevant if the task is to classify observations into known categories, like emails to classify or to predict whether a customer will cancel a service or not. If the categories are not known and the task is to identify natural grouping, clustering methods, like k-means, could be helpful. These differences help reduce the set of available models prior to model training. It is also critical to know what the data is. The number of observations, the types of features, whether there are missing values, whether the classes are balanced or not, and whether there are noisy or biased measurements can all affect which algorithms will be likely to work well.
Another key factor is predictability versus interpretability. In a context where decisions need to be explained, a simple regression model or a small decision tree may be better than a more complex model, although it may be slightly less accurate. Neural networks can also be suitable for certain applications, like large-scale image recognition, where they can learn representations of complex visual content that simpler methods are not able to effectively represent. Other factors that the analyst should take into account are computational expense, training time, time for prediction, and effort needed to keep the model going after deployment. Beginners should set up a simple baseline, explore some feasible alternatives and use the validation set to get an idea of how well each model will work on new examples. It is better to use a disciplined comparison process than popularity or reputation to choose an algorithm.
Train, Evaluate and Improve Machine Learning Models
Once you have a grasp of an algorithm, you need to have a grasp of a useful machine learning system. The model should also be trained with appropriate data and rigorously tested to see if it can make predictions on untrained data. Usual practice is to split the data set into training, validation, and test sets. The training set is used for fitting the model, the validation set is used for comparing approaches and tuning model parameters, and the test set is used for evaluating the model after making decisions for development. The number of data examples that are available and the type of task to be performed will determine the procedure, but the overall idea is to not use only the examples that the model has been trained on. A model may make accurate predictions on the data it was trained on, but fail to make good predictions when it encounters new data, especially if the data it has been trained on is not representative of the data in the real world or if the model has been overfitted.
The metric for evaluating the performance should be a direct consequence of the problem being solved. For regression, a measure of the difference between the predicted numerical values and the actual values can be used such as mean absolute error or root mean squared error. The appropriate accuracy measure to use on classification models is determined by the consequences of the different types of errors and the balance between classes, and may be different than those listed above. In the case of fraud detection, for instance, accuracy alone might not be informative if the fraudulent transactions are very uncommon, since a model could correctly identify most legitimate transactions while failing to identify many of the fraudulent ones. Clustering calls for different kinds of evaluation as there might be no known correct labels to which to compare the clusters. In all these tasks, it’s important to avoid data leakage. Leakage is the leakage of information that, if it was to be included at prediction time, is not an appropriate part of the problem that is being modeled or evaluated. To create models that provide value outside of the development process, it’s important to work with data carefully, the appropriate metrics and honest testing.
Conclusion
Machine learning algorithms offer various approaches to learning from data, pattern recognition, and prediction. Linear regression is used to estimate numerical values, logistic regression to estimate probabilities and make classifications. Random forests use multiple decision trees to produce more stable predictions than do single decision trees. Support vector machines can be trained to form separating boundaries between classes, while k-means clustering can be used to group unlabelled data and neural networks can be trained to recognize complex patterns in large numbers of applications. Both methods have their advantages, as well as their disadvantages and there is no single algorithm that works for every circumstance. By knowing these differences, students, aspiring data analysts, and others with little to no experience in the field will have a practical basis for delving into machine learning concepts without having to learn complex math first.
This understanding will be best developed if the concepts are related to experimental work. A novice could train a linear regression model to predict house prices, train a logistic regression model to classify spam emails, create a decision tree to explore the patterns in loan approvals, or use k-means on a customer data set. These methods can be compared on appropriate data sets to illustrate observation of how the assumptions relate to performance and the importance of evaluating models. As their experience expands, students can discover more sophisticated methods, enhance their data handling abilities, and delve into the practical application and supervision of machine learning systems in real-world environments. The objective is not just to be able to name the algorithms but also to know the type of problems they are used to solve, the evidence on which to assess the outputs of these algorithms, and the constraints that should be taken into account before using the outputs of these algorithms to make decisions.