Introduction to Natural Language Processing
Natural Language Processing (NLP) refers to a subfield of artificial intelligence (AI) that involves the computer processing, analysing, interpreting, and generating human language. It is used in numerous applications in the real world, such as chatbots, virtual assistants, search engines, machine translation systems, spam filters for emails, and text summarisation programs. For instance, when someone requests directions from a virtual assistant or uses a translation service to translate a foreign-language message, NLP aids the system in deciphering the text and providing a helpful reply. The advent of machine learning, deep learning, and large language models has greatly enhanced a computer’s capacity to handle language tasks.
However, human language is more complicated than a collection of words and grammatical rules. Humour, culture, shared experience and implied meaning are ways people convey information, many times in an indirect manner. Whilst modern NLP systems can see patterns and generate fluent responses, they do not always understand language as humans do. These constraints are relevant to understand as more and more people turn to NLP technologies in the field of education, healthcare, business, customer service and more where accurate communication is a critical need.
Constraints of NLP
Although NLP has proven successful, there are a number of technical and linguistic issues that can impact computer-generated interpretation, including accuracy and reliability. People constantly update their language, and the same spoken word may have a different meaning for different people, in different circumstances, or when in the midst of a conversation. These variations will have to be recognised by computers via algorithms and patterns learned from training data, which do not necessarily represent all possible interpretations. The ability to generate language models is now improved with the addition of contextual representations, attention mechanisms, and scales in training data, but not every issue has been solved.
Knowing the limitations of NLP can help to explain why a system might give an incorrect translation, miss a sarcastic comment, or come up with an answer that sounds convincing, but is factually inaccurate. It is not a single weakness that causes these challenges. They, on the contrary, are the consequence of the interplay between language complexity, a lack of information, computational limitations, and the challenges of capturing human knowledge in mathematical systems. By exploring the main issues, it becomes easier to appreciate the limitations of NLP, and the areas where human judgment is still required.
Ambiguity in Human Language
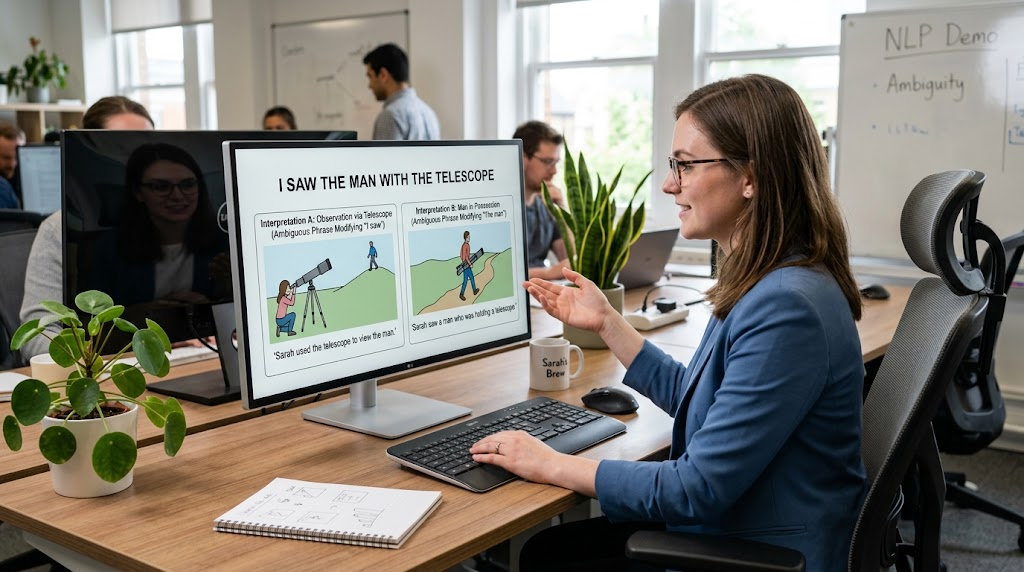
Natural Language Processing is plagued by one of the main problems which is Ambiguity, where words and sentences can have multiple meanings. The surrounding words and context in which a sentence is used will need to be studied by a computer to determine which interpretation is feasible. The sentence ‘I saw the man with the telescope’ can mean two different things, for instance. The speaker may have been using a telescope to view the man or the man may have been using a telescope. The sentence is grammatically valid in either interpretation, but cannot be used to determine which one is correct.
Certain words can take on multiple definitions, depending on the context in which they are used. The word Bank” can mean a financial institution or the bank of a river. The word “light” can mean brightness or lack of weight. There are models of modern NLP that take the context into consideration, but if the context is incomplete, errors can still occur. This is very hard to do when a sentence is brief or poorly organized, or when it is spoken during a conversation without the prior conversation. Thus, an NLP system can choose a logical interpretation, but it doesn’t necessarily match the speaker’s meaning.
Trouble with Sarcasm/Irony
Another problem is sarcasm and irony, as what is meant by a statement may vary from what is actually said. When people are disappointed, critical, amusing, or frustrated they may use sarcasm, which is a form of irony. For instance, if it is raining heavily when someone comes to our school, he or she might have to say, “What beautiful weather we are having!” Although the words appear positive, the speaker may actually be complaining about the rain. A conventional sentiment analysis system could see the sentence as positive since it identifies words like “wonderful” and “wonderful weather” as being expressions of approval.
A more sophisticated system can take into account what is going on around it, but can still misinterpret what is being said if there are missing key context elements. Sarcasm is also different in each community, which makes it hard to have a universal set of rules that will work in all contexts. Several things can affect interpretation, such as punctuation, emojis, facial expressions, tone of voice and shared experiences. These extra signals are not yet available for all text-only NLP systems. When a positive phrase might actually mean negative and is interpreted as such, it can impact social media analysis, customer feedback classification, online moderation, and automated response, particularly.
Idiom, Metaphor and Figurative Language
Idioms, metaphors and phrases that have meanings that are not clear from the literal translation of the individual words are often used in human communication. An idiom is a phrase with a prescribed meaning that is not what the words in it would normally mean. The meaning of break the ice, as in “to ease tension” or “to make people feel more at ease when they first meet” is an example of a common idiom. Literally, it would be wrong to think that someone is actually breaking the ice. The meaning of the phrase “spill the beans” is likewise to spread information that was once kept secret, but not to throw beans on the floor.
Their meaning is created by linguistic conventions and context: These expressions pose challenges to NLP systems. Similar problems are created with metaphors. The expression ‘time is money’ is used to make a point about the value of time, but not to equate it with money. While many common idioms can be identified by modern language models, new, invented, and local expressions may not be familiar to a model. Figurative language is especially difficult if the following words have a literal and an idiomatic meaning. Interpretation will be correct based on the context and purpose of the conversation.
Regional Expressions, Slang and Cultural Context
Language is different by region, age, profession and social community. Individuals communicate the same concept using various words, spellings, phrases and/or grammatical constructions. Such variations pose problems for NLP applications that are mostly trained to handle only one or more common variations in the language. For instance, in the Nigerian Pidgin “How far?” can be used to greet someone, which is akin to asking how he or she is doing, not how far away. Similarly, in some contexts, the expression ‘I’m coming’ can mean that someone is about to come back, depending on the local context.
An unknown system might misinterpret or translate an expression. Cultural understanding also impacts interpretation of greetings, jokes, respectful language, indirect requests, and mentions of local events. What you say that may seem polite to some may sound offensive to others. These can escalate into more severe issues if NLP applications are used to analyse public opinion, moderate online discussions, or provide customer support from various areas. Reliable systems must be built with a variety of training documents, in consultation with local language users and across communities, not solely based on a single model of language.
Challenges of Multilingual Text Processing
With the trend of people crossing national, cultural, and linguistic boundaries, multilingual communication has become more and more frequent. But it is still challenging for NLP systems to accurately process multiple languages. There are variations in grammar, word usage, sentence construction, writing systems and the expression of meaning in the various languages. A model that is accurate in English might not be as accurate in French, Hausa, Yoruba, Igbo or other languages, especially if they are under-represented in the training set. Many languages also have complex word structures, such that a single word can convey information that can be expressed in multiple words in English.
Any translations of the text should be aware of these differences and preserve key information. Another challenge is code switching, switching languages in a conversation or sentence. In one case, a person who speaks Nigerian may use a mixture of English and Yoruba or Nigerian Pidgin when using the Internet with friends of the same ethnic group. If the system needs to consistently interpret each sentence in one language, it can misinterpret words or translate awkwardly. For low-resource languages, research emphasizes the need for improved datasets, language-specific tools and evaluation metrics for enabling improved multilingual NLP. They are crucial to making sure that language technology serves people in communities where languages are under-represented in digital resources.
Spelling Errors, Informal Writing, and Unstructured Text
Spelling and grammatical errors, abbreviations and informal writing is common in the NLP systems like in social media posts, text messages, online reviews, user generated content etc. Common errors may result in a change of meaning or make a word difficult to recognise, although some models can correct these errors. A missing word, for instance, “form” for “from” or a missing space or punctuation mark will cause a grammatical issue, which can then lead to a different interpretation of the sentence. People also use abbreviations like “LOL”, “BTW”, “IDK” as well as repeated letters and shortened words, and emojis. The emphasis of the message can be conveyed in informal spelling, which may not be picked up in a system that normalises the message without taking into account its tone.
When using voice recognition systems to transcribe speech into text, accent, background noise, and differences in pronunciation or unfamiliar names can cause errors in the transcription process. These problems may occur in further processing of language. If the first transcription or misspelling is incorrect, a sentiment analysis tool, translation system or chatbot can generate a response that is based on that incorrect information. Reliable NLP thus needs techniques for dealing with noisy text while retaining the meaning and style of communication.
Small Data Sets and Underrepresented Languages
The training data will contain language patterns that the NLP system is designed to learn, therefore the quality, size and diversity of the training data will have a significant effect on the performance of the NLP system. Creating useful datasets can involve gathering a large amount of text, cleaning the text of errors, anonymizing personal data, and having data reviewed and labelled accurately by human annotators. The activities will require time, money and expertise. In some languages and in some areas of study, there are many digital resources and in other languages and subject areas, digital resources are few. This imbalance presents greater challenges when creating accurate tools for less common languages, specialised professions, or communities whose communication is not well represented online.
An NLP system might be effective for interpreting formal English news text, but less successful with Nigerian Pidgin conversations or with special terminology in a particular local industry. Limited data may also make it challenging to identify less common names, dialects, and expressions. Data scarcity is recognized as a crucial challenge in the development of NLP, especially in low-resource languages where it might be difficult to find high-quality annotated examples and standardised language resources. Current research is focused on transfer learning, data augmentation, multi-lingual training, and community data collection. However, these methods are not a substitute for representative, reliable and ethically gathered language data.
Representation of the Environment
A major drawback of NLP is that its training content may contain stereotypes, social or historical inequalities of training. If the model is trained with skewed examples, then it can replicate or reinforce the patterns in its predictions and generated responses. For example, if the training data of a recruitment system is based on past discriminatory hiring practices, the system could have a bias for certain groups. Likewise, a text classification system might be misapplied to assign aggressive or unprofessional labels to some dialects, if those language varieties are not represented in the training set or are labeled negatively in the training set. Bias can come from the data source, the method of data sampling, how the examples were labelled by human reviewers, or the aims of the training of the model.
It can also have varying effects on different languages; this could mean that a given system might be very accurate for one community but less so for another. They are hard to eradicate, because fairness is subjective and is related to the use of the technology and the social setting involved and the people it will affect. Researchers can mitigate risk by reviewing data for imbalances, testing performance on various demographic and linguistic subgroups, engage a diverse cohort of reviewers and conduct monitoring after deployment. But doing away with obvious stereotypes in training data does not mean it’s fair. If any decision made by a NLP is automated, such decisions must be evaluated and held accountable, especially for responsible NLP development.
Concerns about Privacy and Data Protection.
Another crucial point is privacy, as NLP systems may handle text with personal, confidential or sensitive data. Names, contact info, financial information, or private experiences might be part of emails, customer service chats, medical records, school records, or workplace messages. Lack of proper safeguards means that this information could make it possible for someone to misuse it, access it without permission, or accidentally disclose it to another person. Additionally, because of how the model is trained and designed, a model trained on sensitive text can at times contain or produce information which should not be disclosed. Organisations need to therefore ask themselves the following questions regarding data collection: Have appropriate permission been granted by the users; How long will data be kept; Who will have access to it.
Even if names are removed, it is sometimes not sufficient to protect the identity, as a few details can be linked together to identify a person. Some methods for addressing privacy concerns include data minimisation, access controls, anonymisation, secure data storage, and data techniques that reduce the learnings and disclosure that a model can make with respect to a particular record. These protections can add technical complexity and can impact on model performance and/or model development costs. Current research in privacy-preserving NLP still investigates possible ways in which systems can provide valuable language services without incurring risks for the processing of personal data.
Difficulty Understanding Implied Meaning and Context
Often ideas are communicated indirectly and listeners are expected to draw conclusions from the commonality of knowledge, previous discussions, social norms, and the context. This is a skill that is crucial as many requests, warnings, jokes and complaints are not explicit in their meaning. For instance, the person who says “It’s cold in here” may mean that the temperature is cold or may be telling another person to close a window. What is meant by “correct” interpretation depends on the situation. Likewise, if a manager says to an employee, “You might want to check those numbers again,” it might be a polite way of saying that he or she is concerned about a possible mistake. It is possible that an NLP system will recognize the literal meaning, while not understanding the interpretation of the request or criticism.
The problem of correlation is another contextual one, as the system needs to know what is being referred to by a pronoun. The sentence “Mary spoke to Grace after she finished the report” could leave the reader to wonder who finished the report, Mary or Grace. For many such instances, modern models can be used to determine the correct answer by using surrounding text, however, when the information is ambiguous or incomplete, there are always errors. There are a number of such restrictions that show that there is more to the understanding of language than identifying words and grammatical structures. It also involves thinking about relationships, intentions, mutual knowledge and the contexts for communication.
Incorrect Answers and Misinterpretations
In particular, modern NLP systems, such as generative language models, can generate coherent answers that may be incorrect, or include misleading elements. Even if some of the claims in a response are unsupported, outdated or incorrect, the response can sound confident and well organised. This is considered a “hallucination” issue in generative AI. For instance, if prompted with a scientific explanation, a chatbot can give the right general answer but fabricate a research paper or get a fact wrong. A translation system could also generate a sentence which sounds natural but alters the meaning of the original speaker. Errors can occur when a model is presented with questions it doesn’t know, contexts are missing, information that contradicts the model, or patterns that allow it to make up a plausible continuation without checking all of its statements.
This risk is significant in certain sectors like healthcare, law, education, or finance, where individuals might depend on automated responses to make consequential decisions. Users should thus differentiate a well written answer from verified. These risks can be mitigated by ensuring reliable information retrieval, specialized evaluation of information, estimation of uncertainty, user review, and information guiding the user to reliable information sources. However, no single technique is guaranteed to be 100% accurate. NLP applications must clearly state their limitations and important decisions should not be based entirely on unverified interpretations made by the machine.
High Computational Costs and Resource Requirements
Advanced NLP systems may need significant computing power to develop and run. The training of large language models is a complex task that requires significant computational resources and specialized hardware, and can take a long time to complete. When deployed, these systems also need computing power to process requests, generate responses and to service many users at the same time. These expenses may involve hardware, power, data storage, technical personnel, maintenance and infrastructure. Smaller organisations, schools, researchers and businesses may not be able to develop or implement advanced NLP applications on their own due to these requirements. The computational needs can also impact accessibility in areas with limited internet access, power reserves and low cost computing.
While smaller models and effective training methods can make these requirements more manageable, there is a possibility of compromises in accuracy, versatility, or the extent of tasks a system can process. Organisations should therefore think about the need for an intricate model for a specific job or even if a smaller, specialised solution would be more useful. Reducing resource requirements through efficient algorithms, model compression, quantisation and parameter-efficient fine-tuning are some of the techniques. Environmental aspects such as impacts of computing infrastructure and trade-offs of performance versus financial and environmental costs are also part of responsible development.
Limited Transparency and Challenges with Assessing Performance
Another difficulty in NLP is understanding why a system is going to make a prediction or respond in a certain way. There are two types of systems: Explicit Rules(inspectable) and Complex Networks(number of parameters). They tend to have complex internal calculations even if their outputs are simple to read. In the case of a mistaken categorization of a customer complaint, for instance, developers may find it difficult to determine which words, contextual patterns or training examples may have been wrong. This poses challenges to debugging, accountability and trust. Evaluation is also difficult as the outcome of the performance is influenced by the task being evaluated. A model can be accurate on a benchmark set of messages, but fail on a real-world set of messages with slang, misspellings, regional expressions or unfamiliar topics.
The automated metrics may not reflect the cultural meaning in the translation, or that a generated response is truly useful. Therefore, researchers employ several assessment approaches such as task-based assessment, human assessment, adversarial examples and cross-group and cross-language performance comparisons. Transparent reporting is significant as it gives end-users a clear idea of the areas that are performing well and where the outcomes of a system need to be verified. It is important to test for impressive benchmark results, otherwise the same results can lead to false expectations for how well an NLP system will perform in real-world scenarios.
Ways to Improve Natural Language Processing Systems
NLP is not without its flaws, but researchers and developers are searching for viable solutions to make NLP more accurate, fair, and useful. An important step is to create a variety of good training datasets that cover various languages, dialects, communication styles, and topics. Having local language experts and community voices involved can help developers recognize terms and culture that may be missed by AI systems. A different way of assessing models is being assessed with realistic examples and not just with the standardised benchmarks. Ambiguous, sarcastic, code switching, informal spelling and other challenging language patterns should be assessed. Another interesting avenue of research is the integration of language models with reliable information retrieval systems, allowing for a combination of language learning and retrieval of relevant documents.
The role of human oversight is important when errors may have major repercussions, and privacy protection measures and bias evaluations should be integrated during the development of the complex. Other smaller, more efficient models are being explored as well that can cut down on the computational cost and bring language technology to the masses. These techniques can enhance performance but may not be of service depending on the application and the available resources. There is a need for computer scientists, linguists, ethicists, domain experts and language communities to work together to continue to move forward and to make sure that NLP systems do not only optimize the technical aspects of the work, but also actual communication requirements.
Conclusion
The advent of Natural Language Processing has revolutionized the ability of computers to understand and interact with human language, making it possible to power everything from translation tools to virtual assistants, sentiment analysis, search engines, and generative AI. But there are some great restrictions because humans are not very clear, can say sarcastic things, use idioms and regionalisms, know a lot of culture, and have the ability to convey meaning without words. NLP systems additionally have challenges resulting from spelling mistakes, restricted training dataset, imbalanced data per language, prejudices, privacy hazards, computational expenses, and wrong answers generated. These are problems that illustrate that a satisfactory system in one language, in one situation, may generate an inadequate system in another.
Solutions to them must go beyond the creation of bigger models. It includes data quality management, diversity of community representation, personal information security, system evaluation, and human supervision. While no doubt NLP will have more applications to come, it is important to measure the effectiveness of its applications in a realistic way. In understanding the advantages and disadvantages of natural language technology, organisations and individuals can employ such systems responsibly. In the long-term, NLP tools need to be accurate, fair, secure, efficient, and accessible, but should also recognize the need for reliable communication to be sensitive to context, culture, and human intention.