
The hash table is a type of data structure that is widely used in computer science and is one of the most significant ones in the field of modern computer programming for its ability to store, organize, and retrieve information efficiently. A hash table is used to retrieve information from the table later on, rather than searching through all of the table’s items one by one, as in a list or a tree.A hash table uses a technique called hashing to determine where information can be stored and retrieved later in the table.
This technique is very convenient to use for programs which require many searches, insertions, updates, and deletions. They are employed in the background of many familiar programming constructs such as dictionaries, maps, caches, symbol tables and database systems. Knowing about hash tables also helps beginning programmers to appreciate why some programs can find information in what seems to be a matter of a wink. Through understanding the interaction of keys, values, hash functions, collisions and collision resolution, programmers can gain a better understanding of data structures and the reason hash-based structures are so commonly used.
What is a Hash Table?
A hash table is a data structure that stores information in the form of key-value pairs. A key is a unique identifier or reference to find a specific piece of information, and the value is the data that is related to the key. An app that manages students, for instance, could have a key of a student identification number, and a value of the student’s name. The program can utilize the key to locate where the corresponding value is found in the student record, rather than scanning all the student records for a student name every time a name is requested. This means that in many cases searching is much more efficient. Most hash tables use an underlying array or other form of storage space, but have an associated hashing function that maps keys into indices of that space. The ability to look into them directly and to have a proper structure for storing them is the magic of hash tables and the reason they are such a valuable programming tool.
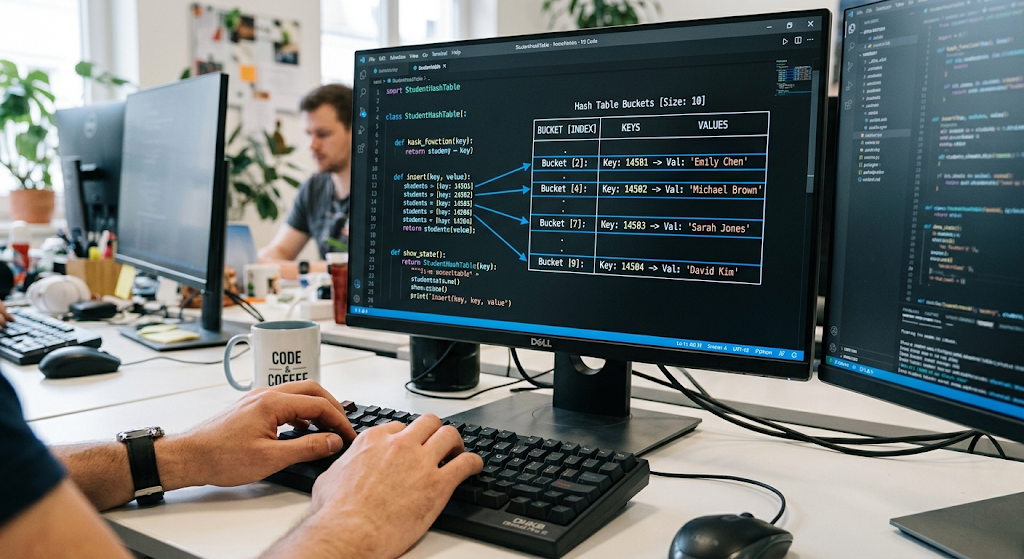
The basic concept of a hash table is to map a key to an index which points to a suitable storage location. This transformation is done by a hash function that takes a key as the input and returns a number (hash value). The value is then used by the table, typically in some calculation to match the size of the table, to decide where to store the related value. If the same key is provided again later in the sequence, it can be used again to determine the expected location of the key in the hash table. The program can then access directly to a small part of the table rather than accessing each stored item. In the best case scenario, insertion, search, and deletion operations can be carried out in constant average time, O(1). The actual performance will depend on the hash function, table design and number of collisions.
How Hashing Works
The act of mapping a key into a numeric value suitable for determining a location of storage. The function that does this is known as a hash function. A hash function takes information, like a string or number, or a key, and operates on it using a specified algorithm. This is known as the hash value or hash code. The hash value is often modified to be a valid table index because a hash table typically has only a finite number of storage locations. In a simple system, for instance, a hash value might be computed, and then the remainder be taken to get one of several possible locations. In practice, hash functions are usually more complex as they need to distribute the keys well and minimize patterns leading to too many collisions.
A good hash function must be efficient and quick enough not to cause a substantial performance penalty and should distribute keys over the positions in the table as uniformly as possible. Many keys may be used for the same few rows, creating long chains or congested rows in the table, which slows down searches. A hash function is one that strives to distribute ordinary input values around a table, as opposed to collocating them in a few regions. A hash function should also be consistent: that is, if a key is processed two times under the same conditions, it should obtain the same hash result each time. This consistency means that the value of a key can be found later in the program, as the key will return to the same approximate value expected in the program. Therefore, hashing is used to associate the human-readable key with a machine-oriented storage position.
Understanding Key-Value Pairs
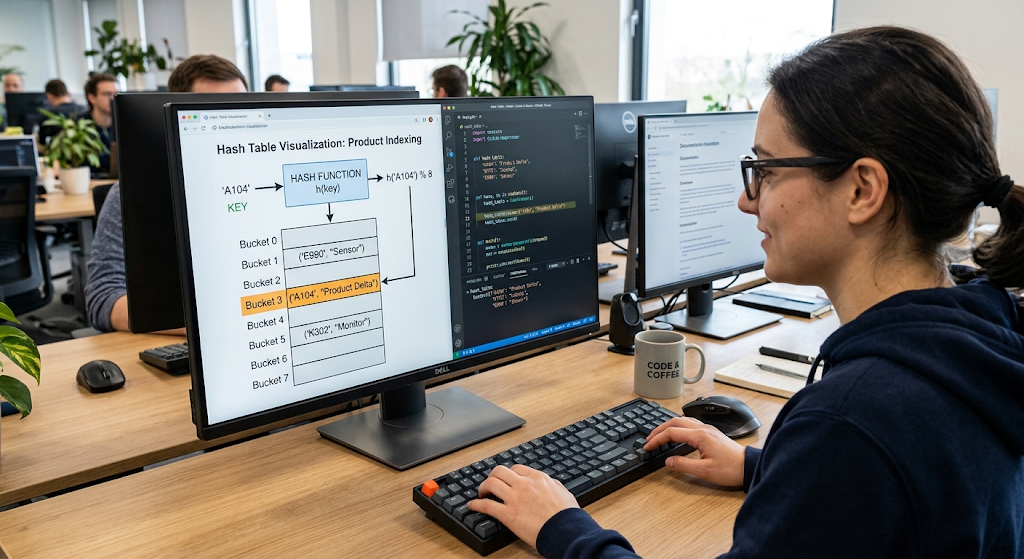
Many hash tables are represented in terms of key-value pairs. The key is the name/label of the item, and the value is the information stored on the item. Think about a simple application which maintains product information. The key might be a product code and the value could be the product name, price or other field in the record. If the program requires to know the information for a specific product, it provides the code for the product and it carries out the hashing process to obtain the value of it. This way of identifying information is distinct from the information itself, so that programs can use meaningful identifiers, rather than having to keep track of the physical storage locations. Keys may be unique in a specific table because if multiple values had multiple keys, there would be no way to determine which value is being retrieved.
The reason why key-value storage is useful is that it is very similar to many of the requirements of the real world when it comes to programming. Many applications require a relationship between two sets of information, e.g., a username to an account record, product code to product details, word to word definition, or even domain name to cached response. Such relationships can be naturally represented using a hash table. Built-in dictionary or map types are constructed by implementing hash-table techniques internally in many programming languages to allow extremely fast access to a value by a key. The programmer doesn’t need to control the hashing process, since the programming language does it for them. However, if you know what is going on under the hood, it is easier to comprehend the performance properties of such structures and select the right data structures to create larger applications.
Collisions and Hash Tables
A collision is when two different keys get the same table position when hashing. Collisions are not a failure of hash function; it’s a normal thing in hash-table operation. This is because a hash table will typically have a limited number of slots and the size of the key space will be very large. For instance, a table may have a limited number of available positions, and many millions of possible strings as keys. There are lots of keys, but not enough positions; some keys have to be mapped to the same position. The key question then is not how to prevent collisions entirely (the answer to which is usually “no way”) but rather how to manage them efficiently so that the table is useful. Effective hash-table implementations combine effective hash function with collision-resolution.
How many and where collisions occur can make a big impact on performance. If the collisions are not frequent and are distributed across the table, the operations can be kept near their expected average performance. If lots of keys are mapping to the same places, however, it may take the program to perform more comparisons to determine which key to track. If the hashtable is not designed well, it can even perform like a linear search structure, and time will be O(n). That’s why things like the quality of the hash function, the size of the tables, and the load factor are important. If the table is designed properly, it will be able to track the table’s size and can adjust it as needed. The system will keep the distribution of entries appropriate so as to minimize the impact of collisions and to ensure the system has good average performance.
Collision-Resolution Techniques
Separate Chaining
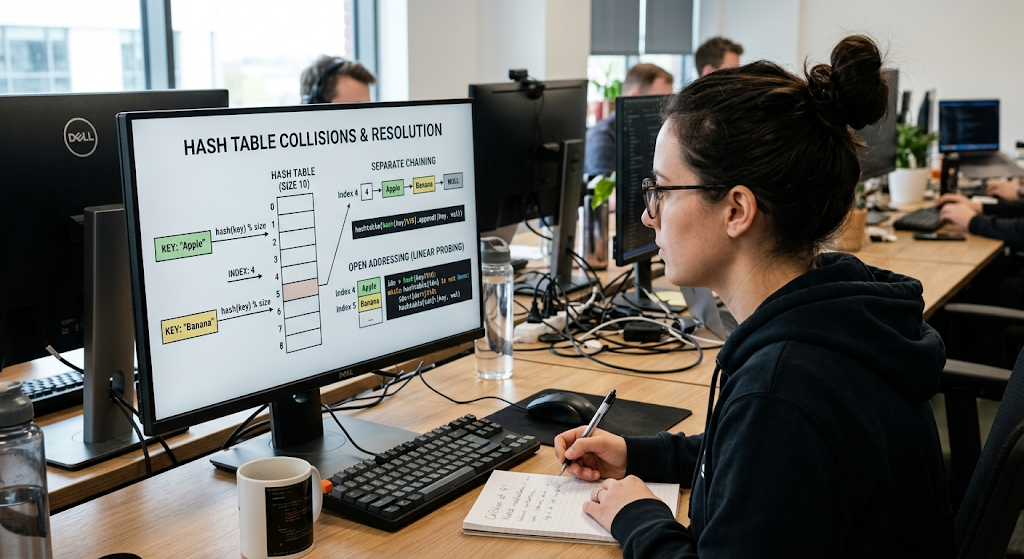
One of the most popular techniques for collision resolution is separate chaining. In such cases, each of the entries in the hash table may be a set of entries instead of just an entry. If multiple keys have the same index, the corresponding key-value pairs are clustered together at that index and are typically linked together into a linked list or another appropriate data structure. The program that does a search operation uses the key to compute its index, and then it looks at the entries at that index to see if it finds the matching key. These collections are relatively small if the hash function distributes the keys so that the size of the collection stays relatively small. Therefore collisions could happen and the extra time to search for the proper value could be manageable. The concept of separate chaining is simple and flexible since the number of entries that may be associated with one position in one table can increase, thus creating space for the new entries.
The primary benefit of separate chaining is that it reduces the complexity of handling collisions, and allows more entries to be stored in the table than there are array locations. The extra structures for the chains, though, do use memory, and searches can be slowed if too many entries end up at the same location. Therefore, the quality of the hash function is still significant. The program will have to check numerous entries when trying to retrieve a key if a large number of keys are in a single chain. The structure of the chain may be more complex than the simple linked list in a real implementation, depending on the programming language used. Though there are some differences, the underlying concept is still the same: more than one key can be stored in the same position, and the key can be checked for correctness to find the appropriate value.
Open Addressing
Open addressing stores entries within the hash table, rather than at separate collections per position, to deal with collisions differently. In case of a collision, another position is looked for using a prescribed probing algorithm. One example of linear probing is when the program scans through the next positions until it finds an appropriate empty position. Quadratic probing addresses some of the clustering problems by employing a different sequence of locations, and double hashing addresses the clustering problems by employing another hash function to calculate the probing sequence. If the program is looking for an existing key, it will use the same probing process to find the key it is searching for. Open addressing can be used to make efficient use of memory, since there are no separate linked structures to store, but it needs to be carefully managed to ensure that the table is not full with empty and deleted positions.
The load factor, especially, is also important in open addressing as the table must have space for new additions, as well as for efficient probing. The more items that are inserted, the more times it will take to find an empty location, thus increasing the amount of time needed to insert and possibly search. Implementations can thus attempt to resize tables before it becomes too full. Another factor that impacts the efficiency of entry distribution is the probing technique and the table size itself. While an open-addressing structure can provide good cache performance when the related entries are all in one array-like structure it is highly dependent on implementation specifics. It is important to understand this technique so that programmers realize that collision handling is not a fixed procedure, but rather different designs involve different compromises in memory usage, speed, complexity, and how the table behaves as the number of elements stored in it increases.
The Load Factor
The load factor is a ratio of the number of elements in a hash map to the capacity of the hash map. The idea of it can normally be settled as the variety of entries stored in the table divided by the number of positions in the table. The load factor is the ratio of the number of elements in a table to the number of positions in the table. If a table has 100 positions and 70 elements filled, the load factor is 0.70. It is significant because if the table is full, there are likely to be more collisions or longer probing sequences.
Therefore, some operations which are usually fast can take more work. Many hash-table implementations have a limit on how large the hash-table can grow. The entries may have to be rehashed during resizing as the hash values can alter the position of the entries when the capacity of the table is changed. While resizing may need to be done with extra effort, it can aid in keeping things running smoothly as data storage grows.
Hash Tables, Dictionaries, and Maps
The Hash Table is a closely related data structure to dictionaries and maps, as both are mainly used to store key-value pairs. A dictionary enables a program to link keys to values, and to retrieve a value from the dictionary given its key. A map is another type of abstraction, and the name and behavior of a map will vary depending on the programming language. Many implementations use hash tables under these structures, due to their efficient average-case insertion, lookup, and deletion. However, a conceptual interface is the dictionary or map, and a hash table is one way to implement that interface. A map might be implemented as a hash table, a balanced tree or other data structure, depending on the needs of the program. It is important to note this distinction so that the programmer can know that an abstract data type is a description of what a structure does, while its implementation is a description of how the operations are performed.
The first time that a beginner meets hash-table concepts in a practical programming context, they are likely to be in a dictionary or map. A programmer can design a dictionary that holds pairs of names and phone numbers, and fetch a phone number from the dictionary by giving a name. The language takes care of hashing, collision resolution, resizing, and storing. This convenience enables the programmer to concentrate on the application and not have to write out the data structure. However, hash-table principles still have an impact on the behavior of the dictionary. The understanding of these principles can help to understand why key lookup is typically quick and why keys should be equipped for the suitable equality and hashing qualities and why altering a key following it was inserted can bring about surprising issues in some programming environments.
Significance of Hash Tables in Software Development.
In many software applications, quick access to data according to an identifier is required, for this reason, hash tables are very popular. In some cases, such as specific types of indexing and in the internal operation of a database, hashing can be employed. Key-value relationships are also used widely in caching systems as a cached item could be linked to a key that represents either a request, a resource, or some identifier. If the same key is used again, the application can check to see if the data for that key is already in the cache. This can decrease the number of costly calculations that need to be repeated or information that must be accessed from slower storage. The other application of hash based structures is in compilers, interpreters, operating systems, web applications, and programming language runtimes as the systems often need to be able to link identifiers to information rapidly.
A hash table is particularly good when the operation that is most important is to find a value from a given key. For instance, a web application might have a list of session data with a session ID being the key. Variable names could be mapped to values or meta data in a programming language implementation. A cache might be able to remember the results of a request from a different identifier. The program may not have to look at all of the records stored in each case. Rather, hashing offers an approach to restrict search to an anticipated site. This is only one of the reasons why hash tables are still significant in the modern software world, even with the growth of its size and complexity. They offer a practical compromise between speed, memory requirements and the flexibility of implementation for a wide variety of applications.
Hash Tables in Databases and Caches
Because there is so much data in databases, it’s important to have efficient data access. Database systems may use hashing for various indexing, partitioning and lookup applications where equality operations are frequently encountered. A hashing strategy is used to find the location of records that contain information that matches the information in a given record, rather than scanning each record to find matching information. For queries that are looking for a record with an exact key, hash-based techniques can be especially beneficial as they may not be sorting or looking up within a range. There are numerous approaches to database systems, however, and a hash-based solution could not be used for all types of queries. This depends on the data, workload, query patterns and storage architecture, and how the database is implemented.
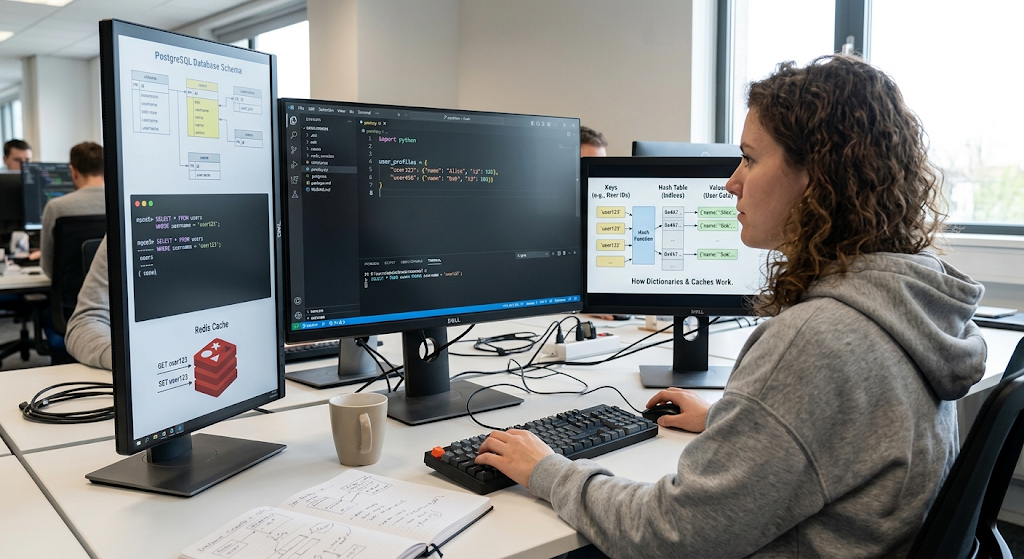
Another obvious example of hash-table principles is found in caching. A cache stores information that is likely to be needed again and it provides an application with quicker access. A key can be attached to each cached item, such as a URL, request identifier, query representation or object identifier. When a new request comes in, the system can compute or check the appropriate key and see if it has a result stored in the cache. If it does, then the application can potentially skip the other more costly operation needed to create or retrieve the information again. This is a pattern that is well suited to hash tables, which offer quick average case access via key. Efficient caching can prevent repeated tasks in large-scale applications, leading to better responsiveness, as well as reducing the strain on databases, external services, or computational resources.
Pros and Cons of Hash Tables
The great thing about hash tables is that they have an average-case runtime of O(1). If an appropriate hash function and appropriate table management are used, searching, adding and removing entries can be accomplished in O(1) average time. Key-value relationships are also easily supported by hash tables, and are useful in applications that need to access data based on a key. Depending on the implementation and the programming language they can store various kinds of keys and values. They are also widely supported in modern programming languages, so that it is easy for programmers to use them without having to implement their own hashing. These attributes can make hash tables a useful tool in programs of any size, including large software systems dealing with considerable amounts of information.
There are some drawbacks of hash tables which programmers should be aware of. The operations do not necessarily have to be O(1) in all cases, as collisions and bad hash distribution can slow these operations. Hash tables are generally used to efficiently find an element that is equal to an element in the hash table, not to store the elements in sorted order. Other structures may be better suited for applications that often must retrieve a value between two numbers or must scan the same entries in sorted order. Memory can also be consumed due to placing a certain amount of spare memory to efficiently support operation of tables and due to some collision-resolution techniques requiring extra memory. These restrictions should not make hash tables ineffective; rather, they illustrate what should be considered when selecting a data structure for a program, as opposed to just using the structure with the fastest average lookup time.
When to Use a Hash Table?
A hash table is a good option for the program that must store a key/value association and frequently access an element based on the element’s key. These can be username to user record, product identifiers to product information, words to their definitions, or cache keys to cache results. Hash tables are especially useful if the application does not need to keep the data sorted, and if the average case performance is more important than performing the operation in an ordered manner.
They can also be helpful when the number of records is variable over time as many can automatically resize to accommodate new records. However, before implementing a hash table, the programmer should determine if the program must have data in order, be able to search for a range of data, expect worst-case performance or any other special property that might be better achieved by another data structure.
Conclusion
Hash tables are a great method for storing and accessing data with key-value pairs. They are effective because they use a method called hashing to convert keys into values, which are then used to determine the position to store them. The function is designed to map keys to a table, and collision resolution methods like separate chaining and open addressing can accommodate multiple keys if the hash function maps them to the same position.
The performance is dependent on the load factor, the size of the table and the quality of the hash function. The basic concepts of hash tables also underlie a variety of other key-value stores, such as dictionaries, maps, caches, and more, that have become common in contemporary software. Beginners will be able to appreciate the reasons why hash tables are so popular, and be able to choose data structures for practical applications and programming projects with greater knowledge.

Good post! We will be linking to this particularly great post on our site. Keep up the great writing