Picking the appropriate data structure is what a great deal of a programmer’s success is based on as the structure in which information is organized will very much determine how well a program performs in storage, search, update, and processing. At the start, beginners learn arrays, linked lists, stacks, queues, trees, hash tables and graphs as separate entities and put time into memorizing what they do and how well they perform. But in reality what is asked of you in coding problems is to recognize what structure best applies to a given situation.
A program may require for elements to be accessed super quick, lots of insertions and deletions, a certain order to things, efficient search functions, little memory use, or the ability to present complex relationships. Also what is best may change based on what the application is. Thus it is not about which is in general faster but what works best for that which you are programming. By this method of thought the transition is from rote memorization of data structures to analysis of problems, identification of constraints, trade off between different models and to choose what is practical as the volume of data grows.
Start with the Issue at Hand
Before choosing a data structure for a program’s data, first study what the program is going to do. Also it is a greenhorn error to go in for a structure too soon, perhaps out of habit which brings up arrays or which associates hash tables with fast search. A better way is to put down the key actions and which ones will take place most often. Ask if the application is mostly for reading present values, adding new ones, deleting some, searching for certain items, keeping a certain order, or representing between object relationships.
Also it is good to estimate the amount of data the application will have to work with and if that will change greatly. For instance a set of ten values may not require the same level of optimization as a system that has millions of records. By identifying the main operations and constraints first a programmer is able to go through many options logically instead of into which they fall just because they are familiar.
Identify the Most Important Operations
The primary functions of a data structure include access, search, insertion, deletion, and traversal. Access looks at how well a program does in retrieving an element whose position is known. Search looks at the efficiency of finding an element by its value or key. Insertion and deletion determine the ease at which information is added or removed without creating a great deal of extra work. Traversal is how the program goes through elements in order or as they relate to each other.
These operations may have very different performance results based on the data structure. An array for example gives easy indexed access, but a linked list may do better in terms of certain insertions and deletions when the related node is known. Thus a programmer should not ask which data structure is the fastest, but what are the main operations that this particular application requires? That shift in focus is one of the bases of practical data structure choice.
Consider Access Speed
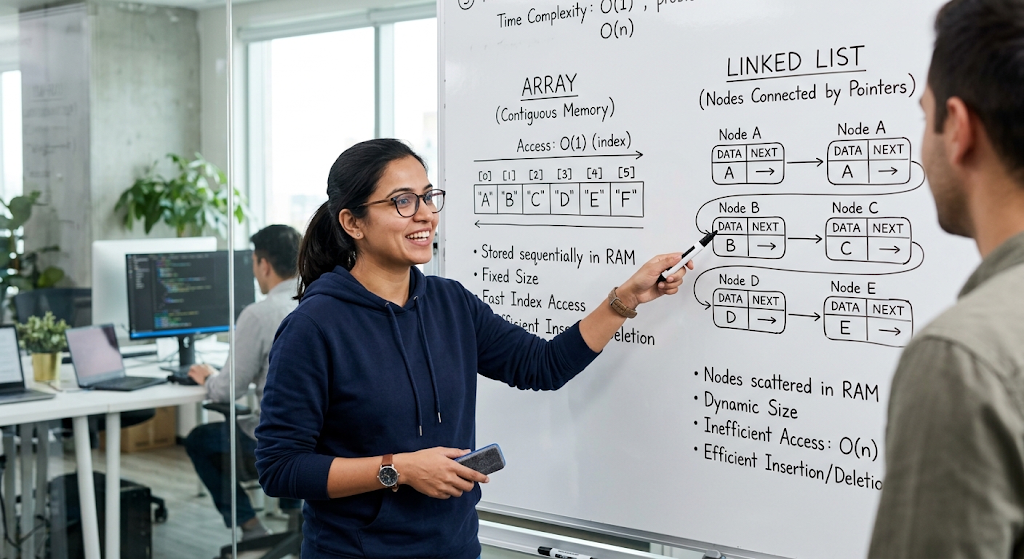
Access time is of great importance in a program which is to frequently access an element at a known position. Arrays do so well in these situations as they store elements in a sequential indexed structure which in turn allows programs to go right to that element’s index. Take into account the application which logs the daily temperature for the entire month and at the same time requires the data for a specific day to be accessed often. In that case if the data set is presented by means of an array the code may simply use the correct index for the needed value that is what makes arrays such a good choice in a scenario where you have pre determined which element you will need.
Also it is in arrays’ favor when there is little to no structural change in the data set. That said, do not assume that any and all which require fast access must use arrays. It is best to also look at how the other functions such as insertions, deletions, memory usage, sorting and search play out as by improving one aspect of performance you may end up degrading another.
When an Array Makes Sense
An array is a good choice when the number of elements is for the most part determined and the program is to access items by position often. Take for example a student record system which puts in storage report card marks for a class. If the program is to go back to and get out a known mark, or go through and process all the marks in a row, an array is a simple way to go about it. Also we see arrays used for things like image pixels, numbers, sets of unchanging config values, and data tables.
Their basic structure may also make programs easier to maintain and understand which in turn makes them a better option. That said, putting in a new element in the middle of an array may cause other elements to shift, also taking out an element may cause the same issue. Thus a go to choose an array is not; it is best when it fits the main actions of the problem at hand.
Insertion and Deletion Requirements
Insertion and removal of elements in the middle of a set can greatly change what data structure is best to use. In a program that is always adding new items and deleting old ones from a collection, an array may prove to be a poor choice because as old elements are deleted, the order of the remaining elements must be shifted. A linked list on the other hand approaches the issue by having elements which are nodes that are put together and not each item has to be put in a fixed position in memory. If a program has a reference to the right node, in and of itself that is enough to insert or remove a node which in turn means that the whole sequence does not have to be shifted.
This feature makes linked lists a good choice for when the application requires a lot of changes. At the same time though linked lists do not give the same easy access of indexed elements that arrays do. To get to a certain element in a certain position may require going through all the previous elements. Thus the right choice between the two depends on if the application values the flexibility of constant change over the quick access to elements at a given position.
When a Linked List Makes Sense
In our consideration is a program which has a collection that sees a lot of action in terms of elements being added to or removed from the set and also which goes through the collection from one element to the at which point the linked list is a good option. Also note that each node in a linked list contains data and a reference to the next node. Think of an application which is tracking a sequence of tasks that may at any time have new tasks added in or old ones removed from known points in the task chain. Also if the program already has a reference to the affected node then it is more a matter of changing the node’s links as opposed to shifting many array elements.
Also, linked lists are the building blocks of other data structures and are a great way to think about dynamic collections. At the same time though they do bring in extra memory use for the node references and in general provide a less fast access to elements by position as compared to arrays. The point is not that linked lists are better than arrays but that they present a very good solution when what you are doing is a lot of insertions and deletions and not so much direct indexed access.
Searching and Key-Based Retrieval
In many cases search requirements play a large role in data-structure choice. If a program is to do a great deal of look up which uses a unique key, a structure which does key based retrieval may be the best choice as opposed to a simple sequential collection. A hash table puts info out in a way which may provide a very efficient average case look up if a good hashing and implementation strategy is used. For example think of an app which has customer info which is identified by customer IDs.
If the program is to get an ID and in return get the related customer info record that goes with it very often, a hash table may be a good choice because the key is used to determine the location of the associated value. This is also different from going through a regular list one element at a time. What is important thus is not just the amount of data which exists but how the application requests that data and whether it is by position, key, order, or relationship.

When a Hash Table Makes Sense
A hash table is a great fit for which you require frequent key based lookups. Dictionaries, caches, symbol tables, and structures which associate one entity with another can also benefit from this. For example a programming language’s interpreter may put in association variable names with info related to those variables at the same time a web app may associate session IDs with stored session data. In these cases what is usually of import is not “What is the third item? ” but rather “What info related to this key do we have? .
Hash tables also may provide very efficient average performance for look up, insert and delete operations which of course is weather dependent upon the quality of the hash function, issues of collision, table size and also the implementation details. Also it does not by design provide for ordered storage of elements. Thus if your application requires keys to be in a certain order or you are going to be often wanting to get at the next or previous key, then another data structure may be a better fit.
Ordering Requirements
Ordering is an aspect which is often left out in the comparison of data structures by programmers. Some uses of data structures are for just storage and retrieval of values and that is fine, while other use cases require the maintenance of a specific order. If the program is of a nature which requires info to stay in a sorted form a data structure which supports that may be a better fit than one which is based on hashing. For instance, think of a that which puts in exam results and very often has to bring up values in ascending order, find the smallest or largest value, or go through records as they fall in a sorted set.
Trees are a good choice for this kind of requirement as some tree structures do a great job of putting values in order. The main issue is that the application has to determine if order is an issue. If order does not play a role and what is mainly done is look up via a key, a hash table may be the natural choice. If you are doing sorted travel and range queries a tree may provide what a hash table does not.
When a Tree Makes Sense
Trees play a key role in which data has a hierarchy or order. For instance a binary search tree will put values in according to comparison relationships, also we have other tree structures which are meant to be balanced or which support special storage and search requirements. Take a file system for example which has folders that contain files and more folders. A tree is the perfect model for this hierarchy as each folder has sub elements which fall below it.
Also we see trees in search engines, databases, parsers and many other applications which require that data be organized hierarchically. But “tree” is a very broad term which includes many different types of structures which perform quite differently. A badly balanced search tree may perform very differently from a well balanced one. Thus programmers must determine the specific features and performance they require instead of thinking that all trees perform the same.

Stack: Push Down Systems
A stack is best used when what you have is a last-in, first-out situation. In this case the most recent element goes out first. We see this play out in many programming uses. In a browser for instance you are going back to previously visited pages which are in reverse order of what you came in which is LIFO. Also a program may use a stack to put in actions that can be easily reversed.
Also function calls into a program follow this structure, the most recent function called is the one that finishes first. If what you have is best described as the last thing put in is the first out, a stack is what you should use. It is also important to note that a stack is not always the best or only choice just because it is a great data structure. In fact stacks can be built using different bases. What does matter is that the stack fits the access that the application needs.
Practical Stack Example
In a similar way think of an editor which has the feature of undoing recent actions. As each action takes place it is put onto a stack. When the user asks to undo the most recent action that is at the top of the stack is removed and the action is reversed. As another change is made it is put on the stack and becomes the next action in the undo queue. This model is put forth as a simple solution which mirrors the application’s behavior exactly.
Also a stack may be used when determining if symbols in an expression are properly nested, in the processing of certain recursive algorithms, and in managing sequences in which the last item is of primary interest. We see that what we do is identify behavioral patterns in applications. When an app in fact says “do the newest item first” a stack is a very clear model which also in turn will prevent programmers from having to create custom solutions to the same problem.
Queues: First in First Out Processing.
Queues are meant for first in first out (FIFO) operation. The very first item that was added is the one which gets processed first which is also what we see in real world queues. We see this in action in print queues, customer support request systems, task schedulers and network processing pipelines which all tend to handle what comes in in the order it was presented. Take for instance a print server which is sending out documents from many users.
If the documents go into a queue they get processed in that order instead of the print server having to go through and find each one which may not be in any particular order. Also in algorithms like breadth first search the order in which we go through pending nodes is a key element to how the algorithm performs. As a programmer chooses a queue for a given application they should look at if strict order of arrival is required, if there is a need for priority handling and if the system needs other features like the ability to remove items from either end.
Practical Queue Example
Imagine a scenario where a customer support system is getting requests from users. In most cases when requests are to be handled in the order of their arrival, a queue is a very suitable data structure. New requests go to the end of the queue and the next to be processed is the one at the front. As the volume of requests increases the system may scale without the programmer having to constantly reorganize the entire set.
Also we see queues in use in operating systems for scheduling, in asynchronous processing, event handling and communication systems. But should some tasks have to be done before others no matter the time of their arrival a basic queue may not do. In these situations a priority queue or some other data structure may be what is required. As always the choice is based on what the application requires, not what is most popular.
Graphs: Relationships and Networks
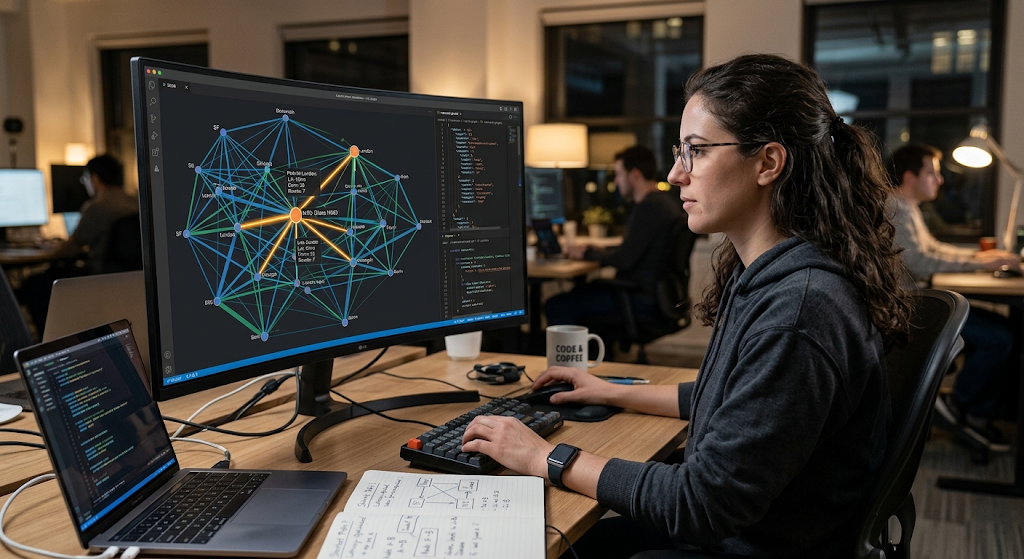
Graphs are used when what you have is a set of relationships which is the main issue. As opposed to arrays and linked lists which do a great job with sequences, graphs are great for many to many connections. In a graph you have vertices which stand in for entities and edges which represent the relationships between them. We see graphs used in social networks, road systems, communication networks, recommendation systems, dependency relationships and many other applications. Take a navigation app for example.
You can put in vertex places and as edges the roads which connect them. If the program is to find routes, determine connectivity, or look at relationships between places a graph is a very natural fit. In terms of which to use, the graph should be a fit for the problem at hand. If you have mostly stand alone data which is in a sequence form a graph may add in unneeded complexity. But if relationships are what you are working with, putting that info into a simple list may cause your program to be hard to design and perform poorly.
Practical Graph Example
Cities and stations may be used as vertices while roads and routes as edges. In some cases edges may also have weights that represent distance, cost, time or some other measure. Thus graphs are very flexible in what complex systems they are able to model which in many instances put into focus the relationship between elements as much as the elements themselves.
What we learn is that programmers should identify in their problems which elements have meaningful relationships. If they do then a graph may present a better representation of the issue than to try and maintain many separate lists and to at the same time manually update relationships between them.
Arrays: Making Choices
Memory issues are a great point as we scale up the amount of data. We see that different data structures do not only put in the actual values but also sometimes they include extra info for organization which may not be relevant. Arrays put elements in a tight sequence which is great for compact storage, on the other hand linked structures use pointers between nodes. Hash tables may allocate extra space for buckets and to reduce collisions and trees require pointers between related nodes. Also we see that these structures which may be great for organization still have different memory footprints which will play a role at scale.
Producers should thus pay attention to what may look like a great feature in terms of what it does for the data but also the memory hit that comes with it. A structure may have a great feature set but still be a bad choice if at the expected scale it runs out of memory. Also memory should not be looked at in isolation from performance, some memory heavy techniques may be used to gain in speed which is also a key factor to consider.
Scalability
A data structure that does very well for a small dataset may not scale at all as the dataset grows. What we mean by scalability is how the chosen data structure and its operations perform as the number of elements goes up by large amounts. For example, a search in an unsorted array may work fine when you only have a few records, but doing the same search in that array as the number of records grows into the millions will not scale. Also a design which involves a lot of element movement may work at small scales but will become very expensive as the set grows.
Thus it is important for programmers to put into play realistic data sets and operation frequencies before they choose a structure. Also think about the growth of your data. A set which today has 100 elements may tomorrow have millions. To go with today’s data only is to set yourself up for a redesign in the future. A good data-structure choice is to predict what the real future needs will be without adding in growth which is not going to happen at all which just adds unneeded complexity.
Decision Making Process: Performance Against Simplicity
Performance is a factor but it is not the only thing to look at. A more complex data structure may add more to the programming experience like extra levels of debug issues, memory issues and what is out there to go wrong in the long term. Also if two choices perform well enough for the task at hand the simpler one is probably better for a dev team to use and understand. In case of a small set which is fixed for example an array works fine, that’s when you use a simple array over a complex specialized design element that may not even improve a function that doesn’t require that kind of performance.
But in large scale data sets or for processes that run in the millions a difference in performance may be seen which at that point may make the added complexity worth it. Also what good programmers do is they look at what is required technically and also what is practical in the real world. We are not talking about using the most advanced data structure out there but to use the right one that has a balance of what it brings to the table and what it costs in terms of all aspects.
A Practical Decision-Making Process
A repeatable decision process which in turn makes data-structure selection easier. First off describe what the program is to store and what it is to do with that info. Then put forth the main operations which are performed and which are performance critical. Determine if direct indexed access is a requirement, how often elements will be added or removed, if data has to be in order, if look up is to be done via unique keys, and if the relationship between objects is a key element of the issue at hand.
Also look at memory constraints, expected size of the data set and how fast the data may grow. Once you have narrowed down your choices, look at the performance features and the implementation complexity. In the end, test the chosen approach with real world work loads instead of depending on theoretical performance alone. This process puts programmers to think in terms of requirements as opposed to recall of rules and also brings to light that each data structure is a set of tradeoffs.
Example: Designing the Structure of a Solution for Different Problems
Consider many different applications together. In some which have to store a set of monthly sales figures a solution like an array may work well as they present a clear sequence which is best checked positionally or in sequence. Also for a program that’s constantly putting in and out of certain spots but isn’t doing so at random a linked list is a good idea, at that point when you are not worried about indexed access. An app going from user names to account info will do best with a hash table which is key based. A model of a folder structure and its subfolders does naturally see the use of a tree for that is a hierarchy.
An undo function can use a stack we put in in reverse we take out. A task which has requests come in in a certain order and are processed in that same order does well with a queue. Also a route planning or social network app will see use in a graph because of the entities and their connections. We see from these that there is no one best data structure out there. What you choose comes out of what the application is doing, how the info relates, if there is a need for a certain order, memory issues, and the size of the application.
Common Mistakes to Avoid
A hash table does very well with key based retrieval, but for an app which needs sorted traversal you may need a different strategy. Also it is important that programmers do not fall into the habit of thinking that theory completely tells the story.
In practice constant factors, memory access patterns, implementation quality, size of the input set, and how often certain operations are performed can play large roles. Therefore it is a good idea to test out and measure performance once the basic design has been picked out.
Conclusion
Choosing which data structure to use is a form of problem solving. Sure, arrays are great for fast access but linked lists do a better job at flexible updates, hash tables excel in average case key look up, trees are for that hierarchical or ordered info, stacks are last in first out which is great for some, queues are first in first out which is perfect for others, and graphs for relationship representation. We don’t have to memorize that, what we should do is understand what each has to offer in different situations. Start with what the application needs from you, which operations are the most important, what is the access and search like you will be doing, what is the insert and delete like, is there a certain order or memory requirement, also look at how the data set will scale.
Once you do that, do a pros and cons analysis of what is out there and pick the one that best plays to the problem at hand. With practice what goes into that data structure choice is less about memorizing separate definitions and more into analyzing the issues at hand, looking ahead at what tradeoffs you will have to make, and in the end creating programs that grow with the changing requirements and still remain easy to understand.