Introduction
Search and sort algorithms are fundamental in computer programming. They allow people to search for specific information in an application. Whether the customer is searching online for a certain item, a teacher is searching for a student’s academic history or a database is searching to find information out of thousands of records, search and sort algorithms allow this to happen. Knowing how these algorithms operate is an important aspect to learning programming or building software. Search algorithms can be used to search for specific information.
Sort algorithms can sort information into a specific format (ascending/descending). Some popular search/sort algorithms are linear search, binary search, bubble sort, insertion sort, selection sort, merge sort and quick sort. Each search/sort algorithm has a different way of searching through data and will have advantages and disadvantages. Knowing how insertion sort works can give you a good basis to understand how information is processed by algorithms and how as a developer you can choose the right solution. As applications start to hold more information the importance of performance increases.
Search Algorithms
Search algorithms are techniques used to search for specific information. This determines if a specific value exists and where it is located or what information is associated with it. Almost every type of software will use search techniques to search for information. In an online shopping application searching techniques could be used to search for a specific item based on its name, category, ID or price.
A school management system could use search algorithms to search through student records to find information based on student admission numbers or names. The performance of a search algorithm depends on factors such as how much data there is, if the information is sorted and how it searches through the information. Two of the most commonly studied search algorithms are linear search and binary search.
- Linear Search Algorithm
Linear search is one of the simplest searching algorithms. It goes through each item of data until the required value is found. It starts off by comparing the first element with the value you are searching for. If it matches then the search ends and the position is returned. If it doesn’t match the next element is compared. This continues until the required information is found.
Linear search doesn’t require the data to be sorted so is useful when there isn’t much data or the data isn’t sorted. For example, an online shopping application could have a list of products that aren’t sorted by their ID. If a customer was searching for an item with an ID of 105 then the application will go through each product until the correct ID is found. However this can become inefficient if there is a large amount of data.
How Linear Search Works
Linear search works by taking in a list of elements and the value you want to search for. It then compares the first element with your target value. If they match then the position is returned. If they don’t match, the next element is compared. This continues until the value is found.
For example, if there was a list of student exam results [45, 67, 82, 59, 91] and you were searching for 82, the algorithm will compare 45, then 67 and finally 82. As the third element matches the value you are searching for the algorithm will stop after making 3 comparisons. This is useful when there is a small amount of data or if it isn’t sorted.
Time Complexity of Linear Search
The performance of linear search can be seen by how many comparisons take place as the amount of data increases. In the best case scenario the value you are searching for is the first value in the list so only one comparison is made. This means the best case time complexity is O(1). In the average case scenario the value could be around the middle of the list so about half the data will be searched.
This means the average case time complexity is O(n) where n is the number of elements. In the worst case scenario the value is the last element or there isn’t any value. This means all the elements will be searched. The worst case time complexity is O(n). Whilst this isn’t always the fastest option for large datasets, this is a simple algorithm and can handle unsorted data so is a good option for many situations.
- Binary Search Algorithm
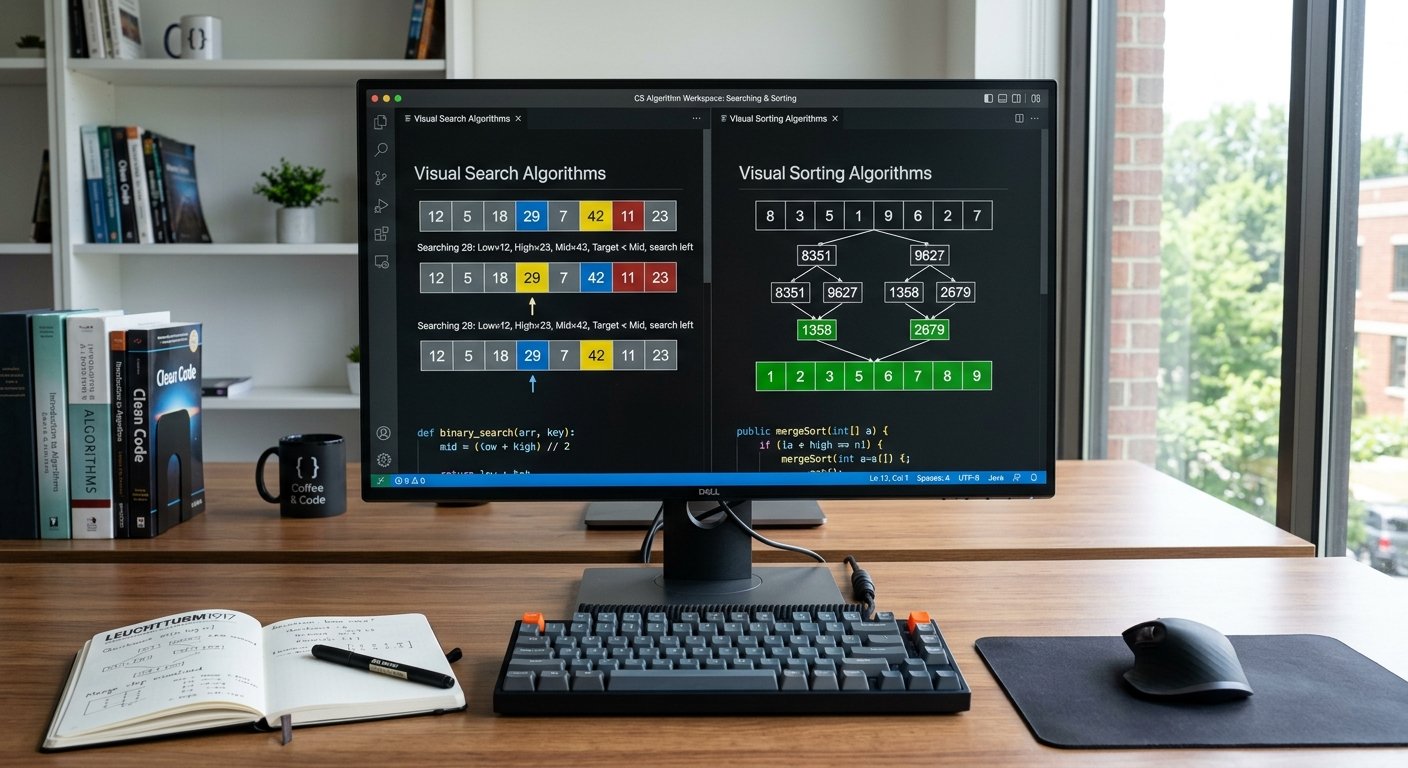
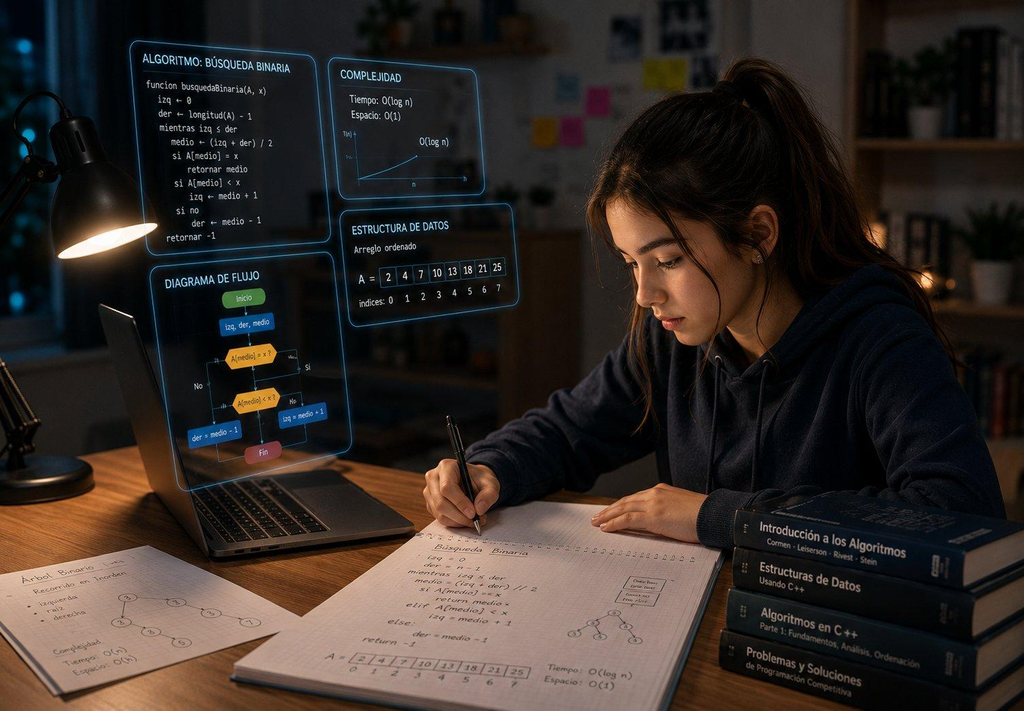
Binary search is a more efficient search algorithm. The algorithm works by splitting the sorted data in half repeatedly until the required information is found. The middle element is compared to the value you are searching for. If it matches then the search is complete. If the value is smaller then the left half of the data is searched. If it is larger then the right half is searched.
By comparing the values, half of the data is eliminated each time. This means fewer operations are needed to find the element. The data must be sorted before this can be done. For example, an online shopping application may have product IDs in ascending order. Using binary search the application can quickly find the product they are looking for. Rather than searching through hundreds/thousands of records, it will narrow down the data until it finds the product.
How Binary Search Works
Binary search works by having two boundaries to indicate what part of the data you are searching through. These are often referred to as the low and high positions. The algorithm calculates the middle position and compares this value with the target. If they match then the middle position is returned. If the value is smaller the high position is set to one less than the middle position. If the value is larger the low position is set to one more than the middle position.
This continues until the value is found or the boundaries cross meaning it doesn’t exist. For example, if there was a list of student admission numbers [101, 105, 109, 113, 117, 121, 125, 129]. If the program was searching for 121, the middle value will be checked. The correct half of data will then be searched. This means binary search is much faster than linear search when searching through large sets of sorted data.
Time Complexity of Binary Search
Binary search is a very efficient algorithm. Each time a comparison is made, half of the data is removed. In the best case scenario the value will be in the middle on the first comparison. This means the best case time complexity is O(1). Both the average and worst case time complexity are O(log n) where n is the number of elements. As the data increases in size the number of comparisons increases slowly. For example, if there are around a million elements of sorted data, in the worst case scenario you will only make around 20 comparisons.
This means binary search is a useful technique to use when frequently searching for information in large sets of ordered data. However, the initial cost of organising the data and keeping it organised as new records are added can be a problem. If the data is constantly changing then another search technique may be more practical.
Sort Algorithms
Sort algorithms are techniques used to sort data. This puts the information in order (ascending, descending, alphabetical, etc). Sorting is important as many applications will have a large amount of information. An online shopping application may sort products by price, customer rating, popularity or date released. A school management application may sort student records alphabetically or sort exam results from highest to lowest.
Sorting can also help with other operations such as searching, analysing data, creating reports and finding information. Different sort algorithms have different ways of sorting data and will vary in performance. Some are simple but will become inefficient with larger sets of data. Others use more advanced techniques to improve performance. Some popular examples are bubble sort, insertion sort, selection sort, merge sort and quick sort.
- Bubble Sort Algorithm
Bubble sort is a simple way to sort data. It compares adjacent elements and swaps them if they are in the wrong order. The algorithm starts at the first element and compares it to the next element. If the first value is larger than the second value (as we are sorting in ascending order) then they will be swapped. This continues until the end of the data. After a full pass through the data the largest unsorted value will be at the end of the list.
For example, if there was a list of product prices [450, 200, 600, 150], the algorithm will compare adjacent prices and swap them if the previous value is larger than the next. After a few passes through the data the prices will be [150, 200, 450, 600]. This algorithm is easy to understand but will involve many comparisons and swaps when dealing with large datasets. This means it is usually only used for educational purposes or very small sets of data.
How Bubble Sort Works
Bubble sort works by going through the data multiple times until it is in the right order. During each pass the algorithm will compare adjacent values and swap them if they aren’t in the right order. When sorting in ascending order if a larger value comes before a smaller value it will be moved to the right. After the first pass the largest value will be at the end of the list.
The algorithm will then continue to go through the unsorted data. This will continue until the data is fully sorted or an optimised version detects that no swaps are needed. For example, if a school application needed to sort student exam results in ascending order [70, 45, 90, 60], the algorithm will compare 70 and 45 and swap them. This will continue until the data becomes [45, 60, 70, 90].
Time Complexity of Bubble Sort
Bubble sort has a worst and average case time complexity of O(n 2 ). This is because the algorithm may need to go through the data many times to sort all the elements correctly. The best case time complexity can be O(n) if an optimised version of the algorithm is used. This uses a swap flag to detect if the data is already sorted so no swaps are needed.
If this isn’t used then the algorithm may still make unnecessary passes. The algorithm will have a space complexity of O(1) as it sorts the data in place. Whilst this isn’t the best option for large datasets, it is a useful algorithm to introduce beginners to comparisons, swapping, loops and sorting. Knowing the limitations of this algorithm will help programmers realise why more advanced algorithms are needed when dealing with large amounts of information.
- Insertion Sort Algorithm
Insertion sort is a simple way to sort data. It works by taking one element at a time and inserting it in the correct position within the sorted data. This works similar to how you would sort playing cards in your hand. You pick up one card and insert it in the correct place. The algorithm starts off by assuming the first element is sorted. It then takes the next element and compares it to the sorted data.
Any elements larger than the selected value will be moved one place to the right. The selected value will then be placed in the correct position. For example, a school management system could use insertion sort to sort a small set of exam results. If new records are being added one at a time then this algorithm could be useful as each new value can be inserted into the sorted data. This algorithm is simple to understand and is useful for small or almost sorted datasets.
How Insertion Sort Works
Insertion sort works by selecting a value, comparing it, moving values and inserting it into the correct position. The algorithm will start at the second element and assume this is the key value. It will compare this value to the elements before it. If any of the previous elements are larger they will be moved one place to the right. This will continue until the correct position is found.
The key will then be inserted into the free space. This will continue until the next element is reached. For example, if there was a list of student scores [60, 35, 80, 45, 70]. The algorithm will assume 60 is sorted. 35 will then be inserted before 60. 80 will come after the values as it is larger. 45 will then be selected. The larger values will be moved to create space for 45. This will continue until the final list is [35, 45, 60, 70, 80]. This will increase the size of the sorted data.
Time Complexity of Insertion Sort
The performance of this algorithm will depend on how the original data is ordered. The best case time complexity is O(n). This is because if the data is already sorted then each new element will only need to be compared once to the previous value. The average and worst case time complexity is O(n 2 ). This is because elements may need to be compared and moved multiple times. If the data is randomly ordered or in descending order then this will occur.
The algorithm will have a space complexity of O(1) as it sorts the data in place. This algorithm is also stable if using the standard comparison condition. This means elements with the same value will keep their original order. This makes this algorithm useful for small datasets and almost sorted data. This algorithm can also be used in more advanced sorting implementations. As it is efficient at sorting small sections of data it can be useful.
- Selection Sort Algorithm
Selection sort is a comparison based algorithm that finds the smallest element in the unsorted data and moves it to the start of the unsorted data. The data will be split into two sections; sorted and unsorted. The sorted section will start off empty and all the elements will be in the unsorted section. The algorithm will search through the unsorted values and find the smallest. This value will then be swapped with the first unsorted value.
This will continue until all the elements have been moved into the sorted section. For example, an online shopping application may use selection sort to sort a small set of products by price starting with the cheapest. If the prices were [500, 200, 700, 300] then the algorithm would find 200 as the smallest value and move it to the start. It would then search through the rest of the values. This algorithm is easy to understand but isn’t the best option for large datasets.
How Selection Sort Works
Selection sort works by assuming the first value is the smallest. It will then compare this value to all the other values in the unsorted section. If a smaller value is found then the position of the smallest value will be updated. Once all the values have been checked the smallest value will be swapped with the first unsorted value. This position will now be sorted and the next position will be moved to. For example, if there was a list of product prices [80, 30, 60, 20, 50].
During the first pass the algorithm will find 20 as the smallest value and move it to the start. During the second pass it will search through the rest of the values and move 30 to the next position. This will continue until the prices become [20, 30, 50, 60, 80]. Unlike bubble sort this algorithm will generally only make one swap at the end of each pass. However most of the remaining values will still be checked.
Time Complexity of Selection Sort
This algorithm has a best, average and worst case time complexity of O(n 2 ). This is because the algorithm will have to check through the unsorted data to find the smallest value. Even if the original data was in the correct order the algorithm will still check through most of the data. During the first pass almost all the elements will be checked.
During the second pass one less element will be checked. This will continue until the data is sorted. This algorithm will have a space complexity of O(1) as it sorts the data in place. This can be useful if you need to keep the memory usage low and the dataset isn’t too large. This could also be considered if you wanted to reduce the number of swaps. This algorithm will generally make less swaps than bubble sort. However due to the quadratic running time this algorithm won’t be suitable when trying to sort very large product catalogues, student databases or other large sets of records.
- Merge Sort Algorithm
The merge sort algorithm is an efficient algorithm that uses the divide and conquer strategy. It works by splitting the original data set into smaller subsets until there is only one element per subset. As this is already sorted the algorithm then begins to combine them. The algorithm compares the first element of each subset and adds the smallest value into the new data set.
This continues until all subsets have been combined into one sorted set. An application that manages thousands of students’ exam data could use the merge sort algorithm to efficiently sort the exam scores. This is done by repeatedly splitting the exam scores into smaller subsets and then combining them. Merge sort works well with large amounts of data as it will always give predictable results.
How Merge Sort Works
Merge sort works by using two phases, splitting and merging. The split phase works by continually splitting the data set in two and repeating this until we have one element per set. The merge phase works by comparing adjacent sets and merging them in the correct order. We’ll take a look at an example of merging a set of product prices [40, 10, 70, 20, 60, 30, 50, 15].
The algorithm will split the set into smaller subsets. Once all subsets are split into individual values they will then be merged. The algorithm merges the subsets into larger and larger sorted sets. So 40 and 10 will be merged into [10, 40]. 70 and 20 will be merged into [20, 70]. These subsets will then be merged together to create the full set [10, 15, 20, 30, 40, 50, 60, 70]. This makes managing large data sets easier as we can manipulate smaller subsets.
Time Complexity of Merge Sort
Merge sort will always run in O(n log n) time, meaning it will have predictable results. This is because the data set is split into smaller subsets and then merged efficiently. The log n part of the algorithm represents how many times the data set can be split up. The n part represents how much work needs to be done to merge the values. Merge sort will typically use O(n) extra space when using arrays.
This makes merge sort more memory intensive than other algorithms like insertion sort or selection sort. However, the predictable nature makes it a valuable algorithm for large amounts of data. It is useful for external sorting. Merge sort is also useful for applications that need predictable sorting. Developers should bear in mind that merge sort will take up more memory.
- Quicksort Algorithm
The quicksort algorithm is another popular sorting algorithm. It works by selecting a pivot value. The remaining values are then ordered based on if they are larger or smaller than the pivot value. Values smaller than the pivot will be moved to one side of the data set. Larger values will be moved to the other side of the data set depending on how we split the data.
The algorithm then applies the same logic to each side of the data set until everything is sorted. For example, an online shopping application could quickly sort a set of product prices. If we have 70, 30, 90, 20, 50 we can select 50 as our pivot. This will allow us to separate our values. Quicksort is very popular due to having good average performance and not taking up too much extra memory.
How Quicksort Works
Quicksort works by selecting a pivot. This can be the first, last, middle or more complex value. The algorithm will then order the data set. Values smaller than the pivot will be moved to one side. Values larger than the pivot will be moved to the other side. The pivot will be placed in the correct position based on how we split the data. Then we will apply the algorithm to each side of the data set.
Using the exam scores [65, 40, 85, 25, 70, 50] and selecting 50 as our pivot, we will separate the values into two sets. One set containing values smaller than 50, and the other containing values larger than 50. Then we will individually sort each set until the full data set is sorted into [25, 40, 50, 65, 70, 85]. The effectiveness of quicksort will depend on how the pivot splits the data. Generally the more even the split the faster the algorithm will be.
Time Complexity of Quicksort
Quicksort will have an average time complexity of O(n log n). This makes quicksort very efficient for general sorting. The best case scenario for quicksort will be O(n log n). This is due to the pivot value always splitting the data set into fairly even sets. The worst case scenario for quicksort will be O(n²). This can happen if the pivot value always causes the data to be split unevenly. In some implementations this can happen if the pivot value is not suitable for the data as it is already sorted. Quicksort will typically have an average time complexity of O(log n).
This is due to the recursive calls used by the algorithm. The worst case scenario can be O(n). Unlike merge sort, many implementations of quicksort will sort the data in place. This means less extra array memory will be used. By carefully selecting the pivot value we can improve the performance of quicksort. By randomising the pivot value we can improve the performance. By using another sorting method for smaller subsets we can improve the performance. This makes quicksort a great choice for sorting large data sets.
Comparing Search and Sort Algorithms
Search and sort algorithms can be used for different purposes. Search algorithms are used to find specific values within data sets. Sort algorithms are used to order values. There are two common search algorithms; linear search and binary search. Popular sort algorithms are bubble sort, insertion sort, selection sort, merge sort and quicksort. The performance of each algorithm varies greatly depending on the amount of data, order of data and resources available.
For example, linear search would be a good choice for searching a small set of unsorted student data. Binary search would be a good choice for searching a large set of sorted admission numbers. Insertion sort may be a good choice for sorting a small set of nearly sorted prices. Merge sort or quicksort may be a good choice for larger data sets. By comparing the time and space complexity of each algorithm we can see which algorithm would be suitable for a problem.
- Time Complexity
Time complexity refers to how much work is completed by an algorithm. Big O is a common way of representing this. Constant time complexity means the algorithm will take roughly the same amount of time to run. Linear time complexity will grow in accordance with the number of elements. Logarithmic time complexity will grow much slower. Quadratic time complexity will generally get expensive when dealing with large data sets. Below is a table showing the common time complexity for the seven algorithms discussed in this article.
| Algorithm | Best Case | Average Case | Worst Case |
| Linear Search | O(1) | O(n) | O(n) |
| Binary Search | O(1) | O(log n) | O(log n) |
| Bubble Sort | O(n) | O(n²) | O(n²) |
| Insertion Sort | O(n) | O(n²) | O(n²) |
| Selection Sort | O(n²) | O(n²) | O(n²) |
| Merge Sort | O(n log n) | O(n log n) | O(n log n) |
| Quicksort | O(n log n) | O(n log n) | O(n²) |
Bubble sort will have a best case time complexity of O(n). This is because an optimised version can detect no swaps are needed.
- Space Complexity
Space complexity refers to how much extra memory is needed for the algorithm to run. This can be an important factor as some applications may be using devices with limited memory. Linear search, iterative binary search, bubble sort, insertion sort and selection sort will generally have a space complexity of O(1). This means they will use a small amount of extra memory. Merge sort will typically use O(n) extra memory when using arrays.
This is because temporary storage is needed. Quicksort will typically have a space complexity of O(log n). This is due to the recursive calls. However, the worst case scenario can be O(n). When choosing an algorithm to use you should take into account the time and memory usage. The fastest algorithm may not be the best choice for your particular application. An algorithm that performs well on a powerful server may not be the best choice if you are using a device with limited resources.
Real World Applications
Search and sort algorithms are used throughout modern software development. Many applications will need to search, sort and manipulate data. Let’s take a look at some real world examples. Online shopping applications may need to search for products using their ID. They may need to sort items based on customer preference. They may need to sort search results. School management applications may need to search for student data.
They may also need to sort exam scores. They may also need to sort student names into alphabetical order. Databases may also need to search and sort. Although many real world applications will use advanced data structures, indexing and sorting methods, the principles are related to the algorithms mentioned in this article. Understanding real world applications will help beginners understand how theoretical programming concepts affect real world software.
- Online Shopping
Many examples of search and sort algorithms can be found in online shopping applications. When a customer searches for a product using either the name or ID, the application will need to find the right products within the catalogue. Search algorithms will help find relevant records. Sort algorithms will sort the results based on price, popularity, customer ratings or newest items.
For example, if a customer searches for a smartphone they may want to see the cheapest smartphones first. The application will search for the right products and sort them by price. Customers may also want to see the highest rated products first. Although many shopping applications will use search engines, indexing and specialised ranking, understanding linear search, binary search, merge sort and quicksort will give a good foundation.
- Student Record Management
School management applications will use search and sort algorithms to manage student data. A school may have thousands of records containing admission numbers, names, exam scores, attendance and class information. Search algorithms will help find individual records. For example, linear search can be used to find a student within a small unsorted list. Binary search can be used to find an admission number within a properly sorted set.
Sort algorithms will help sort exam results, sort student names into alphabetical order and sort class rankings. A school may use insertion sort to sort a small set of scores. Or use merge sort to sort a much larger set. This makes it easier for the administrator to manage the data. It also shows how it is important for developers to understand how the data is organised when creating applications for schools, universities, training institutes and other education organisations.
- Database Management
Database management applications will deal with large amounts of data. It is important to be able to search for data. Many users will search for specific records using identifiers, names, dates, categories etc. Database indexing will help improve the search performance. Sort algorithms are also important as many database applications will need to return sorted information.
For example, an employee management database may need to return staff records sorted into alphabetical order. Or sort salary information from highest to lowest. SQL queries will often use the ORDER BY command to sort the returned records. Although databases will use specialised internal algorithms and data structures, understanding search and sort will give insight into how data is efficiently retrieved and sorted.
- Business and Inventory Management
Businesses need to manage their information accurately. Search algorithms will help employees find specific products, invoices, suppliers and customer accounts. Sort algorithms will allow inventory to be sorted into alphabetical order, quantity, price or expiry date. For example, a supermarket inventory application may show the products with the least stock first.
This will help employees know what needs to be restocked. A sales management application may sort transactions by date or amount. Often these applications will deal with dynamic data. Developers should consider how often records are added, removed or updated. Using the correct search and sort will help keep the application efficient.
Choosing the Correct Search or Sort Algorithm
There are many factors to consider when choosing the correct search or sort algorithm. You should not assume one algorithm will always be the best. Linear search would be a good choice for small or unsorted data. Binary search would be a better choice for sorted data.
Bubble sort and selection sort are easy to understand but are generally only useful for small data sets. Insertion sort would be useful for small or nearly sorted data. This is because it can be efficient if only a few elements need moving. Merge sort will have predictable performance (O(n log n)). However, it will need extra memory. Quicksort will have good average performance and often uses less extra memory.
- Consider the Size of Data
One of the most important things to consider when choosing an algorithm is how much data you have. An algorithm which works well with 10 records may not be efficient with millions of records. Simple algorithms like linear search and insertion sort may be sufficient for small data sets. However, larger data sets will generally need a more efficient algorithm.
Binary search will allow you to find values quickly within sorted data. Merge sort and quicksort will give better average performance for sorting. You should also consider how much the data will grow in the future. An application may start off with a few hundred products but eventually have thousands or millions of records. Choosing algorithms which can cope with more data will help avoid any performance issues.
- Consider if the Data is Sorted
How your data is organised can have a big impact on which algorithm you choose. Binary search will require the data to be sorted. If the data is already sorted you can use binary search to get fast results. If the data is nearly sorted insertion sort may be a good choice.
This is because it can sort the remaining out of place elements with little effort. If the data is unsorted linear search would be a good choice. You should also consider if it will be more efficient to keep the data sorted after each update. For example, an online store may receive many new products. Whereas a school may regularly search for records from a fairly static data set.
- Consider Memory and Performance
You should also consider how much memory you have available. Some algorithms will need extra memory to process the data. Merge sort will have predictable performance but will generally require extra memory proportional to the size of the data set. Quicksort will often perform well and will use less extra memory. However, it will still use memory due to the recursive calls.
Bubble sort, insertion sort and selection sort will generally use constant extra memory. However, they will have a quadratic running time which can get expensive. If you are dealing with millions of records you will need to balance the speed, memory and complexity. You should also test the algorithms with realistic data. The performance can vary depending on the data, programming language and implementation. It is better to actually measure the performance.
Common Mistakes Beginners Make When Learning Searching and Sorting
Beginners sometimes struggle with searching and sorting algorithms because they focus on memorizing definitions without understanding how the algorithms process individual elements. One common mistake is assuming that binary search can operate correctly on any collection, even when the data is unsorted. Another is confusing the purpose of searching algorithms with sorting algorithms or believing that both operations always have the same performance characteristics. Students may also overlook important differences between best-case, average-case, and worst-case time complexity.
For example, insertion sort performs well when the collection is already sorted, but its performance becomes less efficient when elements need to be shifted repeatedly. Quicksort can be very efficient on average, but poor pivot selection may lead to quadratic-time behaviour. Understanding these differences requires practicing with small examples, tracing each operation, and examining how the algorithms behave under different input conditions.
- Ignoring the Importance of Sorted Data
One of the most common mistakes when implementing binary search is forgetting that the collection must be sorted before the algorithm begins. Binary search decides which half of the collection to examine based on the relationship between the target and the middle value. If the elements are not correctly arranged, this decision may eliminate the section containing the required value.
As a result, the algorithm may return an incorrect result even when the target exists in the collection. Beginners should always verify the ordering of the data before applying binary search. If the collection is unsorted, they can use linear search or arrange the information first. This principle is particularly important in applications that retrieve student records, product information, and database entries because incorrect assumptions about data arrangement can lead to unreliable results.
- Confusing Time Complexity with Actual Execution Time
Another common mistake is assuming that time complexity directly represents the number of seconds an algorithm requires to complete an operation. Big O notation describes how an algorithm’s workload grows as the input size increases, rather than providing an exact execution time. Actual performance also depends on hardware, programming language, implementation quality, memory access, and the structure of the input data.
For example, insertion sort may outperform a more advanced sorting algorithm when processing a very small collection because it has low implementation overhead. However, its quadratic growth makes it less suitable for large datasets. Understanding this distinction helps developers avoid selecting algorithms based only on their complexity labels. They should combine theoretical analysis with practical testing to determine how well an algorithm performs in the environment where it will be used.
- Failing to Test Different Input Arrangements
Testing an algorithm with only one example can create a misleading understanding of its performance and correctness. Searching and sorting algorithms may behave differently depending on whether the collection is already sorted, randomly arranged, or arranged in reverse order. For instance, insertion sort performs particularly well when the elements are nearly sorted, while quicksort may experience poor performance with certain input arrangements if its pivot selection is unsuitable.
Similarly, linear search may locate a target immediately when it appears at the beginning but examine the entire collection when the target is absent. Beginners should therefore test algorithms with different collection sizes and arrangements. This approach helps identify logical errors, understand performance limitations, and develop stronger problem-solving skills. It also prepares programmers for coding interviews, where they may be asked to explain how an algorithm behaves under several different conditions.
Conclusion
Searching and sorting algorithms form an important foundation of computer programming because they help applications locate, retrieve, and organize information efficiently. Linear search and binary search demonstrate two different approaches to finding specific values, with binary search offering significantly better performance when the collection is already sorted. Bubble sort, insertion sort, and selection sort introduce basic sorting principles through comparisons, shifting, and element selection, while merge sort and quicksort demonstrate how divide-and-conquer techniques can improve performance when processing larger datasets.
Each algorithm has advantages, limitations, and different time and space complexity characteristics. Their applications can be seen in online shopping platforms, student record management systems, databases, and business inventory applications. For beginners, learning these techniques provides more than the ability to write sorting and searching code; it develops logical thinking, algorithm analysis, and problem-solving skills. By understanding how each method works and when to use it, developers can make better programming decisions and build applications that manage information more effectively.