Introduction
Human language is one of the most important means through which people communicate information, express ideas, pose questions and share experiences. But words and sentences are not natural for the computer. They manipulate information mathematically, numerically, and by programming. This distinction poses a problem when people wish to communicate with machines through common language. To tackle this, computers are now able to analyze, interpret, and create human language with the help of Natural Language Processing (NLP). It is a blend of artificial intelligence, linguistics, statistics and machine learning that converts text and speech into a machine-readable data format. Many common technologies, such as chatbots, search engines, voice assistants, translation software, email filters, and automated customer service systems utilize NLP.
To grasp the mechanics of NLP you need to look at the various stages through which language passes in its way from it being received in the raw state to a useful response. These steps can involve tokenization, normalization of text, stemming, lemmatization, part-of-speech tagging, parsing, named entity recognition, and machine learning processing to interpret. While not all NLP systems employ all of the techniques in the same sequence, these techniques offer a framework for understanding the way language technologies work. Advanced neural networks and big language models are also part of modern systems to understand the connections between words, understand context, and provide relevant answers. The step-by-step approach to the NLP pipeline will help readers appreciate how computers transform words into meaningful, language-related tasks.
What is Natural Language Processing?
NLP is a field of AI that deals with human language. It can be used to read sentences, translate between languages, summarize documents, extract relevant information from them, and answer questions. NLP is a melding of computational techniques and understanding of languages. Traditional systems are based on a set of linguistic rules and statistical methods, and modern systems are increasingly being powered by machine learning and deep learning to identify intricate patterns within vast amounts of text. These strategies can facilitate the processing of various writing styles, word usage, grammar forms, and expressions found in everyday writing by computers.
NLP is the primary goal to make the communication of humans to computers more natural and useful. In the case of asking a virtual assistant about the weather, the system needs to recognise the user’s query and understand that the user is asking for weather forecasts, know what location they are interested in and get an answer that is relevant to their query. Likewise, an email application can analyze an e-mail to discover a name, a meeting date, or an essential action. These tasks will not be completed by recognising individual words alone; the meaning of language can be related to the relationships between words and the situation in which they are used. NLP offers techniques for identifying the relationship between these and transforming language into organised representations that can be understood by the application and which can be called upon to do a certain job.
The NLP Pipeline
The NLP pipeline is a list of the sequence of operations that a language processing system might use for analysing or generating language. It starts with input (a written message or spoken sentence) and then works through the operations required to prepare, represent, interpret or respond to that input. A regular pipeline can clean the text, break into smaller parts, determine the grammatical roles, analyse the sentences, and extract the information. A machine learning model may then be able to categorize the message, determine the meaning of the message, or generate a response. But, modern neural systems do not always process the language in a linear fashion. Others perform some forms of processing text using learned numerical representations and attention mechanisms, thus being able to identify relationships between words without explicitly computing all of the standard NLP processes.
The actual process is dependent on the application. A simple spam filter might be interested in recognising patterns common to spam, and a translation system would need to maintain meaning in two languages. A chatbot might have to understand the user’s goal, keep track of pertinent conversation elements, and produce the correct response. Although there are differences, the overall goal is the same: to use language to represent a helpful computational task. Now you will understand why NLP is a system of a number of complementary techniques instead of just one. The stages focus on different challenges: from preparing inconsistent text to interpreting the context and producing an appropriate output.
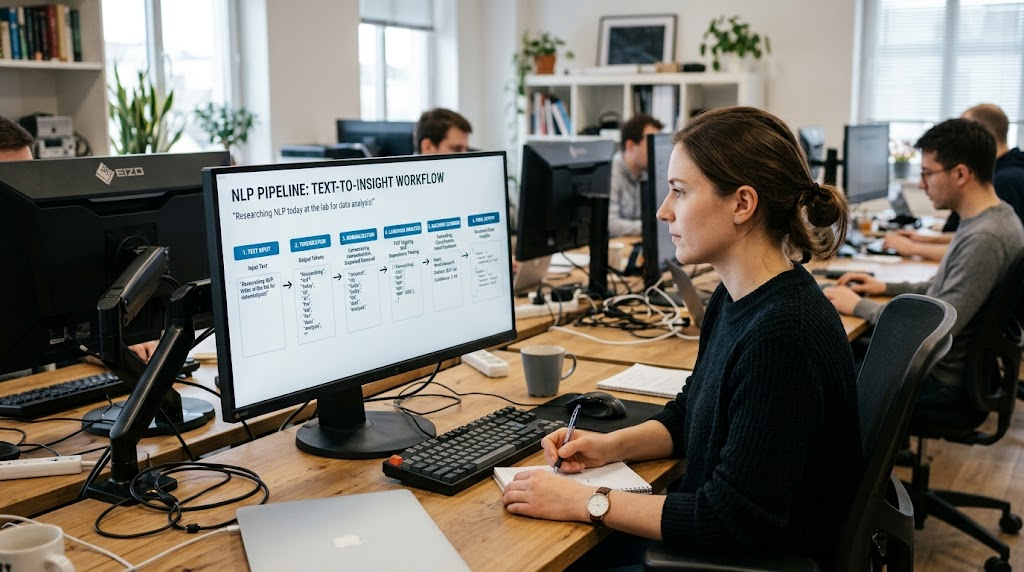
Analysis of Text Input
The first stage is the collection of the language from the source and the preparation of the language for analysis. This can be a typed question, an email, a document on a website, a social media post or a speech-to-text transcript. For any spoken language source, a speech recognition system can be used to first convert the audio signal to text. There may be spelling errors, inconsistent capitalization, extra spaces, punctuation errors, abbreviations, or other oddities present in the resulting text. This information can be used more consistently by the system. However, the amount of preparation depends on the application. The simplest text classifier might need the simplest cleaning, while the more advanced language model can keep punctuation, capitalization and other information that can serve to accentuate meaning.
Suppose that a user asks, “What are the opening hours of the bank? This sentence is sent to an NLP application as a string of characters, then transformed into a format that can be used for additional processing. The system can retain the question mark, recognize the words and prepare the sentence for analysis. For instance, an email application can get an email that includes the sender’s name, date of the meeting, and a few sentences that explain an appointment. The system is to store the necessary information while composing the message for subsequent processing. With good input preparation, there is not too much inconsistency, but it has to be done carefully, as taking out valuable information would affect the final interpretation.
Tokenization
Tokenization involves breaking a text into smaller components known as tokens. A token can be a word, a character, punctuation, or part of a word. When words are tokenized, it becomes easier for the computer to analyze the language as the words are isolated units rather than a single connected sequence of words. The sentence “Artificial intelligence helps people solve problems” might be segmented into the following tokens: Artificial, intelligence, helps, people, solve, and problems. These units can then be analysed separately and the relationship between them thought about. Word segmentation is simple in the case of words that are separated by spaces, but word segmentation can be tricky in the case of contractions, hyphenated expressions, punctuation, and languages that do not use spaces between words.
Subword tokenization is a common technique for modern language models that divide words into smaller components if they are needed. This helps the systems to cope with terms, names, spelling variations, and new terms that they have not previously encountered, without needing a specific token for each word. For instance, if a technical term is not included in the familiar vocabulary of a model, then that term can be represented by several smaller units. The tokenization will then affect the amount of text the model can handle and how the model internally represents language. Later stages may be impacted if an application is not correctly splitting text or is poor with important expressions. Good tokenization serves as the basis for turning a sentence into a series that can be processed by statistical and machine learning techniques.
Text Normalization
The task of text normalization is to ensure that some aspects of the text are more consistent to enable the NLP system to process it more easily. Typical transformations that are performed include character typesetting, removal of unwanted spaces, normalization of some abbreviations, and capitals. For instance, the system may consider “Artificial Intelligence” and “artificial intelligence” to be the same if it is intended to mean the same thing to the user. Normalization can also handle differences in punctuation, repetition of characters, and regularize spelling. They are very useful when a system receives information from several different sources, and the formatting and types of writing are significantly different. But the normalization should be based on the need of the task, not just on the elimination of all variations automatically.
An over-normalized image can cause loss of information that is crucial for interpretation. For example, a person’s name may be separated from a common word by the use of capitalization, and punctuation may change the meaning of a sentence. Note that the word “US” could mean “the United States,” while the word “us” is typically a pronoun. Likewise, omitting punctuation from a message might make it harder to understand the message’s structure. Modern NLP systems tend to retain most of the original text and employ special processing techniques to deal with variation. The primary purpose is to eliminate unnecessary variations, but in the process not losing information that can help convey meaning. A well-designed normalisation process will ensure that the text is consistent without altering its intended meaning.

Stemming and Lemmatization
Stemming and lemmatization are used to find the relationships of the different forms of a word. Selected endings or word parts are removed to create a simplified form called a stem, which is known as stemming. In this way, “playing”, “played”, and “plays” could all be stemmed to “play. Stemming is not always applicable to create a dictionary word, and for many rules, an understanding of the grammatical context is not complete. It is useful for some applications in information retrieval and in text classification, where grouping similar forms of words can be more important than retaining their exact grammatical form. It is easy to use and can be a relatively efficient way of stemming, though it may not be as accurate from a linguistic point of view.
Lemmatization, on the other hand, uses a more linguistically-sophisticated method that identifies a word’s base or dictionary form, called its lemma. Thus, the form “running” can be contracted to “run”, and the form “better” can be linked to “good” if a grammatical analysis of the text suggests this. The difference between stemming and lemmatisation is that lemmatisation can make use of vocabulary information, grammatical rules, and part of speech information to select the base form. There is a more detailed explanation for those readers who want to find out more about the reduction of words to their canonical forms, known as lemmatization. These methods enable NLP systems to identify variations of forms that have related meanings. The utility of them would depend on the application: a search engine could benefit from grouping similar terms together, but a language analysis system would require that grammatical distinctions be maintained in order to accurately analyze the sentence.
Part-of-Speech Tagging
Part-of-speech tagging is the process of assigning the grammatical function of each word to a sentence. Words can be used as nouns, verbs, adjectives, adverbs, pronouns, prepositions, or other grammatical parts of speech, depending on their context. This information is used by an NLP system to figure out the meaning of an expression based on words. Think about the sentence “The student writes the lecture. In this case, the word student is used as a noun, records is used as a verb and lecture is used as a noun. But, in the sentence “The student keeps important records,” records is used as a noun. It will have the same spelling but a different grammatical function based on the surrounding words. A POS tagger system analyzes context clues and makes the appropriate guess as to the meaning of the word.
The part-of-speech tagging is useful for other language-processing applications, such as parsing, information extraction and lemmatization. Determining the role of a word – whether it is a noun or a verb – can assist a system in recognizing its base form and its semantics with respect to the words around it. Traditional tagging approaches rely on grammatical rules and statistical models that are based on annotated text, while state-of-the-art approaches leverage neural networks trained on textual data to identify contextual patterns. Grammatical tagging does not always predict meaning but it gives some information on the sentence structure. For instance, knowing the primary verb can assist a system in determining what type of operation is being performed, and understanding nouns can aid the system in identifying who, what, where, or what is the subject of a message. This information helps in a better understanding of the text.
In step 6 they learn to analyse sentences and to identify the different types of sentence structures.
Parsing is the study of the relations of words and phrases to each other in a sentence. There are two important forms of parsing: constituency parsing and dependency parsing. While constituency parsing groups words into grammatical structures like noun phrases and verb phrases, dependency parsing pins down relationships between words. These techniques enable a computer to figure out which words are action words, which words describe the actions, and which things are being influenced by the actions. Think of the sentence “The manager granted the employee’s request. A dependency parser can find the subject of the verb “approved” as “manager”, and the object of the verb “approved” as “request”. This structural information facilitates determination of the actors and the affected objects.
Sentences can also provide clues to help distinguish between sentences that have the same words but different relationships. The vocabulary is very similar in both “The teacher praised the student” and “The student praised the teacher”, except that the direction of the actions changes. A system which takes into account grammatical relationships can make distinctions among people who perform the action and people who receive the action. Parsing can also be useful in question answering, information extraction, translation, document analysis, etc., since such applications require more than the recognition of individual terms. However, it is possible for there to be ambiguous or complex sentences in natural language, and there can be multiple possible interpretations for different parsers. Explicit parsing methods can be paired with the contextual representations that can be learned from neural networks to better understand the relationships in sentences within modern systems.
Named Entity Recognition
Named Entity Recognition (NER) is the task of identifying the important entities in a text and categorizing those entities. They can be anything such as persons, organizations, places, dates, times, money, and more, depending on the domain type. For instance, the sentence “Ada arrived in Lagos on 12 October to attend a Microsoft conference”. With an NER system, “Ada” can be recognized as a person, “Lagos” as a place, “12 October” as a date, and “Microsoft” as an organization. The system can then “structure” these details into structured fields rather than having them “embedded” in an unstructured sentence. Useful because many applications require extracting particular facts from a lot of written data.
The use of NER is especially valuable in email applications, business intelligence systems, news analysis, customer support systems, and document management systems. For example, an e-mail application might be able to detect a specific meeting time, or the names of a client and a company in an e-mail message, and then draw your attention to the key information in the message or suggest calendar entries. But context needs to be addressed to identify entities accurately. A word can describe a person in one sentence then an organisation or a place in another sentence. Names may also be foreign or shortened, or spelled differently. Thus, machine learning models leverage annotated examples to learn about contextual clues and patterns and enhance entity recognition. By organizing the information in this way, other parts of an application can search the data, make a summary, or organize it more efficiently.
How Machine Learning Models Interpret Language
Traditional NLP techniques tend to be based on explicitly stated linguistic rules, manual-designed features or dictionaries. Machine learning provides another method, where systems learn from examples in the form of patterns. During training, a model runs data and alters the contents of its internal parameters in an attempt to perform a specific task better. In the case of a spam detection model, for instance, it could be trained with messages that are marked as spam and as legitimate email. With experience it can identify groups of words, formatting patterns and other signals of unwanted messages. Rather than forcing the developers to define each possible characteristic of spam, the model learns the statistical relationships from the training data. It is affected by the quality of data, the design of the model, the techniques used for model training, and the representativeness of the examples used for model training in comparison with the messages it encounters in practice.
Recent NLP implementations often rely on deep learning models such as transformers, which can learn associations between words in a sequence. Attention mechanisms are used in transformers to guide the model in their relevance of the tokens that they are processing on a specific token. This enables the system to take into account the context of nearby words, and, depending on the architecture and the length of the input, relationships between words that are far from each other in a sentence or a document. For instance, in the sentence “The animal did not cross the road because it was frightened”, the interpretation of ‘it’ needs to be related to the real person or thing that is frightened in the sentence. Neural models learn patterns that aid such interpretations but can also be wrong. These models generally transform tokens to numerical representations and employ learned computations to aid with classification, prediction, extraction or text generation.
Understanding Context and Meaning
One of the most difficult aspects of NLP is to grasp the context and as with all words, meaning can vary. For example, the term “bank” can be used to describe a financial institution or the land next to a river. The words around the sentence suggest a financial context in the phrase “She deposited money at the bank. In “They sat on the river bank”, there is a geographical interpretation that is supported by the context. NLP systems rely on the words surrounding a word, the structure of the sentences, learned associations, and information about the task to select the most probable interpretation. Contextual models may provide a different representation of the same word based on the context where it is found, and can cope better with ambiguous situations than methods that fix a single representation for a word.
Context can be more than a single sentence. An assistant that is conversational may want to follow up with another question based on something that was said in the conversation before. When asked about “Who wrote that book”, the system should recognize which book the user mentioned. Likewise, a customer support tool can require it to interpret a message based on data from a previous complaint, or a current service request. Contextual understanding is thus the identification of relationships between words, sentences and pertinent conversation information. BUT there is no guarantee that a context will understand a message correctly. Models can misinterpret statements, miss out on the implied meaning and make confident but wrong conclusions. Any good NLP applications should deal with ambiguity and allow the users to ask clarifying questions.
This step involves transforming language into useful outputs.This step is about making language useful outputs.
Once an NLP system has analysed a text, it can use the information to carry out a task. The output can take the form of a category, a collection of details extracted from the document, a ranked list of search results, a translation of a sentence, a summary, or a generated response, depending on the application. One classification system may call a message “urgent,” whereas another information extraction system may provide the name of a person and their appointment date. Based on the user’s request, a chatbot can interpret the query and pick out content that is relevant and create a response. In either case, the output will be determined by the goals of the app and the model’s capabilities. Others create structured data for use in other software components, others create natural language for a human reader.
For instance, an email application could handle the message: “Project review is on 18th November 10am – send the updated report before the review. The system could detect the meeting date and time, the requested report, and classify the message as having an action item. It could remind the user of the deadline or prompt to make a calendar appointment depending on the design and permissions of the application. It should not presume the accuracy of any information that it is pulling out from the user, and assumes that the user has permitted an action. In more advanced applications, information extracted could be compared to other available records prior to its use. This demonstrates the power of NLP in transforming unstructured language into productive outcomes, whilst maintaining the correct validation and protections.
How a Chatbot Analyzes a Question in Practice.
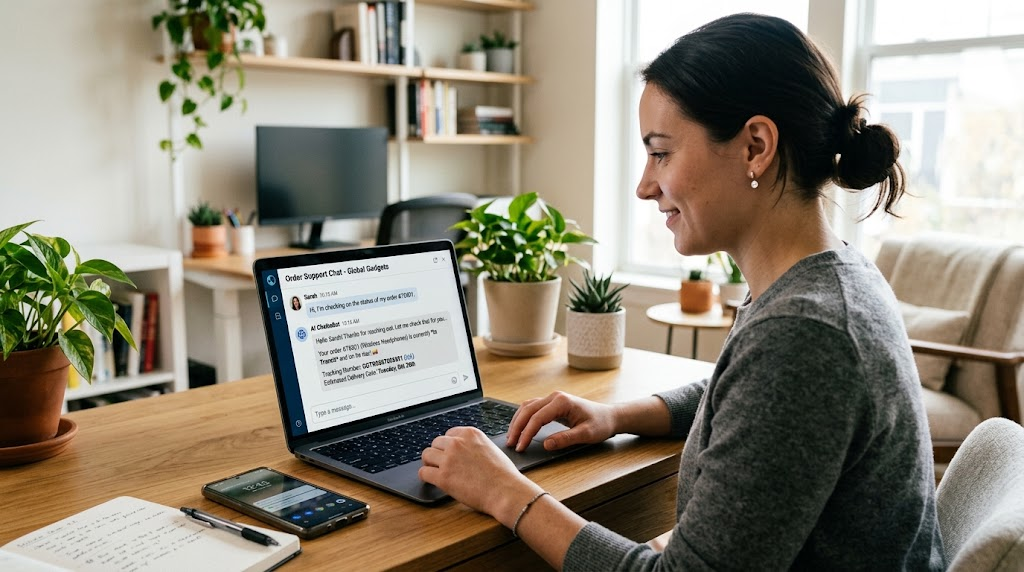
Suppose a customer service chatbot receives a customer inquiry about where they can find their order and when to expect it. The Chatbot takes in the text and splits it into tokens. It can normalize selected elements and represent the tokens as numbers depending on the design of it. A language understanding component identifies what the user is likely to be trying to do: find tracking information and check the estimated delivery time. The system could also identify that the user is requesting a specific order without any mention of the order number in the message. If it is impossible to find the order in the conversation or from a connection from an authorized account, the chatbot could ask for more details, instead of making up an answer.
After grasping the request, the chatbot can seek out data from an order management system or any other approved data source. It can display the order status, track the link and get the estimated delivery date. A response generation component then provides information in a clear language, for example, stating where the order is or when it will be delivered. The process involves language interpretation, intent recognition, information retrieval and response generation. The structure of the system depends on the system, and a simple chatbot can rely on a set of rules instead of a language model. The result is a natural language query to the system matched with the appropriate information or action to answer the query exactly.
Example of NLP and How Search Engines use it
The search engine utilizes NLP techniques for understanding queries and finding relevant information from a vast collection of documents. If a user types in “best ways to protect a small business from online fraud,” the system needs to recognize the main ideas and decide what documents it is likely that he/she is looking for. The query can be prepared by way of the tokenisation and normalisation process and the relationship between the query and the candidate documents can be estimated by language models and other ranking methods. Search engines also will take into account synonyms, associated thoughts, document relevance, freshness, quality signals and search/sentence context. These methods help it to return helpful results even if a website does not have all the words in the exact phrase of the user.
Search systems can consist of multiple stages: identifying candidate documents, assessing their relevance and ranking them for presentation. NLP can represent the meaning of a query and document content, and machine learning models can estimate which ones best represent the user’s intent. But NLP isn’t the only factor in search. Other signals include indexing systems, link analysis, quality assessment, and more. By designing a system which integrates all of these, information can be more easily located. This example illustrates how NLP can be used to assist with large-scale information retrieval tasks by enabling computers to link human questions and documents relevant to the concepts and intentions of the question.
Challenges and Limitations of NLP
Although significant advances have been made, there are still a number of challenges with NLP systems. There are lots of things in human language, such as sarcasm, idioms, slang, cultural references, spelling errors and words that can mean different things in different contexts. On the surface, a positive sentence might convey criticism, and an informal phrase might mean something other than any individual word. Languages vary, too, in terms of their grammar, word formation, writing systems, and electronic materials. Models that are trained primarily on one language or variety may be not so effective for another one. These challenges emphasize the need to assess NLP systems on samples that are representative of the people, languages and contexts where the systems will be applied.
The other one is bias, privacy, and reliability. Machine learning models can replicate patterns and biases that are found in their training data, which may result in unfair and inaccurate outcomes. They may also mispronounce names, misinterpret directions, or make statements that seem to make sense but are not. If it is a message processor for personal messages, a medical record processor, or a financial processor, then data protection and proper controls for access should be taken into account. Using representative training data, systematic testing, human review, clearly defined uncertainty-handling, and task-specific safety measures can improve reliability when developing. When it comes to situations that demand impact, NLP output must not be considered to be a substitute for professional judgment. To create useful, responsible, and trustworthy language technologies, these limitations must be recognized.
The future of NLP.
Enhancements in multilingual systems, speech technologies, multimodal artificial intelligence, and better large language models are closely linked with the future of NLP. Various language processing technologies are now being integrated with images, audio, video and structured databases, enabling people to interact with information in various ways in modern applications. For instance, a system can listen to a user’s question, then look at a photo provided by the user and return a response that combines the information from both sources. Improvements could be made in special document handling and specialized terminology in terms of their handling by applications, using contextual learning and retrieval techniques. The new developments are broadening the scope of tasks language technologies can assist in education, healthcare, research, business, and in daily digital communication.
But future advances will rely on more than simply growing the model or its speed. Developers should keep enhancing the accuracy, efficiency, accessibility, protection of privacy and evaluation of model outputs. Smaller models can be useful in low cost, fast response or when processing is done locally, while larger models can be helpful in more complex applications that can leverage greater context. Learned models, combined with the use of reliable databases, established software systems, and human oversight, can provide applications that are more useful. As these technologies develop, knowing the underlying NLP pipeline will continue to be useful for people to assess what a system does, why it might fail, and how the various parts of the pipeline can help to produce a valuable outcome.
Conclusion
Natural Language Processing (NLP) is the ability of a computer to interact with people in natural language by converting text and speech into a representation that can be analyzed, interpreted, and communicated with. It can be used in input preparation, tokenization, normalization, stemming, lemmatization, part-of-speech tagging, parsing, and named entity recognition. Machine learning and deep learning models extend these capacities by learning patterns from data, capturing contextual relationships, and generating outputs based on specific tasks.
Invoking chatbots, email assistants, search engines, translation services, and voice assistants are examples of applications that illustrate the ways these strategies assist with human-technology interactions. While contemporary systems can execute more intricate language tasks, they continue to encounter a variety of ambiguities, biases, privacy and reliability issues. Understanding the NLP pipeline will enable readers to better understand the potential and current constraints on language technology and why algorithmic design is a crucial element to future advancements in AI.