Introduction
Modern businesses deal with vast amounts of data everyday. To store and manage data effectively, many systems will want to utilise a database system. This is especially true for online shopping, banking applications, social media and international businesses. Centralised databases can cause issues if the application is used by millions of users in different locations. This can be overcome by using a distributed database system.
These systems store data in multiple locations, this can be achieved via multiple computers, servers or locations. Technology like Apache Cassandra allows businesses to utilize distributed databases, providing replication, partitioning and horizontal scalability to help them store data in large scale applications. This can help organisations improve the availability, performance and reliability of their data storage whilst also allowing them to store it across different locations.
What are Distributed Database Systems?
A distributed database system is a type of database system that stores information in multiple locations. These multiple locations will often be referred to as nodes. The data is held in these nodes and there will always be a network that connects to allow communication between them. Although the data is not physically stored in the same location, the database will manage the distribution of the data to allow users to access their information. The data can either be fully replicated across multiple servers or split into smaller sections depending on the database system.
Distributed databases are very useful because they help overcome issues caused by centralised databases. If an organisation has an increase in visitors or expands into new locations then a database that is only running on one server will struggle. Using a distributed database system means that the organisation can spread out their processing across multiple machines. This will make it easier to add more users and store more data. It will also help with reliability as there will be multiple nodes that have access to the data. Distributed databases are ideal for applications that require constant access to their data, quick processing and the ability to run across different locations.
How Distributed Database Systems Work
A distributed database system works by having multiple computers that communicate with each other. Each computer will have some sort of task to complete in the database. This could be storing records, querying data, replicating data or managing transactions. When an application sends a query, the database will see which nodes contain the data and send the request to the right location. Depending on the system, it may be sent to one node or multiple nodes. The results will then be sent back to the application. This allows users to access their data without knowing where it is stored.
A distributed database will also have various features to help manage the data. Data partitioning will decide how the data is split between nodes. Data replication will help increase availability as the data is stored in multiple locations. Synchronisation will ensure that the servers can communicate with each other. Some systems will have a leader that will manage the changes whilst others will allow multiple nodes to receive write requests. Depending on the database system and how much consistency is required, this will change. Overall distributed databases can help manage data across large systems.
Understanding Distributed Database Systems
Distributed database systems have various components that help manage the database. The database will be spread across multiple computers. This could be within one data centre or spread across multiple locations. The database needs to have a good structure to allow the data to be distributed efficiently.
The system should also take into consideration delays in communication, hardware issues, network issues and varying processing power. A well designed system will help ensure data can be distributed efficiently.
- Client – Server
Client-server systems allow applications to communicate with database servers. The client will send a query/transaction and once processed by the database infrastructure it will return a result.
Depending on the system, one server will manage the requests and communicate with the other nodes that hold the data. This helps split up the application from the database and allows the organisation to split the processing across multiple machines. This is commonly used in enterprise applications.
- Peer to Peer
Peer to peer systems allow the nodes to communicate with each other. Each node can contribute to the database. Some systems allow multiple nodes to receive read/write requests.
This can help increase availability as even if one machine goes down the rest can still run. This is useful for large distributed databases. However, managing updates and ensuring consistency can become complicated as multiple nodes can receive changes.
Components of a Distributed Database
A distributed database will usually be made up of several components. The first component will be nodes. These will provide the processing and storage for the database. Communication will be provided between the nodes. There may also be a query coordinator or database driver to decide where the request should go.
The data will also be replicated between selected nodes. If there are multiple records involved, there will be a transaction manager to manage them. This will ensure the database has a unified system allowing applications to access and manipulate data.
10 Key Features of Distributed Database Systems
Distributed database systems have lots of features that make them perfect for large storage, reliable access and location based applications. The database will manage how the data is stored, processed, secured and synchronised.
Whilst different databases will manage this in different ways, most will use some sort of distribution, replication, workload management and fault tolerance. Knowing the features will help organisations decide if a distributed database would be best for their application.
1. Data Replication
This involves data being replicated across multiple nodes. This means the data can be stored in multiple servers or locations. This will help increase availability as the data can be taken from another replicated copy if one server is down. It can also help increase performance for reads as the data can be accessed from a closer location.
However, this must be managed correctly to ensure the data isn’t left out of sync for too long. Some systems will synchronise the replication whilst others will use asynchronous replication.
2. Data Partitioning
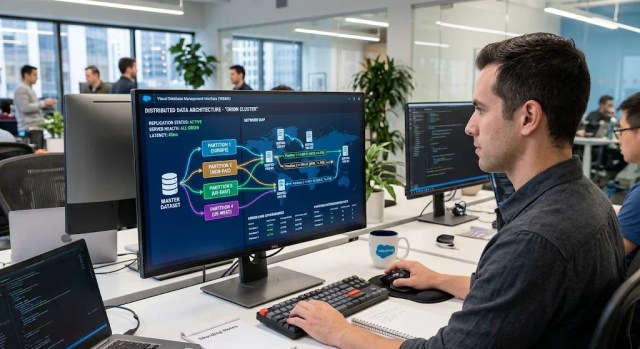
Data partitioning will split large data sets into smaller sections. This means that different sections of the data will be stored on different servers. This will help reduce the workload on each machine and also increase storage by adding more nodes. This can help improve performance for queries as the application will know exactly where to look for the data.
For example, an online shopping application internationally may have customer records partitioned by customer ID or location. Choosing the right partitioning will ensure that no nodes are overwhelmed.
3. Horizontal Scalability (Scaling Out)
This allows organisations to add more computers/servers to increase the size of their database. This means that the distributed database won’t rely on one powerful machine to store and process the extra data.
This can be very useful for organisations who experience unpredictable increases in traffic or constantly increasing data. Adding new nodes may mean the partitions and replicas are rearranged. Some systems will do this with little disruption. This makes distributed databases ideal for large applications.
4. High Availability
High availability means that the database will still be available despite any issues with individual components. This can be achieved using replication, auto recovery and distributing the workload. If one node goes down due to hardware or network issues then another node holding the data may still be able to respond.
Some systems will have the data replicated across multiple data centres meaning that if an entire data centre goes down then not every database operation will be affected. This is very important for online banking, e-commerce, communication platforms etc.
5. Fault Tolerance
Fault tolerance is the ability to have essential operations running despite some faults within the database. This is achieved by not relying on individual servers and having extra copies of important data. If a node goes down the database will identify the issue and send suitable requests to the right location.
The affected data can then be recovered using the replicated data. Some databases will automatically replace the failed replicas or move the data. This is very important for organisations who run applications 24/7. However this doesn’t mean they don’t need to back up, monitor, disaster recovery and test regularly as replication can’t protect against all data loss.
6. Data Synchronisation
Data synchronisation ensures that the data within the database is kept up to date according to the consistency rules. Any data a user updates must be communicated to the correct replicas or servers. Some systems will use synchronous data synchronisation meaning that the replicas will confirm they have received the changes.
Other systems will use asynchronous data synchronisation to allow updates to be sent to remote replicas. This depends on the application, distance, network performance and how important it is to have immediate access to the data.
7. Distributed Query Processing
Distributed query processing means that the database can find and analyse data that has been stored across multiple nodes. When a query is sent by an application, it will decide which servers contain the data. It will then distribute the work across the nodes.
Each node will process their piece of the query and return the results. This can help improve performance by having the data distributed correctly and processing queries in parallel. Queries may take longer if multiple nodes are involved. Database designers will take into consideration partition keys, indexes and query patterns to ensure frequently requested data can be accessed quickly.
8. Consistency
Consistency ensures that operations within the distributed database follow certain rules. As the data may not be updated at the same time across the different replicas, the database must have ways to ensure the application doesn’t get conflicting or old data.
Some systems will provide strong consistency meaning that writes will be visible in a strict order. Other systems will provide eventual consistency meaning replicas may temporarily have different values but eventually will agree. Some distributed databases may also provide configurable consistency meaning developers can decide how fresh, available and quick their data will be.
9. Transactions
Transactions allow distributed databases to process related database operations. For example, an online payment application may need to update an order, update an account balance and log a payment confirmation. This must be managed carefully to avoid incomplete or conflicting results. Some distributed databases can process transactions across multiple records and nodes.
This means they will follow ACID principles (Atomicity, Consistency, Isolation, Durability). However this depends on the database. If the operation involves multiple locations then there may be more communication between servers causing extra latency. Organisations must choose databases that provide the required transaction support.
10. Geographic Distribution
This allows the data to be stored across multiple cities, countries or continents. This can help international organisations as they don’t have to send all requests to one central data centre. The application will be able to access nearby replicas which can help reduce network latency.
This can also help increase resilience as the infrastructure will be across different locations. However organisations must consider data protection laws, cross border data transfers, network latency and replication when deciding where to store their data. This is especially important for businesses that operate internationally and hold sensitive customer data.
Data Replication, Fragmentation and Partitioning
One of the most important factors to consider when managing a distributed database is how the data is distributed. There are three main concepts to consider when doing this. These are data replication, fragmentation and partitioning. Whilst related, they all have different functions within the database.
Replication duplicates data, fragmentation splits the database and partitioning arranges the fragments. Understanding the difference will help database administrators design a system to balance performance, availability, storage and consistency.
Data Replication
Depending on how the data needs to be accessed and updated, there are various ways data can be replicated. Synchronous replication means that the replicas will confirm they have received the changes before the database confirms the operation. This can provide better consistency but may cause longer response times especially if the servers are far apart.
Asynchronous replication means the operation can be completed before the changes have been sent to all remote replicas. This can help increase write performance and availability but some replicas may have old data. Multi-primary means multiple nodes can receive updates. Primary replica means writes are sent to a primary node and then distributed.
Data Fragmentation
Fragmentation means the database is split into smaller sections. This is commonly split into horizontal, vertical and hybrid fragmentation. Horizontal means the table will be split into groups of rows. For example, customer records could be split by location. Vertical means the table will be split into groups of columns.
Hybrid means a combination of both. This can help reduce unnecessary data transferring as the data can be accessed from where it is stored. However, database designers must ensure the data can be pieced together correctly.
Data Partitioning
Partitioning means large tables/datasets can be split into smaller sections. This is commonly used to distribute workloads to different nodes. Common partitioning types include range, hash and list partitioning. Range means the records will be assigned based on value ranges. Hash means a mathematical function will decide where the records go.
List means the records will be organised based on specific values. The type of partitioning will affect how quickly queries can be processed, how the workloads are distributed and whether any nodes become overwhelmed. A good partitioning strategy will ensure the data is evenly distributed and frequently accessed data can be accessed quickly.
Benefits of Distributed Databases
Distributed databases provide many benefits to organisations wanting to access data reliably across multiple computers. They are ideal for applications that experience increasing workloads or need to be accessed by users in different locations.
The system is flexible as the organisation can decide where to store their data. Whilst they must be managed carefully, there are many benefits making them an important aspect of modern enterprise.
- Increased Performance and Fast Data Access
Distributed databases can help increase performance by distributing the database requests across multiple servers. This means the database can utilise the available processing power to process different operations. Having data replicated across different locations can help users access data from a closer server. This can be very useful for applications that have large numbers of concurrent users such as online marketplaces, streaming services and financial services.
However, the performance will depend on the database structure, workload distribution, network performance and query design. If partitioning hasn’t been done correctly or there is too much communication then this can reduce the benefits.
- Increased Reliability and Availability
A major benefit of using a distributed database is that it ensures data can still be accessed if any of the servers have issues. Having the data replicated across different nodes means the organisation won’t rely on one physical machine. If one server goes down then another replica may still be able to respond to the application. Systems that have infrastructure across multiple data centres can also help protect against some location based issues.
This is especially important for organisations who need constant access to customer records, financial data and operational databases. However, organisations must still have suitable back up systems and recovery processes in place as replication won’t protect against any accidental deletion, malicious changes or all types of infrastructure issues.
- Easier Scaling
A distributed database will allow you to scale your system. You can add more nodes to your database to handle the increased amount of data being stored, increased traffic on your applications and new business processes. Horizontal scaling can give you more flexibility than continuously updating your database server. Additionally, resources can be spread out across different nodes in your organisation.
For example, if your company rapidly has more traffic from customers then you could scale up your database by adding more suitable compute resources. Some distributed databases will automatically balance your data. This can save you some manual admin work. However, scaling your database will need to be planned to ensure data isn’t imbalanced and you’re not spending extra money unnecessarily.
- Improved Global Accessibility
If your organisation works in multiple countries then using a distributed database will allow you to have better accessibility. Your data will be stored in multiple places. Your applications can talk to the nearest server potentially increasing your response times and also making accessing data in your business easier. This can be useful for international retail organisations, communication platforms and finance.
Using a distributed database will allow you to create systems which will be resilient to issues in one location. However, your data should be placed in accordance with any privacy rules and company policies. If data is being sent between different countries containing customer details then this needs to be considered.
- Suitable for Large Data Processing
A distributed database is a good choice for applications which have large amounts of data. By distributing your data and queries across multiple nodes you can process heavy workloads which may be too much for a single server. This can be useful for applications which are handling customer activity, online transactions, sensor data and log data.
Distributing your data will allow you to scale up your resources. Along with having a good analytics set up you can process large amounts of data with a distributed database. This will depend on choosing the right technologies and ensuring your database is structured correctly to handle the processing requirements.
Examples of Applications with Distributed Databases
There are a lot of applications which can benefit from using a distributed database system. Organisations often need to store data in multiple locations and have a large amount of users.
Having a distributed database will mean you can store data in multiple locations, replicate your data and process requests from multiple servers. This can be useful for industries where having high availability is important. This includes finance, online retail, telecoms and healthcare.
- E-Commerce
E-commerce applications often have large amounts of data to process. This can include customer profiles, product catalogues, shopping baskets, orders, payments and inventory data. During peak times there can be an increase in traffic to your application.
Having a distributed database can help you process this by distributing data across multiple servers. Frequently accessed data can be replicated. If you have an international shopping platform then having the data stored in multiple locations can help provide a more efficient service to customers. However, payments and inventory may need to have more transaction guarantees.
- Banking
Banking organisations often have sensitive data which needs to be accurate, secure and available to authorised users. A distributed database can help with banking applications. You can store customer data, transaction data, payment services and organisational services across multiple locations. This can help improve resilience as data can be replicated across multiple servers.
However, banking applications often require high consistency and reliable transactions. If there is an issue with account balances or incomplete transactions this can cause serious issues. Therefore, your database technologies should provide the correct consistency, security, transaction and audit capabilities. A distributed database can help banking organisations handle large scale operations but should be carefully designed.
- Social Media
Social media applications produce a constant stream of data. This can include messages, comments, images, videos, likes and user interactions. To handle large amounts of data and provide a service to users from multiple locations a social media application would require a database. Having a distributed database can help distribute user data across multiple nodes and replicate frequently accessed data.
It can also be used for applications requiring a large amount of requests. For example a communication platform may use distributed storage to store user profiles and messages. However, privacy, access, synchronisation and keeping data consistent should be considered.
- Healthcare
Healthcare organisations often need to store patient data, appointments, lab results, prescriptions and organisational data. Having a distributed database can help with providing data to authorised professionals across multiple hospitals, clinics and medical facilities.
This can help organisations keep their data in sync across multiple locations. However, healthcare databases will need to have strong security and privacy features as medical data can be sensitive. Access, encryption, audit and data sharing policies should be in place. A distributed database can help increase accessibility but organisations should consider any regulation requirements.
- Telecoms
Telecom companies often have a large amount of data to process. This can include subscriber data, network data, usage data, payment data and communication data. As network services are used constantly your system will need to be able to run continuously. A distributed database can help you store and process data across multiple facilities.
It can help with applications requiring high availability. A distributed database can help with handling large amounts of data generated from your network. By distributing the workload you can improve your ability to cope with increased demand. This can be very useful if you have communication infrastructure across multiple locations.
Popular Distributed Database Technologies
There are a number of database technologies available which provide distributed storage, replication, consistency and transaction capabilities. Some are specifically for large scale NoSQL applications whilst others provide relational database capabilities across multiple servers.
This will depend on your application and what you require from your data such as structure, querying, transaction guarantees, scalability and complexity.
- Apache Cassandra
Apache Cassandra is an open source distributed NoSQL database. It is designed to store large amounts of data across multiple connected nodes. Cassandra uses a wide column format and has a peer to peer architecture. This means there are no dependencies on a central database server. Data is distributed using partition keys and consistent hashing. Data can be written to multiple nodes using multi-primary replication. Consistency levels can be adjusted to decide how many replicas will need to respond. This makes it a good choice for applications requiring high availability, horizontal scaling and continuous processing.
This is commonly used for applications with large scale time series data, activity data, messaging data and user generated data. The design of Cassandra means it can handle workloads requiring high availability and scalability. You can easily scale up your cluster by adding more nodes. However, data modelling will need to be designed in line with your queries as it doesn’t provide traditional distributed joins or cross partition transactions. The consistency also needs to be carefully configured. Knowing how Cassandra works will help organisations decide if it is the right choice.
- CockroachDB
CockroachDB is a distributed SQL database. It provides relational database capabilities across multiple computers. Data is divided into ranges and replicated. Changes are coordinated using the Raft consensus algorithm. This provides SQL querying and ACID transactions to help with applications requiring relational database functionality. Many aspects of distributed data are automatically handled to help organisations create scalable systems.
This is useful for business applications requiring relational data, reliable transactions and global data. Examples include financial applications, online marketplaces, customer management and enterprise applications. It provides strong consistency using serialisability by default. However, you will need to consider transaction retries. CockroachDB can be deployed across different infrastructures. This can help organisations create systems in line with their requirements. This is a good option if you want a distributed database but still require relational capabilities.
- Google Spanner
Google Spanner is a globally distributed relational database. It stores data in small pieces known as splits. These are automatically distributed. Changes are coordinated using synchronous Paxos based replication. It also has special time management to provide globally consistent transaction ordering. This can help organisations store data across multiple locations with relational database capabilities.
This can be useful for applications requiring reliable access to structured data across multiple locations. Examples include financial applications, large enterprise applications, inventory and global services. It provides strong consistency across distributed infrastructures making it an appealing choice. However, transactions can be affected by increased networking as they are distributed globally. You will need to consider the cost of the service, how it is set up, how the data is stored and what your application requires.
- Amazon DynamoDB
Amazon DynamoDB is a fully managed NoSQL database. It is part of Amazon Web Services and can be used for applications requiring scalable key value and document storage. Much of the infrastructure is automatically managed. The global tables feature can be used to store data in selected AWS locations. Depending on the global table consistency, different methods of replication can be used.
This is commonly used for serverless applications, online retail, mobile applications, gaming and other applications requiring scalable data. As it is a managed database it reduces the amount of work required to manage database infrastructure. It can be integrated with other AWS services to create event driven applications. However, it does not have the same data modelling or querying capabilities as traditional relational databases. Partition keys and access should be carefully designed to avoid issues.
Challenges of a Distributed Database
Whilst a distributed database can provide a number of benefits there are also some challenges to overcome. When storing data across multiple computers there needs to be reliable communication between nodes. This should be coordinated between nodes and security applied. If nodes are in different locations there can be increased complexity.
This can lead to delays in the network affecting your database. Organisations should be aware of these issues to ensure they don’t cause performance issues, inconsistent data and increased costs.
- Network Issues
A distributed database will require a network to communicate between nodes. If there is an issue with the network then some servers may not be able to communicate with the rest of the database. This can cause issues with queries, delays with replication and some operations may not complete.
If there are network partitions then different sets of nodes may not be able to communicate. The database will need to have ways to detect failures and decide what operations can be processed. You should also consider network reliability and design your infrastructure to recover appropriately.
- Conflicting Data
Conflicting data can occur if different updates are made to the same data on different nodes. This can happen in multi primary setups where multiple servers can receive writes. For example, two users may update the same customer data at around the same time on different regional replicas.
When this data reaches other replicas the database will need to know how to deal with the conflict. Some systems will use timestamps and last write wins. Others will provide conflict detection or reconciliation. Developers should be aware of how conflicts are being resolved as automatic reconciliation may not be what you expect.
- Latency
Latency can occur as data needs to be sent from one computer to another. If your database is distributed and you are performing operations on nodes far away from each other then this can cause increased latency. For example, if your transaction requires multiple approvals from replicas across different continents then this will take longer to complete than if everything was done in one datacentre.
Strong consistency can cause increased latency as multiple nodes may need to communicate. You can reduce unnecessary latency by storing data close to your application, optimising your queries and choosing suitable replication methods. However, you will need to consider the trade off between performance and consistency.
- Security
As data is being stored and passed between multiple computers there are additional security considerations. Any node, network, application or admin interface could pose a risk. Security should be in place to ensure only authorised users and applications can access/modify data.
Encryption can help keep your data secure. Authentication and audit can also be used. Database administrators will need to manage security updates, identify unusual activity and ensure suitable back ups are in place. If data is being stored internationally then you should consider what data protection laws apply.
- Consistency
Keeping data consistent can be challenging in a distributed database. Updates may not be applied at the same time to all replicas. The database will need to know when a change has been completed and what data should be returned to applications. Strong consistency can provide more predictable results. However, it may cause increased communication and increased response times.
Eventual consistency can help improve availability and reduce coordination. However, applications must be able to cope with temporary inconsistencies. You should understand how important it is for your data to be accurate, up to date and available. For example, financial records may require stronger guarantees.
- Transactions
Transactions across multiple nodes can be more complex. The system will need to coordinate changes so that related operations can be completed or follow defined rules. Some distributed transaction protocols may require communication between multiple nodes. This can increase latency and increase processing. If transactions are being processed across different locations then this can cause increased latency.
Not all distributed databases will provide the same transaction capabilities. You should carefully consider what database you are using. Applications with complex business processes should use systems which provide the required transaction guarantees. Suitable error handling and retry should be implemented.
Best Practice for Managing Distributed Databases
To improve performance and reliability of your distributed databases you should follow best practice. Choose a data distribution strategy which suits your application. Be careful when choosing partition keys to avoid imbalance. Ensure replication is set up in line with your availability and consistency requirements. Database administrators should monitor storage, querying, network and replication delays.
Ensure security is in place. Role based access should be used, sensitive data should be encrypted, regular back ups should be in place and recovery testing should be carried out. Monitoring can help identify nodes which are unavailable, unusual database activity and performance issues. Developers should be aware of what transaction and consistency guarantees your database provides. Test your systems with realistic workloads and simulate infrastructure failures. This will help ensure your distributed databases are reliable.
Distributed vs Centralised Databases
The main difference between a centralized and distributed database is how data is stored. A centralized database will store its main data in one central place. A distributed database will store data across multiple connected computers. A centralized database can be easier to manage as there is less infrastructure to manage. It can also be suitable for applications with moderate workloads and minimal geographical requirements. However, depending on the architecture your central server may become a bottleneck.
A distributed database can provide more flexibility. This can help with increased workloads, global accessibility and increased fault tolerance. However, it can also introduce more complexity. Synchronisation, networking, consistency and transactions will need to be managed. Whether to use a centralised or distributed database will depend on your requirements, expected data growth, availability, budget and admin capabilities. Some organisations will use both. Choosing the most suitable architecture for each application.
The Future of Distributed Database Systems
Distributed database technology continues to develop as businesses demand more scalable, reliable, and geographically accessible data infrastructure. Cloud computing has made it easier for organizations to deploy database systems across multiple regions without building and maintaining every physical server themselves. Managed database services also reduce some administrative responsibilities by automating activities such as replication, infrastructure monitoring, and capacity management. These developments are making distributed database capabilities more accessible to organizations of different sizes.
Another important development is the increasing use of distributed databases in artificial intelligence, real-time analytics, Internet of Things applications, and large-scale digital services. These applications generate significant amounts of information and often require fast access to data from different locations. Database technologies are therefore continuing to improve their approaches to workload distribution, consistency management, and automated recovery. As organizations adopt more complex digital systems, distributed databases are likely to remain an important part of enterprise computing infrastructure. Their future development will continue to focus on balancing scalability, performance, security, availability, and reliable data management.
Conclusion
Distributed database systems have become essential for modern organizations that need to store, process, and access information across multiple computers and geographical locations. By distributing data through partitioning and fragmentation, maintaining additional copies through replication, and coordinating updates through synchronization mechanisms, these systems can support applications that require scalability, high availability, and reliable data access. Their features make them useful in industries such as banking, e-commerce, healthcare, telecommunications, and social media. Technologies such as Apache Cassandra, CockroachDB, Google Spanner, and Amazon DynamoDB demonstrate different approaches to managing distributed information and supporting large-scale applications.
Despite their advantages, distributed databases introduce challenges involving network failures, latency, data conflicts, security, consistency, and transaction processing. Organizations must therefore select appropriate database technologies, design effective data distribution strategies, and establish suitable monitoring and recovery procedures. Understanding how distributed database systems operate helps developers, database administrators, and business leaders make informed decisions about modern data infrastructure. As applications continue to grow and become more geographically connected, distributed databases will remain an important foundation for reliable and scalable digital services.