Introduction to Database Management Systems
A Database Management System (DBMS) is a software designed to efficiently store, organize, retrieve, update and safeguard information for individuals, applications and organizations. Databases are indispensable for modern applications, as they need to manage data like customer profiles, product details, financial transactions, student records, messages, and website activity. A DBMS offers a structure between the application and data, instead of each application using files and folders to manipulate data.
It regulates the generation, retrieval, modification and security of data, and offers tools to manage many users and lots of information. This means that databases are vital to banking institutions, ecommerce platforms, social platforms, healthcare applications, educational institutions, government services, and business software. The selection of DBMS could have a huge impact on the efficiency of the application’s data-handling and response to any user request.
Meaning of DBMS
A DBMS is an organized layer between the applications and data storage. The user takes an action (e.g. searches for a product, updates an account, places an order), and the application sends a request to the database system. The DBMS understands that request and knows how to retrieve the information that is requested, does whatever is needed, and sends the information back to the application. This has the advantage of giving them a common way of dealing with information without having to know the physical characteristics of the storage devices.
A DBMS may also enforce rules that aid in maintaining accurate and consistent data. A database rule and transaction might be used, for instance, to block an account update from being finished only half way, in a banking application. A DBMS simplifies the creation, administration, security, and scalability of complex information systems by consolidating critical data-management tasks into a single system.
How a Database Management System Works.
A typical DBMS implements one or more of the following components, which manage data storage, requests, transactions, security and recovery. An application makes a query or command, which is first understood by the database system and a way to perform it efficiently is determined. This is typically done by a query optimizer within the relational DBMS that tries to look at all the available indexes, tables, relationships, etc., and decide on an execution plan.
The storage component then locates the required information and returns the results. Concurrently, the DBMS enforces authorization rules, transaction controls and integrity constraints as needed. Database systems also record internal information pertaining to data stored in the system, which is known as metadata, and typically describes structures like tables, fields, indexes, constraints, and relationships. They are designed to operate together, enabling applications to manipulate data via logical operations, not by controlling individual storage blocks.
Core DBMS Features
Modern database systems include the ability to do so much more than save information. The key features of a DBMS are data storage and organization, query capability, indexing, concurrency control, security, backup/recovery, transactions and integrity enforcement. These features enable a database to be used with an application that is continually adding, searching, updating, and removing data. For instance, a web-based shop might update stock as clients are placing orders, get product data quickly, secure customer accounts, and recuperate data should there be a hardware or software failure.
If these operations are not managed well, it could lead to data duplication, data inconsistency, data loss, or unauthorized data access. By ensuring that applications interact correctly with the stored information and offer mechanisms to maintain it available, accurate, and consistent during operation, DBMS features lay the foundation for reliable information management.
Data Storage and Organization
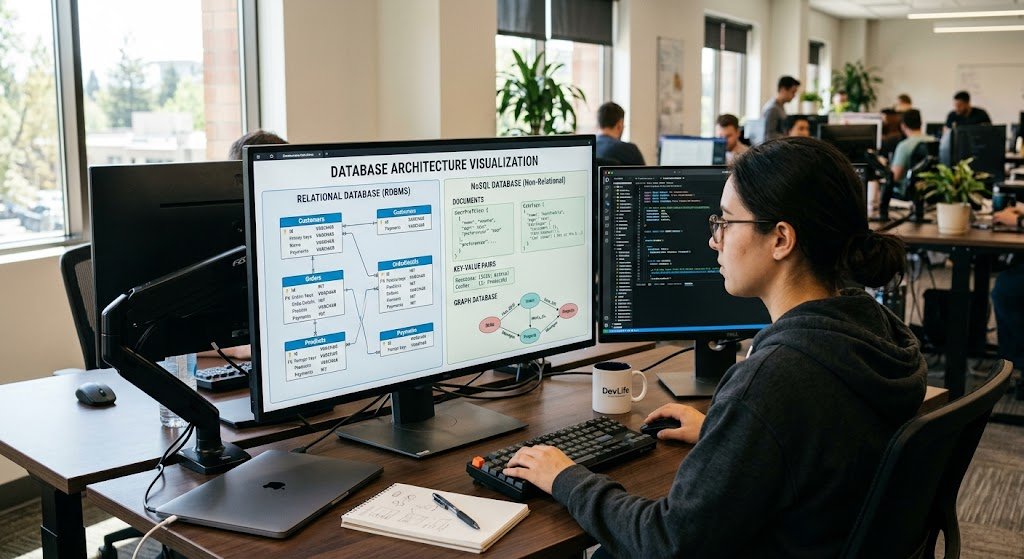
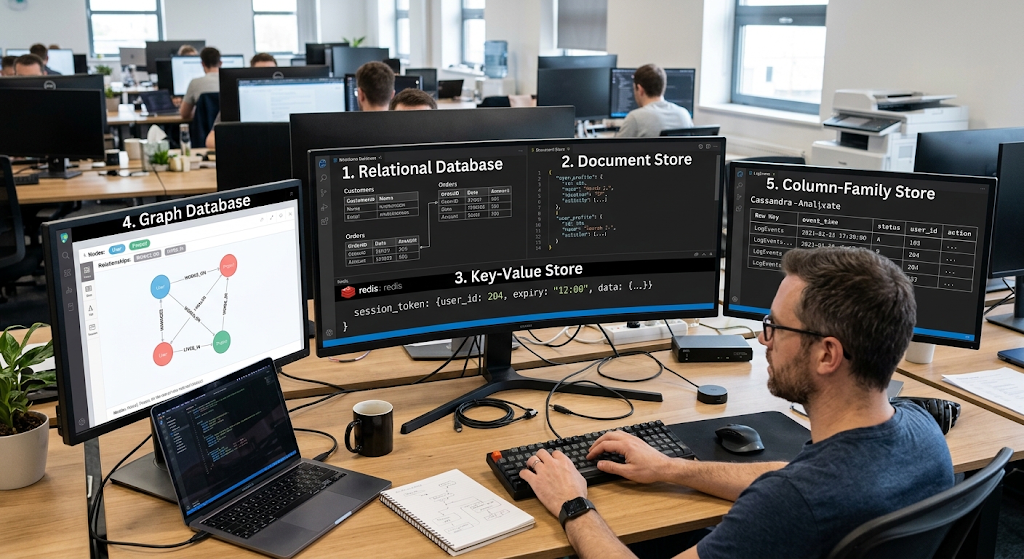
Among the major functions of a DBMS is organizing data to be stored and retrieved efficiently. Information can be represented in a variety of ways in different database models. Relational databases typically store information in tables with columns and rows, and document databases can store flexible records in a document. Key-value databases store data as key-value pairs, while graph databases store information in the form of nodes and the relationships between them as edges.
Column-oriented databases store data by column and are especially suitable for workloads that require a lot of selected columns. The logical structures are managed by the DBMS, which takes care of physical storage, memory buffers, files and other resources. It is not usually necessary for applications to be aware of the location of specific records. The database system manages these details, and provides the developers and users with a logical model that is easier to use.
Querying: The Process of Asking Questions and Finding Information.
Querying is a process in which an application and/or user can ask for certain data from the database without having to search every record in the database. Relational DBMS platforms typically employ Structured Query Language (SQL) to operate on data, including select, insert, update, and delete. For instance, an application might want to return all orders placed in a specific time period or get the products in a specific category.
Other database models might have different query languages, APIs or query formats that better fit their data model. The DBMS handles these requests and tries to perform them efficiently. When databases have millions or billions of records, it is especially important to optimize query performance, as a poorly designed operation can require a lot of computing resources. Efficient query is thus related to both the database technology and the method of data structure and access patterns of the developers.
Indexing and Performance
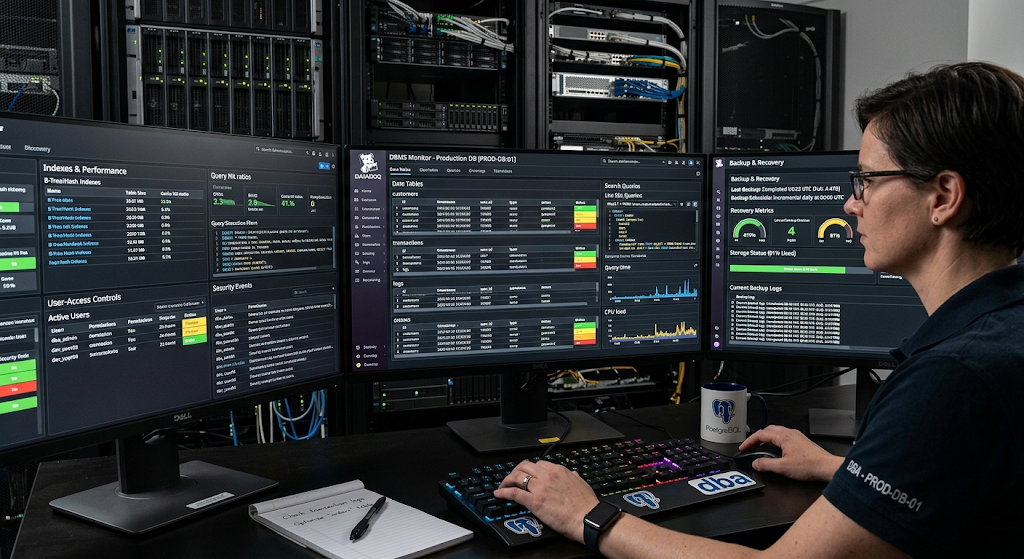
Indexing is also a vital database feature because it may minimize the quantity of data that needs to be examined during a search. An index is a data structure that allows the DBMS to locate records that contain specific fields or values without having to read through all records in the database. For instance, if you have an application that fetches customers based on their email, it can keep an index on the email field so that the database can find matching emails more quickly.
While indexes can enhance read performance, they also come with extra storage needs and maintenance tasks as the index might require updates when the data it indexes changes. Thus, database designers must select indexes based on the workload of the application. You don’t always want to add an index for each field – too many indices could affect the performance of insert and update statements. Effective indexing is a balance between the speed of retrieval and the cost of having additional data structures.
Concurrency Control
Concurrency control is a critical DBMS feature that is required for many applications and users to concurrently access the same database. Think of a web shop in which a few customers try to buy the final item at the same time.Picture a web shop in which a number of customers try to buy the final item at the same time. Without proper coordination of operations from the databases, the system may try to sell out more than it has in stock. Concurrency control is used to prevent such issues when two or more transactions run concurrently by controlling their interactions.
Depending on the technology, techniques such as locking, isolation levels, timestamps and/or multi-version concurrency control can be used with database systems. Properties, like atomicity, consistency, isolation, and durability are also commonly referred to and used in transactions. These properties are important to ensure that related operations are performed reliably, particularly if many users are accessing the same information. For applications with conflicting updates, like banking, reservations, payment systems, inventory platforms, and others, concurrency management is of special significance.
Access Control and Database Security
Database security safeguards the data stored in the database from unauthorized access, accidental modification, and other security threats. A DBMS can furnish an authentication system that can verify users and authorize controls that can decide what they are permitted to do. For instance, an employee might be able to access customer records, but not delete them, or a database admin might have wider access to the system’s management tools. Other security measures for databases include role-based access control, secure connections, auditing, encryption, and safeguarding sensitive data.
Security needs vary from database to database, depending upon the kind of data being stored and the environment the database runs in. Financial information, personal records, business data and authentication information may need to be well protected as unauthorized access can have serious consequences. A secure DBMS is not just a tool for data storage; it offers tools to manage access to specific data and the operations that can be performed on it.
Backup and Recovery
Backup and recovery capabilities allow organizations to safeguard data in the event of failures, software errors, data corruption, accidental deletion, or any other event that could prevent access to the data. A database backup is an independent copy of the database information which can be recovered if needed. Various types of backup strategies can be implemented such as full backups, incremental backups, differential backups, snapshot, and transaction-log-based backups. Recovery mechanisms enable the DBMS, or administrators, to recover information after failure.
Point in time recovery can also be an option for some systems, meaning that an organization can recover data to a specific point in time prior to when a problem arose. A successful recovery strategy should also take into account if there are backups and how often they are made, where they are stored, how long they are kept for and whether restoration procedures have been tested. A backup without recovery processes may not give the protection you are expecting during an actual incident.
Different Types of Database Management Systems
There are a number of different models of database management systems, depending on the structure of the data and the types of workloads used. There are four types of databases: relational, document, key-value, graph, and column-oriented. The differences of these models are in the way they represent information, the way applications query that information, and the different types of workloads they typically support. Structured tables and relationships are the main focus in relational systems, whereas flexible records are the primary focus in document databases.
The key-value data is used for quick access via unique keys, a graph database stores connections between nodes, and a column-oriented database stores specific columns of large datasets. When considering which database technology is used to power an application, it is important to recognize the differences between these two types so developers can choose the appropriate technology for the right situation and not assume that one will fit all situations. In reality, in large systems, multiple database technologies can be used, as different applications might require different data-management needs.
Relational Databases
Relational databases store data in the form of rows and columns. Keys are used to establish relationships between tables, and to connect related information without duplicating data. SQL is a standardized and powerful language for creating, retrieving, updating and managing relational data. Relational databases are typically employed in scenarios demanding structured data and robust transaction control such as financial systems, business applications, inventory platforms, and numerous enterprise systems.
A relational model is useful if there are definite relationships between the various kinds of records. For instance, an eCommerce system could have a Customers table, a Products table, an Orders table, and a Payments table, and there would be foreign key constraints linking the records in these tables together. Relational databases have a structure that makes it easier to enforce consistency, but if the data structures are very dynamic or have a high number of variations, other techniques may be needed to ensure consistency.
Document Databases
Document databases hold data as documents, not all records having to conform to the same table structure. This model may be helpful for an application that has multiple records with different structures, as these records may include nested fields and collections of related information. For instance, a content platform might maintain articles as documents, where the documents have fields such as articles.title, articles.author, articles.category, articles.tag, etc. with the basic idea that not every document needs to have all the fields.
Document databases are often linked to applications that require flexible schemas and quick application development. They can also be useful when an application tends to fetch an entire logical record instead of the information from numerous individual records. But flexibility doesn’t obviate the need for careful data modeling. There are still factors to be taken into account such as duplication, consistency, indexing, patterns of query, and the way the database will work over time as the application grows.
Key-Value Databases
The model used in a key-value database is relatively simple, each item is tied to a key and a value. The key is a name that can be used to retrieve the value quickly by the applications. The model comes in handy when applications need to make simple queries to a single record, instead of when they need to interact with many different records and establish relationships between them. It can be used for caching, session data, configuration data, temporary application state and other workloads that require fast access to data by key.
Key-value systems can scale well for workloads with large numbers of simple operations, as the structure is simple. But, they are not necessarily the best solution for applications that involve queries across several related entities. The selection of this model is thus critically dependent on the way in which information is to be accessed. For an application where there is a high need to retrieve data efficiently with known identifiers, a key-value based architecture may be appropriate.
Graph Databases
A graph database is a type of database that explicitly models relationships. They typically have nodes that represent entities and edges that represent relationships between entities, and properties that are added to a node or both node and edge. This is very helpful when the relationships among pieces of information are as significant as the information itself. Some of these include social networks, recommendation systems, fraud detection, network analysis and knowledge graphs. Relationships like person knows person, product bought with another product or an account involved in several transactions can be represented on a graph database.
Graph queries can travel relationships directly, based on the database model, without having to repeatedly join many tables. This can make graph databases suitable to handle applications with complex and interconnected data. While they can be useful, their utility is contingent on the access pattern of the application, as not all workloads can be represented in a graph.
Column-Oriented Databases
Column-oriented databases store and manipulate data not just by row, but by column. This architecture can be useful for analytical workloads that are focused on a few fields for very large datasets. For instance, a business intelligence system could determine that the total number of transactions in the sales column is many millions, but the other columns don’t need to be retrieved for each transaction. Similar values can also be stored in a column-oriented fashion, which helps with compression and effective aggregation.
A column-oriented approach is beneficial for data warehouses, reporting applications, analytical applications, and for processing large amounts of data. They tend to be built to offer a different level of performance than transactional databases, where more important may be the ability to update individual records often. It is therefore important to consider the type of application – whether it is primarily transactional or analytical – when assessing database architectures.
Selecting the Appropriate Database Model.
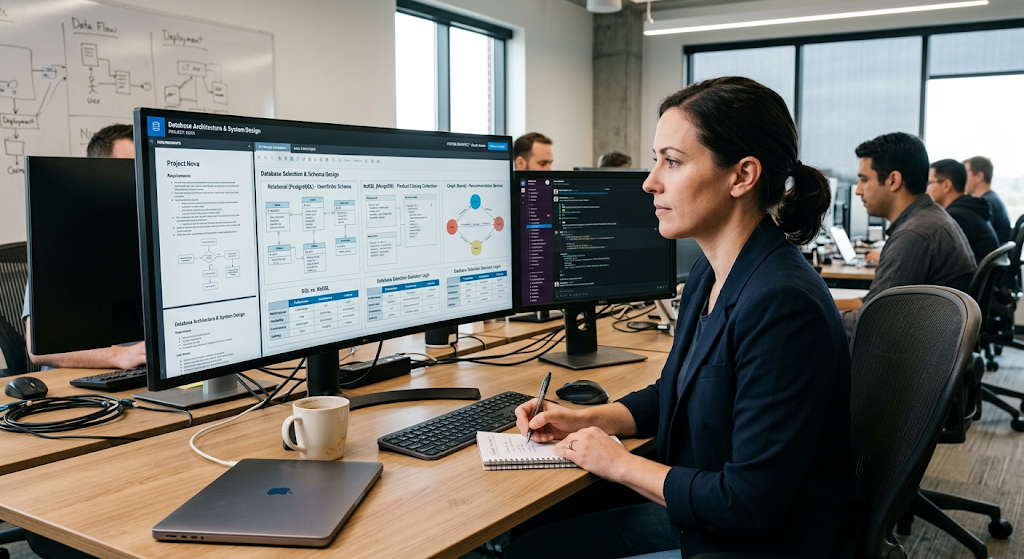
It is important to start with application requirements, not popularity of a technology when selecting a DBMS. The structure of the data, workload, transaction, and query patterns, scalability, consistency requirements, security requirements, and operational resources are all factors for consideration by the developers. A relational database might be a good choice if an application has structured data and complex relationships that need good transaction support. This can be helpful when records have flexible structures, and a key-value database can work well for applications that are dominated by simple key-based lookups.
Relations are at the center of the data, then graph databases should be used, while large-scale analytical workloads can be better handled using column-oriented databases. The categories are not mutually exclusive and many features common to traditional categories are now available in modern database platforms. The suitable one is determined by the technical needs and limitations of the application.
Conclusion
Database Management Systems offer the foundation needed for storing, structuring, accessing, securing, and restoring data in contemporary software systems. They have the duty to store data, but they also provide advanced functions like indexing, transactions, concurrency control, security, backup and recovery. The various models of databases are built based on the various methods of data representation and retrieval. Relational databases are good for organized tables and relationships, document databases are good for storing documents, key-value stores are good for direct lookups, graph databases are good for relationships between entities, and column-oriented databases are good for analytical processing.
Knowing the characteristics of these models will aid the developers in making architectural decisions according to the requirements of the application they are developing. The choice and design of a proper DBMS and its careful implementation are still significant components of the development of a reliable, secure and efficient information system, as the number of applications is growing and generating an ever-growing amount of information.