Introduction
The capability of artificial intelligence (AI) to empower virtual assistants, translation tools, recommendation systems, chatbots and automated customer service is integral to today’s technology. The technologies that underlie these power this computing ability to process information, recognize patterns, and execute tasks that are normally accomplished by human intelligence. Natural Language Processing (NLP), machine learning (ML), and deep learning (DL) are three key concepts in this field. While these terms are sometimes used together, they refer to different concepts and have different applications in the field of AI. Knowing their differences allows students, technologists and novices to better understand the operation of intelligent systems and why some methods are better suited for some tasks than others.
The emphasis of NLP is to make computers work with human language, whereas the emphasis of machine learning is to learn patterns from data and make predictions. Machine learning is a subset of AI that focuses on a specialized type of AI known as deep learning, which involves multiple layers of artificial neural networks designed to uncover complex patterns in large amounts of data. They are often in use concurrently, particularly where written text, spoken language and conversational interaction are all being employed in a task. For instance, a translation application can leverage NLP for linguistic tasks, machine learning for language data pattern recognition, and deep learning for creating natural-sounding translations. In this article, each of these concepts is explained, its key techniques are discussed, its pros and cons are discussed, and its contribution to modern AI systems is shown.
What Is Natural Language Processing (NLP)?
Natural Language Processing is an area of AI focused on the ability of computers to understand, interpret, analyse and produce human language. Knowing individual words isn’t enough to understand what is being said in human communication because meaning is determined by grammar, context, tone, sentence structure, and how parts of a communication relate. NLP is a discipline that takes in concepts from computer science, linguistics, statistics and AI in order to enable machines to deal with these complexities. It can be used for language detection, finding key information in a report, sentiment analysis in a customer review, sentence translation, and answering questions. NLP is not about machine learning or deep learning, which refer to methods of learning from data but rather, it’s about a problem domain in the realm of human language.
In many cases, traditional NLP systems are based on explicit linguistic rules and well-structured algorithms. For instance, an early text-processing program may recognize the names in a text by looking for words that start with capital letters, or it might be able to detect sentence breaks from punctuation. Advanced traditional techniques include Tokenization, Stemming, Lemmatisation, Part of Speech Tagging and Syntactic Parsing. Tokenization is the process of breaking the text into smaller pieces, whereas stemming and lemmatization simplify words. Part-of-speech tagging classifies words as nouns, verbs, adjectives, etc. and syntactic parsing analyzes the relationship between words in a sentence. In recent years, NLP systems have become more common that incorporate machine learning and deep learning, but traditional approaches have their value in preprocessing, rule-based applications, and situations where predictable behavior is essential.

Common Applications of NLP
There are many technologies that people use regularly without realizing that they are making use of NLP. Language-related techniques have been developed to understand search queries and find relevant information in them for search engines, and to classify email to identify spam and prioritize incoming email for email services. Translation tools compare sentences in one language to another and generate sentences in the other language and voice assistants listen to and understand requests before responding.
NLP is also employed to analyze customer feedback, to summarize lengthy documents, to retrieve information from contracts, and to classify support tickets based on their content. The following are examples of NLP applications today. While the method of accomplishing these techniques varies from one system to another, the goal is always the same: to make computers more useful and meaningful processors of human language.
What is Machine Learning (ML)?
Machine learning is a subset of artificial intelligence which allows the computer systems to learn patterns from the data instead of relying completely on rules that are manually programmed. Developers do not state all the possible scenarios that a system might face, but instead give examples for an algorithm to use to make inferences and find patterns. A machine learning model that aims to be able to classify emails, for example, could be trained on a set of previously classified emails that include examples of spam and regular email. While learning, the model looks at the characteristics of the examples and alters its internal parameters to better predict the examples. After training it can assess new messages and make an estimate of which category they can be classified under. The accuracy of its predictions relies on the amount and quality of data it was trained on, the chosen algorithm, features utilized, and how the model is assessed.
There are several types of machine learning, such as supervised learning, unsupervised learning and reinforcement learning. Supervised learning is performed on examples that are already labeled such that it can be used to learn to associate inputs with known outputs, e.g., in sentiment analysis and text classification. Unsupervised learning is used to find patterns or structure in data without any predefined labels, and can be helpful for clustering documents based on the similarity in content. Reinforcement learning is a learning algorithm based on interaction, action and feedback; and some of the language model training and optimization can be done using reinforcement learning. Examples of traditional machine learning algorithms are logistic regression, decision trees, support vector machines, and naive Bayes classifiers. These techniques may be useful for language tasks if the data is properly represented and the problem is well defined, and if computing resources are limited, and if model behaviour is reasonably easy to interpret.
How Machine Learning Supports NLP
NLP is reinforced by machine learning, which allows language-processing systems to learn from examples rather than just relying on linguistic rules that have been manually written. Imagine a business that has thousands of customer reviews they need to rate positively or negatively or as neither. A machine learning model could be developed from labeled reviews based on their sentiment. During training, the model can be made to look at word frequencies, phrases and patterns that belong to each category before it is trained to classify unknown reviews. For instance, if a customer support message is about billing or technical issues or access to the account, you can determine that. The trained classifier can review the message and classify it to the most suitable category, enabling the organization to better organize requests. In both situations, NLP is used to specify the language-related task, and machine learning is used to learn patterns used to complete the task.
Typically, machine learning models are trained on data that has been converted from text to numbers by the developer. One widely-used approach is bag-of-words, where a document is described by its content of words, possibly including the frequency with which they occur. An alternative is the term frequency-inverse document frequency (tf-idf), which assigns more weight to terms that are somewhat uncommon to a library of documents. They can be used effectively with spam detection, document categorization and topic classification algorithms like Naive Bayes and support vector machines. They might have a difficult time grasping subtle meanings, relationships between unusual words, sarcasm, and context specific language, though. These constraints have spurred a search for alternative methods of language representation that are more expressive and can learn richer relationships from data, namely, neural network techniques.
What Is Deep Learning (DL)?
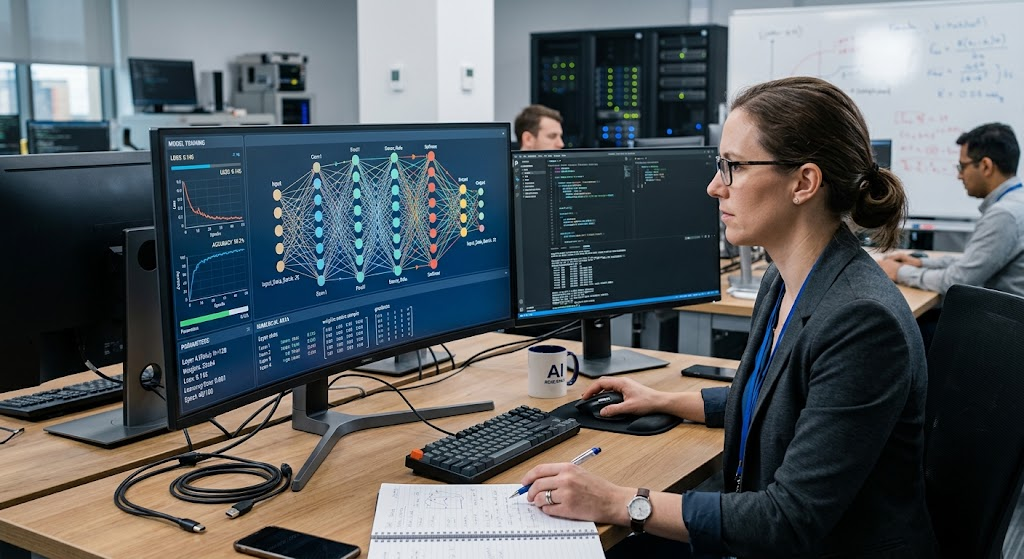
Deep learning is a specialized field of machine learning that relies on artificial neural networks with multiple layers to learn more and more complex representations of data. Such networks are loosely based on features of biological neural networks, but their mathematical functions are distinct from that of the human brain. A neural network is a system that takes numerical inputs, performs computations (using the interconnected units), and generates an output. In the training phase, the network is fed with a set of expected outputs, with its outputs compared to those expected and its parameters fine-tuned to minimize error. If this is repeated for many samples, the network is able to discover something useful that might not be easy to specify using hand-crafted rules. Deep learning works particularly well in applications like pattern recognition, speech processing, and text generation where the relationships between the components are intricate and highly context-specific.
Deep Learning is often able to learn useful representations directly from relatively raw data, without requiring a lot of manual feature engineering, which is the case in many traditional machine learning approaches. For instance, a traditional text classifier can rely on word counts or hand-picked features while a neural network can learn numerical representations that detect relationships between words and phrases. Recurrent neural networks have long been used to process sequential data such as text, as they were structured to process data in a sequential manner. Convolutional neural networks are also used in some tasks of text-classification. Transformer architectures are also now a key component of many modern language systems, as they can capture relationships between words that span a sequence and can be trained efficiently over large volumes of data. Although powerful, deep learning models can be resource-intensive, need large amounts of training data, and take time to evaluate.
Neural Networks and Language Understanding
Neural networks are useful for language-processing systems that are unable to recognize patterns using simple rules or word-frequency features. A case in point is sentiment analysis on sentences where the meaning of the sentence is based on multiple words collaborating. This sentence is an example of a hybrid sentence that could be confused by only picking up the keywords: “The service was surprisingly good despite the long wait”. By being trained with appropriate examples, a neural network can learn these relationships between words, phrases and the meaning of a sentence. For certain words, more sophisticated models could consider context, and for linguistic relationships, word embeddings and other learned representations can be used to encode information. While these capabilities can be useful in text classification, translation, question answering, and conversational AI, the results will still rely on data quality and language patterns present in the training set.
Deep learning has also helped to make significant strides in speech recognition and natural language generation. Speech recognition systems can transcribe spoken words into text, and the language models can then process the text to provide answers or summaries or to carry on a conversation. Various parts in a voice assistant can listen to speech, understand what is being asked, find the required information and respond accordingly. These can be supported by several of these stages, but the overall system could involve other components such as databases, search capabilities, business rules, and traditional software elements. So, it’s not worth assuming that every aspect of an intelligent application is running on deep learning. Rather, contemporary systems frequently integrate neural networks with other technologies so as to provide a trade-off between accuracy, speed, cost, reliability and the requirements of the specific application.
Transformer Models: Connecting NLP and Deep Learning
Transformers are deep learning models that have had a profound impact on today’s NLP and have enhanced the way models capture relationships between words and other elements of text. Proposed in a groundbreaking study published in 2017, the transformer architecture takes advantage of a mechanism called attention which identifies which parts of an input are particularly significant when processing a specific element. Unlike regular recurrent neural networks (RNNs) that take in and process one element of a sequence at a time, transformers can simultaneously process many elements of a sequence during key training phases. This architecture makes training much more efficient, and enables models to learn many complex relationships over longer passages. Transformer models are currently being used in various applications, such as translation, summarization, information extraction, question answering, and conversational AI.
There are various types of transformer models which are used for different purposes. For instance, BERT, which is used in text classification and question answering tasks, was developed to learn representations that can be used for a given context. The GPT models are trained to predict and generate text, which makes them applicable to tasks such as writing assistance, conversational systems, and more. Tasks that involve converting one text sequence to another, like translation and summarization, can be handled by encoder-decoder models like the original Transformer architecture and models like T5. These models are not the end of NLP or machine learning as a whole. Rather, they illustrate the potential of deep learning approaches in the realm of language issues. NLP defines problems and tasks of human language; machine learning gives the general background of learning from data and deep learning gives the powerful neural network techniques that many modern language models are based on.
Key Differences Between NLP, Machine Learning, and Deep Learning
While NLP, machine learning and deep learning are similar in this regard, they are not the same concept, nor are they used in the same way, nor do they have the same scope or purpose. While NLP is more focused on programming computers to understand human language, machine learning is focused on creating systems that can learn from data. Deep learning is one form of machine learning that uses a multi-layered neural network. This is crucial since NLP is not a replacement for machine learning or deep learning, but rather another algorithm in the same vein as another algorithm. Instead, NLP has the ability to tackle language-related challenges with the help of machine learning and deep learning methods. In addition to NLP, ML and DL can be used in other fields like Medical image analysis, Fraud detection, Forecasting, Robotics, and Recommender systems.
The traditional NLP systems can be based on manually designed processing steps, linguistic rules, and dictionaries. In most conventional machine learning systems, the features are selected or created by the developers, and some learning systems can learn a representation from data. With training, deep learning systems can learn more complex representations, sometimes directly from raw or minimally processed inputs. There are also differences in the amount of computing power needed. Rule-based systems can be cheap and easy to operate when the requirement is a very specific task, whereas conventional machine learning models can train efficiently on moderate size datasets. Complex deep learning models may need dedicated hardware, vast amounts of data, and ample energy. Yet, it is not only the complexity of the models that should be considered; also the nature of the task, the quality of available data, the desired accuracy and operational considerations.
Comparison Table
| Feature | Natural Language Processing (NLP) | Machine Learning (ML) | Deep Learning (DL) |
| Main purpose | Analyses and processes human language. | Learn patterns from data. | Taught complex patterns with multilayered neural network |
| Classification | The field of AI was focused on language.Field of AI was about language. | Branch of AI | A specialized branch of the field of machine learning. |
| Primary focus | Use text, speech, meaning, and language generation. | Prediction, classification, clustering, etc. of learning tasks | Representation learning and prediction with ease. |
| Common techniques | These elements are essential for self-service.These are the key components of self-service. | Logistic regression, naive Bayes, decision trees and support vector machines. | Tutorials: Transformer, Recurrent neural network, Deep feedforward neural network |
| Feature engineering | Might apply language conventions and conventions associated with oral texts | Often uses engineered features, depending on the method | Is able to learn representations from training data automatically. |
| Data requirements | Adjust as needed to the technique | Handle large and small sets of data | Usually requires large amounts of data but vary in the need for large amounts of data |
| Computing needs | May be somewhat low for rule based tasks | Usually moderate depending on algorithm | May be elevated, particularly with large models |
| Applications | Translation, text analysis, chat-bots, speech processing | Detect, predict, classify, recommend frauds | Using picture recognition, language production and high quality translation. |
| Relationship to other fields | Can use methods for ML and DL | Can assist in NLP and numerous other areas. | Can power modern NLP and non-language applications |
The table illustrates the relationship between but not the interchangeability of these technologies. NLP is about language and machine learning is about learning from data and deep learning is a class of machine learning methods that use neural networks. An NLP application can be based on a rule-based system without machine learning, a traditional machine learning classifier, or a large transformer system constructed with deep learning. Similarly, without doing any NLP task, a deep learning model can be employed for image recognition. Knowing these differences helps to assess technology claims, compare AI solutions, and choose the right one for a specific problem. It also provides an understanding of why single modern applications may consist of multiple components, or pieces of different techniques, and not a single algorithm.
Practical Examples of How the Three Technologies Work Together

1. Machine Translation
Machine Translation is an example of how NLP and deep learning are used in tandem to translate between languages. The user might type a sentence in English, wish it to be translated into French or Yoruba or another supported language. The system should detect patterns in the source text, represent the meaning of the source text, explain the relationships among the grammar patterns, and produce an appropriate sentence in the target language. NLP specifies the problem of translation and the language problems it entails, and machine learning offers a means to learn the correspondences between languages from examples. The most recent translation systems employ transformer-based deep learning models that are pre-trained on a vast multilingual corpora. These models are trained to identify patterns in word order, grammar, and context, which can lead to more coherent translations than just substituting words.
The traditional translation systems depended largely on a dictionary, a set of rules built up and elaborated by hand, or statistics methods which estimated the probability of different translation. These methods are still applicable in specific cases, but they can have trouble with expressions whose meaning is context-dependent or culturally-specific. While neural machine translation models can learn more complex relationships, they are not always accurate. Some words and phrases can have multiple definitions and often the translation of a single word or phrase is influenced by the context of the sentence and what is being talked about. Models also might not work as well on languages with few training examples. Thus, to be effective, translation systems need to be provided with suitable data sets and tested and evaluated by users of the languages to be translated. This is just an example of how NLP can be used to recognise the problem, and machine learning and deep learning can be used to solve it.
2. Text Classification and Spam Detection
Text classification is the process of categorizing a text or message into one or more predefined categories. Email spam detection is a well known example, where email service companies must tell the difference between spam and legitimate email. An NLP system processes the text and prepares the text for classification, which may involve identifying words, phrases, links, or other properties that are relevant to the text. A pattern that is learned from all the emails that have been previously labeled is then used to predict and classify a new email as spam or not spam. Naive Bayes, Logistic regression, Support vector machines or Neural network can be used by the developers depending on the application. It depends on the size of the data set, available computer resources, interpretability and the cost of classification errors. An effective system should not block legitimate e-mail messages in addition to recognizing unwanted messages.
In situations where more complex language patterns are needed for text classification, deep learning can be used to enhance the process. For instance, a message could contain incorrect language, non-explicit requests or an unusual sentence structure to evade easy detection of keywords. A neural network can be trained from a variety of examples, and may learn relationships that would not be easily defined by a few rules. But high-tech models aren’t always better in all cases. In simpler situations, where categories are well-defined and the data is not too complex, a traditional classifier might yield sufficient accuracy without the high computational expense. It’s important to test models with representative data and track performance over time as the pattern of messages changes. Spam detection is thus an example of the hybridization or comparison of NLP, machine learning, and deep learning as per the need of the application.
3. Conversational AI and Virtual Assistants
Conversational AI systems enable users to interact with technology using natural language, instead of having to use all menus or fixed commands. This can range from customer support chatbots to voice assistants and AI-driven question answering or task completion tools. These can require an understanding of a user’s query, the ability to identify relevant information, and the ability to provide an informative answer. NLP offers methods to analyze language, to identify entities, to categorize intentions, and to generate understandable language. The machine learning code can be trained to identify patterns in customer requests, and deep learning models can be used to understand the context and respond in a natural way. Neural networks can also be employed in a voice-based application to transform speech to text and vice versa, in addition to speech synthesis.
Transformer-based language models are commonly employed in modern conversational systems as they can capture intricate language relationships and produce answers in the context of conversations. But when responding to a text you have to understand the language very well, but that does not mean that you will be correct in every answer or that it will be suitable. Models can have misinterpretations of some questions, make unsupported claims and not know when information is missing. These risks can be mitigated by developers by evaluating carefully, using credible information sources, providing instructions, and by humans if required. Some apps that use conversation also employ retrieval systems to get the information that is relevant before they can produce a response. The interaction of language processing, learned prediction, information retrieval, and software rules shows the possible interplay of more than one AI technique to provide one product for the user.
Advantages and Limitations of Each Approach
Advantages and Limitations of NLP
The great thing about NLP is that it concentrates on language related issues that are not just theoretical. It aids in the search for information, communication across language barriers, document organization and interaction with digital services on a more natural level. The techniques of NLP can be customized for each industry, such as Education, Health Administration, Customer Service, and Legal Document Management. Predictable processing of a limited number of expressions may also warrant the use of rule-based methods.
But human language is complex, multi-layered and evolving constantly. Words have more than one meaning; people use slang and idioms; sentences can mean different things in different contexts. This can cause problems for systems that rely heavily on rule-based systems, and for learned models, these variations can be picked up from the training data leading to errors and biases.
Advantages and Limitations of Machine Learning
Machine learning allows systems to adapt to patterns in data and make predictions without requiring developers to write a separate rule for every possible example. Many conventional algorithms are relatively efficient, and some offer useful explanations of how input features influence predictions. These qualities make machine learning attractive for classification, forecasting, and structured decision-support tasks.
Nevertheless, model performance depends on data quality, feature representation, and the relationship between training examples and real-world situations. A classifier trained on unrepresentative data may make unreliable predictions when it encounters unfamiliar language or new patterns. Traditional models may also require extensive feature engineering to handle complicated linguistic relationships. For these reasons, machine learning systems need suitable training data, clear evaluation criteria, and ongoing monitoring after deployment.
Advantages and Limitations of Deep Learning
Deep learning can model highly complex relationships and learn useful representations from large datasets, making it especially valuable for advanced language processing, speech recognition, and text generation. Transformer models have enabled major advances in translation, summarization, question answering, and conversational systems. However, training and operating large neural networks can be expensive, and their internal decision processes may be difficult to interpret. They can also reproduce biases, generate inaccurate information, or perform poorly on examples that differ significantly from their training data.
Smaller datasets, limited computing resources, and strict latency requirements may make simpler models more suitable for some tasks. Selecting deep learning merely because it is more advanced can therefore lead to unnecessary cost and complexity. A successful implementation balances performance with reliability, explainability, resource requirements, and the consequences of incorrect outputs.
How to Choose the Right Approach
Choosing between traditional NLP techniques, conventional machine learning, and deep learning begins with defining the problem clearly. Developers should consider what the system needs to accomplish, what data is available, how accurate the results must be, and what happens when a prediction is wrong. A simple rule-based system may be sufficient for extracting information from documents that follow a consistent format. A conventional machine learning classifier may work well for sorting customer messages into a small number of categories. A transformer-based model may be more appropriate for generating natural-language responses, translating complex sentences, or interpreting questions that require contextual understanding. In practice, many applications combine these approaches rather than relying on one method exclusively.
Resource constraints are equally important when selecting a solution. Organizations should consider development time, computational costs, response speed, privacy requirements, maintenance, and the need for understandable decisions. A large language model may provide impressive results, but a smaller model can be easier to operate and may perform sufficiently well for a specific task. Developers should compare candidate systems using representative test data and appropriate evaluation measures rather than relying only on general claims about model capabilities. They should also monitor performance after deployment because user behavior, language patterns, and data distributions can change. The most suitable approach is the one that meets the application’s real requirements reliably, efficiently, and responsibly.
The Future of NLP, Machine Learning, and Deep Learning
The development of AI continues to bring NLP, machine learning, and deep learning closer together. Large language models have expanded the range of tasks that computers can perform through natural-language instructions, while improvements in training methods and model design continue to influence translation, document analysis, conversational systems, and information retrieval. Researchers are also exploring systems that combine language models with external tools, structured databases, and specialized models. These combinations can help applications retrieve current information, carry out defined operations, and solve problems that require more than generating text. At the same time, progress in smaller and more efficient models may make advanced language technologies accessible to organizations that cannot afford large-scale computing infrastructure.
Despite these developments, important challenges remain. Language systems must be evaluated for accuracy, fairness, privacy, security, and their ability to handle unfamiliar situations. Multilingual performance is another significant concern because many languages have fewer digital resources than English, which can limit the quality of training data and model outputs. Organizations must also determine when automated decisions require human review and how to communicate the limitations of AI-generated information. Future advances will depend not only on increasing model size but also on improving data quality, evaluation methods, efficiency, and responsible deployment. Understanding the relationship between NLP, machine learning, and deep learning will remain valuable as these technologies evolve and become more integrated into everyday applications.
Conclusion
Natural Language Processing, machine learning, and deep learning are closely connected, but each represents a different concept within artificial intelligence. NLP focuses on enabling computers to process and generate human language. Machine learning provides methods that allow systems to learn patterns from data, while deep learning uses multilayered neural networks to learn complex representations. NLP applications can rely on traditional linguistic rules, conventional machine learning classifiers, deep neural networks, or combinations of these techniques. Modern transformer-based models demonstrate how deep learning can support sophisticated language tasks such as translation, text classification, summarization, and conversational AI.
Understanding these differences makes it easier to recognize how modern AI systems are designed and why particular technologies are chosen for specific problems. Not every language task requires a large neural network, and not every machine learning application involves human language. The best solution depends on the task, available data, computing resources, performance requirements, and potential risks. As AI continues to develop, the combination of language-focused methods, data-driven learning, and advanced neural architectures will remain central to many technological innovations. For students, developers, and technology enthusiasts, understanding these foundational relationships provides a useful starting point for exploring how intelligent applications work and how they can be built more effectively.